> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/mo-xing/tutorials/glm-4.6-how-to-run-locally.md).
# GLM-4.6:本地运行指南
关于如何在你自己的本地设备上运行 Z.ai 的 GLM-4.6 和 GLM-4.6V-Flash 模型的指南!
GLM-4.6 和 **GLM-4.6V-Flash** 是最新的推理模型,来自 **Z.ai**,在代码和智能体基准测试上取得了 SOTA 性能,同时提供了更好的对话聊天体验。 [**GLM-4.6V-Flash**](#glm-4.6v-flash) **较小的 9B 模型于 2025 年 12 月发布,你现在也可以运行它。**
完整的 355B 参数模型需要 **400GB** 的磁盘空间,而 Unsloth Dynamic 2-bit GGUF 将大小缩减到 **135GB** (-**75%)**. [**GLM-4.6-GGUF**](https://huggingface.co/unsloth/GLM-4.6-GGUF)
{% hint style="success" %}
为了获得最佳性能,请确保你的可用总内存(VRAM + 系统内存)大于你正在下载的量化模型文件大小。如果不足,llama.cpp 仍可通过 SSD/HDD 卸载运行,但推理会更慢。
{% endhint %}
所有上传都使用 Unsloth [Dynamic 2.0](/docs/zh/ji-chu-zhi-shi/dynamic-3.0-ggufs.md) 以在 SOTA 5-shot MMLU 和 Aider 上取得更好的表现,这意味着你可以在几乎不损失准确率的情况下运行并微调量化后的 GLM LLM。
**教程导航:**
运行 GLM-4.6V-Flash 运行 GLM-4.6
### :bug:Unsloth 聊天模板与错误修复
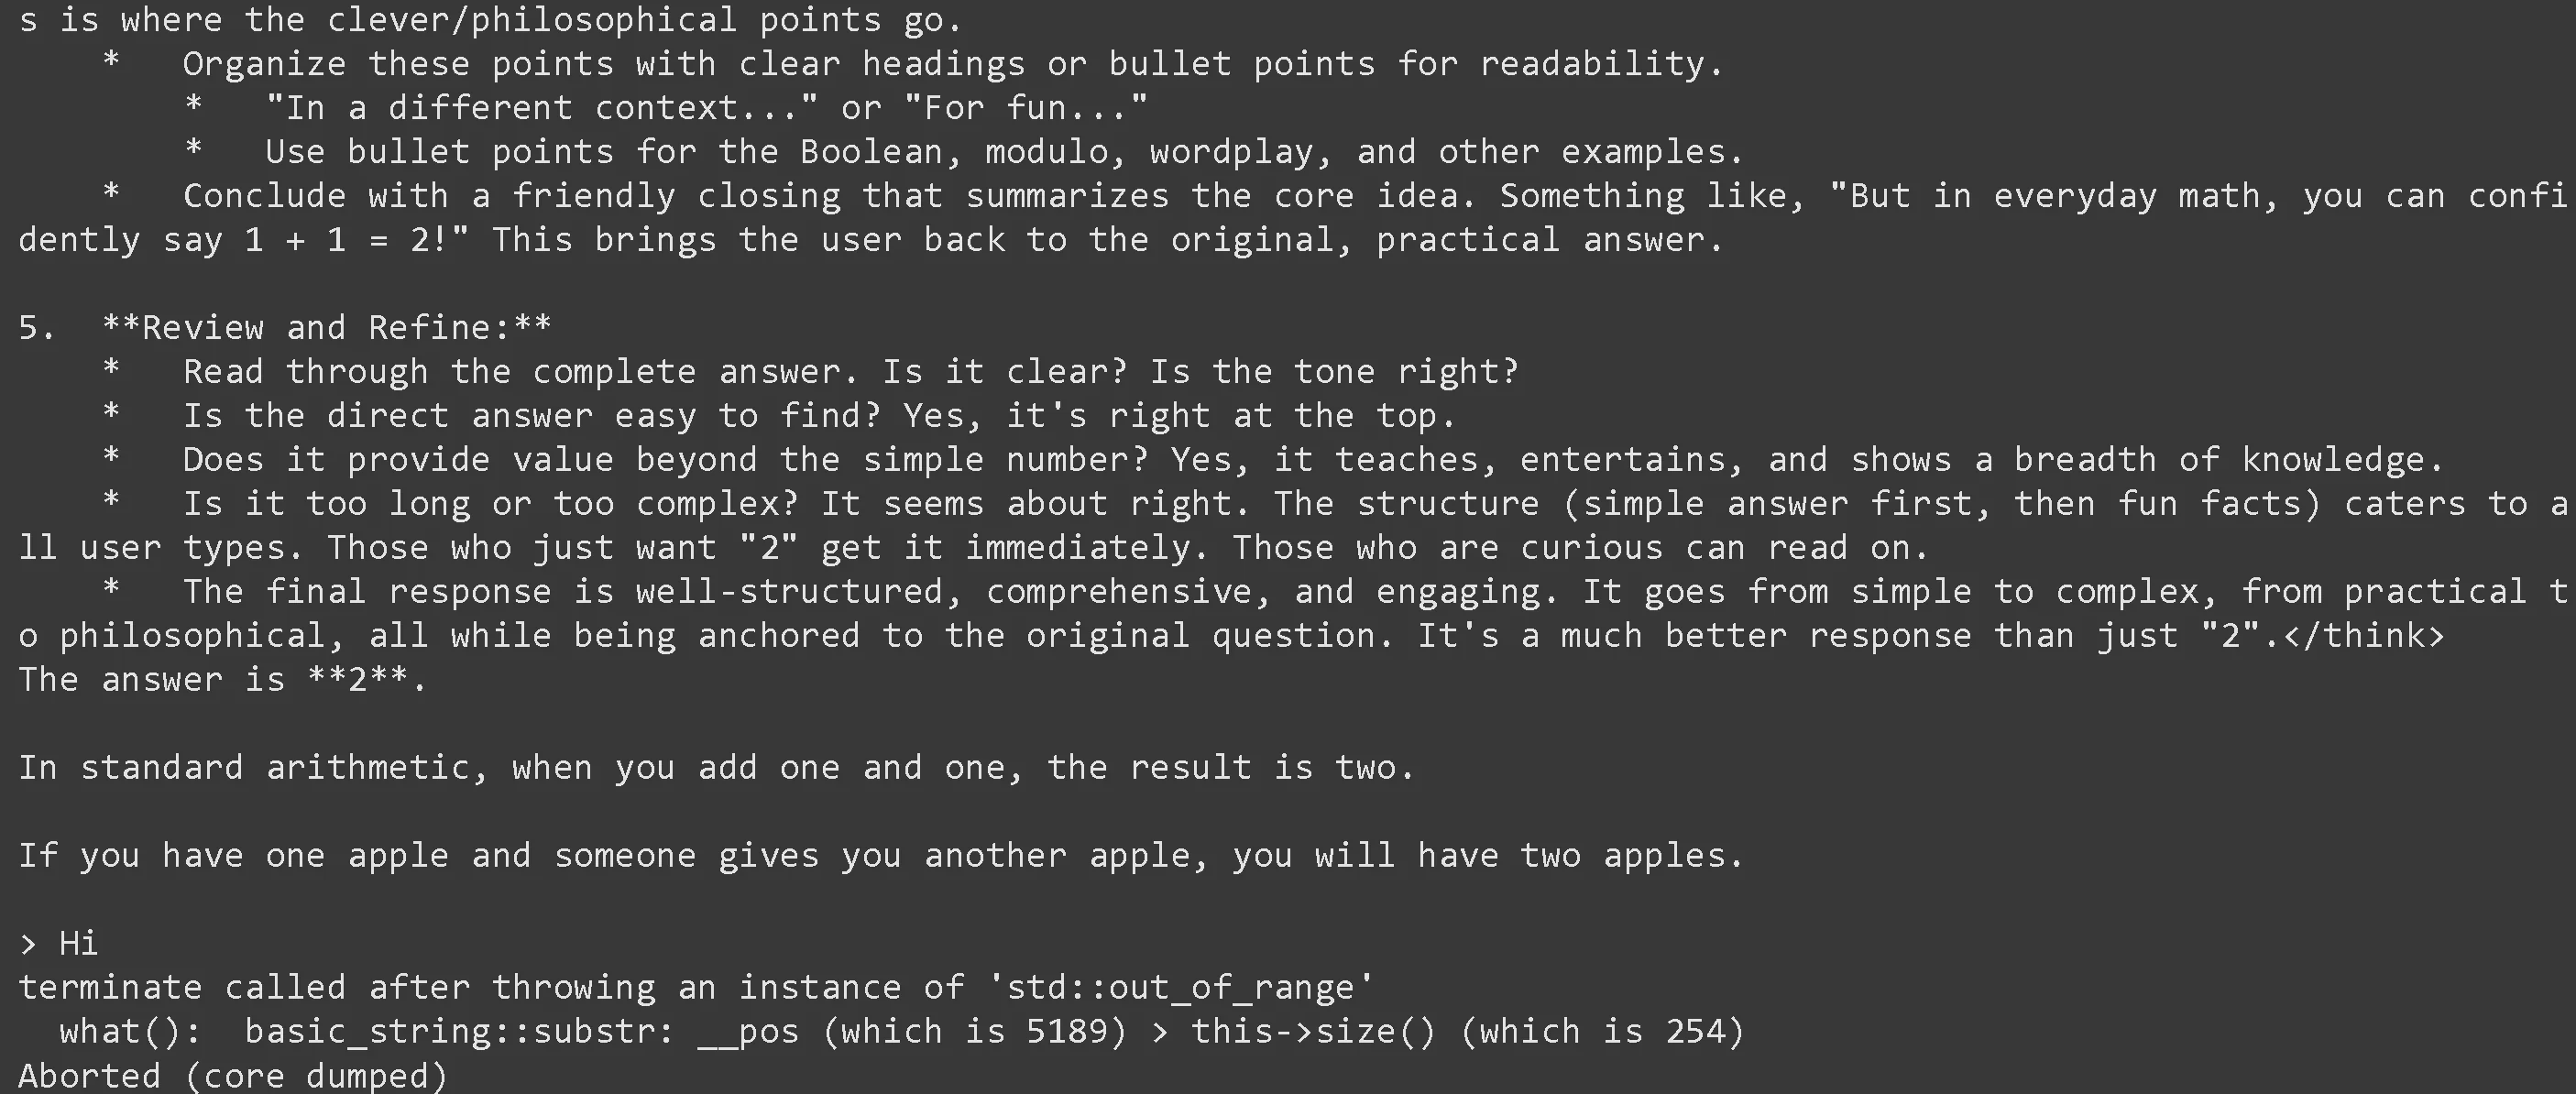
我们做的一项重要修复是解决了 GGUF 提示中的一个问题,即第二个提示无法工作。我们已经修复了这个问题,不过如果没有我们的修复,这个问题在 GGUF 中仍然存在。例如,使用任何非 Unsloth 的 GLM-4.6 GGUF 时,第一次对话可以正常工作,但第二次就会出错。
**temperature = 0.8** | **temperature = 1.0** |
| **top\_p = 0.6** (推荐) | **top\_p = 0.95** (推荐用于编码) |
| **top\_k = 2** (推荐) | **top\_k = 40** (推荐用于编码) |
| **128K 上下文长度** 或更少 | **20 万上下文长度** 或更少 |
| **repeat\_penalty = 1.1** | |
| **max\_generate\_tokens = 16,384** | **max\_generate\_tokens = 16,384** |
* 使用 `--jinja` 用于 llama.cpp 变体——我们 **也修复了一些聊天模板问题!**
## 运行 GLM-4.6 教程:
请查看我们关于运行的分步指南 [GLM-4.6V-Flash](#glm-4.6v-flash) 以及更大的 [GLM-4.6](#glm-4.6) 模型。
### GLM-4.6V-Flash
{% hint style="success" %}
**截至 2025 年 12 月 16 日的新消息:GLM-4.6-V 现已更新,支持视觉功能!**
{% endhint %}
#### ✨ 在 llama.cpp 中运行
{% stepper %}
{% step %}
获取最新的 `llama.cpp` 在 [GitHub](https://github.com/ggml-org/llama.cpp)。你也可以使用下面的构建说明。更改 `-DGGML_CUDA=ON` 改为 `-DGGML_CUDA=OFF` 如果你没有 GPU,或者只想使用 CPU 推理。 **对于 Apple Mac / Metal 设备**,设置 `-DGGML_CUDA=OFF` 然后按常规继续——Metal 支持默认开启。
```bash
apt-get update
apt-get install pciutils build-essential cmake curl libcurl4-openssl-dev -y
git clone https://github.com/ggml-org/llama.cpp
cmake llama.cpp -B llama.cpp/build \\
-DBUILD_SHARED_LIBS=OFF -DGGML_CUDA=ON -DLLAMA_CURL=ON
cmake --build llama.cpp/build --config Release -j --clean-first --target llama-cli llama-mtmd-cli llama-server llama-gguf-split
cp llama.cpp/build/bin/llama-* llama.cpp
```
{% endstep %}
{% step %}
如果你想使用 `llama.cpp` 若要直接加载模型,你可以这样做:(:Q8\_K\_XL) 是量化类型。你也可以通过 Hugging Face 下载(第 3 点)。这类似于 `ollama run` 。使用 `export LLAMA_CACHE="folder"` 来强制 `llama.cpp` 保存到特定位置。请记住,该模型的最大上下文长度只有 128K。
```bash
export LLAMA_CACHE="unsloth/GLM-4.6V-Flash-GGUF"
./llama.cpp/llama-cli \\
-hf unsloth/GLM-4.6V-Flash-GGUF:UD-Q8_K_XL \
--n-gpu-layers 99 \
--jinja \\
--ctx-size 16384 \
--flash-attn on \\
--temp 0.8 \
--top-p 0.6 \
--top-k 2 \
--repeat-penalty 1.1 \
-ot ".ffn_.*_exps.=CPU"
```
{% endstep %}
{% step %}
通过以下方式下载模型(在安装 `pip install huggingface_hub hf_transfer` 之后)。你可以选择 `UD-`Q4\_K\_XL(动态 4bit 量化)或其他量化版本,例如 `Q8_K_XL` .
```python
# !pip install huggingface_hub hf_transfer
import os
os.environ["HF_HUB_ENABLE_HF_TRANSFER"] = "0" # 有时可能会触发速率限制,因此将其设为 0 以禁用
from huggingface_hub import snapshot_download
snapshot_download(
repo_id = "unsloth/GLM-4.6V-Flash-GGUF",
local_dir = "unsloth/GLM-4.6V-Flash-GGUF",
allow_patterns = ["*UD-Q8_K_XL*"],
)
```
{% endstep %}
{% endstepper %}
### GLM-4.6
#### :llama: 在 Ollama 中运行
{% stepper %}
{% step %}
安装 `ollama` 如果你还没安装的话!要运行该模型的更多变体, [请看这里](https://unsloth.ai/docs/zh/mo-xing/tutorials/pages/e159c2414bf59eef4f0d1e98dc6013b013c34532#run-in-llama.cpp).
```bash
apt-get update
apt-get install pciutils -y
curl -fsSL https://ollama.com/install.sh | sh
```
{% endstep %}
{% step %}
运行模型!注意,如果失败,你可以在另一个终端中调用 `ollama serve`!我们把所有修复和建议参数(温度等)都包含在 `params` 中,位于我们上传到 Hugging Face 的文件里!
```
OLLAMA_MODELS=unsloth ollama serve &
OLLAMA_MODELS=unsloth ollama run hf.co/unsloth/GLM-4.6-GGUF:TQ1_0
```
{% endstep %}
{% step %}
要运行其他量化版本,你需要先将 GGUF 分割文件合并成 1 个,如下方代码所示。然后你需要在本地运行模型。
```bash
./llama.cpp/llama-gguf-split --merge \\
GLM-4.6-GGUF/GLM-4.6-UD-Q2_K_XL/GLM-4.6-UD-Q2_K_XL-00001-of-00003.gguf \
merged_file.gguf
```
```bash
OLLAMA_MODELS=unsloth ollama serve &
OLLAMA_MODELS=unsloth ollama run merged_file.gguf
```
{% endstep %}
{% endstepper %}
#### ✨ 在 llama.cpp 中运行
{% stepper %}
{% step %}
获取最新的 `llama.cpp` 在 [GitHub 上获取](https://github.com/ggml-org/llama.cpp)。你也可以按照下面的构建说明进行操作。将 `-DGGML_CUDA=ON` 改为 `-DGGML_CUDA=OFF` 如果你没有 GPU,或者只想使用 CPU 推理。
```bash
apt-get update
apt-get install pciutils build-essential cmake curl libcurl4-openssl-dev -y
git clone https://github.com/ggml-org/llama.cpp
cmake llama.cpp -B llama.cpp/build \\
-DBUILD_SHARED_LIBS=OFF -DGGML_CUDA=ON -DLLAMA_CURL=ON
cmake --build llama.cpp/build --config Release -j --clean-first --target llama-quantize llama-cli llama-gguf-split llama-mtmd-cli llama-server
cp llama.cpp/build/bin/llama-* llama.cpp
```
{% endstep %}
{% step %}
如果你想使用 `llama.cpp` 直接加载模型,你可以执行如下操作:(:Q2\_K\_XL) 是量化类型。你也可以通过 Hugging Face 下载(见第 3 点)。这类似于 `ollama run` 。使用 `export LLAMA_CACHE="folder"` 来强制 `llama.cpp` 保存到特定位置。请记住,该模型的最大上下文长度只有 128K。
{% hint style="success" %}
请试试 `-ot ".ffn_.*_exps.=CPU"` 将所有 MoE 层卸载到 CPU!这实际上让你可以把所有非 MoE 层放到 1 张 GPU 上,从而提升生成速度。如果你有更多 GPU 容量,还可以自定义正则表达式以容纳更多层。
如果你有更多一点 GPU 内存,可以尝试 `-ot ".ffn_(up|down)_exps.=CPU"` 这会卸载上投影和下投影 MoE 层。
尝试 `-ot ".ffn_(up)_exps.=CPU"` 如果你有更多 GPU 内存。这只会卸载上投影 MoE 层。
最后通过以下方式卸载所有层: `-ot ".ffn_.*_exps.=CPU"` 这会使用最少的 VRAM。
你也可以自定义正则表达式,例如 `-ot "\.(6|7|8|9|[0-9][0-9]|[0-9][0-9][0-9])\.ffn_(gate|up|down)_exps.=CPU"` 表示从第 6 层开始,只卸载 gate、up 和 down MoE 层。
{% endhint %}
```bash
export LLAMA_CACHE="unsloth/GLM-4.6-GGUF"
./llama.cpp/llama-cli \\
--model GLM-4.6-GGUF/UD-Q2_K_XL/GLM-4.6-UD-Q2_K_XL-00001-of-00003.gguf \
--n-gpu-layers 99 \
--jinja \\
--ctx-size 16384 \
--flash-attn on \\
--temp 1.0 \\
--top-p 0.95 \\
--top-k 40 \
-ot ".ffn_.*_exps.=CPU"
```
{% endstep %}
{% step %}
通过以下方式下载模型(在安装 `pip install huggingface_hub hf_transfer` 之后)。你可以选择 `UD-`Q2\_K\_XL(动态 2 位量化)或其他量化版本,例如 `Q4_K_XL` . 我们 **建议使用我们的 2.7 位动态量化** ** ** **`UD-Q2_K_XL`** ** ** **以平衡体积和准确率** .
```python
# !pip install huggingface_hub hf_transfer
import os
os.environ["HF_HUB_ENABLE_HF_TRANSFER"] = "0" # 有时可能会触发速率限制,因此将其设为 0 以禁用
from huggingface_hub import snapshot_download
snapshot_download(
repo_id = "unsloth/GLM-4.6-GGUF",
local_dir = "unsloth/GLM-4.6-GGUF",
allow_patterns = ["*UD-Q2_K_XL*"], # 动态 2bit 使用 "*UD-TQ1_0*" 表示动态 1bit
)
```
{% endstep %}
{% step %}
你可以修改 `--threads 32` CPU 线程数, `--ctx-size 16384` 用于上下文长度, `--n-gpu-layers 2` 用于 GPU 卸载的层数。如果你的 GPU 显存不足,请尝试调整它。如果你只使用 CPU 推理,也请将其移除。
{% code overflow="wrap" %}
```bash
./llama.cpp/llama-cli \\
--model unsloth/GLM-4.6-GGUF/UD-Q2_K_XL/GLM-4.6-UD-Q2_K_XL-00001-of-00003.gguf \
--jinja \\
--n-gpu-layers 99 \
--temp 1.0 \\
--top-p 0.95 \\
--top-k 40 \
--ctx-size 16384 \
--seed 3407 \
-ot ".ffn_.*_exps.=CPU"
```
{% endcode %}
{% endstep %}
{% endstepper %}
### ✨ 使用 llama-server 和 OpenAI 的 completion 库进行部署
要使用 llama-server 进行部署,请使用以下命令:
{% code overflow="wrap" %}
```bash
./llama.cpp/llama-server \\
--model unsloth/GLM-4.6-GGUF/UD-Q2_K_XL/GLM-4.6-UD-Q2_K_XL-00001-of-00003.gguf \
--alias "unsloth/GLM-4.6" \
--n-gpu-layers 999 \
-ot ".ffn_.*_exps.=CPU" \\
--prio 3 \
--temp 1.0 \\
--top-p 0.95 \\
--top-k 40 \
--ctx-size 16384 \
--port 8001 \\
--jinja
```
{% endcode %}
然后使用 OpenAI 的 Python 库 `pip install openai` :
```python
from openai import OpenAI
import json
openai_client = OpenAI(
base_url = "http://127.0.0.1:8001/v1",
api_key = "sk-no-key-required",
)
completion = openai_client.chat.completions.create(
model = "unsloth/GLM-4.6",
messages = [{"role": "user", "content": "2+2 等于多少?"},],
)
print(completion.choices[0].message.content)
```
### :minidisc:模型上传
**我们所有的上传** - 包括那些非 imatrix-based 或非动态的版本,都使用了我们的校准数据集,该数据集专门针对对话、编码和语言任务进行了优化。
* 下面是完整的 GLM-4.6 模型上传:
我们还上传了 [IQ4\_NL](https://huggingface.co/unsloth/GLM-4.6-GGUF/tree/main/IQ4_NL) 和 [Q4\_1](https://huggingface.co/unsloth/GLM-4.6-GGUF/tree/main/Q4_1) 量化版本,它们分别专门针对 ARM 和 Apple 设备提供更快的运行速度。
### :snowboarder: 提升生成速度
如果你有更多 VRAM,可以尝试卸载更多 MoE 层,或者直接卸载整个层。
通常, `-ot ".ffn_.*_exps.=CPU"` 会将所有 MoE 层卸载到 CPU!这实际上让你可以把所有非 MoE 层放到 1 张 GPU 上,从而提升生成速度。如果你有更多 GPU 容量,还可以自定义正则表达式以容纳更多层。
如果你有更多一点 GPU 内存,可以尝试 `-ot ".ffn_(up|down)_exps.=CPU"` 这会卸载上投影和下投影 MoE 层。
尝试 `-ot ".ffn_(up)_exps.=CPU"` 如果你有更多 GPU 内存。这只会卸载上投影 MoE 层。
你也可以自定义正则表达式,例如 `-ot "\.(6|7|8|9|[0-9][0-9]|[0-9][0-9][0-9])\.ffn_(gate|up|down)_exps.=CPU"` 表示从第 6 层开始,只卸载 gate、up 和 down MoE 层。
Llama.cpp 还引入了高吞吐模式。使用 `llama-parallel`. 了解更多 [这里](https://github.com/ggml-org/llama.cpp/tree/master/examples/parallel). 你还可以 **将 KV 缓存量化为 4 位** 例如以减少 VRAM / RAM 数据传输,这也可以让生成过程更快。
### 📐如何适配长上下文(完整 20 万)
要容纳更长的上下文,你可以使用 **KV 缓存量化** 将 K 和 V 缓存量化为更低的位数。这也可以因为减少 RAM / VRAM 数据传输而提高生成速度。K 量化允许的选项(默认是 `f16`)包括以下内容。
`--cache-type-k f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1`
你应该使用 `_1` 这些变体以获得稍高的准确率,不过会稍慢一些。例如 `q4_1, q5_1`
你也可以量化 V 缓存,但你需要 **通过以下方式编译支持 Flash Attention 的 llama.cpp** 支持,方法是使用 `-DGGML_CUDA_FA_ALL_QUANTS=ON`,并使用 `--flash-attn` 来启用它。然后你可以将其与 `--cache-type-k` :
`--cache-type-v f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1`
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://unsloth.ai/docs/zh/mo-xing/tutorials/glm-4.6-how-to-run-locally.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.