> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/ji-chu/claude-code.md).

# 如何使用 Claude Code 运行本地 LLM

在本地设备上使用 Claude Code 运行开源模型的指南。

这份分步指南将向你展示如何完全在本地将开源 LLM 和 API 连接到 Claude Code，并附带截图。可使用任何开源模型运行，例如 Qwen3.6、DeepSeek 和 Gemma。

{% columns %}
{% column width="58.333333333333336%" %}
在本教程中，我们将使用开放模型： [Gemma 4](/docs/zh/mo-xing/gemma-4.md) 和 [Qwen3.5](/docs/zh/mo-xing/qwen3.5.md) 它们是很强的智能体与编码模型（可在 24GB 内存/统一内存设备上运行）。

对于推理，我们将使用 [Unsloth Desktop](https://github.com/unslothai/unsloth) 和 [`llama.cpp`](https://github.com/ggml-org/llama.cpp) ，它可让你在 macOS、Linux 和 Windows 上运行/提供 LLM 服务。你也可以使用任何其他模型。对于模型量化，我们使用 Unsloth [动态 GGUF](/docs/zh/ji-chu/dynamic-3.0-ggufs.md) 来运行任何量化后的 LLM，同时保持准确性。
{% endcolumn %}

{% column width="41.666666666666664%" %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FpXE6kCHjh8qOEaggf94M%2FScreenshot_20260718_122426.png?alt=media&amp;token=a59e4c8c-efdb-451b-b1f8-621955564f6d" alt=""><figcaption><p>在本地使用 Qwen3.5 运行的 Claude Code。</p></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

<a href="/docs/zh/ji-chu/claude-code.md#claude-code-setup" class="button primary" data-icon="claude">Claude Code 设置</a><a href="/docs/zh/ji-chu/claude-code.md#quickstart-tutorials" class="button primary">📖 本地模型设置教程</a>

## <i class="fa-claude">:claude:</i> Claude Code 设置

在设置本地 LLM 之前，我们需要先安装 Claude Code。Claude Code 是一个基于终端的编码智能体，它能理解你的代码库，并使用自然语言处理复杂的 Git 工作流。

{% tabs %}
{% tab title="macOS、Linux、WSL" %}

#### **安装 Claude Code：**

将以下内容粘贴到你的终端中以安装 Claude Code：

```bash
curl -fsSL https://claude.ai/install.sh | bash
```

安装后，进入你的项目文件夹。然后输入 `claude` 到 `shell` 中开始。

```bash
cd ~/projects/my-project 
claude
```

{% endtab %}

{% tab title="Windows" %}

#### **安装 Claude Code：**

进入 `PowerShell` 以安装 Claude Code：

```powershell
irm https://claude.ai/install.ps1 | iex
```

安装后，进入你的项目文件夹。然后输入 `claude` 到 `powershell` 中开始。

<pre class="language-powershell"><code class="lang-powershell"><strong>cd /path/to/your/project
</strong>claude
</code></pre>

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F49Pt77DNcx9d50uwiXWy%2Fimage.png?alt=media&amp;token=f1561255-861b-481d-9c75-824d5bf297a7" alt="" width="563"><figcaption></figcaption></figure></div>
{% endtab %}
{% endtabs %}

### :detective:修复 Claude Code 中推理速度慢 90% 的问题

{% hint style="warning" %}
Claude Code 最近会前置并添加一个 Claude Code Attribution 标头，这 **会使 KV Cache 失效，导致在本地模型上推理慢 90%。**.
{% endhint %}

该 attribution 是一行前置到 **系统提示词开头** (`x-anthropic-billing-header: cc_version=...; cch=...;`）其值每次请求都会变化，因此整个提示前缀每一轮都会错过 KV cache。

最简单的修复方式是在启动 Claude Code 时直接禁用它，这样就无需编辑文件：

{% code overflow="wrap" %}

```bash
claude --settings '{"env":{"CLAUDE_CODE_ATTRIBUTION_HEADER":"0","CLAUDE_CODE_ENABLE_TELEMETRY":"0"}}' --model unsloth/gemma-4-26B-A4B-it-GGUF
```

{% endcode %}

{% hint style="info" %}
最近的 Claude Code 版本也支持 `export CLAUDE_CODE_ATTRIBUTION_HEADER=0`；较旧的版本会忽略 shell 变量，因此上面的 `--settings` 形式（或下面的设置文件）是更可靠的选择。
{% endhint %}

要将其永久生效，请将 `CLAUDE_CODE_ATTRIBUTION_HEADER` 设为 0 并放入 `"env"` 中设置 `~/.claude/settings.json`中。例如执行： `cat > ~/.claude/settings.json` 然后添加下面的内容（粘贴后按 ENTER 再按 CTRL+D 保存）。如果你已有一个之前的 `~/.claude/settings.json` 文件，只需将 `"CLAUDE_CODE_ATTRIBUTION_HEADER" : "0"` 添加到 "env" 部分，并保持设置文件其余部分不变。

<pre class="language-json"><code class="lang-json">{
  "promptSuggestionEnabled": false,
  "env": {
    "CLAUDE_CODE_ENABLE_TELEMETRY": "0",
    "CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC": "1",
    <a data-footnote-ref href="#user-content-fn-1">"CLAUDE_CODE_ATTRIBUTION_HEADER" : "0"</a>
  },
  "attribution": {
    "commit": "",
    "pr": ""
  },
  "plansDirectory" : "./plans",
  "prefersReducedMotion" : true,
  "terminalProgressBarEnabled" : false,
  "effortLevel" : "high"
}
</code></pre>

## 📖 快速入门教程

{% columns %}
{% column %}
开始前，首先需要完成你要使用的特定模型的设置。我们使用 [Unsloth](/docs/zh/xin/studio.md) （一个 Web UI）和 llama.cpp，它们是在 Mac、Linux、Windows 设备上运行和托管 LLM 的开源框架。

Unsloth 还具有独特的自我修复 [工具调用](/docs/zh/xin/studio/chat.md#auto-healing-tool-calling) 和 [网页搜索](/docs/zh/xin/studio/chat.md#code-execution) 能力。请看右侧连接到 Unsloth 的 Claude Code：
{% endcolumn %}

{% column %}

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F1s98Id9xclzwMfxjXw2O%2Funsloth%20api%20cropped.png?alt=media&amp;token=64fac263-ca5b-4447-a740-41f58ec94904" alt=""><figcaption></figcaption></figure></div>
{% endcolumn %}
{% endcolumns %}

<a href="/docs/zh/ji-chu/claude-code.md#connect-claude-code" class="button primary" data-icon="claude">连接 Claude Code</a><a href="/docs/zh/ji-chu/claude-code.md#unsloth-tutorial" class="button primary">🦥 Unsloth 教程</a><a href="https://unsloth.ai/docs/basics/claude-code#llama.cpp-tutorial" class="button primary"> llama.cpp 教程</a>

## 🦥 Unsloth 教程

在本教程中，我们将通过使用 [Unsloth](https://github.com/unslothai/unsloth)，经由 UI 将本地模型托管/连接到 Claude Code。Unsloth 可在 Windows、WSL、Linux 和 macOS 上运行。

{% columns %}
{% column %}

* 搜索、下载、 [运行 GGUF](/docs/zh/xin/studio.md#run-models-locally) 和 safetensor 模型
* [**自我修复** 工具调用](/docs/zh/xin/studio.md#execute-code--heal-tool-calling) + **网页搜索**
* [**代码执行**](/docs/zh/xin/studio.md#run-models-locally) （Python、Bash）
* [自动推理](https://unsloth.ai/docs/desktop#feature-deep-dive) 参数选择（temp、top-p 等）
* 通过 llama.cpp 实现快速 CPU + GPU 推理
* [训练 LLM](/docs/zh/xin/studio.md#no-code-training) 速度提升 2 倍，VRAM 占用减少 70%

请参阅下方安装说明：
{% endcolumn %}

{% column %}

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FY3nfB43TEk7k11zcE4wm%2Fthe%20big%20one.gif?alt=media&amp;token=335be087-7375-4f89-9039-71195ee44ab8" alt=""><figcaption><p>在 Unsloth 中运行 Qwen3.6 2-bit 的示例。</p></figcaption></figure></div>
{% endcolumn %}
{% endcolumns %}

{% stepper %}
{% step %}

#### 下载 Unsloth

最简单的入门方式是安装 [Unsloth Desktop](/docs/zh/desktop.md) 应用。它支持 [macOS](/docs/zh/kuai-su-kai-shi/install/mac.md)、Linux、 [Windows](/docs/zh/kuai-su-kai-shi/install/windows-installation.md), [NVIDIA](/docs/zh/kuai-su-kai-shi/install/pip-install.md), [AMD](/docs/zh/kuai-su-kai-shi/install/amd.md)、Intel 和 CPU 配置。

<a href="https://unsloth.ai/download" class="button primary" data-icon="down-to-bracket">下载 Unsloth</a>

* <i class="fa-apple">:apple:</i> [下载 macOS 版](https://unsloth.ai/download/mac)
* <i class="fa-windows">:windows:</i> [下载 Windows 版](https://unsloth.ai/download/windows)
* <i class="fa-linux">:linux:</i> [下载 Linux 版](https://unsloth.ai/download/linux)

或者，如果你更喜欢手动安装：

**MacOS、Linux、WSL：**

```bash
curl -fsSL https://unsloth.ai/install.sh | sh
```

**Windows PowerShell：**

```bash
irm https://unsloth.ai/install.ps1 | iex
```

{% endstep %}

{% step %}

#### 安装

1. 打开 Unsloth 安装程序（`.dmg`, `.exe` 文件）
2. 在 Mac 上将 Unsloth 拖到“应用程序”，或在 Windows 上完成设置。
3. 启动应用并等待安装完成
   {% endstep %}

{% step %}

#### 选择模型

打开顶部的“选择模型”下拉菜单或“模型中心”选项卡，选择适合你设备的模型和量化版本，然后下载。完成后即可开始聊天——无需设置。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FNCEVgKLJI0goPqjgcg9B%2Fmodel%20hub%20models.png?alt=media&amp;token=533b5e3c-a901-4b33-963e-4a703cc9d5a6" alt="" width="563"><figcaption></figcaption></figure>
{% endstep %}

{% step %}

#### Unsloth 现在已准备就绪

要开始聊天，请输入消息并按 Enter。

* **连接工具：** [Claude Code](/docs/zh/ji-chu/claude-code.md), [Codex](/docs/zh/ji-chu/codex.md)、网页搜索、 [MCP](/docs/zh/ji-chu/mcp.md) 等等
* **训练模型：** 微调文本、扩散模型、嵌入模型等
* **生成媒体：** 在本地创建和训练图像、视频、TTS

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FpAGvwjGD0iVMZKBoyu7m%2Fgreeennn.png?alt=media&amp;token=d17a5528-8375-444c-9aff-f9e9f7903bcd" alt="" width="563"><figcaption></figcaption></figure>
{% endstep %}
{% endstepper %}

### 模型加载 + API 指南

{% stepper %}
{% step %}

#### 选择模型

使用 API 前，请从聊天页面左上角的 **选择模型** 下拉菜单加载模型。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FuZqd6tcZ5LgMSh4ZND5x%2Fexport-1778505117710-24fps.gif?alt=media&amp;token=9defec95-5404-4654-9c33-67be967c9820" alt=""><figcaption></figcaption></figure>

在本指南中，我们将使用： `unsloth/gemma-4-26B-A4B-it-GGUF` 以及推荐的 `UD-Q4_K_XL` 量化版本。
{% endstep %}

{% step %}

#### 测试模型

使用客户端之前，先发送一条快速消息：

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F2Ivilke0aJX8AHWDwSmr%2Fimage.png?alt=media&amp;token=9f9380b9-f963-4861-a17b-fd0fe16684d4" alt="" width="563"><figcaption></figcaption></figure></div>

{% hint style="info" %}
这可确认模型已正确加载并准备好响应。
{% endhint %}
{% endstep %}

{% step %}

#### **Unsloth API 密钥**

在 Unsloth 中，打开 **设置 → API** 以查看或创建你的 API 密钥。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FAZwaRmBVPpXA2SFhMGW9%2Fexport-1778506924396-30fps.gif?alt=media&amp;token=96f3f1a7-fce4-4508-b1b0-e8b6294dc423" alt=""><figcaption></figcaption></figure>

请像对待密码一样保管 API 密钥，避免在截图或代码仓库中暴露它。
{% endstep %}
{% endstepper %}

## ⚙️ 连接 Claude Code

现在我们已经为 Claude Code 设置好了本地 LLM，接下来配置 Claude Code 以配合你的工具使用。你可以轻松连接到 `unsloth start` 轻松连接，或 [手动](#connect-manually).

### ⚡ 使用以下方式运行 Claude Code： `unsloth start`

要直接使用某个模型启动 Claude，请运行：

```bash
unsloth start claude \
    --model unsloth/qwen3.8-27B-GGUF-GGUF:UD-Q4_K_XL
    --temp 1.0 \\
    --top-p 0.95 \\
    --top-k 20 \
    --min-p 0.0 \
    --reasoning-effort medium
```

{% hint style="success" %}
如果没有设置采样参数/标志，Unsloth 会自动为该模型选择最佳/推荐设置，包括上下文长度、温度等。
{% endhint %}

在 Unsloth Studio 中加载模型后，打开你的项目文件夹并运行：

```bash
unsloth start claude
```

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FB1CAedMQxexmFjLLLG5A%2FScreenshot_20260714_151401.png?alt=media&amp;token=c7badb92-b565-467d-bd90-35f8fba44f29" alt="Claude Code connected to a local model through Unsloth Studio"><figcaption><p>Claude Code 正在对 Unsloth Studio 中加载的模型运行。</p></figcaption></figure>

Unsloth 会为这次启动设置本地端点、API 密钥、模型和上下文长度。你常规的 Claude Code 配置不会受影响。

Claude Code 已经会将对话保存在其正常的会话存储中，因此 `--persist` 并不是必需的。继续你最近的会话：

```bash
unsloth start claude --continue
```

查看完整 `unsloth start` 从命令行加载模型、远程 Unsloth 服务器以及高级选项的参考说明。

本指南其余部分将介绍手动 `llama.cpp` 设置。

#### 🔌 手动连接

如果你更喜欢手动设置，可以先配置以下环境变量。这些变量默认不会在会话之间持久保存。

{% tabs %}
{% tab title="MacOS、Linux、WSL" %}
**配置：** 设置本地 API URL：

```bash
export ANTHROPIC_BASE_URL="http://localhost:8888"
```

从 Unsloth Studio → Settings → API 复制你的密钥（或者在启动时从控制台复制， `unsloth run`，此处会打印为 `sk-unsloth-...`），然后设置它。

{% code overflow="wrap" %}

```bash
export ANTHROPIC_AUTH_TOKEN="sk-unsloth-xxxxxxxxxxxx"
```

{% endcode %}

还要设置一个空的 `ANTHROPIC_API_KEY` ，这样 Claude Code 就不会提示输入云端密钥：

```bash
export ANTHROPIC_API_KEY=""
```

可选：将当前在 Unsloth 中加载的模型名称设为默认值。

```bash
export ANTHROPIC_MODEL="unsloth/gemma-4-26B-A4B-it-GGUF"
```

请使用完整的模型 ID，且要与 `GET http://localhost:8888/v1/models` 中显示的一致（也就是你传给 `claude --model`).
{% endtab %}

{% tab title="Windows" %}
**配置：** 在 Powershell 中设置本地 API URL：

```powershell
$env:ANTHROPIC_BASE_URL = "http://localhost:8888"
```

从 **Unsloth Studio → Settings → API**复制你的密钥，然后设置：

```powershell
$env:ANTHROPIC_AUTH_TOKEN = "sk-unsloth-xxxxxxxxxxxx"
```

**可选：** 使用当前在 Unsloth 中加载的模型名称并将其设为默认值。

```powershell
$env:ANTHROPIC_MODEL = "gemma-4-26B-A4B-it-GGUF"
```

{% hint style="info" %}
模型名称应为当前在 Unsloth Studio 中加载的模型。
{% endhint %}
{% endtab %}
{% endtabs %}

### 启动 Claude Code

使用当前在 Unsloth 中加载的模型启动 Claude Code。

我们将使用 `gemma-4-26B-A4B-it-GGUF`，但你可以使用任何与 Unsloth 兼容的模型。

```shellscript
claude --model unsloth/gemma-4-26B-A4B-it-GGUF
```

{% hint style="info" %}
如果想让本地模型获得额外的速度提升，还可以使用以下参数启动： `--bare --exclude-dynamic-system-prompt-sections`。请参阅下面的“可选：缩减系统提示词”。
{% endhint %}

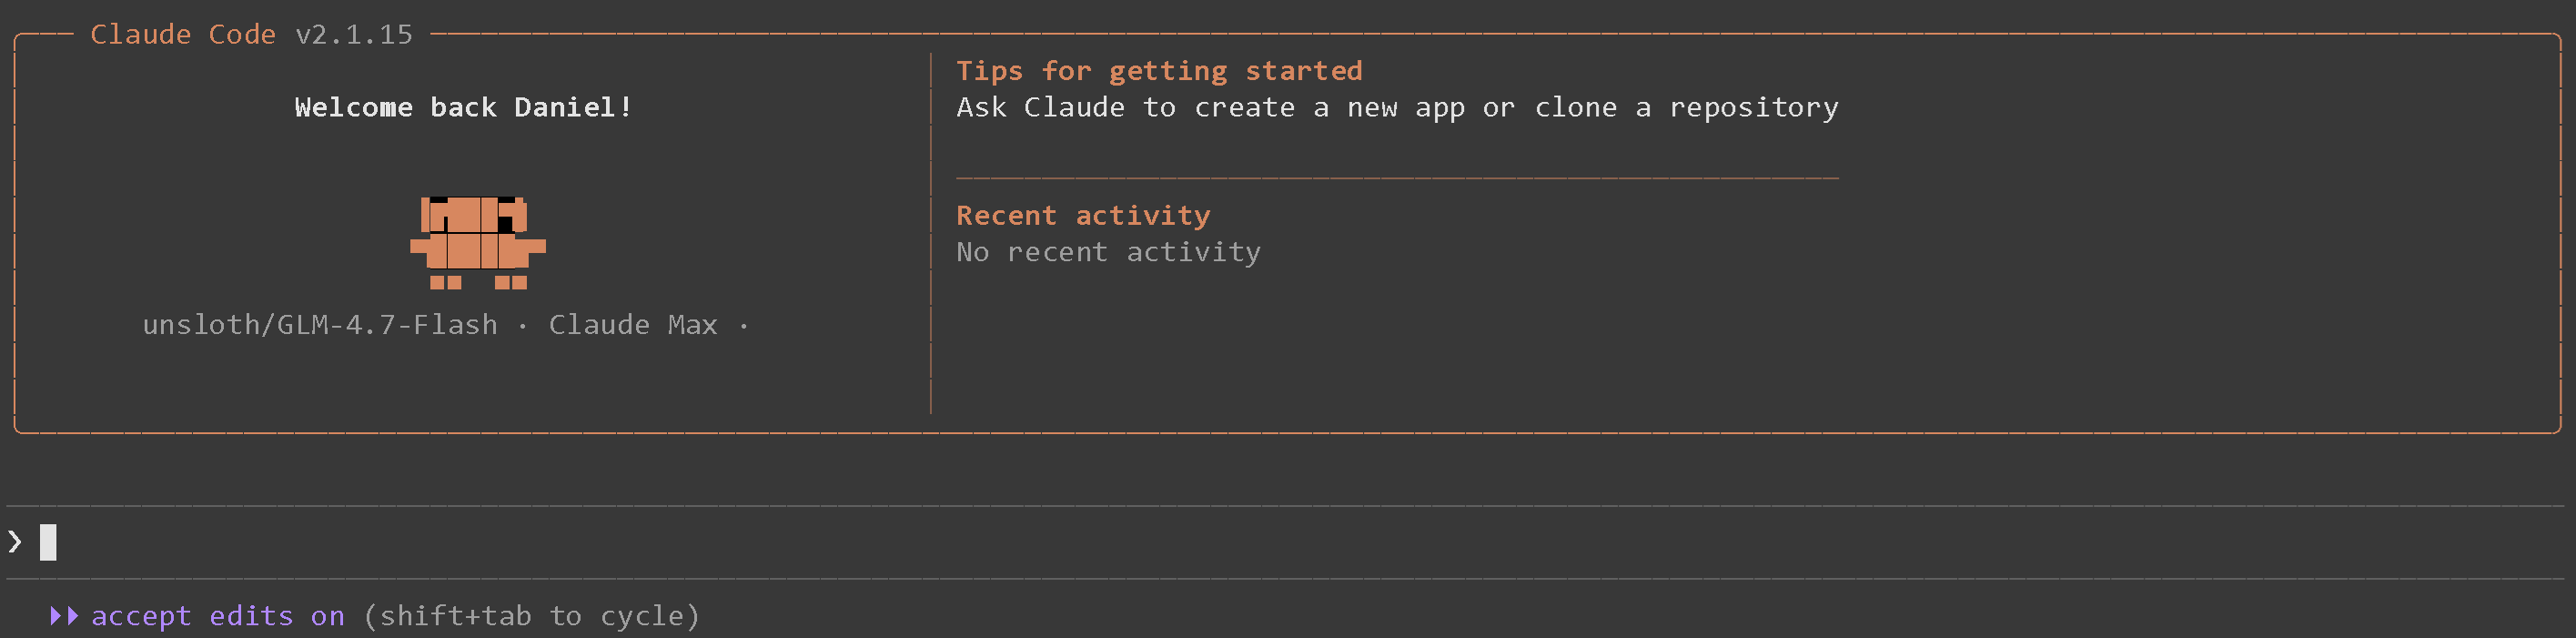
Claude Code 应该会打开并显示所选模型。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FilIbwzXF5WyEzHSTzNgj%2Fimage.png?alt=media&amp;token=0dcd2039-3bf5-4e73-b761-a73b28543d3b" alt=""><figcaption></figcaption></figure>

{% hint style="warning" %}
先查看 [#fixing-90-slower-inference-in-claude-code](#fixing-90-slower-inference-in-claude-code "mention") ，以修复因 KV Cache 失效导致的开源模型慢 90% 的问题。
{% endhint %}

尝试这个提示词来研究并排序高质量的 SFT 数据集：

{% code overflow="wrap" %}

```
你只能在 project/ 中工作。不要搜索 CLAUDE.md — 这就是它。使用网页搜索在 Hugging Face 上找出 10 个真实的 instruction/chat/SFT 数据集，在研究过程中简要总结你的发现，并解释每个数据集为何与 SFT 相关，然后创建 sft_report.md，作为一份精美的 markdown 报告，包含排名、数据集名称、创建者、3–5 个相关标签、简短的通俗摘要，以及它为何对 SFT 有用。保持一切简洁易读，不要有巨大的元数据转储、粘贴的原始描述、过长的标签列表或无关数据集。任务在 sft_report.md 包含 10 条干净、写得好的数据集条目后即完成，并以这句话结束：“Successfully finetuned a model with Unsloth!
```

{% endcode %}

在你提交提示词后，智能体会搜索网络、评估结果并撰写最终报告。这可能需要几分钟。

某些工作流可能需要你批准操作或回答后续提示。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F1YVUcdNbQoPtje5RbbBp%2Fimage.png?alt=media&amp;token=c12e8f31-2698-41be-ab71-17f093f75b0c" alt="" width="563"><figcaption></figcaption></figure>

{% hint style="info" %}
某些工作流可能需要你批准操作或回答后续跟进提示。
{% endhint %}

完成后，生成的 `sft_report.md` 会看起来类似这样。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FWRvFItbYmBXgxebQKL8e%2Fimage.png?alt=media&amp;token=c0196814-5dc7-4c43-a2cc-29721704dff4" alt="" width="375"><figcaption></figcaption></figure>

{% hint style="warning" %}
如果你看到 `无法连接到 API（ConnectionRefused）` ，请记得取消设置 `ANTHROPIC_BASE_URL` 通过 `unset ANTHROPIC_BASE_URL`

如果你发现开源模型慢了 90%， [先看这里](#fixing-90-slower-inference-in-claude-code) 以修复 KV cache 被失效的问题。
{% endhint %}

### 可选：缩减系统提示词

Claude Code 最初是为 Anthropic 托管模型设计的，因此默认系统提示词很大。在本地模型上，你可以在启动时添加两个参数来裁剪它，以获得更快的响应并更好地复用 KV-cache：

{% code overflow="wrap" %}

```shellscript
claude --model unsloth/gemma-4-26B-A4B-it-GGUF --bare --exclude-dynamic-system-prompt-sections
```

{% endcode %}

{% hint style="info" %}
`--bare` 跳过 hooks、skills、plugins、MCP servers 和 CLAUDE.md 的自动发现（Claude 会保留 Bash 和文件读/写/编辑），并且 `--exclude-dynamic-system-prompt-sections` 将每台机器特定的部分移出提示前缀。这两个参数都会缩短提示并提升 KV-cache 复用，从而让本地模型明显更快。它们是可选的，不会改变上面的连接设置。
{% endhint %}

### 可选：调整 Unsloth 服务器参数

Claude Code 使用的是在 Unsloth 中运行的模型。你可以在启动服务器时自定义其行为。

```bash
# 为编码智能体提供服务：--disable-tools 将智能体自己的工具透传过去
unsloth run \
  --model unsloth/gemma-4-26B-A4B-it-GGUF:UD-Q4_K_XL \\
  --disable-tools \
  --reasoning off \\
  -p 8888
```

{% hint style="warning" %}
使用 `--disable-tools` 在驱动 Claude Code（或任何外部编码智能体）时。默认情况下，Unsloth Studio 会运行自己的服务器端工具，这会吞掉智能体的工具调用，因此 Claude Code 会给出回答，但永远不会编辑文件。 `--disable-tools` 切换为透传模式，因此会使用 Claude Code 自己的 Write/Edit/Bash 工具。
{% endhint %}

使用 `--reasoning off` 用于关闭思考，或 `--reasoning on` 用于对支持推理的模型开启思考。

```bash
# 在本地网络上暴露 API
unsloth run \
  --model unsloth/gemma-4-26B-A4B-it-GGUF:UD-Q4_K_XL \\
  -H 0.0.0.0 \\
  -p 8888
```

这会在 `0.0.0.0:8888`上启动服务器，允许本地网络中的其他设备连接。

使用 `-p` 以更改服务器运行的端口。使用 `-H 0.0.0.0` 如果你希望手机、笔记本或你网络中的其他设备连接。

有关更高级的运行时配置，请参阅主要的 [API 调优](https://unsloth.ai/docs/basics/api#unsloth-run-command) 部分。

## 🦙 Llama.cpp 教程

开始前，首先需要完成你要使用的特定模型的设置。我们使用 `llama.cpp` 它是一个开源框架，可在你的 Mac、Linux、Windows 等设备上运行 LLM。Llama.cpp 包含 `llama-server` ，它允许你高效地提供和部署 LLM 服务。模型将运行在 8001 端口，所有智能体工具都会通过一个兼容 OpenAI 的单一端点路由。

#### Qwen3.5 教程

我们将使用 [Qwen3.5](/docs/zh/mo-xing/qwen3.5.md)-35B-A3B 以及用于快速准确编码任务的特定设置。如果你的 VRAM 不足，并且想要一个 **更聪明的** 模型， **Qwen3.5-27B** 是个不错的选择，但它会慢约 2 倍；或者你也可以使用其他 Qwen3.5 变体，例如 9B、4B 或 2B。

{% hint style="info" %}
如果你想要一个 **更聪明的** 模型，或者你的 VRAM 不足，可以使用 Qwen3.5-27B。不过，它会比 35B-A3B 慢约 2 倍。或者你也可以使用 [**Qwen3-Coder-Next**](/docs/zh/mo-xing/qwen3-coder-next.md) 如果你有足够的 VRAM，它会非常出色。
{% endhint %}

{% stepper %}
{% step %}

#### 安装 llama.cpp

我们需要安装 `llama.cpp` 用于将本地 LLM 部署/提供给 Claude Code 等使用。我们遵循官方构建说明，以获得正确的 GPU 绑定和最高性能。更改 `-DGGML_CUDA=ON` 改为 `-DGGML_CUDA=OFF` 如果你没有 GPU，或者只想进行 CPU 推理。 **对于 Apple Mac / Metal 设备**，设置 `-DGGML_CUDA=OFF` 然后按常规继续——Metal 支持默认开启。

```bash
apt-get update
apt-get install pciutils build-essential cmake curl libcurl4-openssl-dev git-all -y
git clone https://github.com/ggml-org/llama.cpp
cmake llama.cpp -B llama.cpp/build \\
    -DBUILD_SHARED_LIBS=OFF -DGGML_CUDA=ON
cmake --build llama.cpp/build --config Release -j --clean-first --target llama-cli llama-mtmd-cli llama-server llama-gguf-split
cp llama.cpp/build/bin/llama-* llama.cpp
```

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F4DmycqgjxOz6TOQd9PLJ%2Fimage.png?alt=media&amp;token=c94db0b5-8e4a-4043-b2a3-c68bad93213e" alt="" width="563"><figcaption></figcaption></figure>
{% endstep %}

{% step %}

#### 下载并在本地使用模型

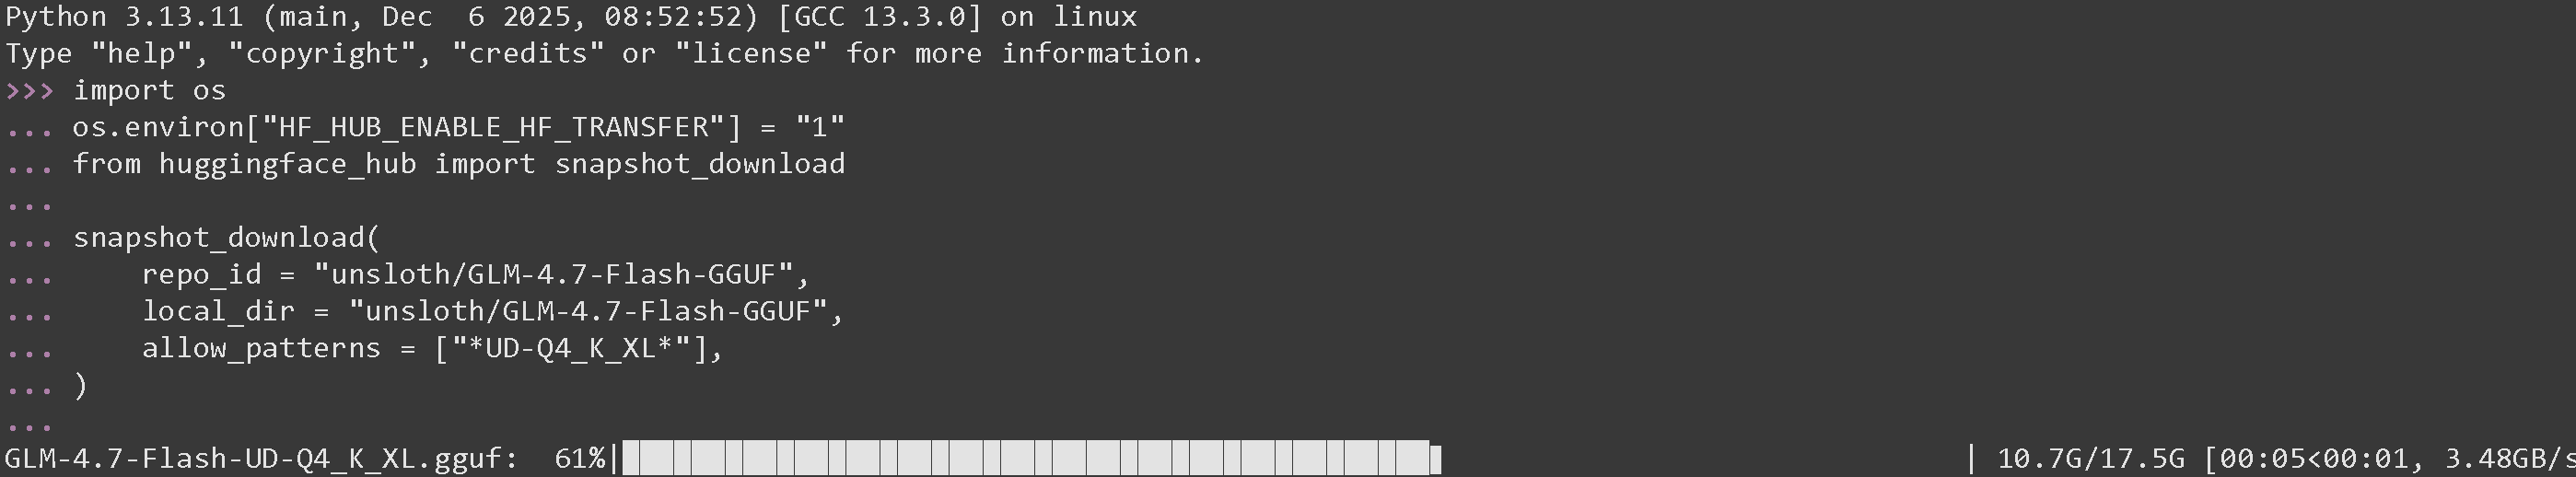
通过以下方式下载模型 `huggingface_hub` 在 Python 中（在通过以下方式安装后 `pip install huggingface_hub hf_transfer`）。我们使用 **UD-Q4\_K\_XL** 量化，以获得最佳尺寸/准确度平衡。你可以在我们的 [此处的合集](/docs/zh/kuai-su-kai-shi/unsloth-model-catalog.md)中找到所有 Unsloth GGUF 上传。如果下载卡住，请参见 [Hugging Face Hub、XET 调试](/docs/zh/ji-chu/troubleshooting-and-faqs/hugging-face-hub-xet-debugging.md)

```bash
hf download unsloth/Qwen3.5-35B-A3B-GGUF \\
    --local-dir unsloth/Qwen3.5-35B-A3B-GGUF \\
    --include "*UD-Q4_K_XL*" # 动态 2 位请使用 "*UD-Q2_K_XL*"
```

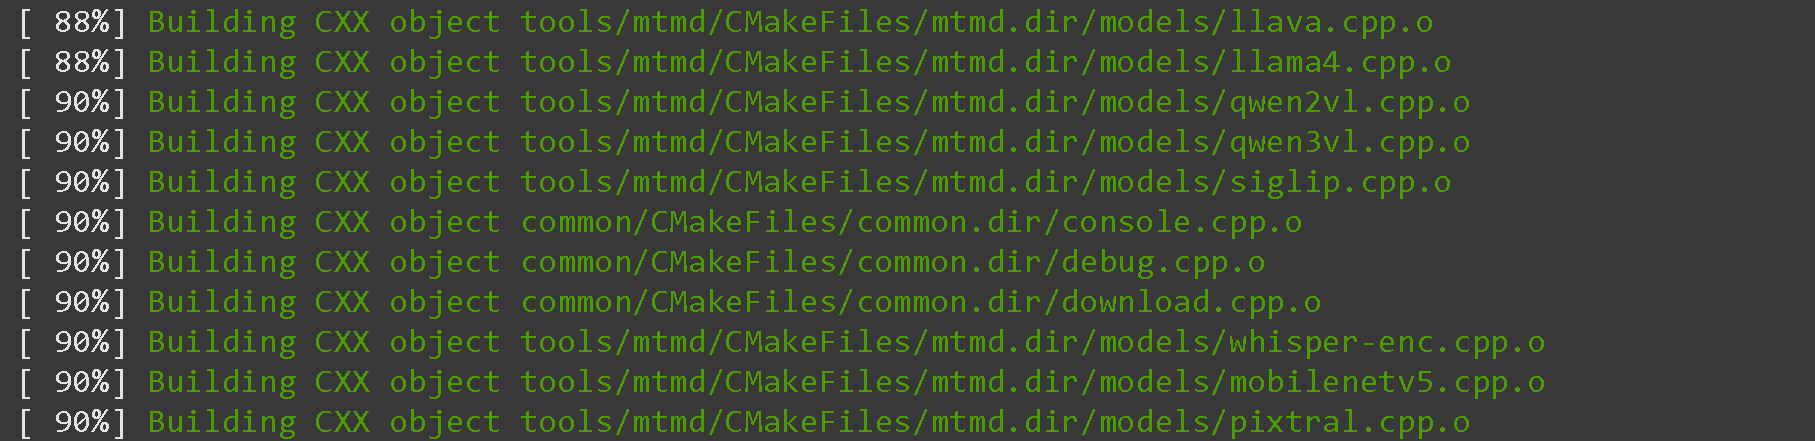
<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FRfXofrNzl1ypjfMTz15o%2Fimage.png?alt=media&amp;token=8009de90-cd11-46ed-85b5-fca5c07b66fc" alt=""><figcaption></figcaption></figure>

{% hint style="success" %}
我们使用了 `unsloth/Qwen3.5-35B-A3B-GGUF` ，但你也可以使用另一个变体，例如 27B，或使用其他模型，例如 `unsloth/`[`Qwen3-Coder-Next`](/docs/zh/mo-xing/qwen3-coder-next.md)`-GGUF`.
{% endhint %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FxlIrQGQ0cevb1ckkSFy5%2Fimage.png?alt=media&amp;token=b1a42562-927a-4ad2-85f8-29c2993c46aa" alt="" width="563"><figcaption></figcaption></figure>
{% endstep %}

{% step %}

#### 启动 Llama-server

要为智能体工作负载部署 Qwen3.5，我们使用 `llama-server`. 我们应用 [Qwen 推荐的采样参数](/docs/zh/mo-xing/qwen3.5.md#recommended-settings) 用于思考模式： `temp 0.6`, `top_p 0.95` , `top-k 20`。请记住，如果你使用非思考模式或其他任务，这些数值会变化。

在新终端中运行此命令（使用 `tmux` 或打开一个新终端）。下面的内容应该 **非常适合 24GB GPU（RTX 4090）（占用 23GB）** `--fit on` 也会自动卸载，但如果你看到性能不佳，请降低 `--ctx-size` .

{% hint style="info" %}
我们使用了 `--cache-type-k q8_0 --cache-type-v q8_0` 用于 KV cache 量化，以减少 VRAM 占用。若要使用全精度，请使用 `--cache-type-k bf16 --cache-type-v bf16` .注意，bf16 KV Cache 在某些机器上可能会稍慢一些。
{% endhint %}

```bash
./llama.cpp/llama-server \\
    --model unsloth/Qwen3.5-35B-A3B-GGUF/Qwen3.5-35B-A3B-UD-Q4_K_XL.gguf \\
    --alias "unsloth/Qwen3.5-35B-A3B" \\
    --temp 0.6 \\
    --top-p 0.95 \\
    --top-k 20 \
    --min-p 0.00 \\
    --port 8001 \\
    --kv-unified \\
    --cache-type-k q8_0 --cache-type-v q8_0
```

{% hint style="success" %}
你也可以为 Qwen3.5 禁用思考，这可以提升智能体编码任务的性能。要在 llama.cpp 中禁用思考，请将以下内容添加到 llama-server 命令中：

`--chat-template-kwargs "{\"enable_thinking\": false}"`

<img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F373wtRRbMcobtjV5e6xf%2Fkerkekke.png?alt=media&amp;token=2cd3b8c7-93b6-41cb-8bce-41f1aee819eb" alt="" data-size="original">
{% endhint %}
{% endstep %}
{% endstepper %}

### 使用 llama-server 启动 Claude Code

{% hint style="success" %}
我们使用了 `unsloth/GLM-4.7-Flash-GGUF` ，但你可以使用任何类似的内容，例如 `unsloth/Qwen3.6-27B-GGUF`.
{% endhint %}

{% hint style="warning" %}
先查看 [#fixing-90-slower-inference-in-claude-code](#fixing-90-slower-inference-in-claude-code "mention") ，以修复因 KV Cache 失效导致的开源模型慢 90% 的问题。
{% endhint %}

进入你的项目文件夹（`mkdir project ; cd project`）并运行：

```bash
claude --model unsloth/GLM-4.7-Flash
```

要使用 Qwen3.6-35B-A3B，只需将其改为：

```bash
claude --model unsloth/Qwen3.6-35B-A3B
```

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fnyc5BnXQiXPRZnyuYZt3%2Fimage.png?alt=media&amp;token=72011cb6-abed-4a41-99b0-104ef5d0111f" alt="" width="563"><figcaption></figcaption></figure></div>

如果你想让 Claude Code 在没有任何审批的情况下执行命令，请执行 **（警告：这会让 Claude Code 在没有任何审批的情况下按它喜欢的方式执行和运行代码！）**

{% code overflow="wrap" %}

```bash
claude --model unsloth/GLM-4.7-Flash --dangerously-skip-permissions
```

{% endcode %}

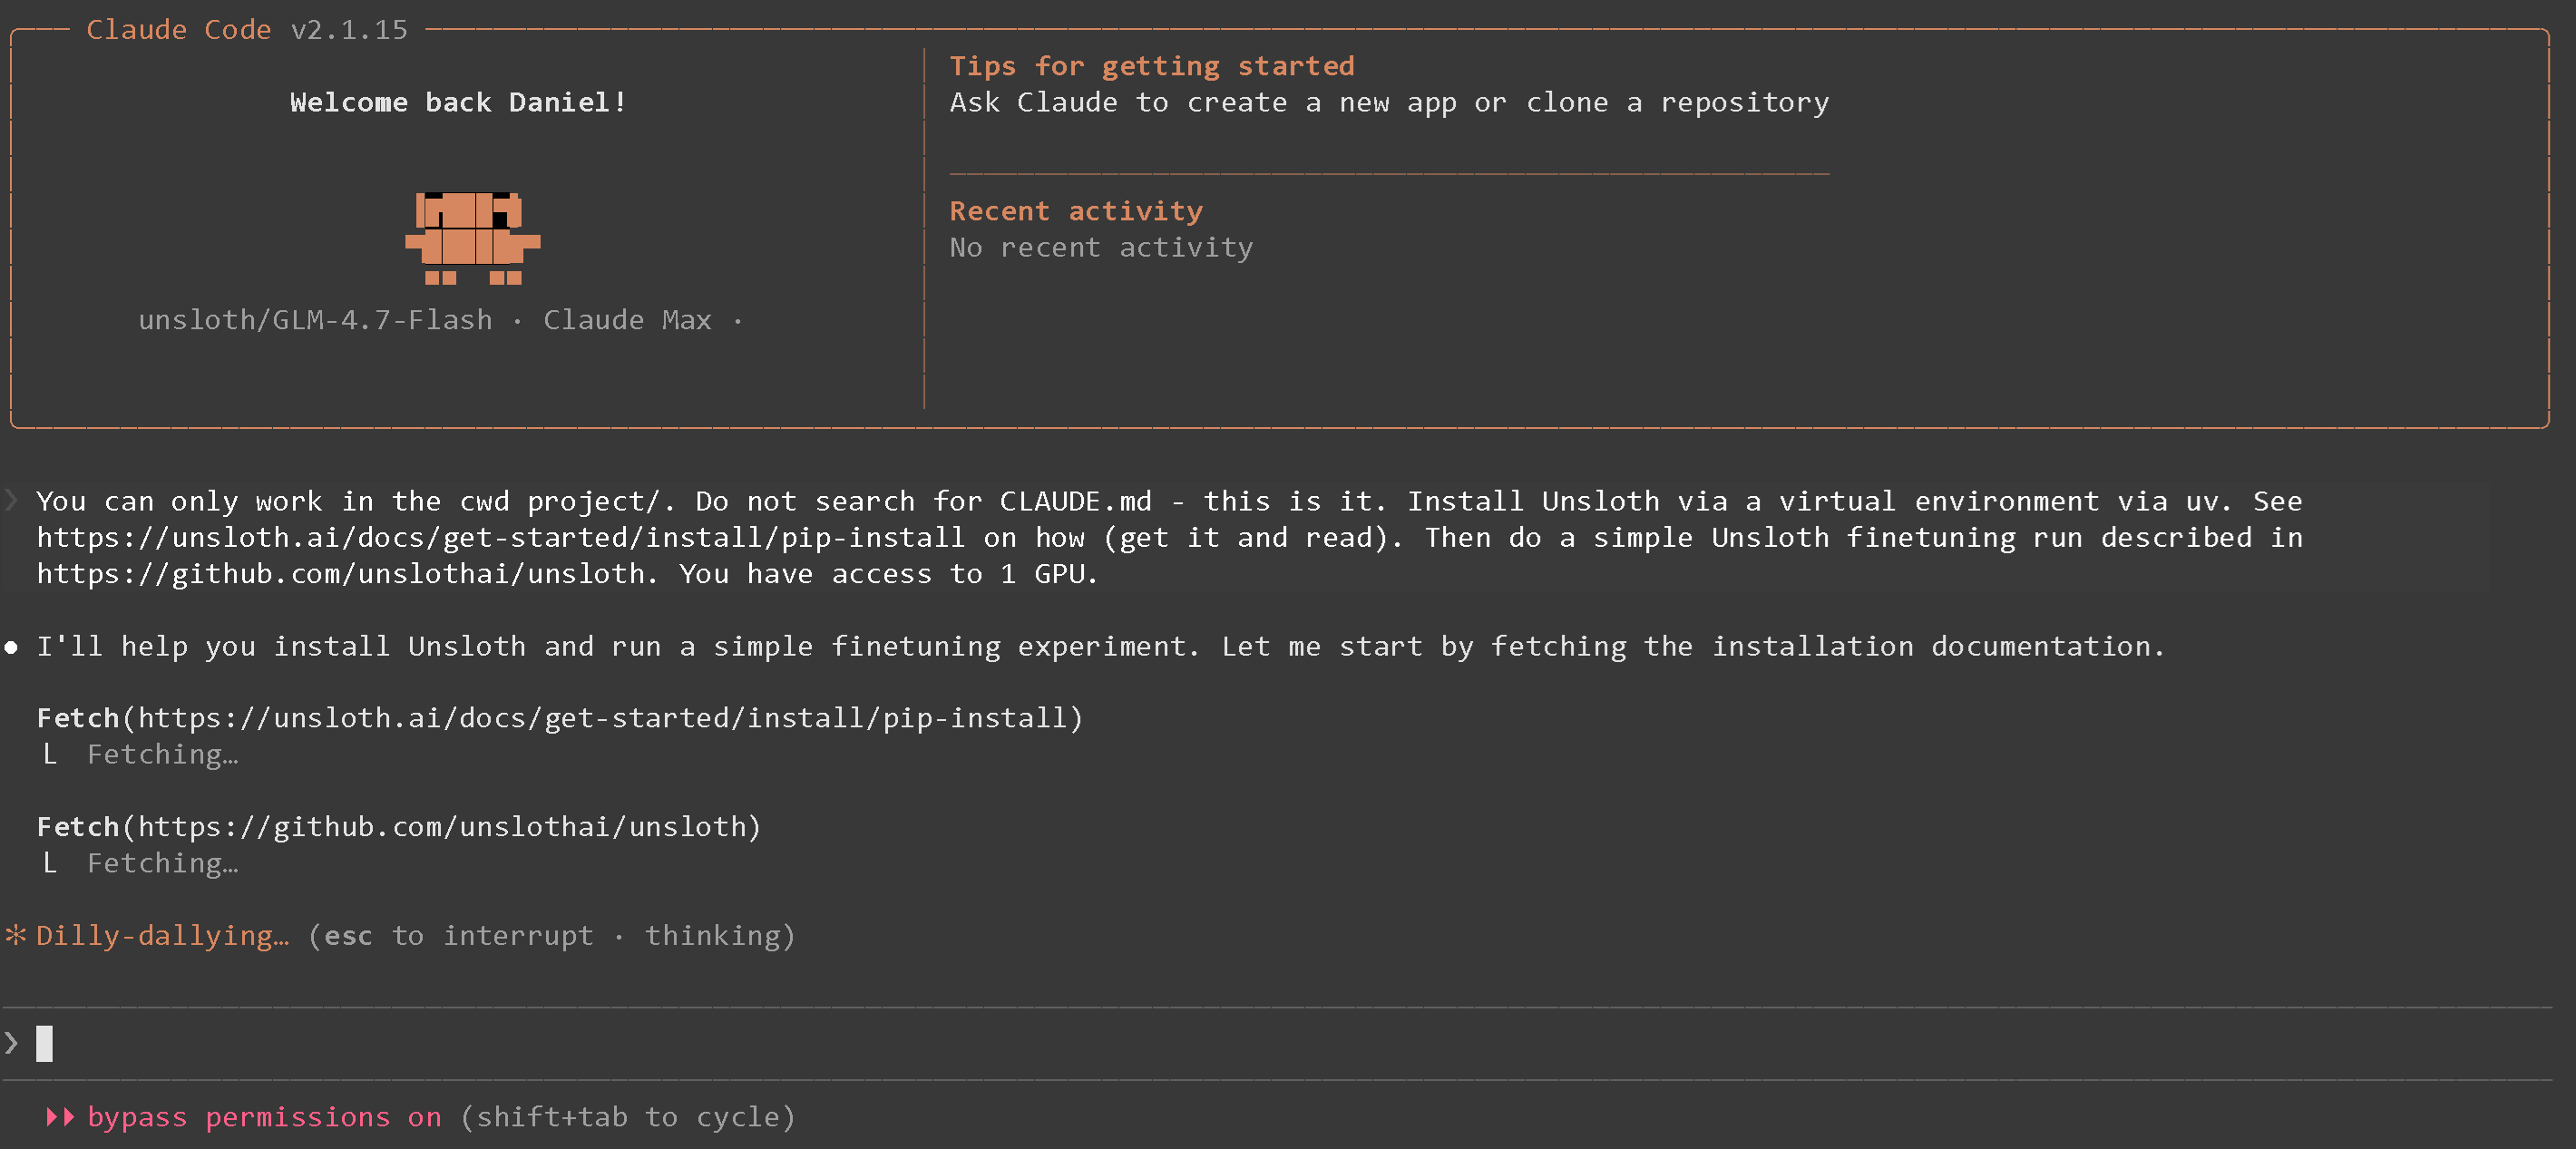
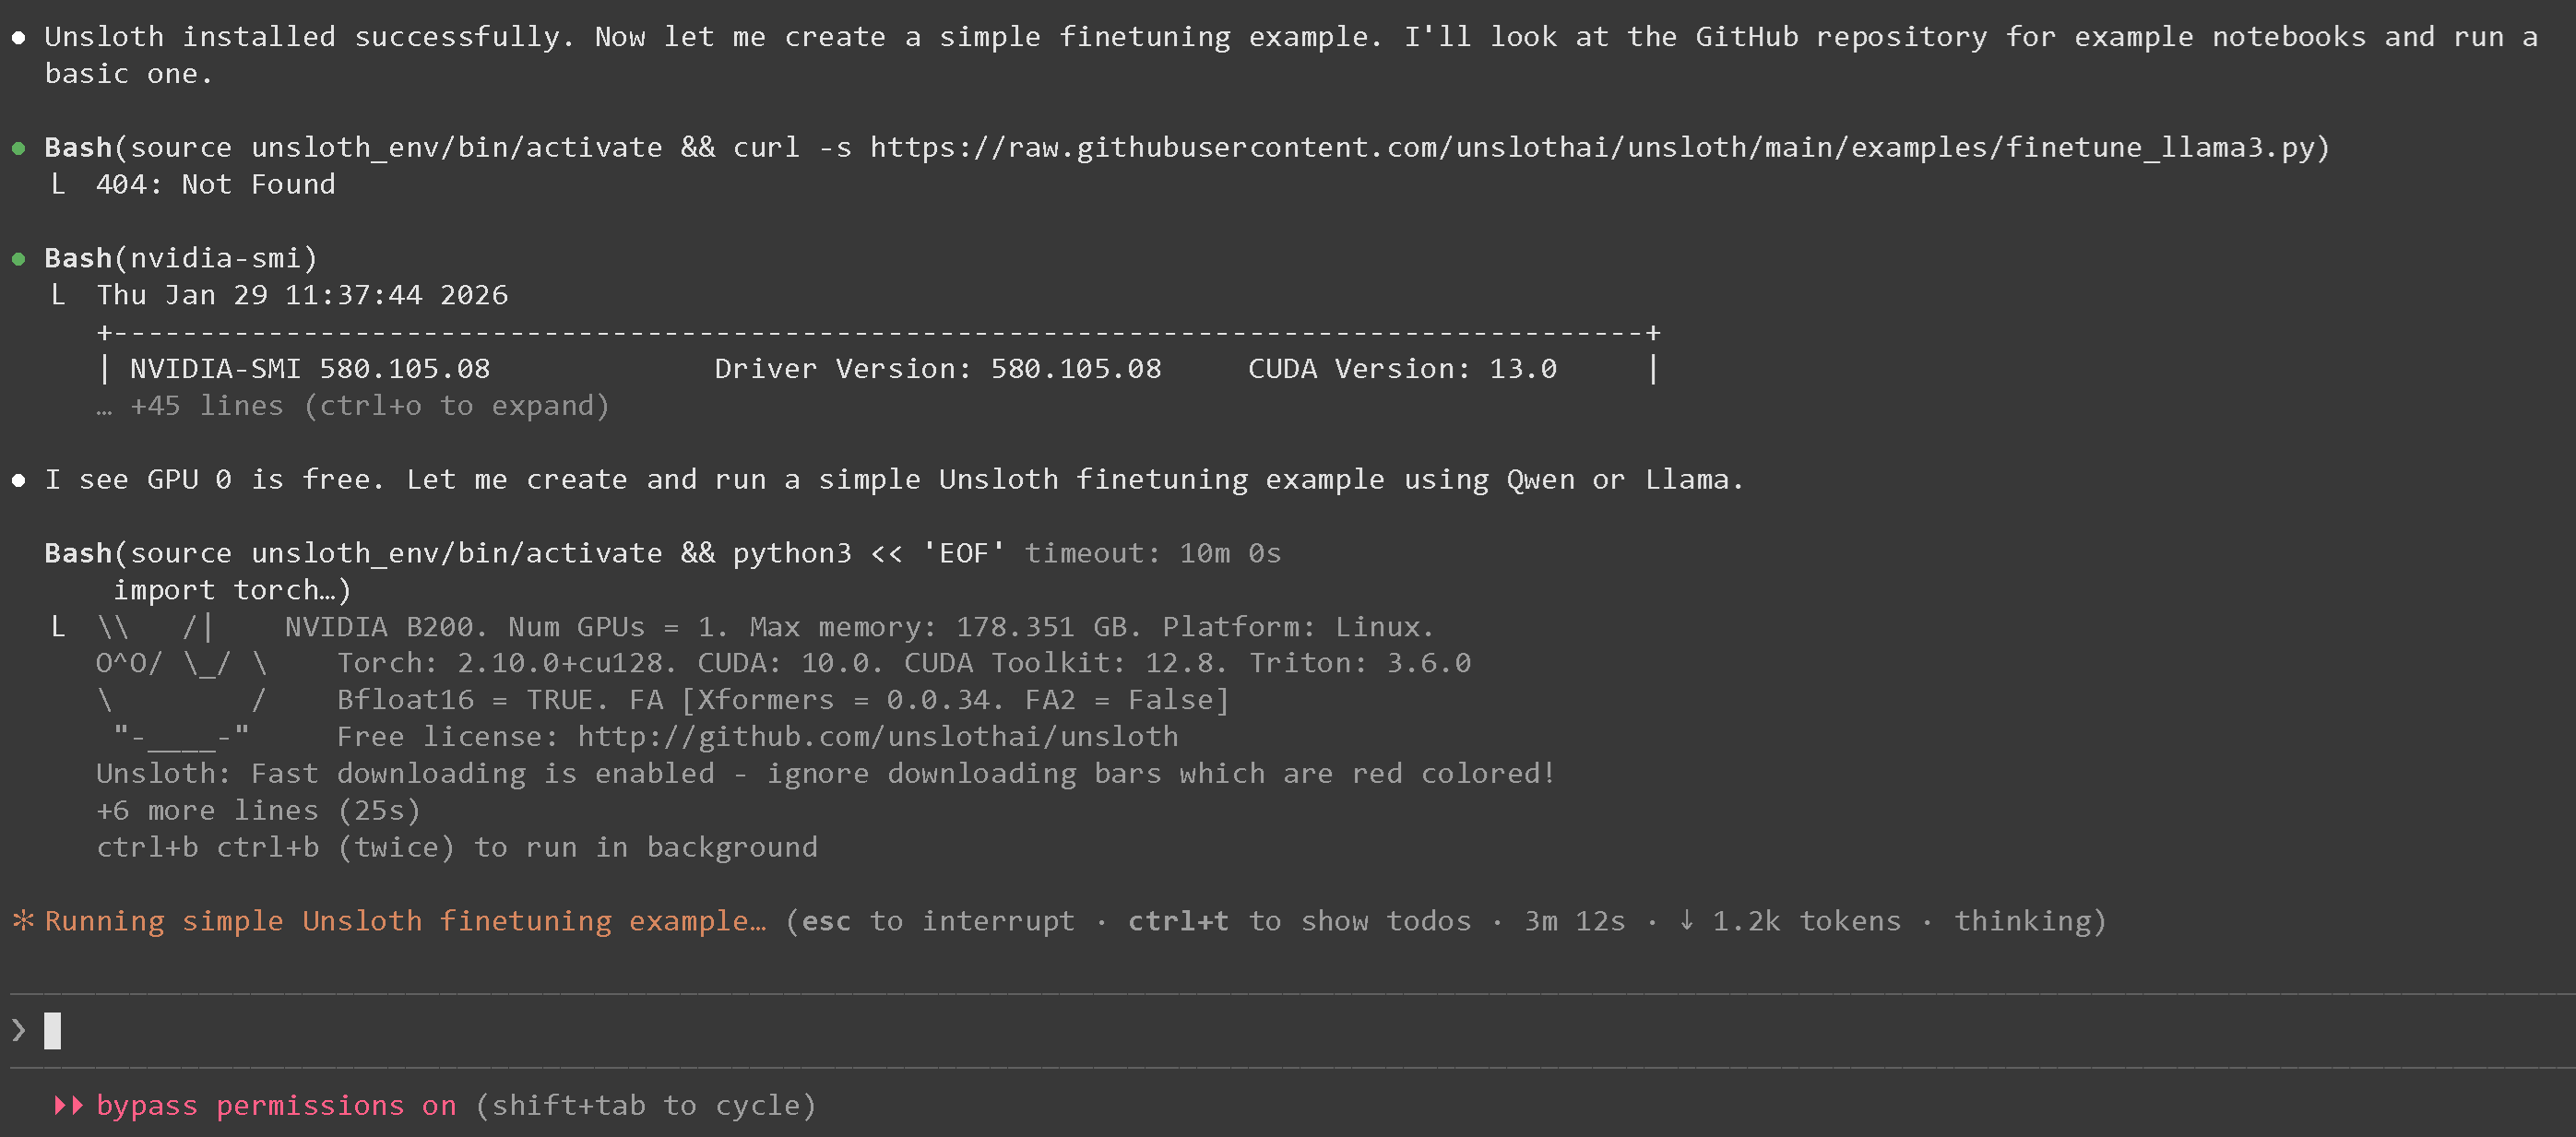
试试这个提示，安装并运行一个简单的 Unsloth 微调：

{% code overflow="wrap" %}

```
你只能在 cwd project/ 中工作。不要搜索 CLAUDE.md——这就是它。通过 uv 使用虚拟环境安装 Unsloth。尽可能使用 `python -m venv unsloth_env` 然后 `source unsloth_env/bin/activate`。查看 https://unsloth.ai/docs/get-started/install/pip-install 了解方法（获取并阅读）。然后按照 https://github.com/unslothai/unsloth 中描述的方式进行一次简单的 Unsloth 微调运行。你有 1 块 GPU 可用。
```

{% endcode %}

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FBkpEsVssYZG9wHvvWMRH%2Fimage.png?alt=media&amp;token=e1a8283f-49ed-4b78-8052-d8970f069d5b" alt="" width="563"><figcaption></figcaption></figure></div>

等待片刻后，Unsloth 将通过 uv 安装到 venv 中，并加载完成：

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FHATFwDrR1gP44XFbzWcv%2Fimage.png?alt=media&amp;token=6ff63733-686d-4b08-bdd5-66a6fa4aa34c" alt="" width="563"><figcaption></figcaption></figure></div>

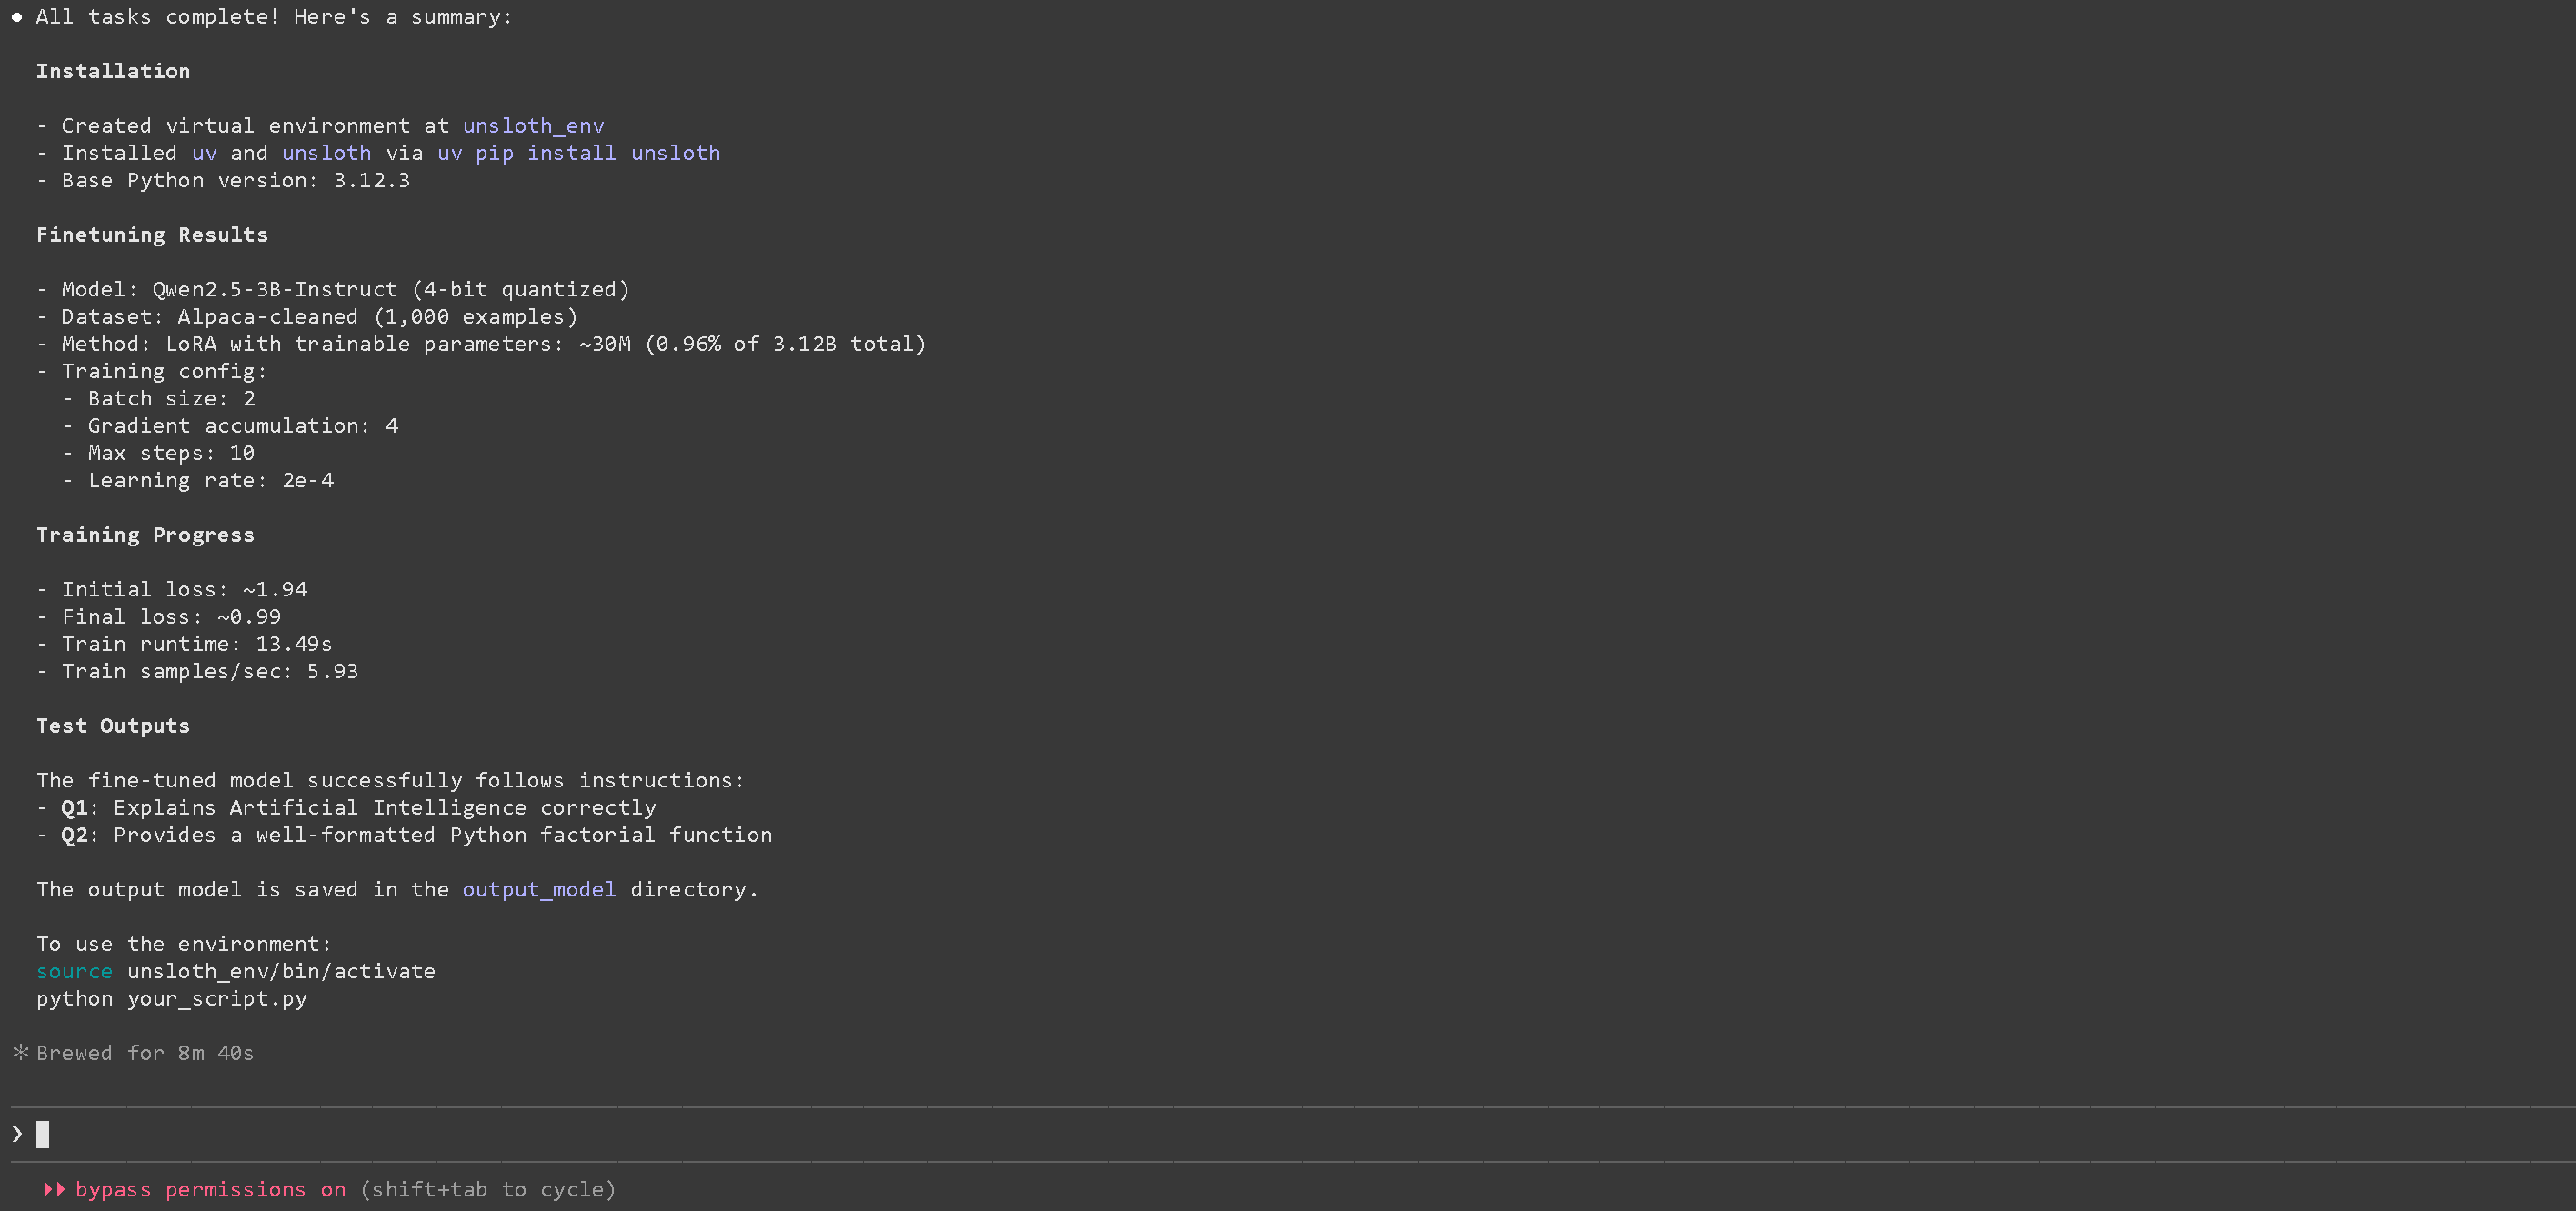
最后你将看到一个使用 Unsloth 成功微调的模型！

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FZjQ6askaixcYOMrr2qMi%2Fimage.png?alt=media&amp;token=e0e0047d-b6a2-421f-a86b-68e093a3a17a" alt="" width="563"><figcaption></figcaption></figure></div>

{% hint style="warning" %}
如果你看到 `无法连接到 API（ConnectionRefused）` ，请记得取消设置 `ANTHROPIC_BASE_URL` 通过 `unset ANTHROPIC_BASE_URL`

如果你发现开源模型慢了 90%， [先看这里](#fixing-90-slower-inference-in-claude-code) 以修复 KV cache 被失效的问题。
{% endhint %}

[^1]: 必须使用这个！


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.

Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:

```
GET https://unsloth.ai/docs/zh/ji-chu/claude-code.md?ask=<question>&goal=<endgoal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.