> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/jp/meru/reinforcement-learning-rl-guide/fp8-reinforcement-learning.md).

# FP8強化学習

Unslothを使って、FP8精度で強化学習（RL）とGRPOを学習します。

RL向けにFP8精度の学習を導入し、FP8 GRPOが今や可能に **コンシューマー向けGPU** （RTX 40、50など）。DeepSeek-R1はFP8の威力を示し、UnslothではQwen3-1.7BのFP8 GRPOが今やわずか **5GBのVRAM**.

より高速なRL推論は重要です。RLで最も計算負荷が高いワークロードだからです。私たちは [TorchAO](https://github.com/pytorch/ao) 精度を損なうことなく性能向上を実現するために

* **約1.4倍高速** 〜によるRL推論 [vLLM](https://github.com/vllm-project/vllm) ・BF16およびFP16より2倍長いコンテキスト
* **VRAM使用量60%削減** そして **10倍長い** 他のFP8 RL実装より長いコンテキスト
* Unslothは **唯一のフレームワーク** コンシューマー向けGPU（例: NVIDIA GeForce RTX 40および50シリーズ）でFP8 RL LoRAを動作させるための唯一のフレームワークです。H100、H200、B200などでも動作します。
* 次を使います: `load_in_fp8 = True` 〜内で `FastLanguageModel` FP8 RLを有効にするために。
* Qwen3-8Bは16GBのVRAMに収まりますが、無料のColabのNVIDIA Tesla T4 GPUは **FP8をサポートしていません**。そのため、私たちのノートブックでは **Qwen3-14Bが収まる24GBのL4 GPUを使用しています**.

**ノートブック：** [Qwen3-8B FP8 GRPO](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_8B_FP8_GRPO.ipynb) そして [Llama-3.2-1B FP8 GRPO](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Llama_FP8_GRPO.ipynb)

{% hint style="success" %}
おまけ： Unslothが今ではかなり少ないVRAMしか使わないことにお気づきでしょう。詳細はまもなく新しいブログで共有します。
{% endhint %}

私たちのFP8サポートはUnslothの [重み共有機能](/docs/jp/meru/reinforcement-learning-rl-guide/memory-efficient-rl.md)、さらにVRAM使用量を **50%**&#x524A;減し、 **10倍多くの** コンテキストを精度を落とさずに実現します。私たちは [vLLM](https://github.com/vllm-project/vllm) 高速推論に使用し、Unslothのような私たちの技術は [スタンバイ](/docs/jp/meru/reinforcement-learning-rl-guide/memory-efficient-rl.md) そして [Flex Attention](/docs/jp/moderu/gpt-oss-how-to-run-and-fine-tune/long-context-gpt-oss-training.md) でVRAM使用量をさらに削減します。TorchAOは汎用的なオンザフライFP8を可能にするため、Llama、Gemma、Mistralなども動作します。さらに私たちは [アップロードしました](#unsloth-fp8-uploads) ほとんどのFP8モデル（Qwen3を含む）を。

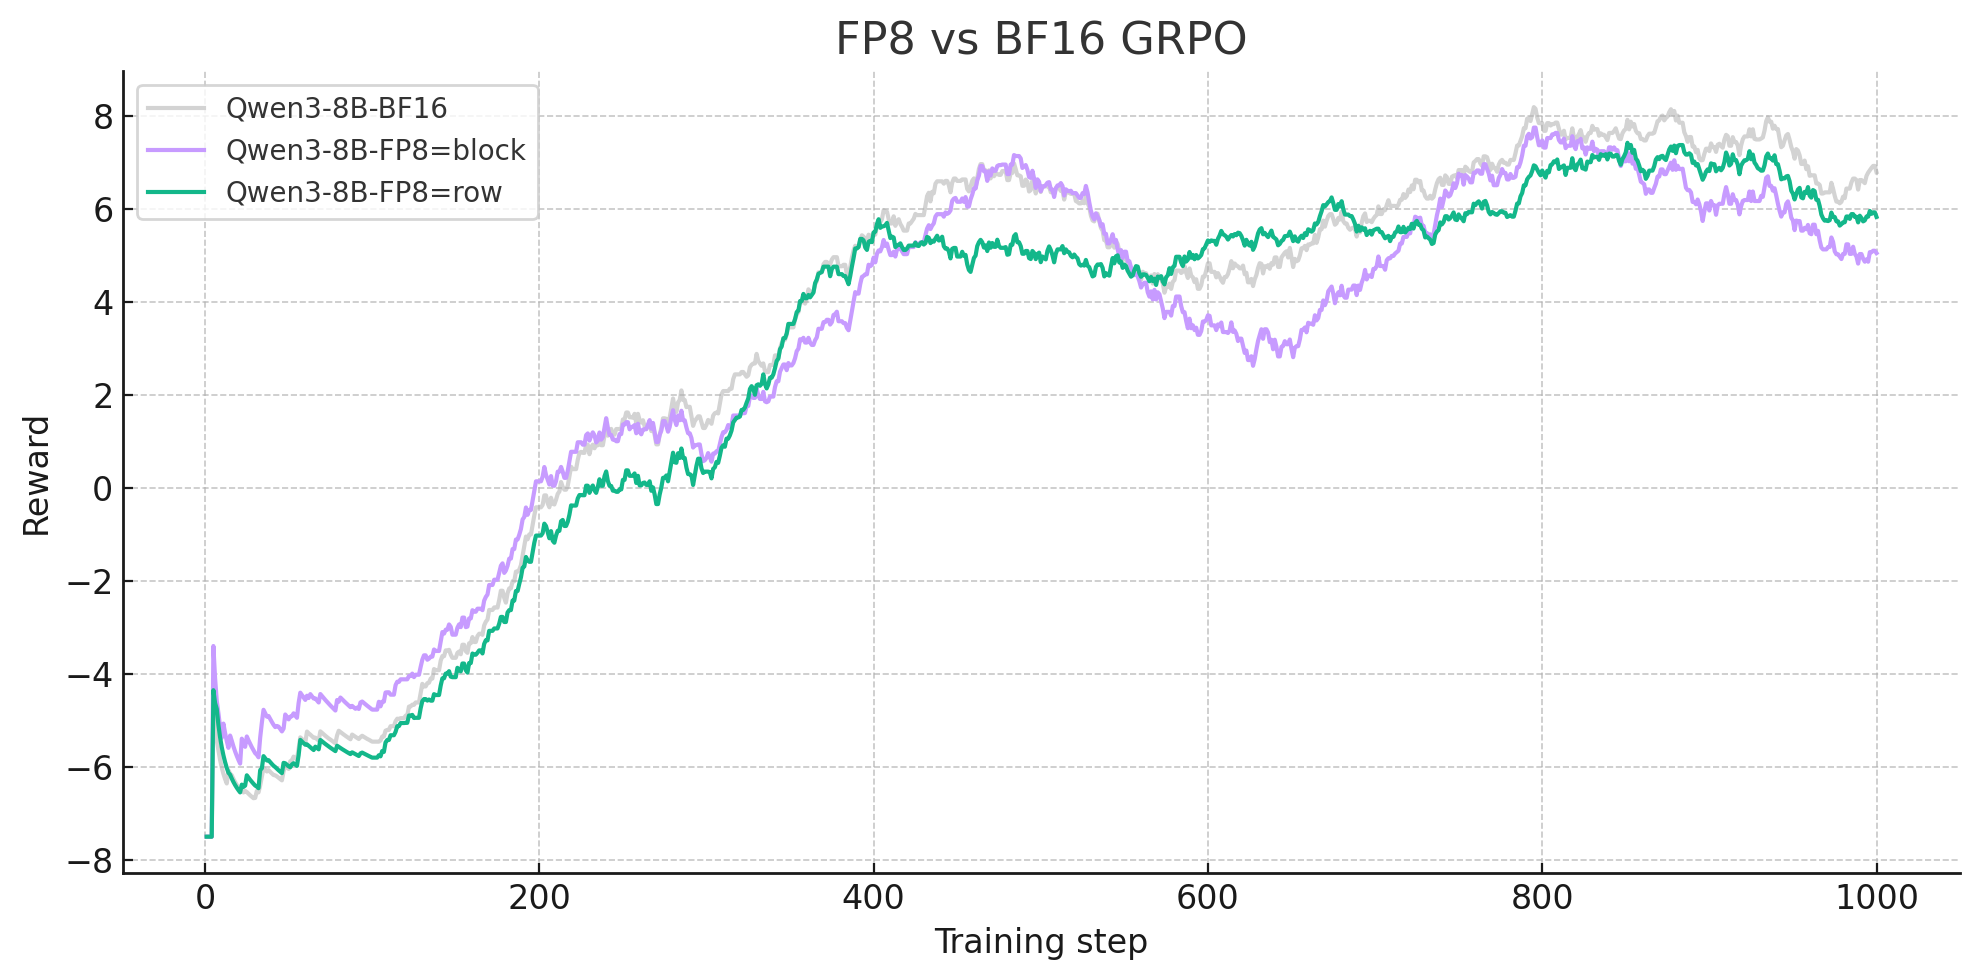
<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FNhbi7jRc6zwCAeuddBBk%2Foutput(14).png?alt=media&amp;token=80ad0712-4626-4536-aa57-29bc53b40540" alt="" width="375"><figcaption><p>報酬プロットは、FP8がBF16と同じ傾向をたどっていることを示しています</p></figcaption></figure>

### :sunflower:FP8 vs BF16の学習

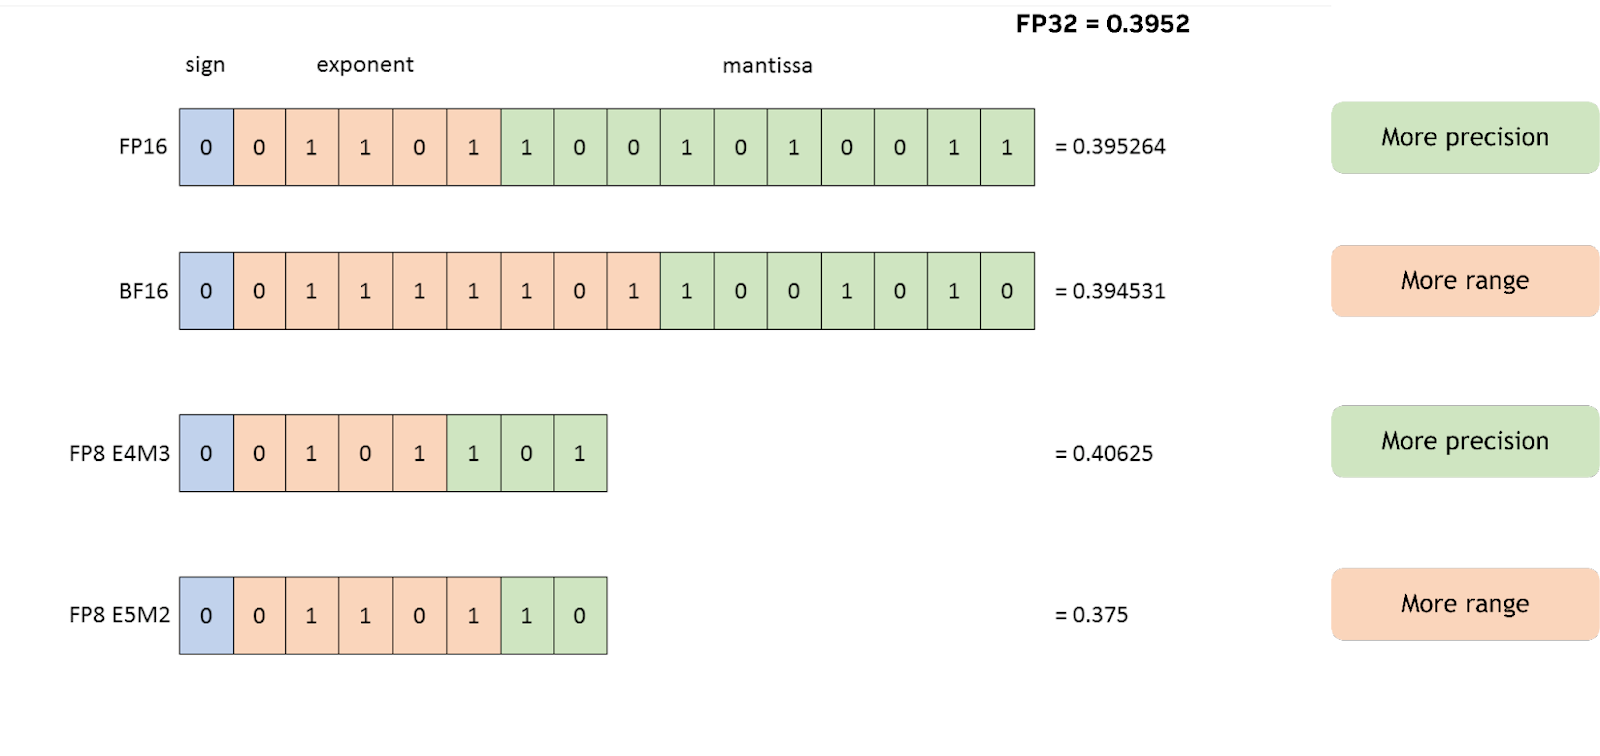
研究によれば、FP8学習はBF16の精度にほぼ匹敵し、モデルをFP8で提供する場合は **学習と提供を同じ精度で行うことは** 精度の維持に役立ちます。また、FP8とBF16を比べると、H100では1.6倍高いスループットと2倍少ないメモリ使用量が得られます。

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FApLfXUBVZSbjpPhRJG6z%2Ffp8%20f16%20quant.png?alt=media&amp;token=77a2917a-f191-44a7-8597-6796fcf24ed7" alt="" width="375"><figcaption></figcaption></figure>

#### 重みスケールとFP8タイプ

量子化学習では、低精度の重み（例: FP8）に加えて、より高精度のスケール（FP16/BF16/FP32）を保存します。元の重みは概ね次の式で復元できます： `元の重み ≈ 量子化された重み * 重みスケール`

スケールは重みの範囲をFP8で表現可能な範囲に写像します。スケールが多いほど通常は精度が向上しますが、スケールには追加の高精度メモリが必要なため、トレードオフです。 [DeepSeek R1](https://arxiv.org/abs/2501.12948)たとえば、主にブロック量子化が好まれます。

vLLMの定義する一般的なFP8タイプは3種類あります [llm-compressor](https://github.com/vllm-project/llm-compressor)。私たちはQwen3-8Bを3種類すべてでベンチマークし、スループット、MMLU Pro、GQPA Diamondも確認しました。その結果、 **FP8のブロック単位またはチャネル単位（-FP8-Dynamic）が最良です** 精度とスループットの両面で。

<table><thead><tr><th width="121">型</th><th width="225.20001220703125"></th><th width="126.4000244140625">スループット</th><th width="121.60003662109375">MMLU Pro</th><th>GQPA Diamond</th></tr></thead><tbody><tr><td></td><td>Bfloat16ベースライン</td><td>11,367</td><td><strong>62.04%</strong></td><td>28.79%</td></tr><tr><td>ブロックごと</td><td>ブロックごとのスケール（128×128）</td><td>12,041</td><td><strong>62.37%</strong></td><td><strong>29.29%</strong></td></tr><tr><td>チャネルごと</td><td>行または列ごとに1つのスケール</td><td>12,963</td><td>61.89%</td><td><strong>31.82%</strong></td></tr><tr><td>テンソルごと</td><td>テンソル全体に対して1つのスケール</td><td><strong>13,681</strong></td><td>61.83%</td><td>27.78%</td></tr></tbody></table>

### :zap:FP8性能ベンチマーク

vLLMによるUnslothのFP8 RL推論は、一般的にBF16より1.4倍高速です。モデルが大きいほど、さらに高速化が見込めます！

#### 精度・学習損失ベンチマーク

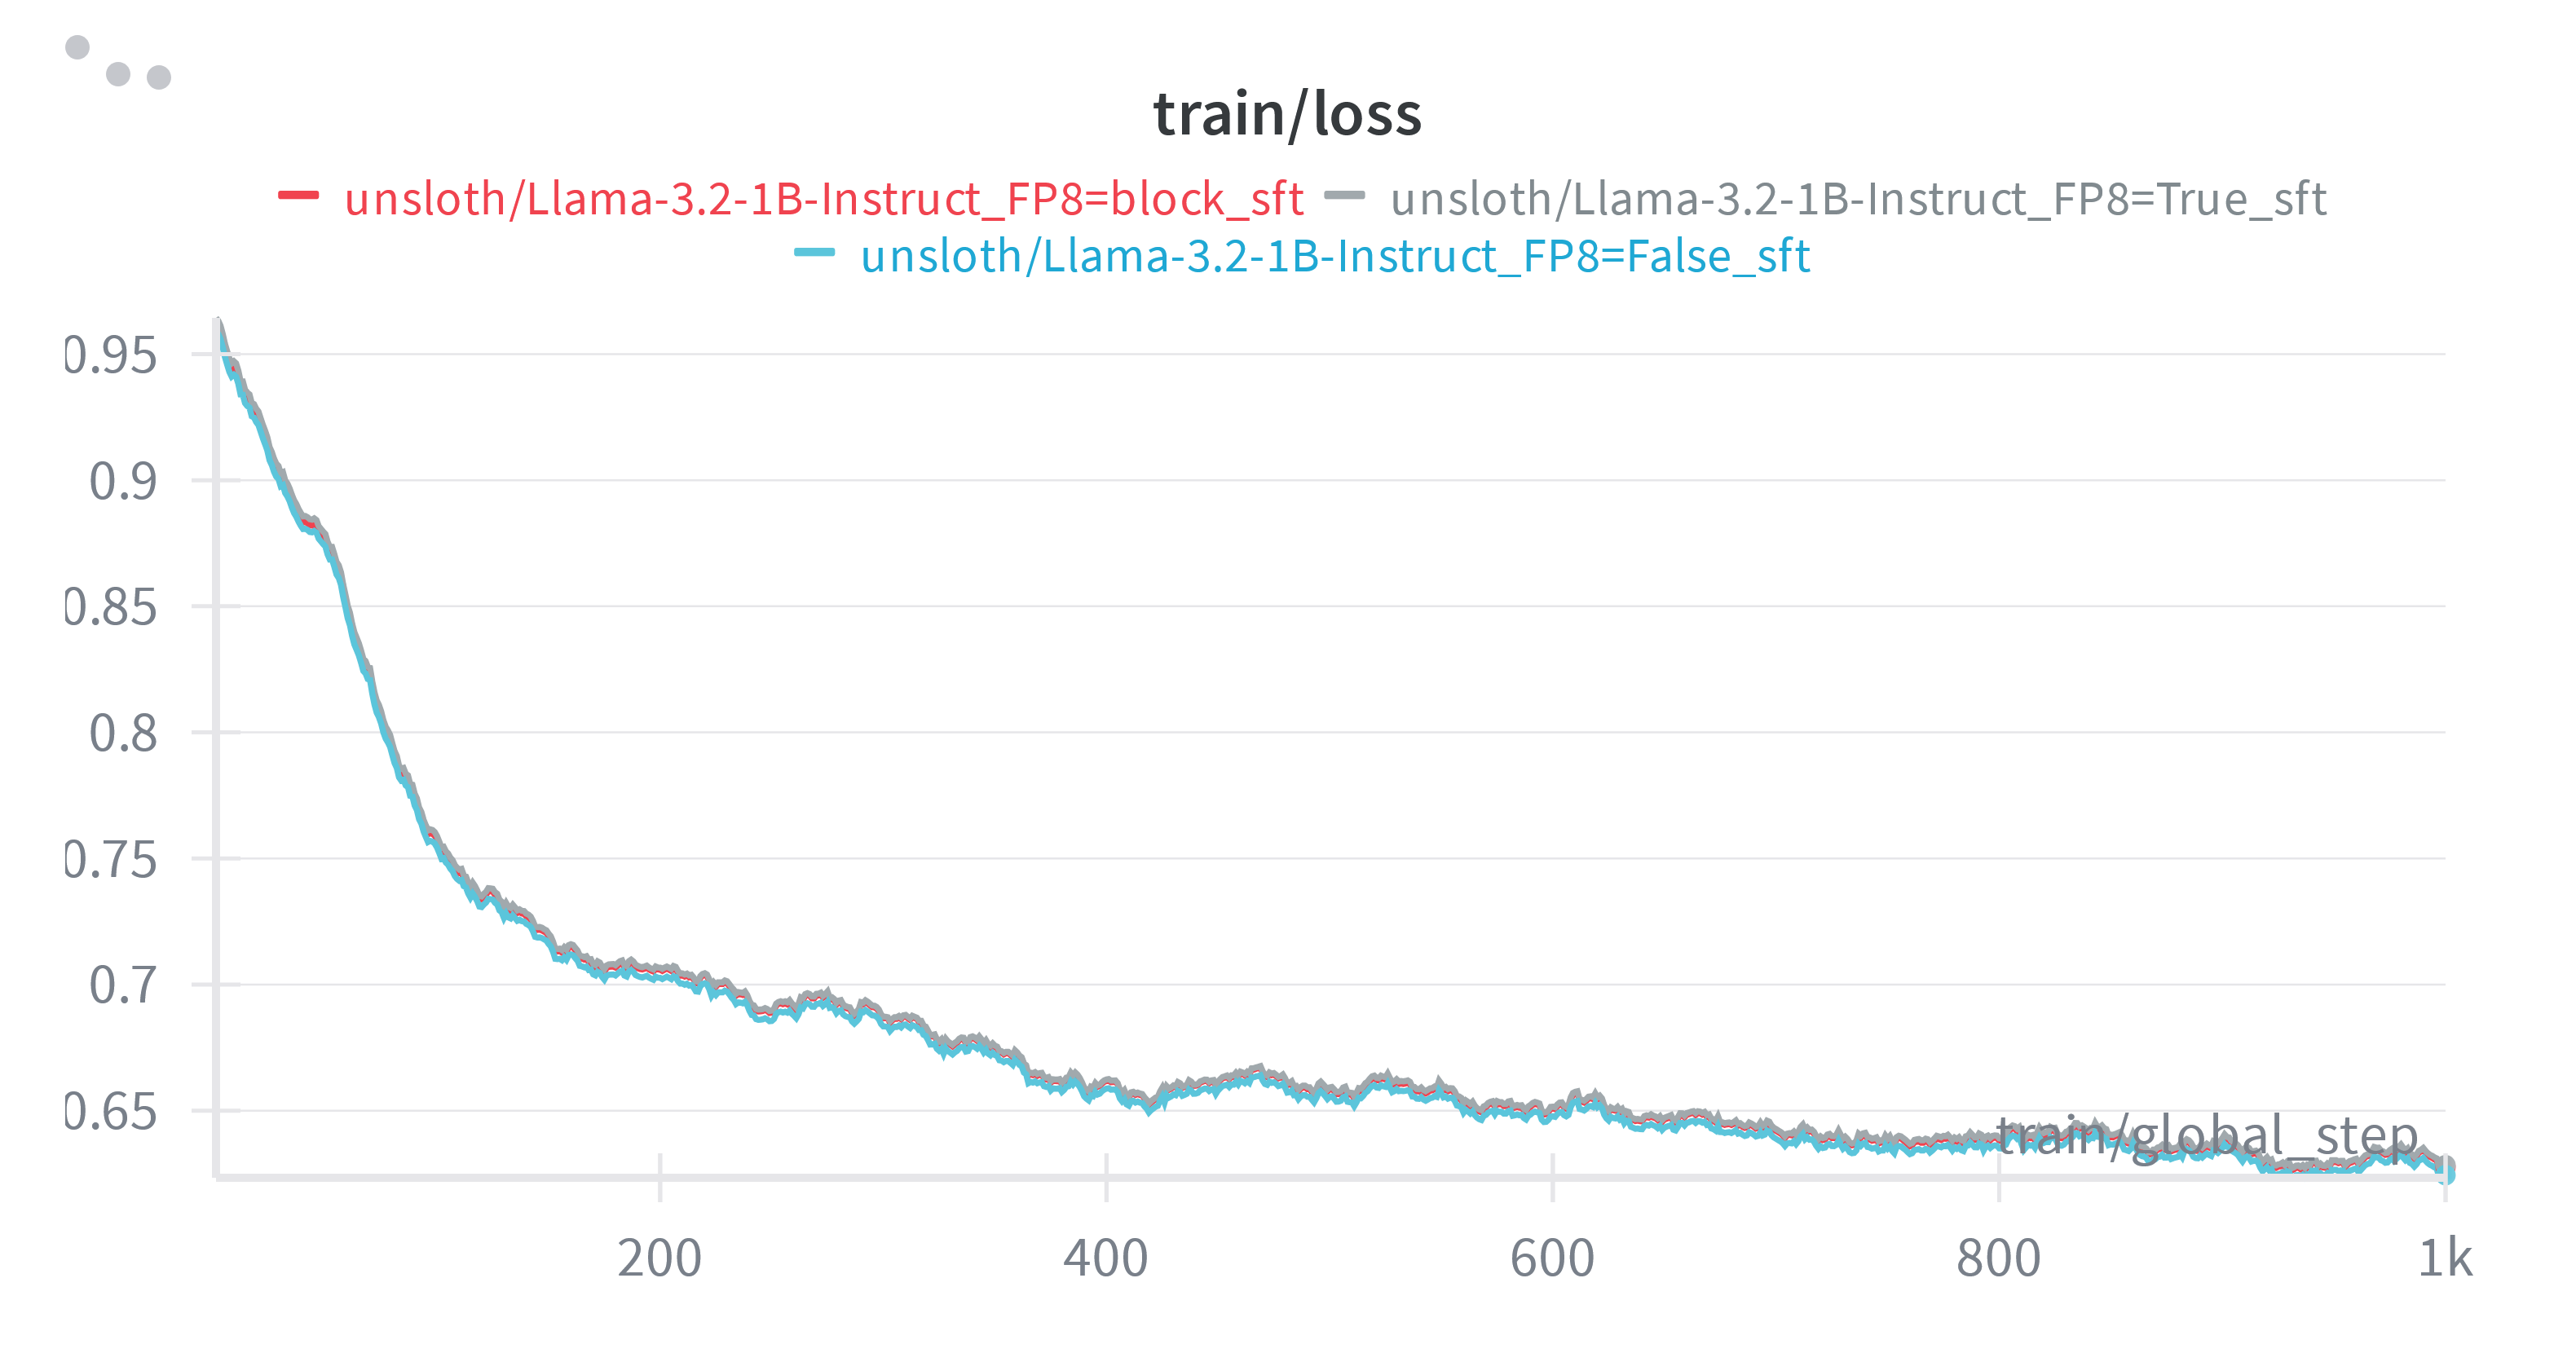
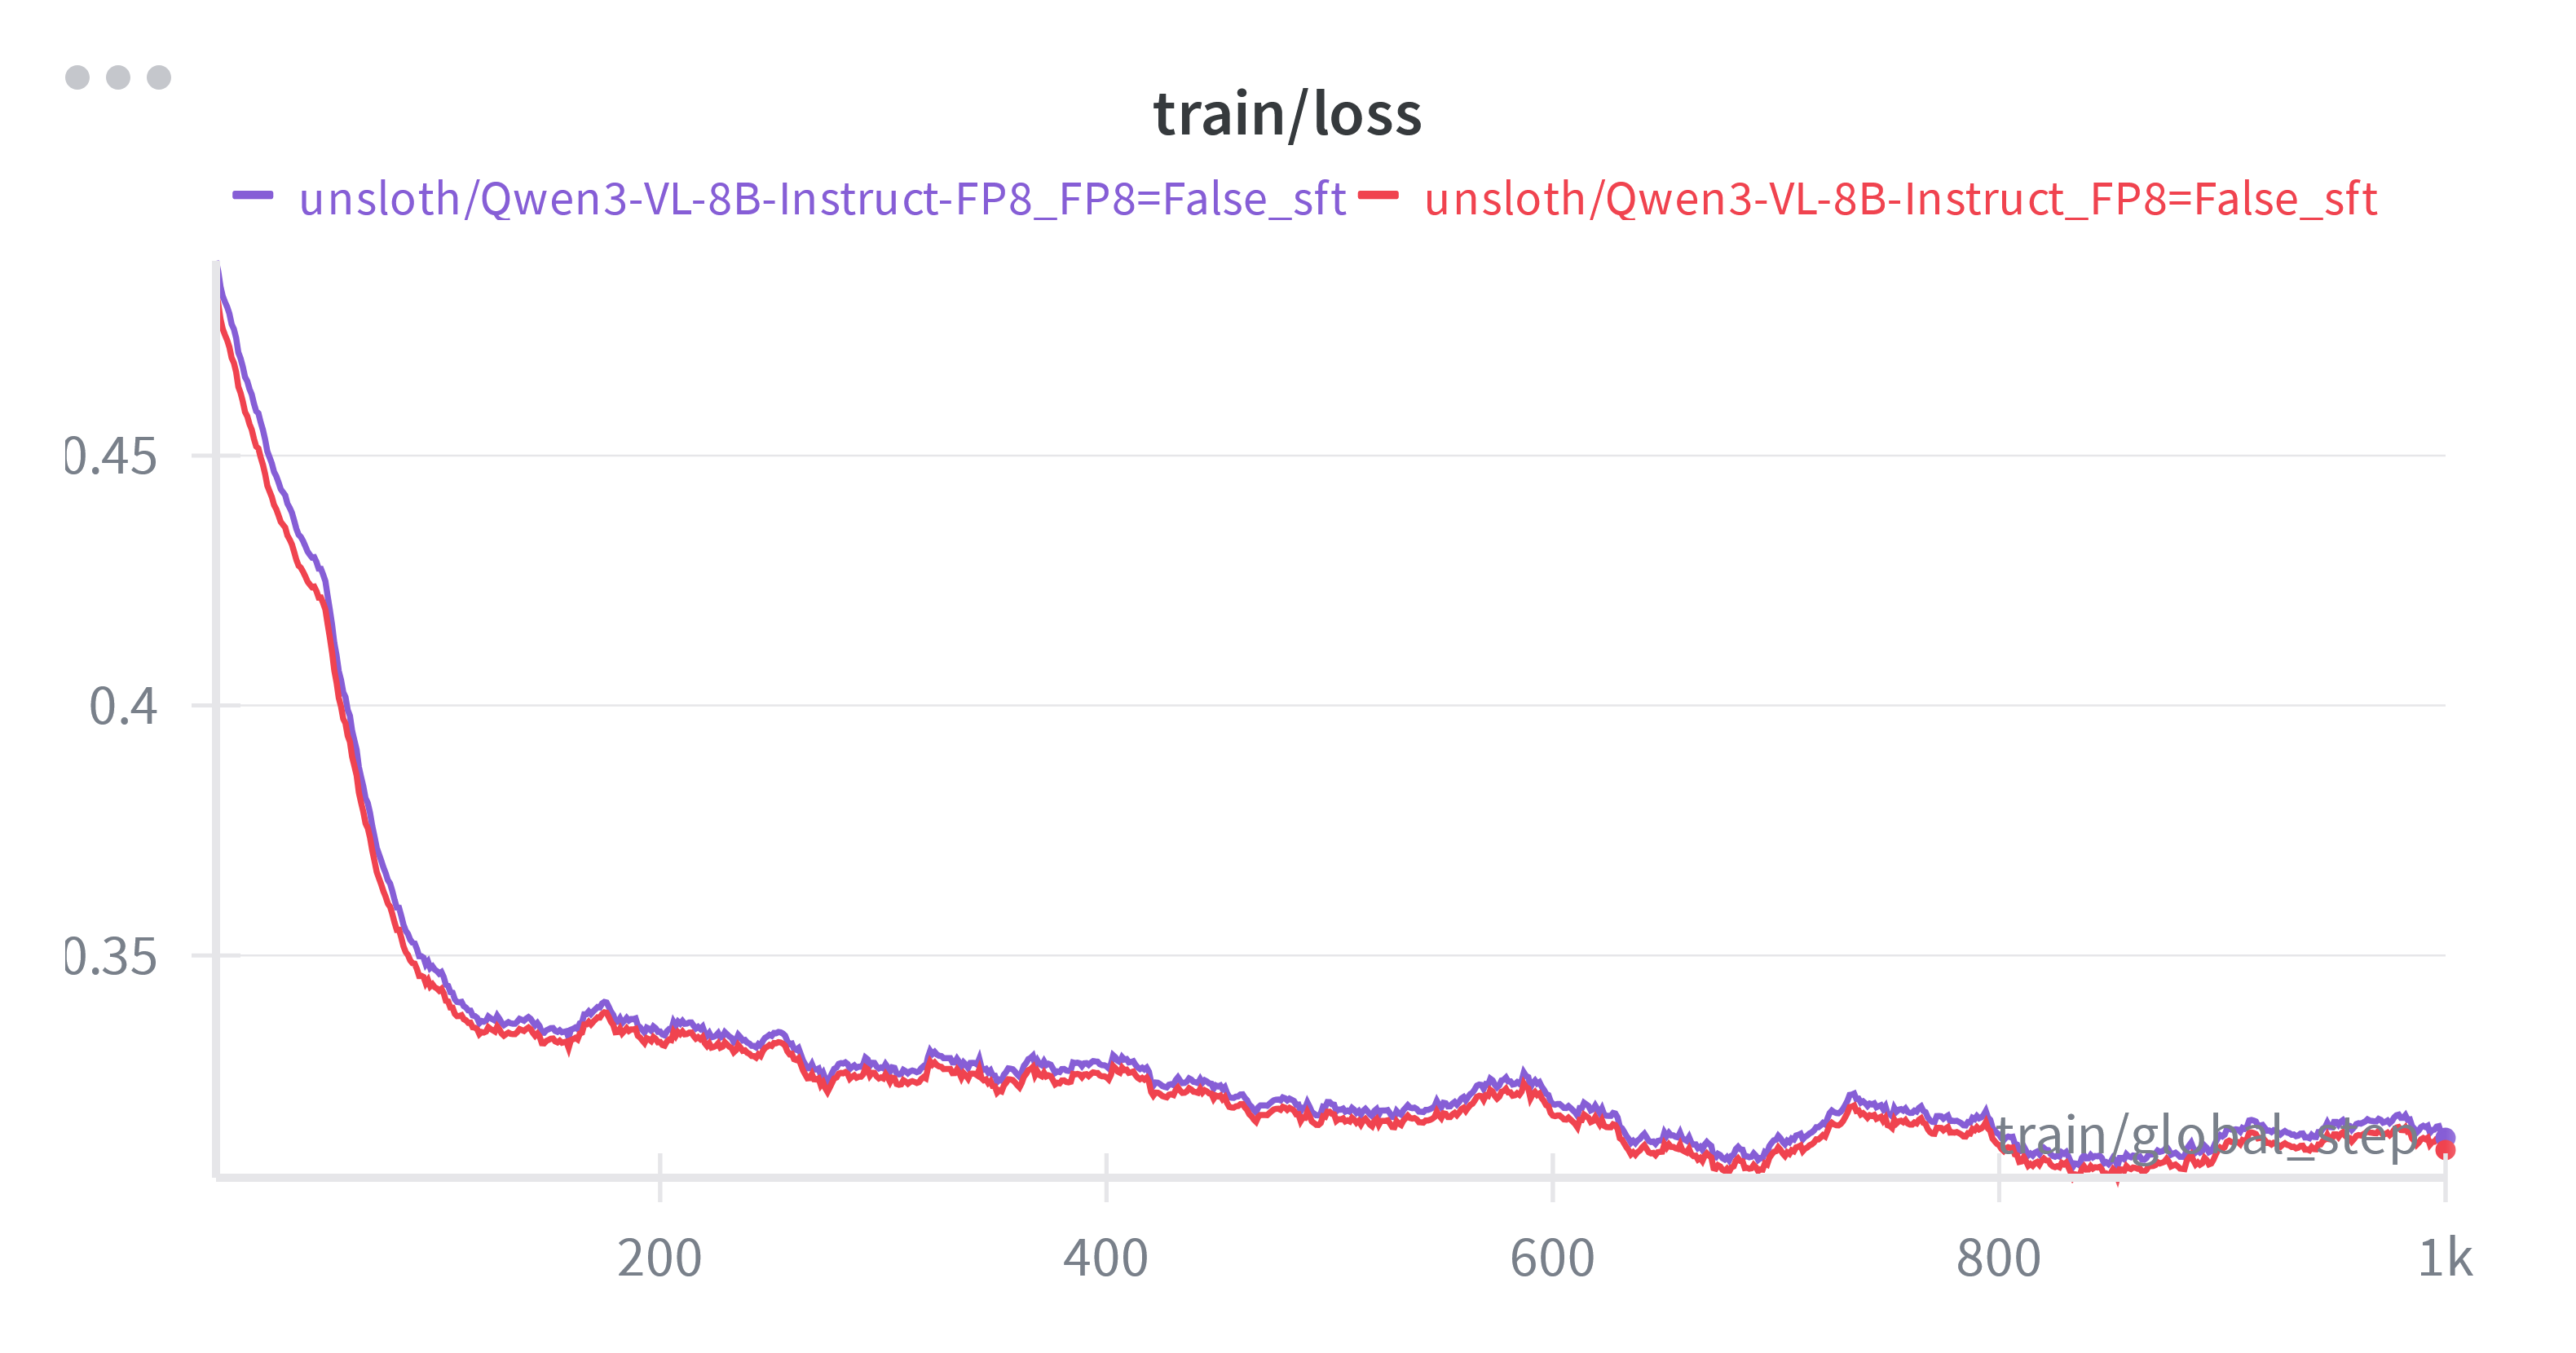
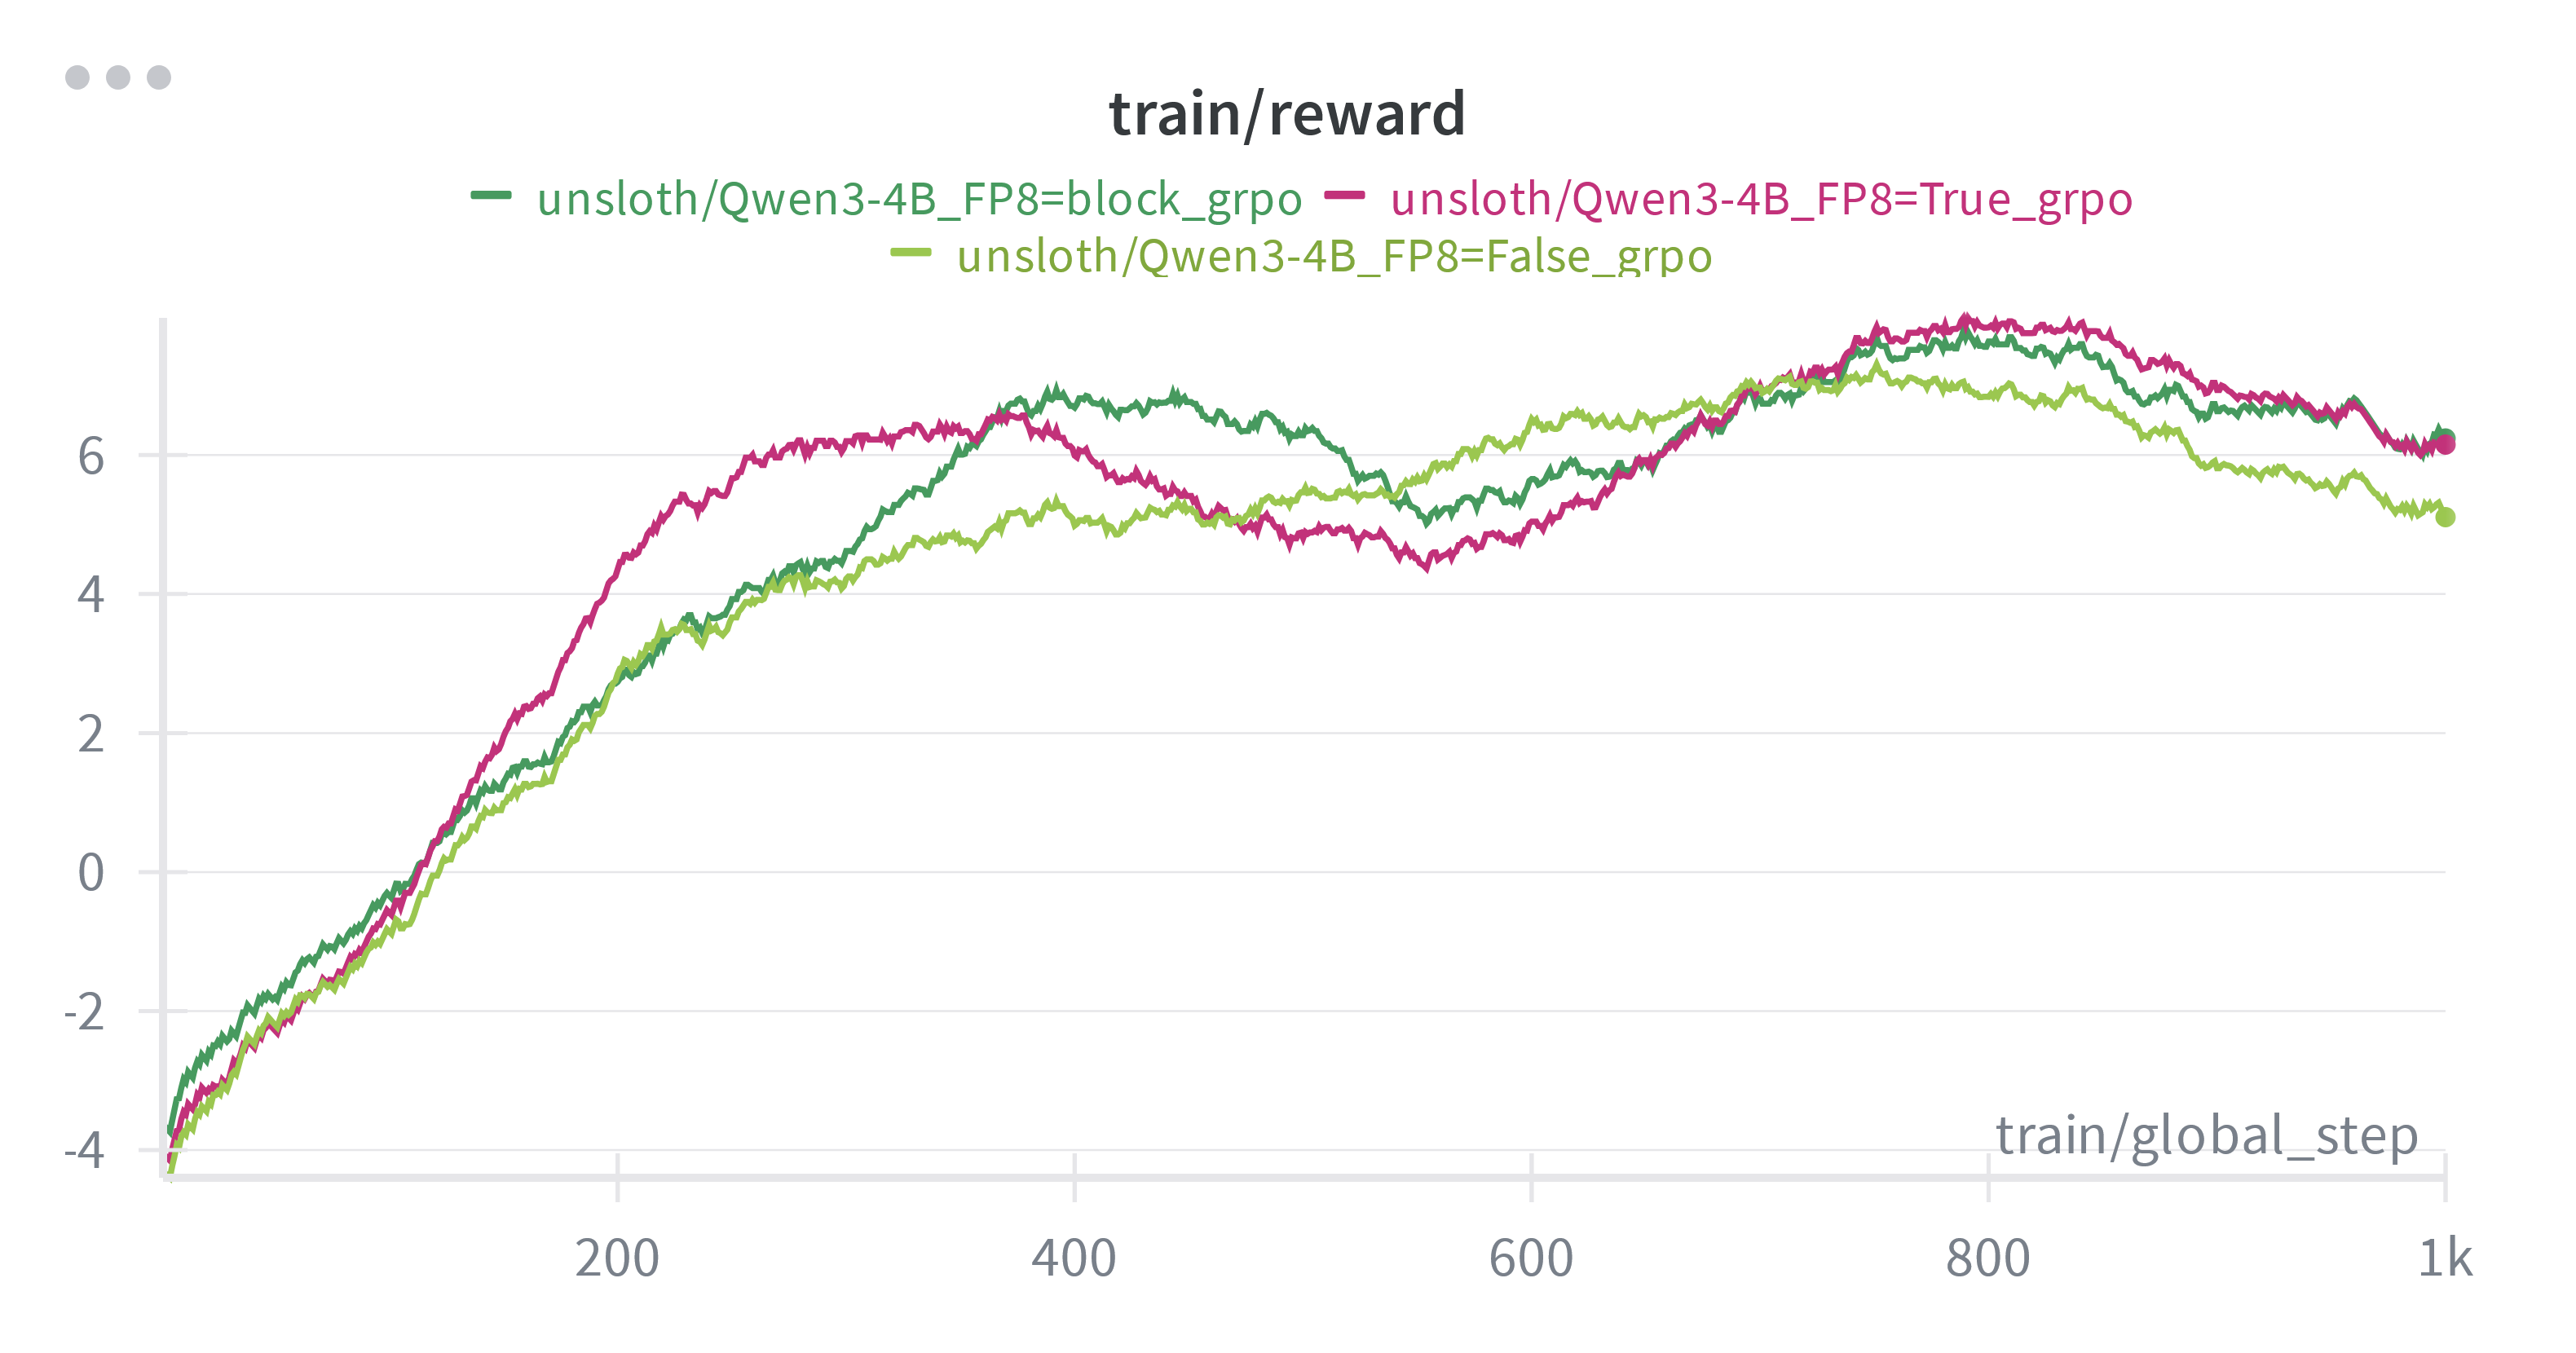
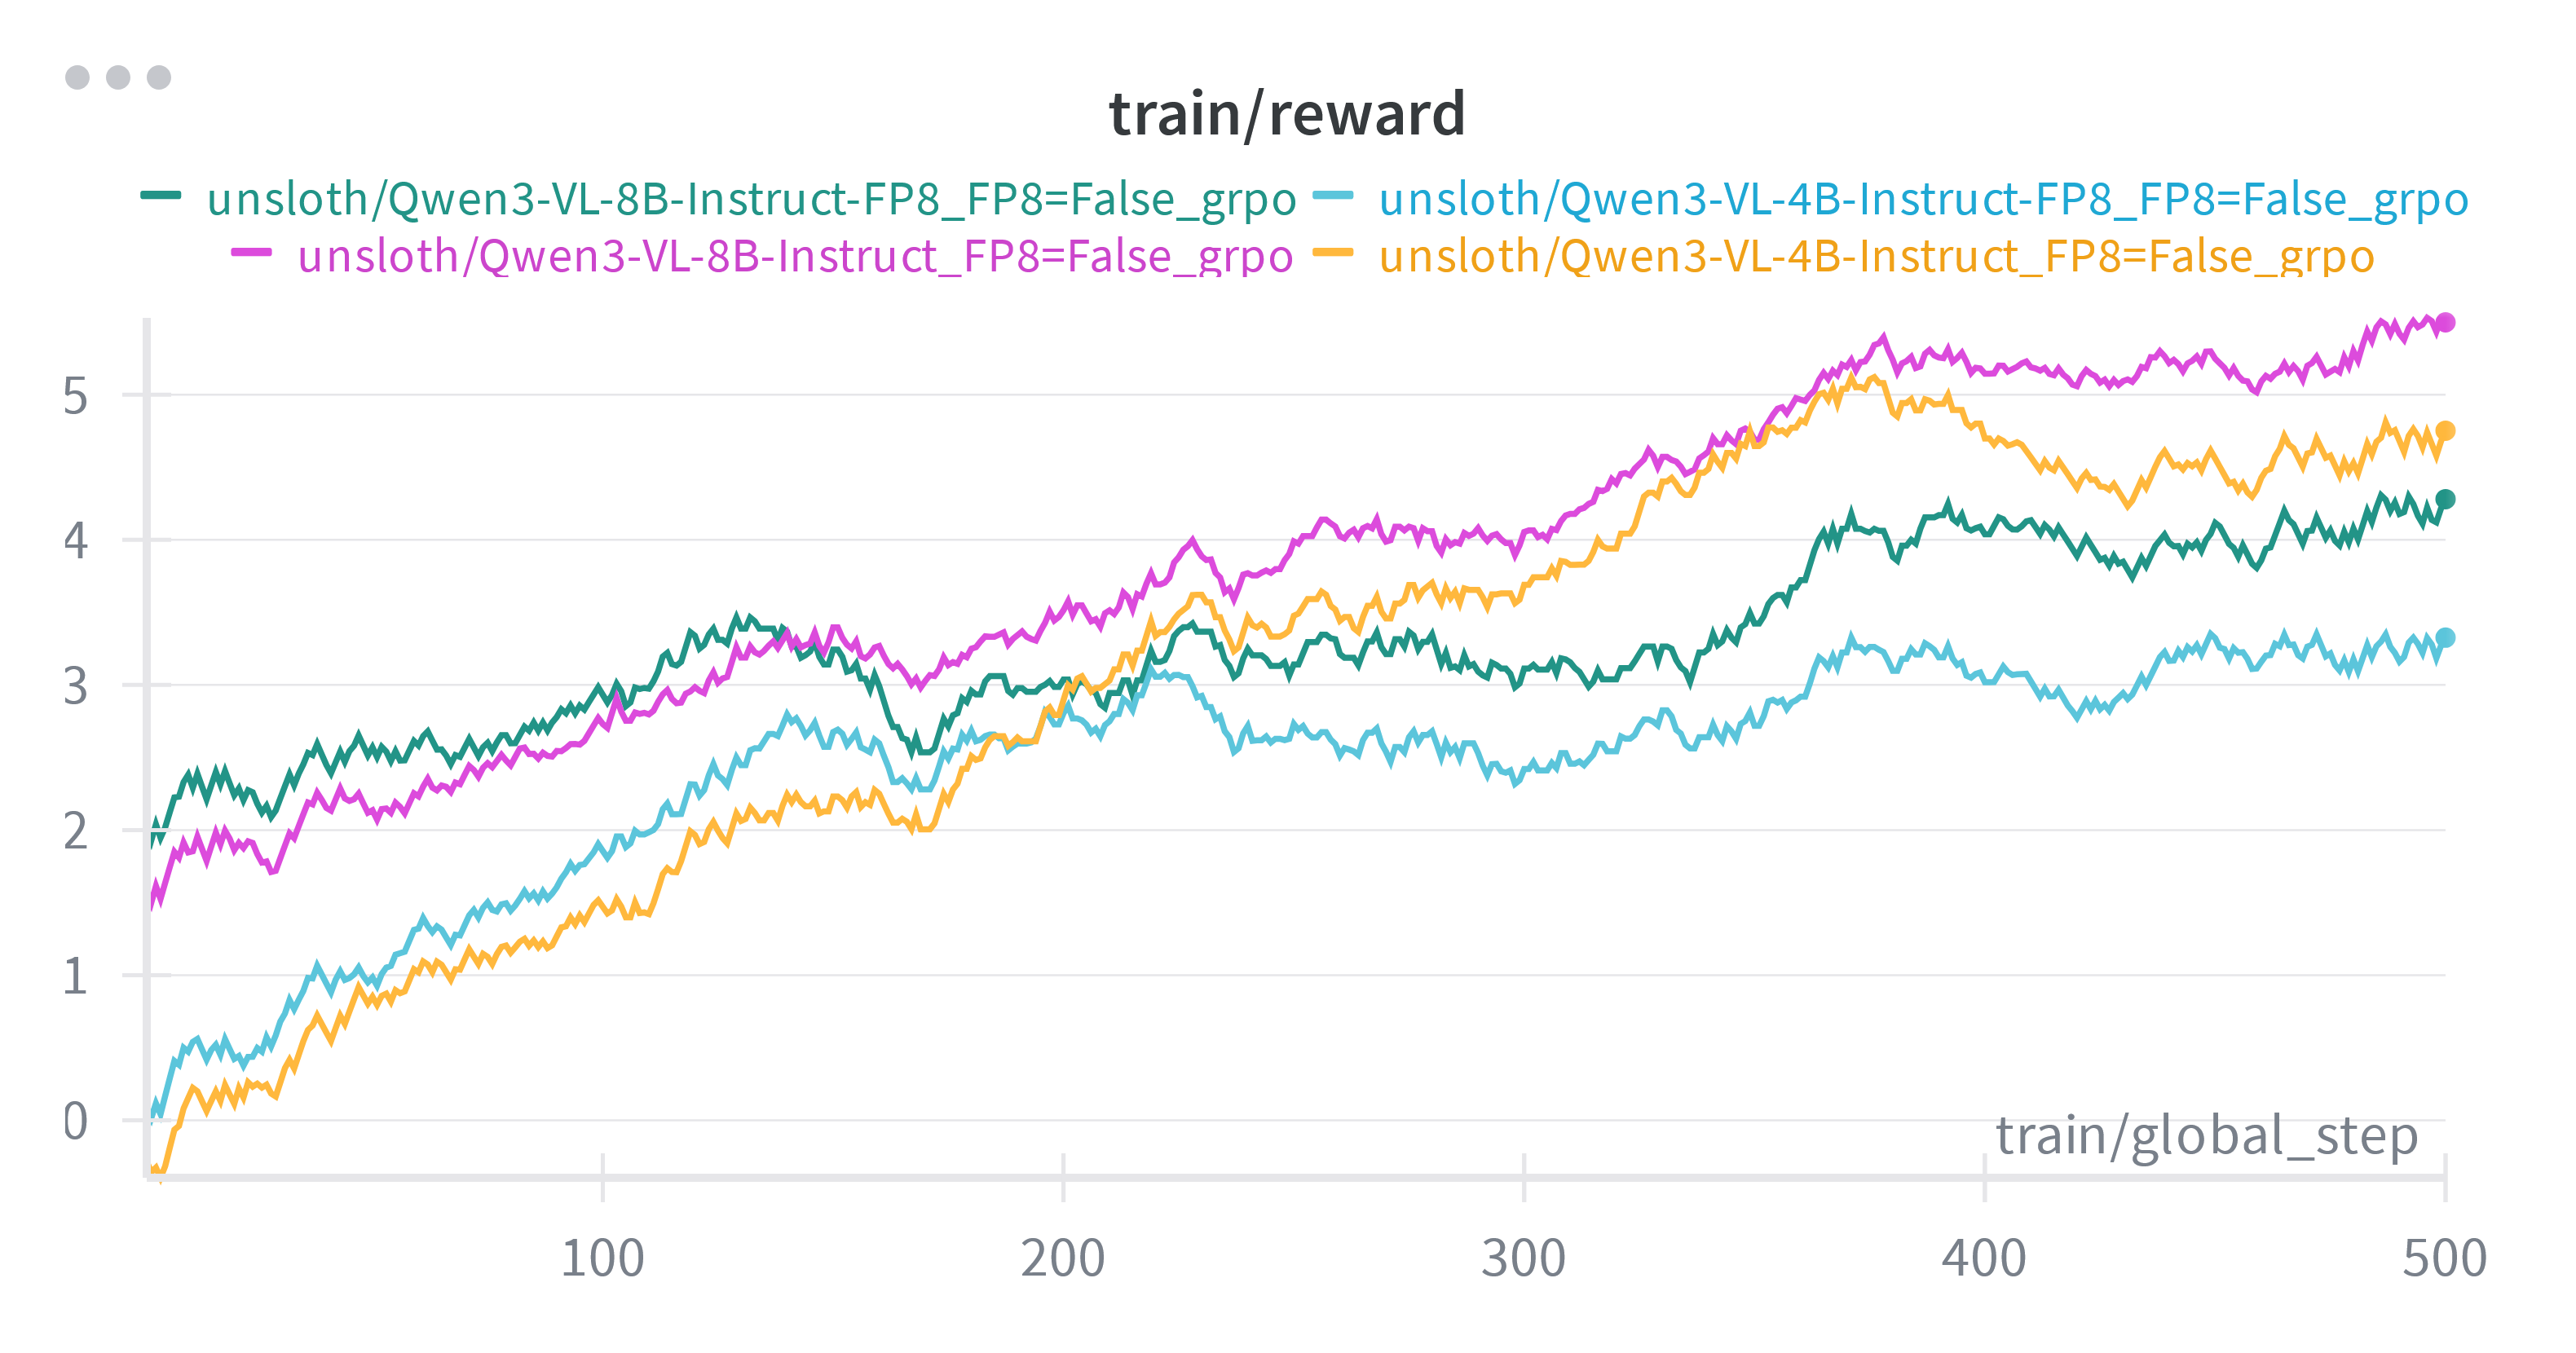
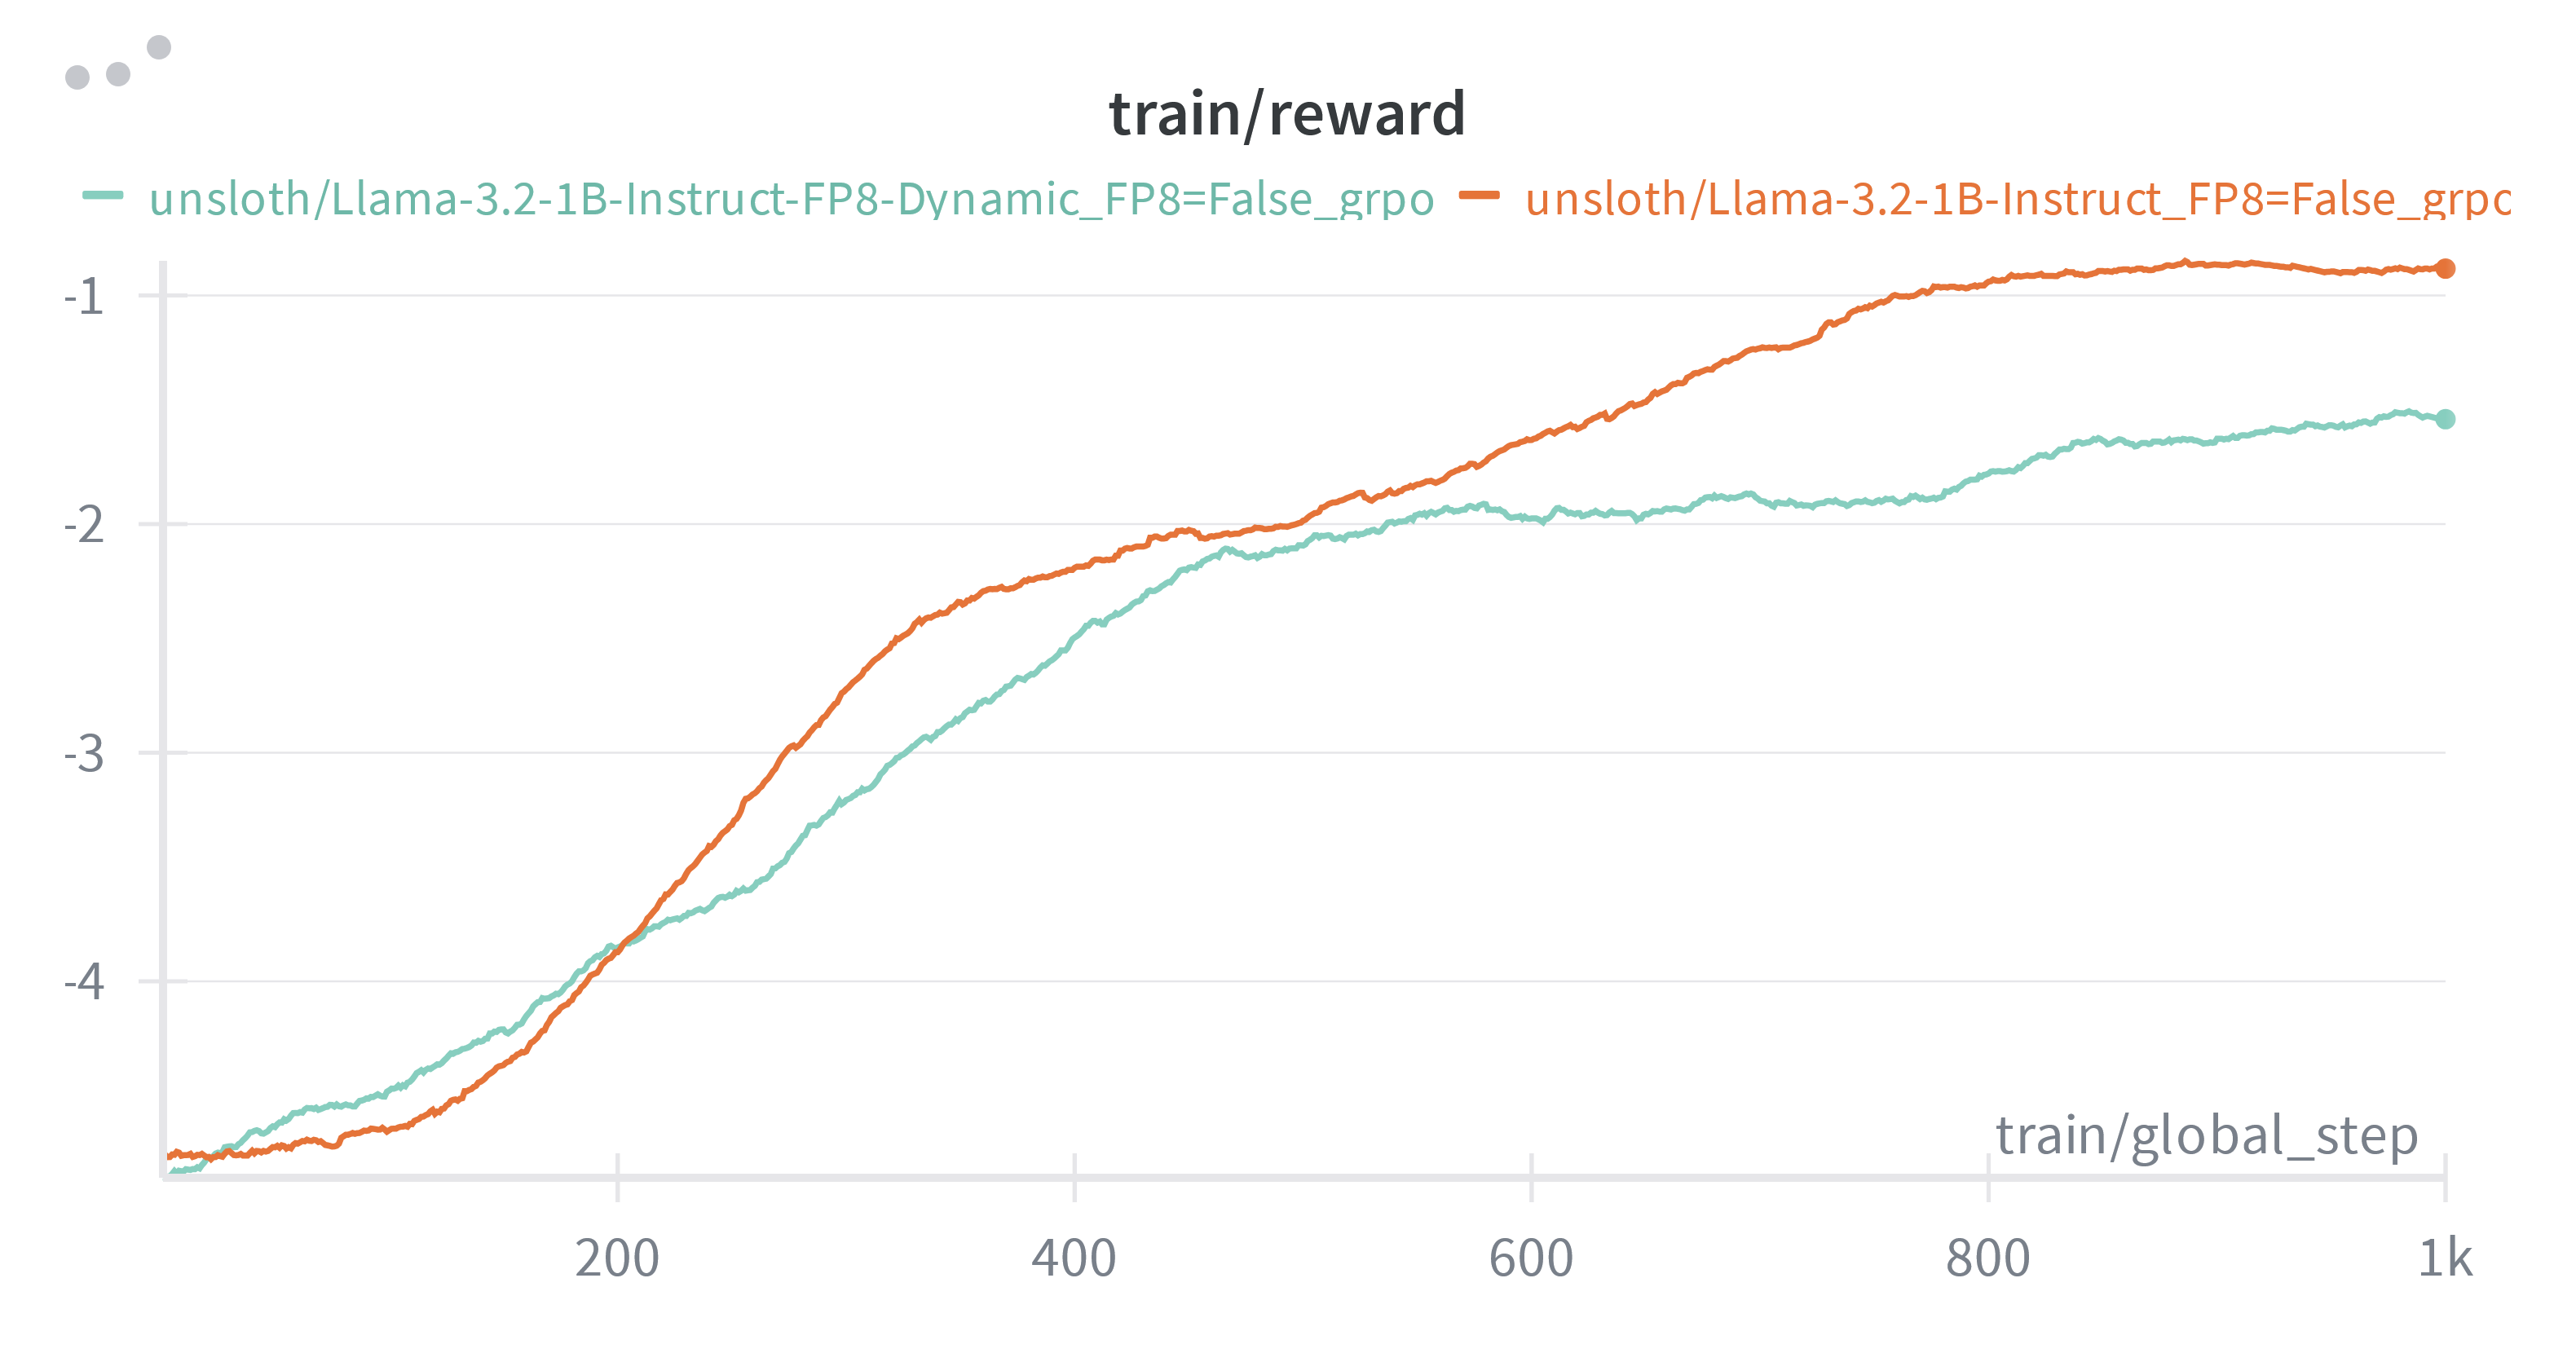
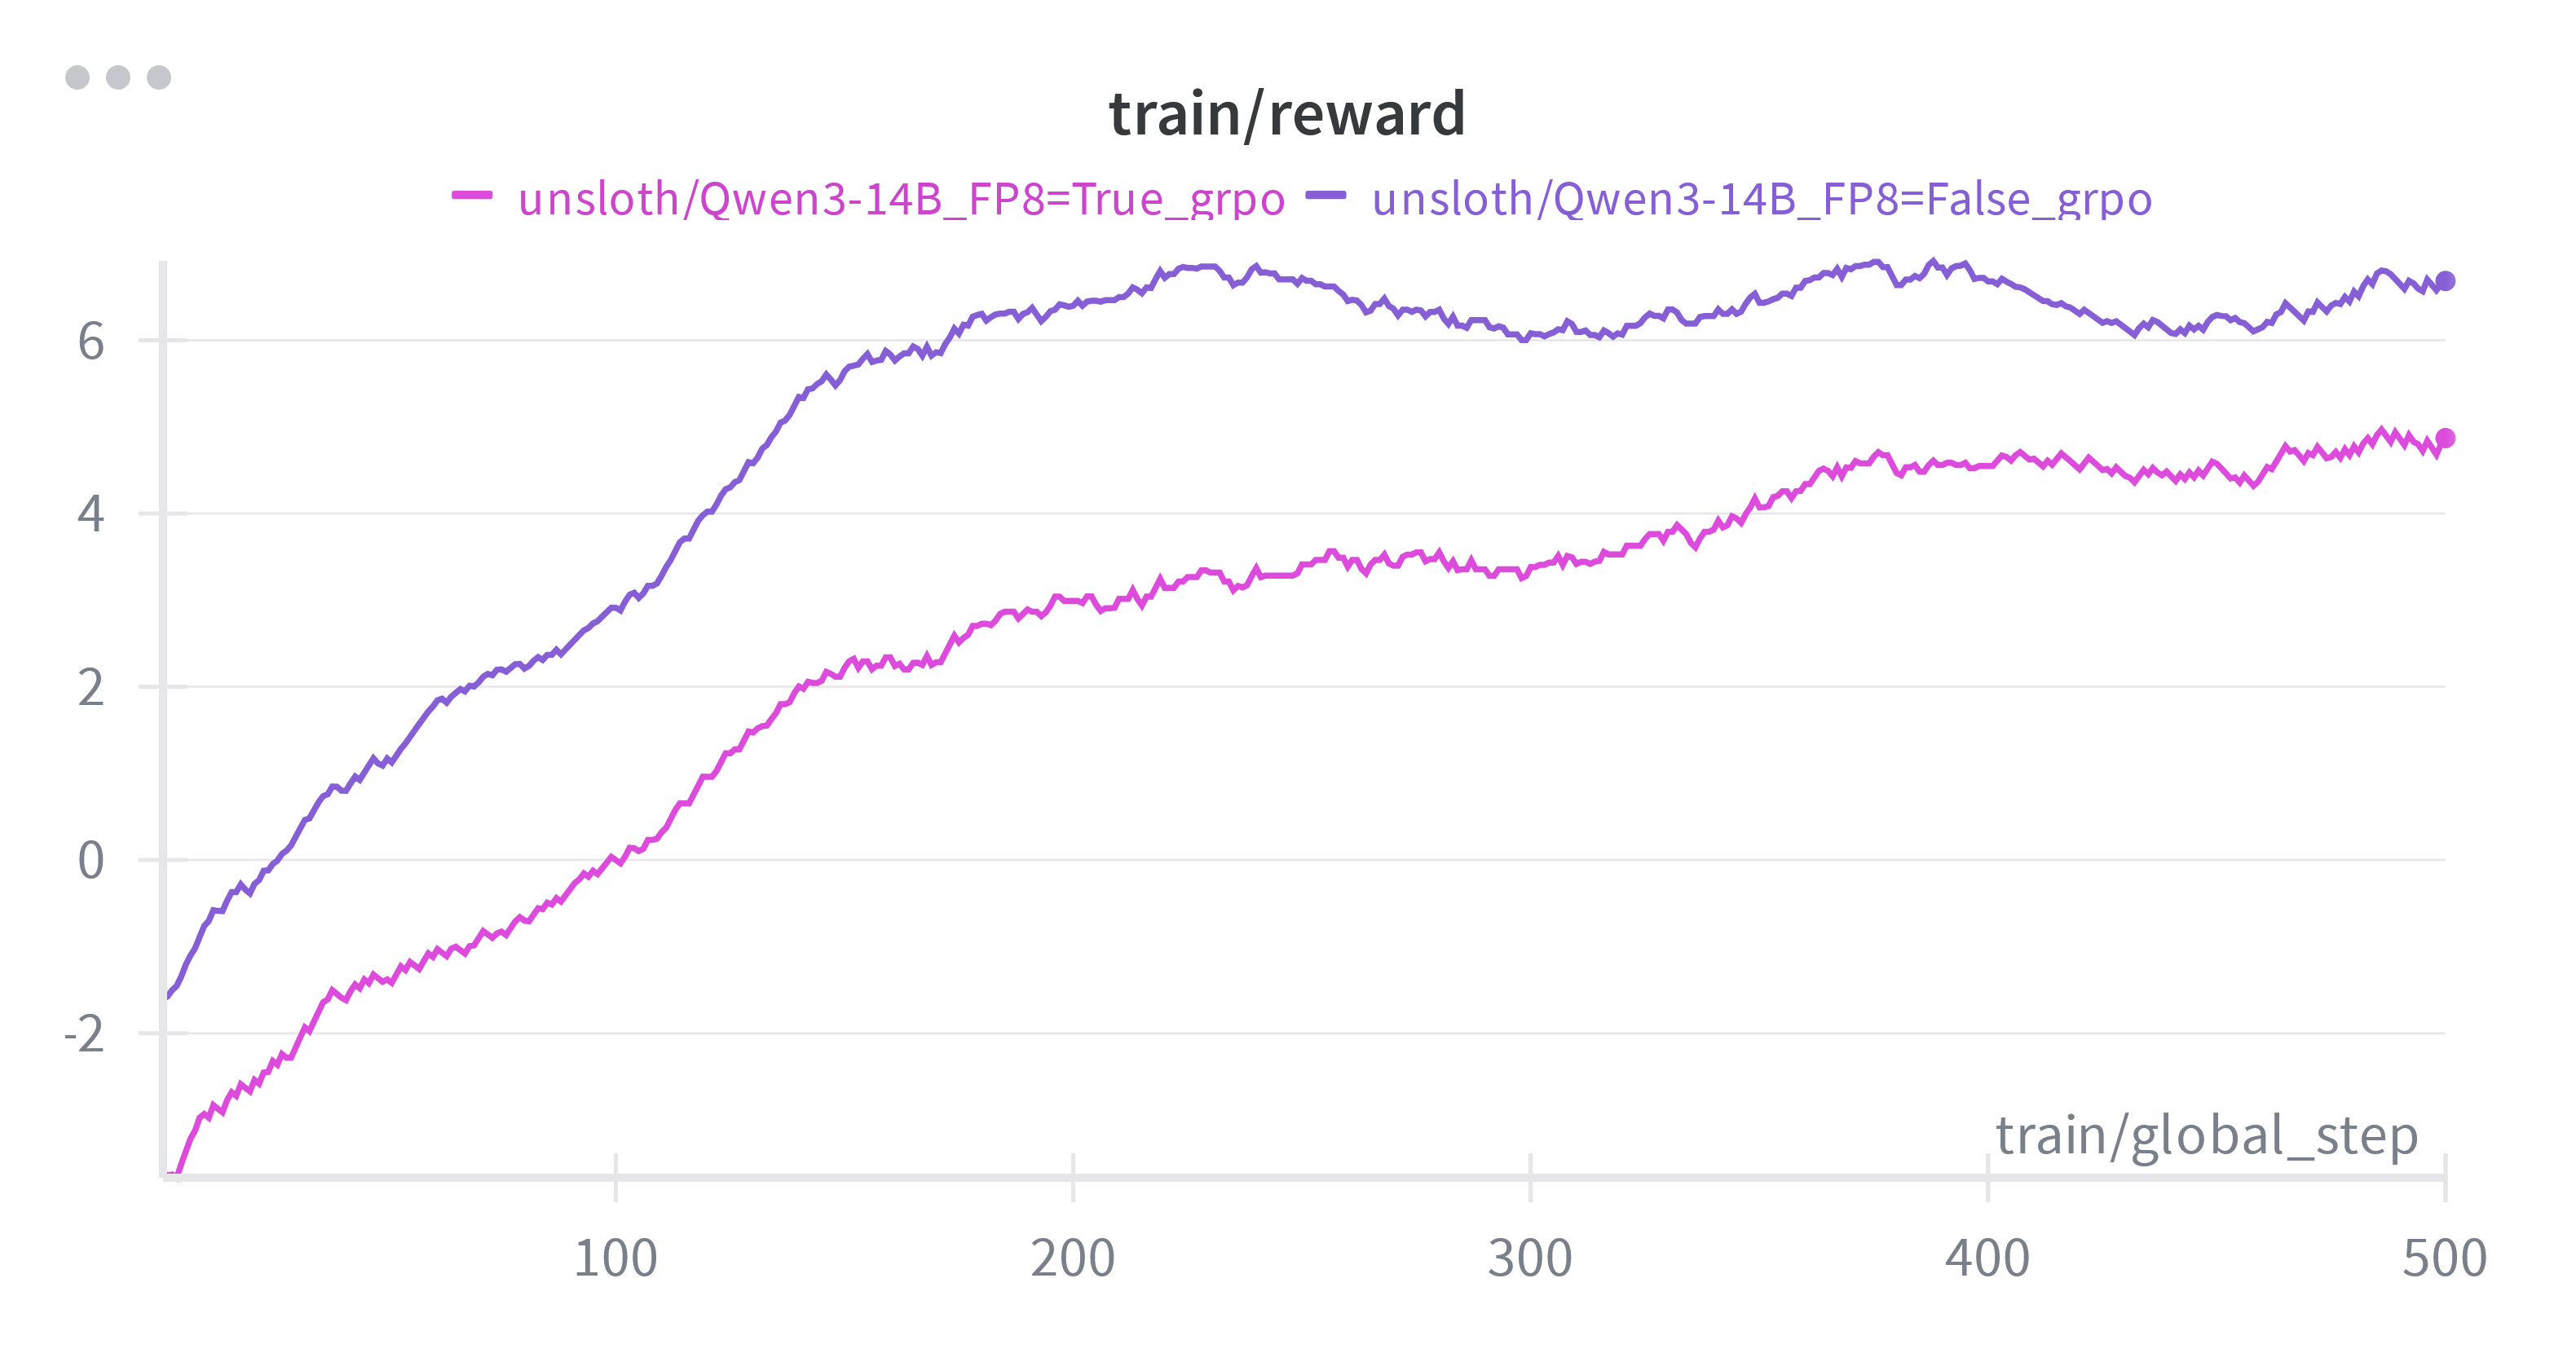
Qwen3-4B、8B、14B、Llama 3.2 1B、3B、Qwen3-VL-2B、Qwen3-VL 4Bなど、多数のモデルをテストしました。すべてBF16とFP8の両方で学習しました。プロットを見ると、 **BF16とFP8のSFT中の損失曲線は非常によく一致しています**。学習損失の観点では、両者に大きな差はありません：

{% columns %}
{% column %}

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FR6Hx9RtgqPXnYxvx5BbR%2FW%26B%20Chart%2025_11_2025%2C%208_54_56%20am.png?alt=media&amp;token=d1d70d59-df00-45bb-8352-e833f9b5f3cd" alt=""><figcaption></figcaption></figure>
{% endcolumn %}

{% column %}

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FlUzs2uNkCyF1ulNdrVRc%2FW%26B%20Chart%2025_11_2025%2C%208_56_50%20am.png?alt=media&amp;token=09545235-c9fa-4b76-a834-ffe0ceb8f639" alt=""><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

特にGRPOでは、生成の違いがあるため、少なくとも報酬プロットが一致し、乖離しないかを見るのが目的です（たとえばQwen3-14Bの実行結果は必ずしも完全に同じではない場合があります）

{% columns %}
{% column width="50%" %}

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FeLBs5GrQb988GcrYVzpF%2FW%26B%20Chart%2025_11_2025%2C%209_00_50%20am.png?alt=media&amp;token=59220833-33c6-4c28-abe7-b5d0d93a0a17" alt=""><figcaption></figcaption></figure>

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FPqXVeofauAIr5Qngm9d2%2FW%26B%20Chart%2025_11_2025%2C%209_08_06%20am.png?alt=media&amp;token=16498cf1-17e1-4984-b933-fe3633e19a6b" alt=""><figcaption></figcaption></figure>
{% endcolumn %}

{% column width="50%" %}

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FC76ql9G59SB0v3nG3pbL%2FW%26B%20Chart%2025_11_2025%2C%209_05_32%20am.png?alt=media&amp;token=554b6fe8-c121-48a4-8b33-41f28fc38ebb" alt=""><figcaption></figcaption></figure>

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FqM5NKHjOxqJv0hrzmr2B%2FW%26B%20Chart%2025_11_2025%2C%209_07_12%20am.png?alt=media&amp;token=a7ad9eb0-0ea2-4364-982a-0875ec63459f" alt=""><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

### :shinto\_shrine:推論 = RL学習の96%

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FTvC7GqMM5XAfV8Zv2tpf%2Fimage.avif?alt=media&amp;token=62b40c34-3111-40a9-b02a-4bfa8826402d" alt=""><figcaption></figcaption></figure>

RLでは、LLM/VLMを呼び出して実行ごとの候補解を生成し、それぞれの候補解を評価して **良い解に報酬を与え、悪い回答にペナルティを与えます**。最大効率を達成するには、学習全体のほぼ100%を推論に割り当てる必要があります。Unslothでは、 **学習がRL全体の実行時間の4%未満に収まり、96%が純粋なvLLM推論になるようにできました。**

たとえばQwen-3-8Bは短い系列長で1.15倍高速ですが、推論のみ（学習なし）におけるvLLM FP8自体のスループットも1.15倍高速です。UnslothでのRL実行でも処理トークン数が1.15倍速くなっており、 **Unslothでは学習オーバーヘッドがほぼ無視できることを示しています。**

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F105iKEPXAor00mdUPTfo%2FTokens%20Processed%20during%20RL.svg?alt=media&amp;token=ca1c1d76-64b2-4019-91ac-7043f0ab79fd" alt=""><figcaption></figcaption></figure>

### :1234:メモリ使用量60%削減

理論的には、メモリ削減はおおよそ **モデルの重みメモリに等しいと期待されます**。というのも、最適化状態は引き続き高精度で保存され、活性化も（現時点では）高精度で保存されるからです。私たちの結果は理論と一致しました。LoRAファインチューニングでは、次を観測しました： **約30GB削減** を **Qwen3-32Bで約14GB削減** を **Qwen2.5-14B** そして **約8GB削減** を **Qwen3-8B**

以下では **BF16でのLoRAファインチューニングでは** Qwen3-32Bでは、より大きなバッチサイズでOOMになってしまい、バッチを縮小する必要がありました。 **FP8版ではそのような問題はありませんでした**、そして私たちは **より大きなバッチサイズを使用でき** 、OOMすることなく済みました。

また、Unslothでは、で導入された仕組みに従い、vLLMの重み用メモリ空間を共有していることもお忘れなく [メモリ効率の高いRL](/docs/jp/meru/reinforcement-learning-rl-guide/memory-efficient-rl.md) — この技をFP8の領域にも持ち込みました！

| 80GB GPU                                                                                                                                               | 推論エンジン        | 学習エンジン       |
| ------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------- | ------------ |
| モデルの重み                                                                                                                                                 | **8共有FP8 GB** | **<<< 共有**   |
| <p><mark style="background-color:purple;"><strong>多目的</strong></mark></p><p><mark style="background-color:purple;"><strong>72GBの領域</strong></mark></p> | KVキャッシュ       | 活性化、勾配、最適化状態 |

有効にするために [Unslothスタンバイ](/docs/jp/meru/reinforcement-learning-rl-guide/memory-efficient-rl.md) FP8（またはBF16）のRLでは、Unslothをインポートする前に、以下をすべてのRL / GRPO学習実行に追加するだけです：

```python
import os
os.environ["UNSLOTH_VLLM_STANDBY"] = "1"
```

### :question:FP8 RLの使い方 / インストール

Unslothをアップデートするか、新しい仮想環境にUnslothをインストールするだけで、H100、L4、RTX 50x、RTX 40x、H200、B200、そしてRTX 4090以降に発売されたあらゆるNVIDIA GPU（コンシューマー向け・データセンター向けの両方）で使えます。

Unslothを更新するには： `pip install --upgrade --force-reinstall --no-cache-dir --no-deps unsloth unsloth_zoo`または新しい環境を作成します：

{% code overflow="wrap" %}

```bash
python -m venv unsloth_env
source unsloth_env/bin/activate

pip install unsloth vllm
pip install --pre torchao --index-url https://download.pytorch.org/whl/nightly/cu128 --force-reinstall
pip install --pre fbgemm-gpu fbgemm-gpu-genai --index-url https://download.pytorch.org/whl/cu128 --force-reinstall
pip install --upgrade numba numpy
```

{% endcode %}

次に、 `load_in_fp8 = True` これで準備完了です！モデル名を自動的にFloat8版へマッピングするか、その場でモデルをFloat8へ変換します！

<pre class="language-python" data-overflow="wrap"><code class="lang-python">import os
os.environ['UNSLOTH_VLLM_STANDBY'] = "1" # UnslothスタンバイはRLのメモリを30%以上節約します
from unsloth import FastLanguageModel
import torch
max_seq_length = 2048 # より長い推論トレースには増やせます
lora_rank = 32 # rankが大きいほど賢いが、遅くなる
model, tokenizer = FastLanguageModel.from_pretrained(
    model_name = "unsloth/Qwen3-8B",
    max_seq_length = max_seq_length,
    load_in_4bit = False, # LoRA 16bitではFalse
    fast_inference = True, # vLLM の高速推論を有効化
    max_lora_rank = lora_rank,
<strong>    load_in_fp8 = True, # Float8 RL / GRPO!
</strong>)
</code></pre>

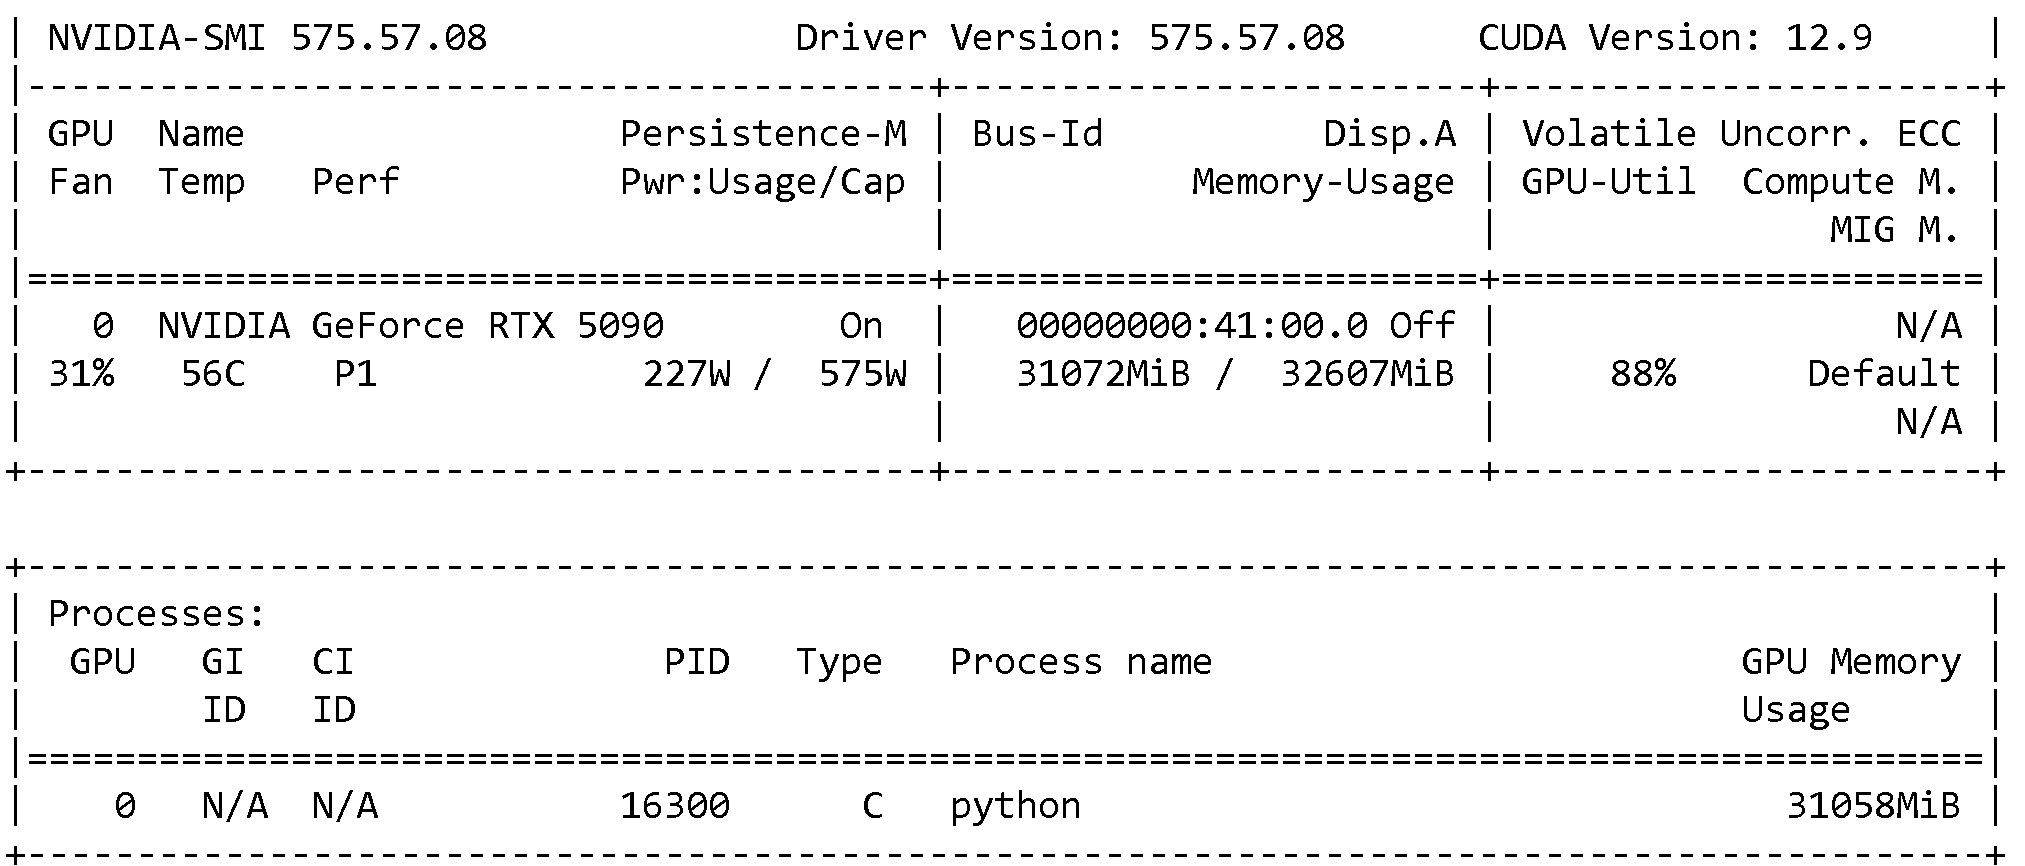
たとえばRTX 5090では（設定を忘れずに `os.environ["UNSLOTH_VLLM_STANDBY"] = "1"` )

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FlVA3v7E5J8pHb1QKLi2V%2Fimage.png?alt=media&amp;token=20b5329c-6ac2-479a-a4cc-2a0d74486696" alt="" width="375"><figcaption></figcaption></figure>

その後、RL用の2つのFP8ノートブックを使います：

{% columns %}
{% column %}
**Qwen3-8B FP8 RL Colab**

{% embed url="<https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_8B_FP8_GRPO.ipynb>" %}
{% endcolumn %}

{% column %}
**Llama-3.2-1B-FP8 RL Colab**

{% embed url="<https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Llama_FP8_GRPO.ipynb>" %}
{% endcolumn %}
{% endcolumns %}

### :cd:FP8学習の実装

最初の基準点は `transformers`で、すでにいくつかの方法でFP8をサポートしています。その一つはブロック量子化されたmatmul実装です。層が16ビットの活性化を受け取ると、それを量子化してカスタムFP8 matmulカーネルに渡します。これを組み込み、NVIDIA H100でベンチマークしたところ、望んでいたのとは逆に、ファインチューニングは約 **4倍遅く** 標準的なBF16ファインチューニングよりも遅くなりました。

### 🔥TorchAOとの共同作業

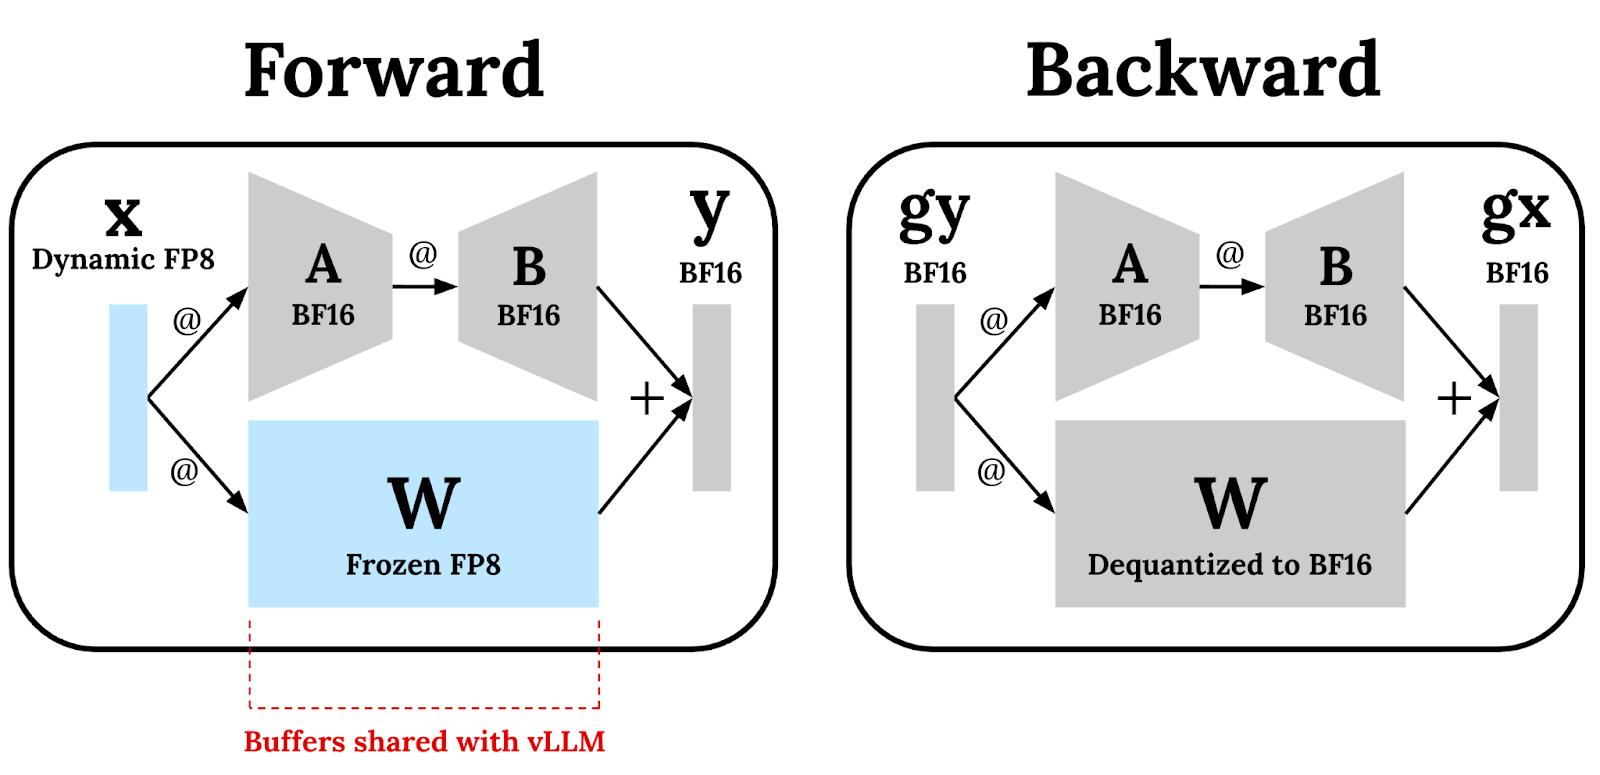
そこで私たちは [TorchAO](https://github.com/pytorch/ao) チームと協力し（[ Andrew](https://github.com/unslothai/unsloth/pull/3440)には大きな感謝を。TorchAOのFP8サポートを私たちのRLワークロードに組み込み、約 **1.4倍高速なスループット** と最大 **モデルメモリ使用量60%削減**を実現しました。大まかには次の通りです：

* 固定されたLoRA重みをFP8で保存します。
* 順伝播では、入力活性化に動的FP8量子化を適用し、学習可能なLoRAアダプタはBF16のまま保持します。
* これらのFP8重みはvLLMのモデル重みと同じバッファを共有するため、メモリ上には常にモデルのFP8コピーが1つだけあります（「二重モデル」のメモリオーバーヘッドはありません）。
* 逆伝播ではLoRA重みを非量子化し、すべての勾配計算をBF16で行って精度を高めます。

この一般的な構成は、以下を含むサポート済みのすべてのRLアルゴリズムで機能します： [GSPO](/docs/jp/meru/reinforcement-learning-rl-guide/advanced-rl-documentation/gspo-reinforcement-learning.md)、Dr. GRPO、PPO、DPO。

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FUir0hB7T0xBtWUTnK3aG%2Funknown.png?alt=media&amp;token=d225cd2e-fdf4-4521-8e9f-72bd684eb9e4" alt="" width="375"><figcaption></figcaption></figure>

TorchAOは、学習と推論の両方に対してPyTorchネイティブのFP8サポートを提供し、テンソル単位、行単位、128×128ブロック単位（プロトタイプ）など、さまざまなスケーリング粒度を備えています。TorchAOのFP8サポートは、推論スループットを最大で [27B規模で1.64倍](https://huggingface.co/pytorch/gemma-3-27b-it-FP8/blob/main/README.md#results-h100-machine) 行単位スケーリング粒度で向上させます。詳細はTorchAOの [FP8 README](https://github.com/pytorch/ao/blob/main/torchao/float8/README.md).

#### TorchAOのブロック量子化FP8 matmul

私たちはTorchAOのブロック量子化FP8 matmul実装を使用し、次のものを得ました：

* **BF16スループットの80%**
* 損失や学習安定性を損なうことなく

そのためしばらくの間、これが私たちのデフォルトのFP8 matmulバックエンドでしたが、その後FBGEMMが追いつきました。GPUが対応していれば、今ではFBGEMMの実装をデフォルトで使います！現在のUnslothは、インストール済みのものに応じて最適なバックエンドを自動的に選択できます。適切なパッケージがあれば、性能を取りこぼす必要はありません🙂

追伸: DeepSeekのDeepGEMMも試しましたが、クリーンで公平な比較を行うためのエンドツーエンドの完全統合まではできませんでした。

### :bird:オンザフライのTorchAO FP8量子化

多大なる感謝を [Andrew](https://github.com/unslothai/unsloth/pull/3440) TorchAOの〜により、Unsloth FP8 RLでは、モデル読み込み時に量子化を行い、それをvLLMへ渡すことで、モデルをその場で量子化することもできます。これにより、自分で明示的にモデルを量子化する必要はありません（こちらで処理します）。これは次を設定することで可能です： `load_in_fp8 = True` をモデル読み込み引数に指定します。適切な事前量子化済みチェックポイントが見つからない場合は、オフラインでFP8化を行います。

```python
from unsloth import FastLanguageModel
fp8_model = FastLanguageModel.from_pretrained(
    "unsloth/Llama-3.3-70B-Instruct"、# 任意のモデル名でOK！
    load_in_fp8 = True, # ブロックFP8なら「block」、行FP8ならTrue、False
)
```

### :tada:Unsloth FP8アップロード

便利なように、Hugging FaceにFP8 DynamicとFP8 Blockのモデルをアップロードしました。FP8学習に使えるほか、次による効率的で高速なサービング/デプロイにも使えます： [vLLM](/docs/jp/ji-chu/inference-and-deployment/vllm-guide.md)/[SGLang](/docs/jp/ji-chu/inference-and-deployment/sglang-guide.md) などを使用します。

FP8 DynamicはFP8 Blockより学習がやや速く、VRAM使用量も少ない一方で、精度に小さなトレードオフがあります。 [こちらをご覧ください](/docs/jp/meru/unsloth-model-catalog.md#fp8) FP8量子化モデルの完全な一覧はこちらですが、ここでは特に人気のあるものを挙げます：

| モデル                   | FP8アップロード                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                               |
| --------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Qwen3（2507）**       | <p>4B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-4B-Instruct-2507-FP8">FP8</a><br>4B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-4B-Thinking-2507-FP8">FP8</a><br>30B-A3B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-30B-A3B-Instruct-2507-FP8">FP8</a><br>30B-A3B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-30B-A3B-Thinking-2507-FP8">FP8</a></p>                                                                                                                                                                                                                                                                                                                             |
| **Qwen3-VL**          | <p>4B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-VL-4B-Instruct-FP8">FP8</a><br>4B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-VL-4B-Thinking-FP8">FP8</a><br>8B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-VL-8B-Instruct-FP8">FP8</a><br>8B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-VL-8B-Thinking-FP8">FP8</a></p>                                                                                                                                                                                                                                                                                                                                                         |
| **Llama 3.1**         | <p>8B Instruct — <a href="https://huggingface.co/unsloth/Llama-3.1-8B-Instruct-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.1-8B-Instruct-FP8-Block">ブロック</a><br>8B Base — <a href="https://huggingface.co/unsloth/Llama-3.1-8B-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.1-8B-FP8-Block">ブロック</a><br>70B — <a href="https://huggingface.co/unsloth/Llama-3.1-70B-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.1-70B-FP8-Block">ブロック</a></p>                                                                                                                                                                                               |
| **Qwen3**             | <p>0.6B — <a href="https://huggingface.co/unsloth/Qwen3-0.6B-FP8">FP8</a><br>1.7B — <a href="https://huggingface.co/unsloth/Qwen3-1.7B-FP8">FP8</a><br>4B — <a href="https://huggingface.co/unsloth/Qwen3-4B-FP8">FP8</a><br>8B — <a href="https://huggingface.co/unsloth/Qwen3-8B-FP8">FP8</a><br>14B — <a href="https://huggingface.co/unsloth/Qwen3-14B-FP8">FP8</a><br>32B — <a href="https://huggingface.co/unsloth/Qwen3-32B-FP8">FP8</a></p>                                                                                                                                                                                                                                                                                     |
| **Llama 3.3**         | 70B — [Dynamic](https://huggingface.co/unsloth/Llama-3.3-70B-Instruct-FP8-Dynamic) ・ [ブロック](https://huggingface.co/unsloth/Llama-3.3-70B-Instruct-FP8-Block)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                            |
| **Llama 3.2**         | <p>1B Base — <a href="https://huggingface.co/unsloth/Llama-3.2-1B-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.2-1B-FP8-Block">ブロック</a><br>1B Instruct — <a href="https://huggingface.co/unsloth/Llama-3.2-1B-Instruct-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.2-1B-Instruct-FP8-Block">ブロック</a><br>3B Base — <a href="https://huggingface.co/unsloth/Llama-3.2-3B-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.2-3B-FP8-Block">ブロック</a><br>3B Instruct — <a href="https://huggingface.co/unsloth/Llama-3.2-3B-Instruct-FP8-Dynamic">Dynamic</a> ・ <a href="https://huggingface.co/unsloth/Llama-3.2-3B-Instruct-FP8-Block">ブロック</a></p> |
| **Granite 4.0**       | <p>h-tiny — <a href="https://huggingface.co/unsloth/granite-4.0-h-tiny-FP8-Dynamic">FP8 Dynamic</a><br>h-small — <a href="https://huggingface.co/unsloth/granite-4.0-h-small-FP8-Dynamic">FP8 Dynamic</a></p>                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                           |
| **Magistral Small**   | [FP8 Dynamic](https://huggingface.co/unsloth/Magistral-Small-2509-FP8-Dynamic) ・ [FP8 torchao](https://huggingface.co/unsloth/Magistral-Small-2509-FP8-torchao)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                         |
| **Mistral Small 3.2** | [FP8](https://huggingface.co/unsloth/Mistral-Small-3.2-24B-Instruct-2506-FP8)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                           |
| **Gemma 3**           | <p>270m — <a href="https://huggingface.co/unsloth/gemma-3-270m-it-FP8-Dynamic">FP8</a><br>1B — <a href="https://huggingface.co/unsloth/gemma-3-1b-it-FP8-Dynamic">FP8</a><br>4B — <a href="https://huggingface.co/unsloth/gemma-3-4b-it-FP8-Dynamic">FP8</a><br>12B — <a href="https://huggingface.co/unsloth/gemma-3-12B-it-FP8-Dynamic">FP8</a><br>27B — <a href="https://huggingface.co/unsloth/gemma-3-27b-it-FP8-Dynamic">FP8</a></p>                                                                                                                                                                                                                                                                                              |

### :person\_tipping\_hand:謝辞

PyTorchおよびTorchAOチーム全体のご支援と協力に心から感謝します！特に、FP8 RLに関する多くの議論や、Unslothへの統合を手伝ってくれたAndrew Or、Jerry Zhang、Supriya Rao、Scott Roy、Mergen Nachinに深く感謝します！Executorchチームにも感謝します！


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://unsloth.ai/docs/jp/meru/reinforcement-learning-rl-guide/fp8-reinforcement-learning.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.