> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/mo-xing/minimax-m3.md).

# MiniMax M3 - 如何在本地运行

在你自己的设备上本地运行 MiniMax M3 LLM！

MiniMax M3 是一款新的 **\~428B（23B 激活）** 用于编码、代理式工作流、协作任务和多模态聊天的开源模型。该多模态模型支持文本、图像和视频输入，并且有一个 **1M 上下文** **窗口**。未量化的 bf16 权重大约为 \~**855GB** 而 1 比特 GGUF 将其降至仅 **128GB（-85%）**: [**MiniMax-M3 GGUF**](https://huggingface.co/unsloth/MiniMax-M3-GGUF)

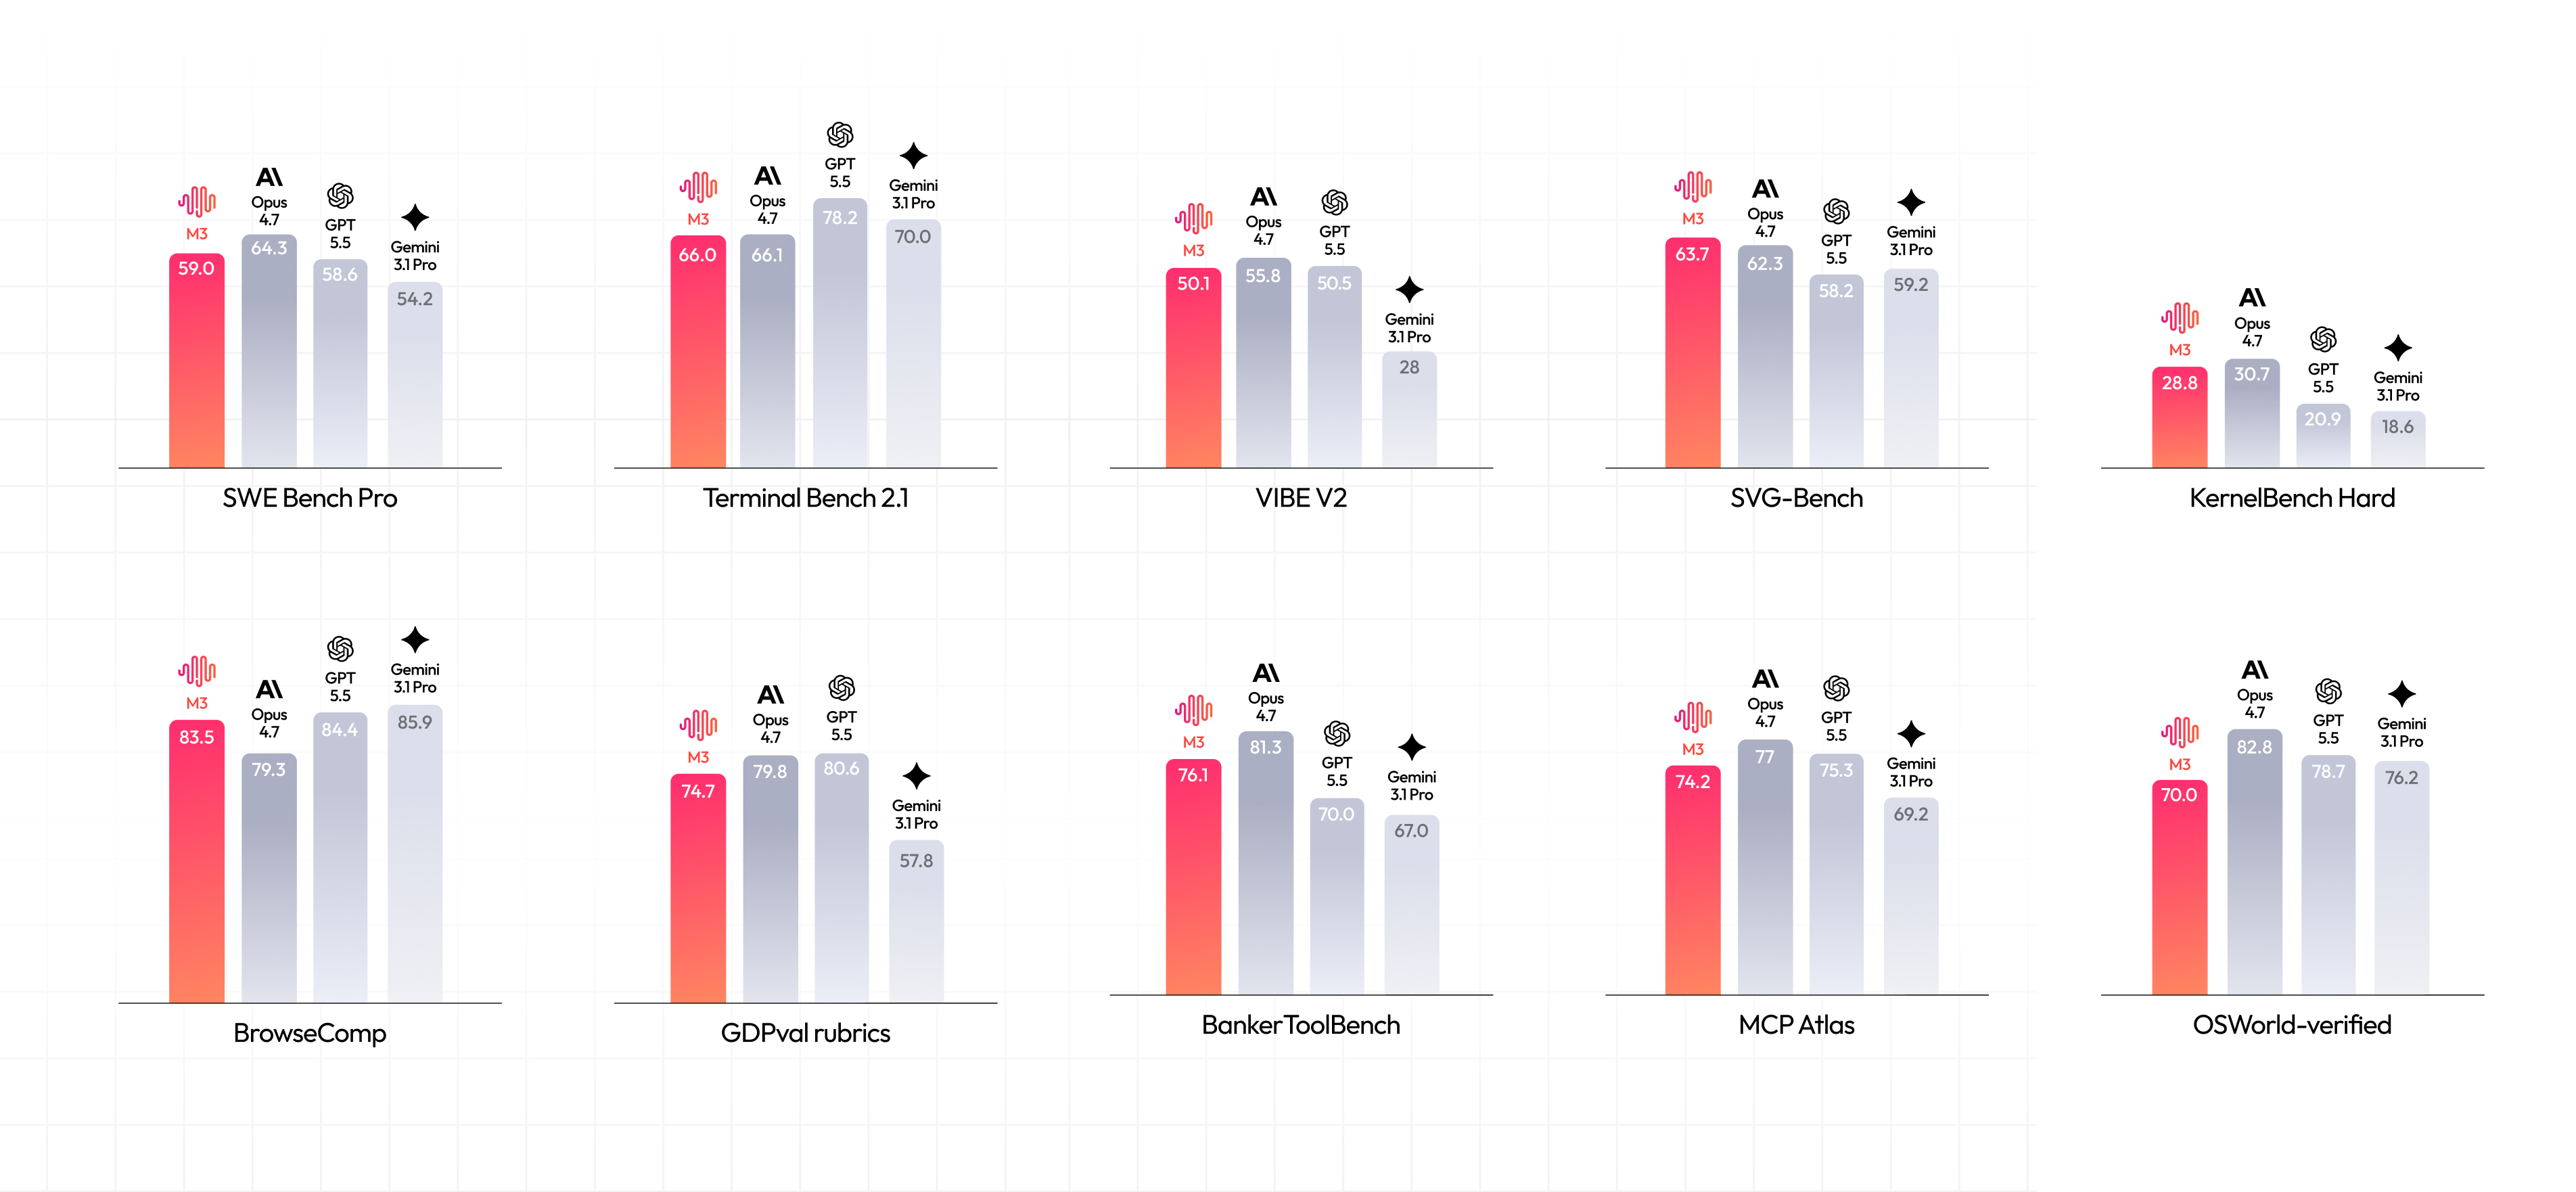
该模型的表现与 Gemini 3.1 Pro 不相上下——得分为 在 SWE-Bench Pro 上为 59%，在 Terminal-Bench 2.1 上为 66%，在 SWE-fficiency 上为 34.8%，在 KernelBench Hard 上为 28.8%。感谢 MiniMax 提供首日访问权限。

{% columns %}
{% column width="50%" %}
{% hint style="info" %}
MiniMax-M3 GGUF 目前仍属实验性。MiniMax-M3 本身原生支持多模态，但当前实验性 GGUF 是 **仅文本** 并且不支持 MiniMax Sparse Attention。
{% endhint %}
{% endcolumn %}

{% column width="50%" %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F7A3LPw7ex1psFIPkY6FF%2Fminimax%20m3%20guide.gif?alt=media&amp;token=b733672e-fa14-4572-952c-c9b3dbf82beb" alt="" width="375"><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

#### :gear: 使用指南

最小的 GGUF 量化版本， `UD-IQ1_M`，使用 **128GB** 磁盘空间。由于文件大小不包含 KV cache 和上下文分配，请尽量至少有 **133GB 内存** 来运行该模型。建议使用 `UD-IQ3_XXS` 它是 **159GB** 以获得最佳结果。

“ **4 位** `UD-IQ4_XS` 量化版本为 **208GB**，而 `UD-Q4_K_XL` 是 **265GB**。这些更适合 256GB 以上或 512GB 级别的系统、多 GPU 服务器，或带有 CPU 内存加 GPU 卸载的系统。

**表：推理硬件需求** （单位 = 总内存：RAM + VRAM，或统一内存）

<table><thead><tr><th>1-bit</th><th>2 位</th><th width="128">3 位</th><th>4 位</th><th>5-bit</th><th>8 位</th></tr></thead><tbody><tr><td>133 GB</td><td>148 GB</td><td>164-200 GB</td><td>213-270 GB</td><td>325 GB</td><td>460-470 GB</td></tr></tbody></table>

{% hint style="success" %}
为获得最佳性能，请确保你的总可用内存（包括 VRAM 和系统 RAM）比量化后的模型文件大小有充足的余量。
{% endhint %}

#### 推荐设置

MiniMax 建议使用以下参数以获得最佳性能： `temperature=1.0`, `top_p=0.95`, `top_k=40`.

{% columns %}
{% column %}

| `temperature = 1.0` |
| ------------------- |
| `top_p = 0.95`      |
| `top_k = 40`        |
| {% endcolumn %}     |

{% column %}

* **最大上下文窗口：** `1,048,576`
* 默认系统提示：

{% code overflow="wrap" %}

```
你是一个乐于助人的助手。你的名字是 MiniMax-M3，由 MiniMax 构建。
```

{% endcode %}
{% endcolumn %}
{% endcolumns %}

## 运行 MiniMax-M3 教程：

在本教程中，我们将使用当前最小的量化版本 UD-IQ1\_M，因为 MiniMax-M3 很大。如果你的机器有足够内存，可将 UD-IQ1\_M 替换为 UD-IQ4\_XS、UD-Q4\_K\_XL 或其他量化版本。现在你可以在 Unsloth 中运行 MiniMax-M3。

Unsloth 指南

#### 下载 Unsloth

#### 下载 Unsloth

<https://unsloth.ai/download>

<https://unsloth.ai/download>

### Unsloth 指南

#### 下载 Unsloth

<https://unsloth.ai/download>

{% hint style="success" %}
你现在可以通过以下方式运行 MiniMax M3： [Unsloth](#unsloth-studio-guide) ✨。请确保你使用 > [`v0.1.463-beta`](https://github.com/unslothai/unsloth/tree/v0.1.462-beta) 或 `2026.6.6`.
{% endhint %}

MiniMax M3 可在 MacOS、Windows 和 Linux 上通过 Unsloth 运行。你可以：

{% columns %}
{% column %}

* 搜索、下载、 [运行 GGUF](/docs/zh/xin/studio.md#run-models-locally) 和 safetensor 模型
* [**自修复** 工具调用](/docs/zh/xin/studio.md#execute-code--heal-tool-calling) + **网页搜索**
* [**代码执行**](/docs/zh/xin/studio.md#run-models-locally) （Python、Bash）
* [自动推理](https://unsloth.ai/docs/desktop#feature-deep-dive) 参数调优（温度、top-p 等）
* 通过 llama.cpp 实现快速 CPU + GPU 推理
* [训练 LLM](/docs/zh/xin/studio.md#no-code-training) 速度快 2 倍，VRAM 占用减少 70%
  {% endcolumn %}

{% column %}

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fszoidwwj70dLm5vBjpmL%2Fdiffusiongemma.gif?alt=media&amp;token=8ce359fd-f92c-4cf8-a491-06b04c505cb7" alt=""><figcaption></figcaption></figure></div>
{% endcolumn %}
{% endcolumns %}

{% stepper %}
{% step %}

#### 安装 Unsloth

请确保你使用最新的 [`v0.1.463-beta`](https://github.com/unslothai/unsloth/tree/v0.1.462-beta) 或 `2026.6.6`。在你的终端中运行：

**MacOS、Linux、WSL：**

```bash
curl -fsSL https://unsloth.ai/install.sh | sh
```

**Windows PowerShell：**

```bash
irm https://unsloth.ai/install.ps1 | iex
```

{% endstep %}

{% step %}

#### 启动 Unsloth

**MacOS、Linux、WSL 和 Windows：**
{% endstep %}

{% step %}

#### 搜索并下载 MiniMax M3

然后前往 [Unsloth Chat](/docs/zh/xin/studio/chat.md) 选项卡，并在搜索栏中搜索 MiniMax M3，然后下载你想要的模型和量化版本。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FYUbbg1xVmfmJYVEQTNaS%2FScreenshot%202026-06-12%20at%206.33.22%E2%80%AFPM.png?alt=media&amp;token=9b672870-3c8b-4b38-bfe8-16cdef0b5e25" alt="" width="563"><figcaption></figcaption></figure>
{% endstep %}

{% step %}

#### 运行 MiniMax M3

<div data-with-frame="true"><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F7A3LPw7ex1psFIPkY6FF%2Fminimax%20m3%20guide.gif?alt=media&amp;token=b733672e-fa14-4572-952c-c9b3dbf82beb" alt=""><figcaption></figcaption></figure></div>
{% endstep %}
{% endstepper %}

### 🦙 Llama.cpp 指南

{% stepper %}
{% step %}
获取特定的 `llama.cpp` PR 上 [**GitHub 上获取**](https://github.com/ggml-org/llama.cpp/pull/24523)。你也可以按照下面的构建说明进行操作。将 `-DGGML_CUDA=ON` 改为 `-DGGML_CUDA=OFF` 如果你没有 GPU，或者只想使用 CPU 推理。 **对于 Apple Mac / Metal 设备**，设置 `-DGGML_CUDA=OFF` 然后按常规继续——Metal 支持默认开启。

```bash
git clone https://github.com/ggml-org/llama.cpp
cd llama.cpp
git fetch origin pull/24523/head:minimax-m3
git checkout minimax-m3
cmake -B build -DGGML_CUDA=ON
cmake --build build --config Release -j --target llama-cli llama-server
```

{% endstep %}

{% step %}
你现在可以使用 `llama.cpp` 直接加载和下载模型，就像 `ollama run`。首先，选择你想要的量化类型，例如 `Q2_K_XL`。同时使用 `export LLAMA_CACHE="folder"` 来强制 `llama.cpp` 保存到指定位置。注意，此下载过程可能非常慢，因此最好使用下一节中的手动下载方式。

```bash
export LLAMA_CACHE="unsloth/MiniMax-M3-GGUF"
./build/bin/llama-cli \\
    -hf unsloth/MiniMax-M3-GGUF:UD-IQ1_M \\
    --temp 1.0 \\
    --top-p 0.95 \\
    --top-k 40
```

{% hint style="info" %}
注意：目前尚不支持 MiniMax Sparse Attention，因此推理会回退到稠密注意力。
{% endhint %}
{% endstep %}

{% step %}
如果你想手动下载模型，我们可以通过下面的代码下载模型（在安装 `pip install huggingface_hub`）。如果下载卡住，请参见： [Hugging Face Hub、XET 调试](/docs/zh/ji-chu-zhi-shi/troubleshooting-and-faqs/hugging-face-hub-xet-debugging.md)

```bash
hf download unsloth/MiniMax-M3-GGUF \\
    --local-dir unsloth/MiniMax-M3-GGUF \\
    --include "*UD-IQ1_M*" # 4 位请使用 "*UD-IQ4_XS*"
```

{% endstep %}

{% step %}
你可以修改 `--threads 32` CPU 线程数， `--ctx-size 32768` 用于上下文长度， `--n-gpu-layers 2` 用于 GPU 卸载的层数。如果你的 GPU 内存不足，请尝试调整它。如果你只进行 CPU 推理，也请将其移除。记住，MSA 目前尚不支持，所以请保持 `--ctx-size` 适度——在非常长的上下文中使用稠密注意力会占用大量内存。

{% code overflow="wrap" %}

```bash
./build/bin/llama-cli \\
    --model unsloth/MiniMax-M3-GGUF/UD-IQ1_M/MiniMax-M3-UD-IQ1_M-00001-of-00004.gguf \\
    --temp 1.0 \\
    --top-p 0.95 \\
    --top-k 40
```

{% endcode %}
{% endstep %}
{% endstepper %}

## 📊 基准测试

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F4SjJ6hXo8PijYgtdfMGp%2Fminimaxm3%20short%20benchmarks.jpeg?alt=media&amp;token=1a544bfd-1c81-4b45-89f7-04b88190d473" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FnRfDibKjJo3LG99RxlqW%2Fminimaxm3.jpeg?alt=media&amp;token=f0c4b21f-9680-4fa8-862f-c79f1c0bf55f" alt=""><figcaption></figcaption></figure>


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://unsloth.ai/docs/zh/mo-xing/minimax-m3.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.