#### :interrobang:Gemma-4 31B 和 26B-A4B 推理中的 IndexError
在使用 31B 和 26B 进行推理时,你可能会看到此错误:
```python
文件 "/.../cache_utils.py",第 937 行,在 update 中
keys, values = self.layers[layer_idx].update(...)
IndexError: 列表索引超出范围
```
罪魁祸首如下:
```python
if hasattr(decoder_config, "num_kv_shared_layers"):
layer_types = layer_types[: -decoder_config.num_kv_shared_layers]
```
Gemma-4 31B 和 26B-A4B 附带 `num_kv_shared_layers = 0`。在 Python 中, `-0 == 0`,因此 `layer_types[:-0]` 会退化为 `layer_types[:0] == []`。缓存会在没有任何层槽位的情况下构建,第一次注意力前向传播就会在 `Cache.update`.
#### :no\_entry: `use_cache = True` 对 E2B、E4B 来说,生成结果一团糟
[见 issue](https://github.com/huggingface/transformers/issues/45242) "\[Gemma 4] `use_cache=False` 会破坏注意力计算,产生垃圾 logits #45242"
Gemma-4 E2B 和 E4B 在各层之间共享 KV 状态(`num_kv_shared_layers = 20` 和 `18`)。缓存是早期层为后续层复用而存放 KV 的唯一位置。当 `use_cache=False` (正如每个 QLoRA 教程都会设置的那样,而且 `gradient_checkpointing=True` 强制启用时), `Gemma4TextModel.forward` 会跳过缓存构建,因此共享 KV 的层会退回到基于当前隐藏状态在本地重新计算 K 和 V。logits 会变成垃圾,训练损失会发散。
**之前(`unsloth/gemma-4-E2B-it`,提示“1+1 是多少?”):**
```
use_cache=True -> '1 + 1 = **2**'
use_cache=False -> 'BROAD\\肯. Specificallyboard K supposed\\_n통 \\'
max_abs_logit_diff: 48.937500
```
**修复后:**
```
use_cache=True -> '1 + 1 = **2**'
use_cache=False -> '1 + 1 = **2**'
max_abs_logit_diff: 0.000000 (逐位完全一致,全部 9 个 token 相同)
```
#### :radio:音频 fp16 溢出
`Gemma4AudioAttention` 使用 `config.attention_invalid_logits_value = -1e9` 在 `masked_fill` 调用中。在 fp16(Tesla T4)上,-1e9 会溢出 fp16 的最大值 65504,导致:
```python
RuntimeError: value cannot be converted to type c10::Half without overflow
```
这是由于 `self.config.attention_invalid_logits_value` :
```python
attn_weights = attn_weights.masked_fill(
attention_mask.logical_not(), self.config.attention_invalid_logits_value
)
```
#### 💡Gemma-4 提示
1. 如果你想 **保留推理** 能力,你可以将推理风格示例与直接回答混合使用(保持至少 75% 为推理内容)。否则你可以全部输出。\
\
使用 `gemma-4` 用于非思考的聊天模板,以及 `gemma-4-thinking` 用于思考变体。\
较大的 26B 和 31B 请用思考版,小型号请用非思考版。
```python
from unsloth.chat_templates import get_chat_template
tokenizer = get_chat_template(
tokenizer,
chat_template = "gemma-4-thinking", # 或 "gemma-4"
)
```
2. 要启用思考模式,请使用 `enable_thinking = True / False` 在 `tokenizer.apply_chat_template`
已启用思考:
processor.tokenizer.apply_chat_template([
       {"role" : "user", "content" : "2+2 等于多少?"},
   ], tokenize = False, enable_thinking = True, add_generation_prompt = True)
将打印 `<|turn>system\n<|think|>\n<|turn>user\n2+2 等于多少?\n<|turn>model\n`
已禁用思考:
```python
processor.tokenizer.apply_chat_template([
{"role" : "user", "content" : "2+2 等于多少?"},
], tokenize = False, enable_thinking = False, add_generation_prompt = True)
```
将打印 `<|turn>user\n2+2 等于多少?\n<|turn>model\n<|channel>thought\n`
3. Gemma 4 支持 140 种语言,因此在多语言微调方面非常强大。
4. 建议训练 **E4B QLoRA** 而不是 **E2B LoRA** ,因为 E4B 更大,而且量化精度差异微乎其微。Gemma 4 E4B LoRA 甚至更好。
5. 微调后,你可以导出为 [GGUF](#saving-export-your-fine-tuned-model) (用于 llama.cpp/Unsloth/Ollama 等)
### ⚡快速开始
#### 🦥 Unsloth Studio 指南
{% columns %}
{% column %}
Gemma 4 可以在 [Unsloth Studio](/docs/zh/xin/studio.md)中运行和微调,这是我们新的本地 AI 开源网页 UI。
使用 Unsloth Studio,你可以在 **MacOS、Windows**、Linux 上本地运行模型并训练 NVIDIA GPU。Intel、MLX 和 AMD 训练支持将于本月推出。
{% endcolumn %}
{% column %}


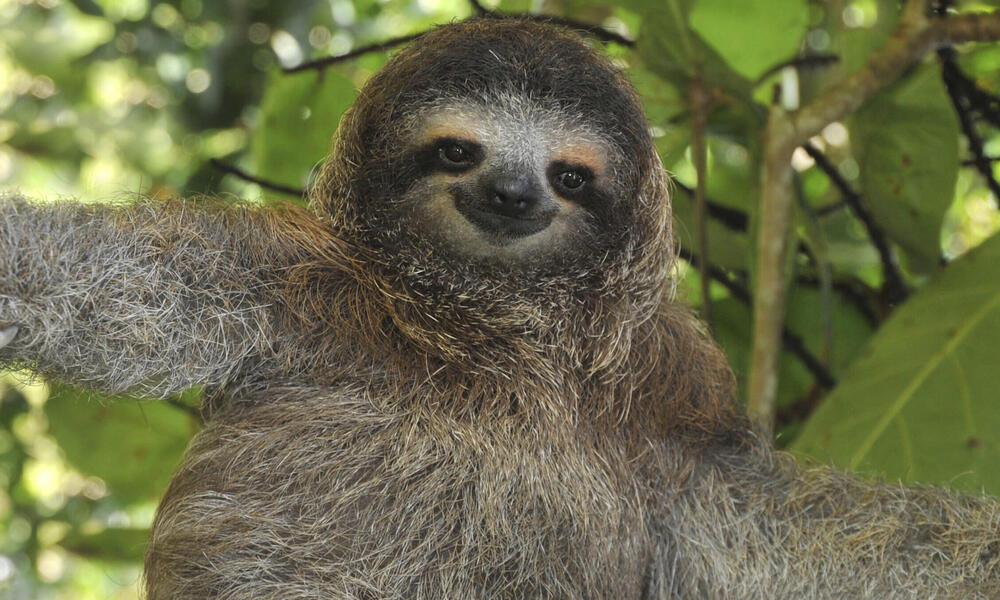 """
sloth_link = "https://files.worldwildlife.org/wwfcmsprod/images/Sloth_Sitting_iStock_3_12_2014/story_full_width/8l7pbjmj29_iStock_000011145477Large_mini__1_.jpg"
messages = [{
"role" : "user",
"content": [
{ "type": "image", "image" : sloth_link },
{ "type": "text", "text" : "这只动物出演了哪些电影?" }
]
}]
# 你可能需要等待 1 分钟,等待 Unsloth 的自动编译器
do_gemma_4_inference(messages, max_new_tokens = 256)
"""给树懒写一首诗吧!"""
messages = [{
"role": "user",
"content": [{ "type" : "text",
"text" : "写一首关于树懒的诗。" }]
}]
do_gemma_4_inference(messages)
"""# 让我们微调 Gemma 4!
你现在可以通过选择来微调视觉和文本部分——音频部分也可以微调——我们正在努力让它也可被选择!
现在我们添加 LoRA 适配器,这样只需更新少量参数!
"""
model = FastModel.get_peft_model(
model,
finetune_vision_layers = False, # 仅文本时关闭!
finetune_language_layers = True, # 应保持开启!
finetune_attention_modules = True, # 注意力模块适合 GRPO
finetune_mlp_modules = True, # 应始终保持开启!
r = 8, # 越大 = 精度越高,但可能过拟合
lora_alpha = 8, # 建议 alpha 至少等于 r
lora_dropout = 0,
bias = "none",
random_state = 3407,
)
"""
### 数据准备
我们现在使用 `Gemma-4` 格式进行对话风格微调。我们使用 [Maxime Labonne 的 FineTome-100k](https://huggingface.co/datasets/mlabonne/FineTome-100k) 数据集,采用 ShareGPT 风格。Gemma-4 会像下面这样呈现多轮对话:
```
<|turn>user
你好
<|turn>model
嗨!
```
我们使用 `get_chat_template` 函数来获取正确的聊天模板。我们支持 `zephyr, chatml, mistral, llama, alpaca, vicuna, vicuna_old, phi3, llama3, phi4, qwen2.5, gemma3, gemma-4` 等更多模板。
"""
from unsloth.chat_templates import get_chat_template
tokenizer = get_chat_template(
tokenizer,
chat_template = "gemma-4-thinking",
)
"""我们取数据集的前 3000 行"""
from datasets import load_dataset
dataset = load_dataset("mlabonne/FineTome-100k", split = "train[:3000]")
"""我们现在使用 `standardize_data_formats` 尝试将数据集转换为适合微调用途的正确格式!"""
from unsloth.chat_templates import standardize_data_formats
dataset = standardize_data_formats(dataset)
"""让我们看看第 100 行是什么样!"""
dataset[100]
"""我们现在必须将 `Gemma-3` 的聊天模板应用到这些对话上,并保存到 `text`。由于我们正在微调,因此使用 removeprefix(`''`) 去掉 `` 令牌。Processor 会在训练前添加这个令牌,而模型只期望一个。"""
def formatting_prompts_func(examples):
convos = examples["conversations"]
texts = [tokenizer.apply_chat_template(convo, tokenize = False, add_generation_prompt = False).removeprefix('') for convo in convos]
return { "text" : texts, }
dataset = dataset.map(formatting_prompts_func, batched = True)
"""让我们看看聊天模板效果如何!注意这里没有 `` 令牌,因为处理器 tokenizer 会添加一个。"""
dataset[100]["text"]
"""
### 训练模型
现在让我们训练模型。我们做 60 步来加快速度,但如果要完整运行,你可以设置 `num_train_epochs=1`,并关闭 `max_steps=None`。
"""
from trl import SFTTrainer, SFTConfig
trainer = SFTTrainer(
model = model,
tokenizer = tokenizer,
train_dataset = dataset,
eval_dataset = None, # 可设置评估!
args = SFTConfig(
dataset_text_field = "text",
per_device_train_batch_size = 1,
gradient_accumulation_steps = 4, # 使用 GA 来模拟 batch size!
warmup_steps = 5,
# num_train_epochs = 1, # 将此设置为一次完整训练。
max_steps = 60,
learning_rate = 2e-4, # 长训练时降到 2e-5
logging_steps = 1,
optim = "adamw_8bit",
weight_decay = 0.001,
lr_scheduler_type = "linear",
seed = 3407,
report_to = "none", # 使用 TrackIO/WandB 等
),
)
"""我们还使用 Unsloth 的 `train_on_completions` 方法,仅训练助手输出并忽略用户输入上的损失。这有助于提高微调准确率!"""
from unsloth.chat_templates import train_on_responses_only
trainer = train_on_responses_only(
trainer,
instruction_part = "<|turn>user\n",
response_part = "<|turn>model\n",
)
"""让我们确认对指令部分的掩码已完成!再打印一次第 100 行。注意样本现在如预期只有单个 ``!"""
tokenizer.decode(trainer.train_dataset[100]["input_ids"])
"""现在让我们打印被掩码后的示例——你应该只会看到答案:"""
tokenizer.decode([tokenizer.pad_token_id if x == -100 else x for x in trainer.train_dataset[100]["labels"]]).replace(tokenizer.pad_token, " ")
"""# 让我们训练模型!
要恢复训练,请设置 `trainer.train(resume_from_checkpoint = True)`
"""
trainer_stats = trainer.train()
````
{% endcode %}
{% hint style="info" %}
如果你 OOM:
* 降低 `per_device_train_batch_size` 改为 **1** 和/或减少 `max_seq_length`.
* 保持 `use_`[`gradient_checkpointing`](/docs/zh/bo-ke/500k-context-length-fine-tuning.md#unsloth-gradient-checkpointing-enhancements)`="unsloth"` 开启(它旨在减少显存使用并延长上下文长度)。
{% endhint %}
**MoE(bf16 LoRA)加载示例:**
```python
import os
import torch
from unsloth import FastModel
model, tokenizer = FastModel.from_pretrained(
model_name = "unsloth/Gemma-4-26B-A4B-it",
max_seq_length = 2048,
load_in_4bit = False, # 不推荐 MoE QLoRA,稠密型 31B 可以
load_in_16bit = True, # bf16/16 位 LoRA
full_finetuning = False,
)
```
加载后,你会附加 LoRA 适配器,并像上面的 SFT 示例一样训练。
### 强化学习(RL)
你现在可以使用 [我们的免费笔记本](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_5_\(4B\)_Vision_GRPO.ipynb).
{% columns %}
{% column %}
用 RL 训练 Gemma 4 E2B 可在 9GB 上运行。
{% embed url="" %}
这个笔记本的目标是让 Gemma 4 学会使用 [GRPO](/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide.md#from-rlhf-ppo-to-grpo-and-rlvr).
模型将制定一种填充空白单元格的策略,我们会对正确放置以及完成有效谜题给予奖励。
即使 vLLM 不支持,你也可以通过设置以下内容,使用 Unsloth 运行 Gemma 4 RL `fast_inference=False` 在加载模型时:
{% endcolumn %}
{% column %}
 {% endcolumn %}
{% endcolumns %}
```python
from unsloth import FastLanguageModel
model, tokenizer = FastLanguageModel.from_pretrained(
model_name="unsloth/gemma-4-E2B-it",
fast_inference=False,
)
```
### MoE 微调(26B-A4B)
“ **26B-A4B** 模型是 Gemma 4 系列中速度 / 质量的折中选择。由于它是一个 **MoE** 模型,并且每个 token 只有一部分参数激活,因此更稳妥的微调方式是:
* 使用 **LoRA** 而不是完整微调
* 优先使用 **16 位 / bf16 LoRA** 如果显存允许
* 先从更短的上下文和更小的 rank 开始
* 只有在流水线稳定后再扩大规模
如果你的目标是最高质量,并且你有更多显存,请使用 **31B** 。
### 多模态微调(E2B / E4B)
由于 **E2B** 和 **E4B** 支持 **图像** 和 **音频**,它们是 Gemma 4 多模态微调的主要变体。
* 使用以下方式加载多模态模型 `FastVisionModel`
* 保持 `finetune_vision_layers = False` 首先
* 只微调语言层、注意力层和 MLP 层
* 如果你的任务需要,再稍后启用视觉或音频层
#### Gemma 4 多模态 LoRA 示例:
{% code expandable="true" %}
````python
from unsloth import FastVisionModel # FastLanguageModel for LLMs
import torch
model, processor = FastVisionModel.from_pretrained(
"unsloth/gemma-4-26B-A4B-it",
load_in_4bit = True, # 使用 4bit 以减少显存占用。若为 16bit LoRA,则设为 False。
use_gradient_checkpointing = "unsloth", # 长上下文时可设为 True 或 "unsloth"
)
"""现在我们添加 LoRA 适配器,用于参数高效微调,使我们能够只高效训练全部模型参数中的 1%。
**[NEW]** 我们也支持只微调视觉组件、只微调语言组件,或者两者都微调。此外,你还可以选择微调注意力模块、MLP 层,或者两者都微调!
"""
model = FastVisionModel.get_peft_model(
model,
finetune_vision_layers = True, # 如果不微调视觉层则设为 False
finetune_language_layers = True, # 如果不微调语言层则设为 False
finetune_attention_modules = True, # 如果不微调注意力层则设为 False
finetune_mlp_modules = True, # 如果不微调 MLP 层则设为 False
r = 32, # 越大,准确率越高,但可能过拟合
lora_alpha = 32, # 建议 alpha 至少等于 r
lora_dropout = 0,
bias = "none",
random_state = 3407,
use_rslora = False, # 我们支持 rank stabilized LoRA
loftq_config = None, # 也支持 LoftQ
target_modules = "all-linear", # 现在是可选项!如有需要可以指定列表
)
"""
### 数据准备
我们将使用一个手写数学公式的抽样数据集。目标是把这些图像转换为机器可读格式——具体来说是 LaTeX——这样它们就可以被渲染出来。这对复杂表达式尤其有用。
你可以在[这里](https://huggingface.co/datasets/unsloth/LaTeX_OCR)访问该数据集。完整数据集在[这里](https://huggingface.co/datasets/linxy/LaTeX_OCR)。
"""
from datasets import load_dataset
dataset = load_dataset("unsloth/LaTeX_OCR", split = "train")
"""让我们先概览一下这个数据集。我们将查看第二张图像及其对应的说明文字。"""
dataset
dataset[2]["image"]
dataset[2]["text"]
"""我们也可以直接在浏览器中渲染 LaTeX!"""
from IPython.display import display, Math, Latex
latex = dataset[3]["text"]
display(Math(latex))
"""要格式化数据集,所有视觉微调任务都应遵循以下格式:
```python
[
{
"role": "user",
"content": [
{"type": "text", "text": instruction},
{"type": "image", "image": sample["image"]},
],
},
{
"role": "user",
"content": [
{"type": "text", "text": instruction},
{"type": "image", "image": sample["image"]},
],
},
]
```
"""
instruction = "为这张图像写出其 LaTeX 表示。"
def convert_to_conversation(sample):
conversation = [
{
"role": "user",
"content": [
{"type": "text", "text": instruction},
{"type": "image", "image": sample["image"]},
],
},
{"role": "assistant", "content": [{"type": "text", "text": sample["text"]}]},
]
return {"messages": conversation}
pass
"""让我们把数据集转换成适合微调的“正确”格式:"""
converted_dataset = [convert_to_conversation(sample) for sample in dataset]
"""第一个示例如下所示:"""
converted_dataset[0]
"""让我们采用 Gemma 4 的指令聊天模板,并将其用于我们的基础模型"""
from unsloth import get_chat_template
processor = get_chat_template(
processor,
"gemma-4-thinking"
)
"""在微调之前,让我们评估一下基础模型的表现。我们不指望有很强的结果,因为它之前还没有见过这种聊天模板。"""
image = dataset[2]["image"]
instruction = "为这张图像写出其 LaTeX 表示。"
messages = [
{
"role": "user",
"content": [{"type": "image"}, {"type": "text", "text": instruction}],
}
]
input_text = processor.apply_chat_template(messages, add_generation_prompt = True)
inputs = processor(
image,
input_text,
add_special_tokens = False,
return_tensors = "pt",
).to("cuda")
from transformers import TextStreamer
text_streamer = TextStreamer(processor, skip_prompt = True)
result = model.generate(**inputs, streamer = text_streamer, max_new_tokens = 128,
use_cache = True, temperature = 1.0, top_p = 0.95, top_k = 64)
"""你可以看到这简直糟透了!它完全没有遵循指令
### 训练模型
现在让我们训练模型。我们进行了 60 步以加快速度,但你可以设置 `num_train_epochs=1` 来完整运行,并将 `max_steps=None` 关闭。我们也支持用于强化学习的 `DPOTrainer` 和 `GRPOTrainer`!!
我们使用新的 `UnslothVisionDataCollator`,它将帮助我们完成视觉微调设置。
"""
from unsloth.trainer import UnslothVisionDataCollator
from trl import SFTTrainer, SFTConfig
trainer = SFTTrainer(
model = model,
train_dataset = converted_dataset,
processing_class = processor.tokenizer,
data_collator = UnslothVisionDataCollator(model, processor),
args = SFTConfig(
per_device_train_batch_size = 1,
gradient_accumulation_steps = 4,
max_grad_norm = 0.3,
warmup_ratio = 0.03,
max_steps = 60,
# num_train_epochs = 2, # 在完整训练运行时,请用这个替代 max_steps
learning_rate = 2e-4,
logging_steps = 1,
save_strategy = "steps",
optim = "adamw_8bit",
weight_decay = 0.001,
lr_scheduler_type = "cosine",
seed = 3407,
output_dir = "outputs",
report_to = "none", # 用于 Weights and Biases 或其他工具
# 视觉微调时你必须加入以下项目:
remove_unused_columns = False,
dataset_text_field = "",
dataset_kwargs = {"skip_prepare_dataset": True},
max_length = 2048,
)
)
trainer_stats = trainer.train()
````
{% endcode %}
#### 图像示例格式
请记住:对于 Gemma 4 多模态提示,将图像放在 **之前** 文本指令。
{% code expandable="true" %}
```json
{
"messages": [
{
"role": "user",
"content": [
{"type": "image", "image": "/path/to/image OR object"},
{"type": "text", "text": "从这张收据中提取所有文本。以 JSON 形式返回行项目、总计、商家和日期。"}
]
},
{
"role": "assistant",
"content": [
{"type": "text", "text": "{\"merchant\": \"Example Store\", \"total\": \"19.99\"}"}
]
}
]
}
```
{% endcode %}
#### 音频示例格式
音频仅用于 **E2B / E4B** 。请保持片段简短,并且与任务相关。
{% code expandable="true" %}
```json
{
"messages": [
{
"role": "user",
"content": [
{"type": "audio", "audio": "/path/to/audio OR object"},
{"type": "text", "text": "将下面这段英文语音转写为英文文本。只输出转写内容。"}
]
},
{
"role": "assistant",
"content": [
{"type": "text", "text": "大家好,欢迎回来。"}
]
}
]
}
```
{% endcode %}
### 保存 / 导出微调后的模型
你可以查看我们针对以下内容的特定推理 / 部署指南: [Unsloth Studio](/docs/zh/xin/studio/export.md), [llama.cpp](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/saving-to-gguf.md), [vLLM](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/vllm-guide.md), [llama-server](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/llama-server-and-openai-endpoint.md), [Ollama](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/saving-to-ollama.md) 或 [SGLang](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/sglang-guide.md).
#### 保存为 GGUF
Unsloth 支持直接保存为 GGUF:
```python
model.save_pretrained_gguf("directory", tokenizer, quantization_method = "q4_k_m")
model.save_pretrained_gguf("directory", tokenizer, quantization_method = "q8_0")
model.save_pretrained_gguf("directory", tokenizer, quantization_method = "f16")
```
或者将 GGUF 推送到 Hugging Face:
```python
model.push_to_hub_gguf("hf_username/directory", tokenizer, quantization_method = "q4_k_m")
model.push_to_hub_gguf("hf_username/directory", tokenizer, quantization_method = "q8_0")
```
如果导出的模型在另一个运行时中的表现更差,Unsloth 会指出最常见的原因: **推理时使用了错误的聊天模板 / EOS 标记** (你必须使用与你训练时相同的聊天模板)。
更多细节请阅读我们的推理指南:
{% columns %}
{% column width="50%" %}
{% content-ref url="/pages/9a72670992feb75def412a693565c84a88c8a266" %}
[推理与部署](/docs/zh/ji-chu-zhi-shi/inference-and-deployment.md)
{% endcontent-ref %}
{% content-ref url="/pages/b83d88f106d75c3396c46f5342fb401501910093" %}
[GGUF & llama.cpp](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/saving-to-gguf.md)
{% endcontent-ref %}
{% endcolumn %}
{% column width="50%" %}
{% content-ref url="/pages/f7c3389bdba9af3050e66a941596d827cdb11e0b" %}
[Model Export](/docs/zh/xin/studio/export.md)
{% endcontent-ref %}
{% content-ref url="/pages/9f0e22d200c9105481e4854b8473aba99ca44835" %}
[vLLM](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/vllm-guide.md)
{% endcontent-ref %}
{% endcolumn %}
{% endcolumns %}
### Gemma 4 数据最佳实践
Gemma 4 有几个格式细节需要你注意。
#### 1. 使用标准聊天角色
Gemma 4 使用标准的:
* `system`
* `user`
* `assistant`
这意味着你的 SFT 数据集应写成常规聊天格式,而不是旧版 Gemma 特定的角色格式。
#### 2. 思考模式是显式的
如果你想在 SFT 期间保留思考式行为:
* 保持格式一致
* 决定你想训练的是 **可见的思考块** 还是 **仅最终答案**
* 要 **不要** 在同一数据集中混用多种不兼容的思考格式
对于大多数生产级助手来说,最简单的设置是只对 **最终可见答案**.
#### 3. 多轮规则
对于多轮对话,只保留 **最终可见答案** 在对话历史中。不要 **不要** 把更早的思考块再喂回后续轮次。
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://unsloth.ai/docs/zh/mo-xing/gemma-4/train.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.

