> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/fp8-reinforcement-learning.md).

# FP8 强化学习

使用 Unsloth 以 FP8 精度训练强化学习（RL）和 GRPO。

我们正在为 RL 引入 FP8 精度训练，使 FP8 GRPO 现在可以在 **消费级 GPU 上** （RTX 40、50 等）。DeepSeek-R1 展示了 FP8 的强大潜力，而借助 Unsloth，Qwen3-1.7B 的 FP8 GRPO 现在仅需 **5GB VRAM**.

更快的 RL 推理至关重要，因为它是 RL 中计算最密集的工作负载。我们与 [TorchAO](https://github.com/pytorch/ao) PyTorch 的团队合作，实现了在不损失准确率的情况下提升性能。

* **约快 1.4×** 通过…进行 RL 推理 [vLLM](https://github.com/vllm-project/vllm) • 相比 BF16 和 FP16，上下文长度长 2 倍
* **减少 60% VRAM** 和 **长 10 倍** 的上下文，比其他 FP8 RL 实现更
* Unsloth 是 **唯一的框架** 能让 FP8 RL LoRA 在消费级 GPU（如 NVIDIA GeForce RTX 40 和 50 系列）上运行的框架。也可用于 H100、H200、B200 等。
* 使用 `load_in_fp8 = True` 在…中 `FastLanguageModel` 以启用 FP8 RL。
* 尽管 Qwen3-8B 可装入 16GB VRAM，但免费 Colab 的 NVIDIA Tesla T4 GPU **不支持 FP8**。因此我们的 notebook 使用 **24GB L4 GPU，可容纳 Qwen3-14B**.

**Notebook：** [Qwen3-8B FP8 GRPO](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_8B_FP8_GRPO.ipynb) 和 [Llama-3.2-1B FP8 GRPO](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Llama_FP8_GRPO.ipynb)

{% hint style="success" %}
额外内容： 你会注意到 Unsloth 现在使用的 VRAM 少了很多。我们很快会在新博客中分享细节。
{% endhint %}

我们的 FP8 支持使用了 Unsloth 的 [权重共享功能](/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/memory-efficient-rl.md)，又将 VRAM 占用减少了 **50%**，从而实现 **多 10 倍** 上下文长度，且不损失准确率。我们使用 [vLLM](https://github.com/vllm-project/vllm) 用于快速推理，而我们的技术，如 Unsloth [Standby](/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/memory-efficient-rl.md) 和 [Flex Attention](/docs/zh/mo-xing/gpt-oss-how-to-run-and-fine-tune/long-context-gpt-oss-training.md) 以进一步减少 VRAM 占用。TorchAO 支持通用的即时 FP8，因此 Llama、Gemma、Mistral 等都能工作。我们还 [上传了](#unsloth-fp8-uploads) 大多数 FP8 模型（包括 Qwen3）。

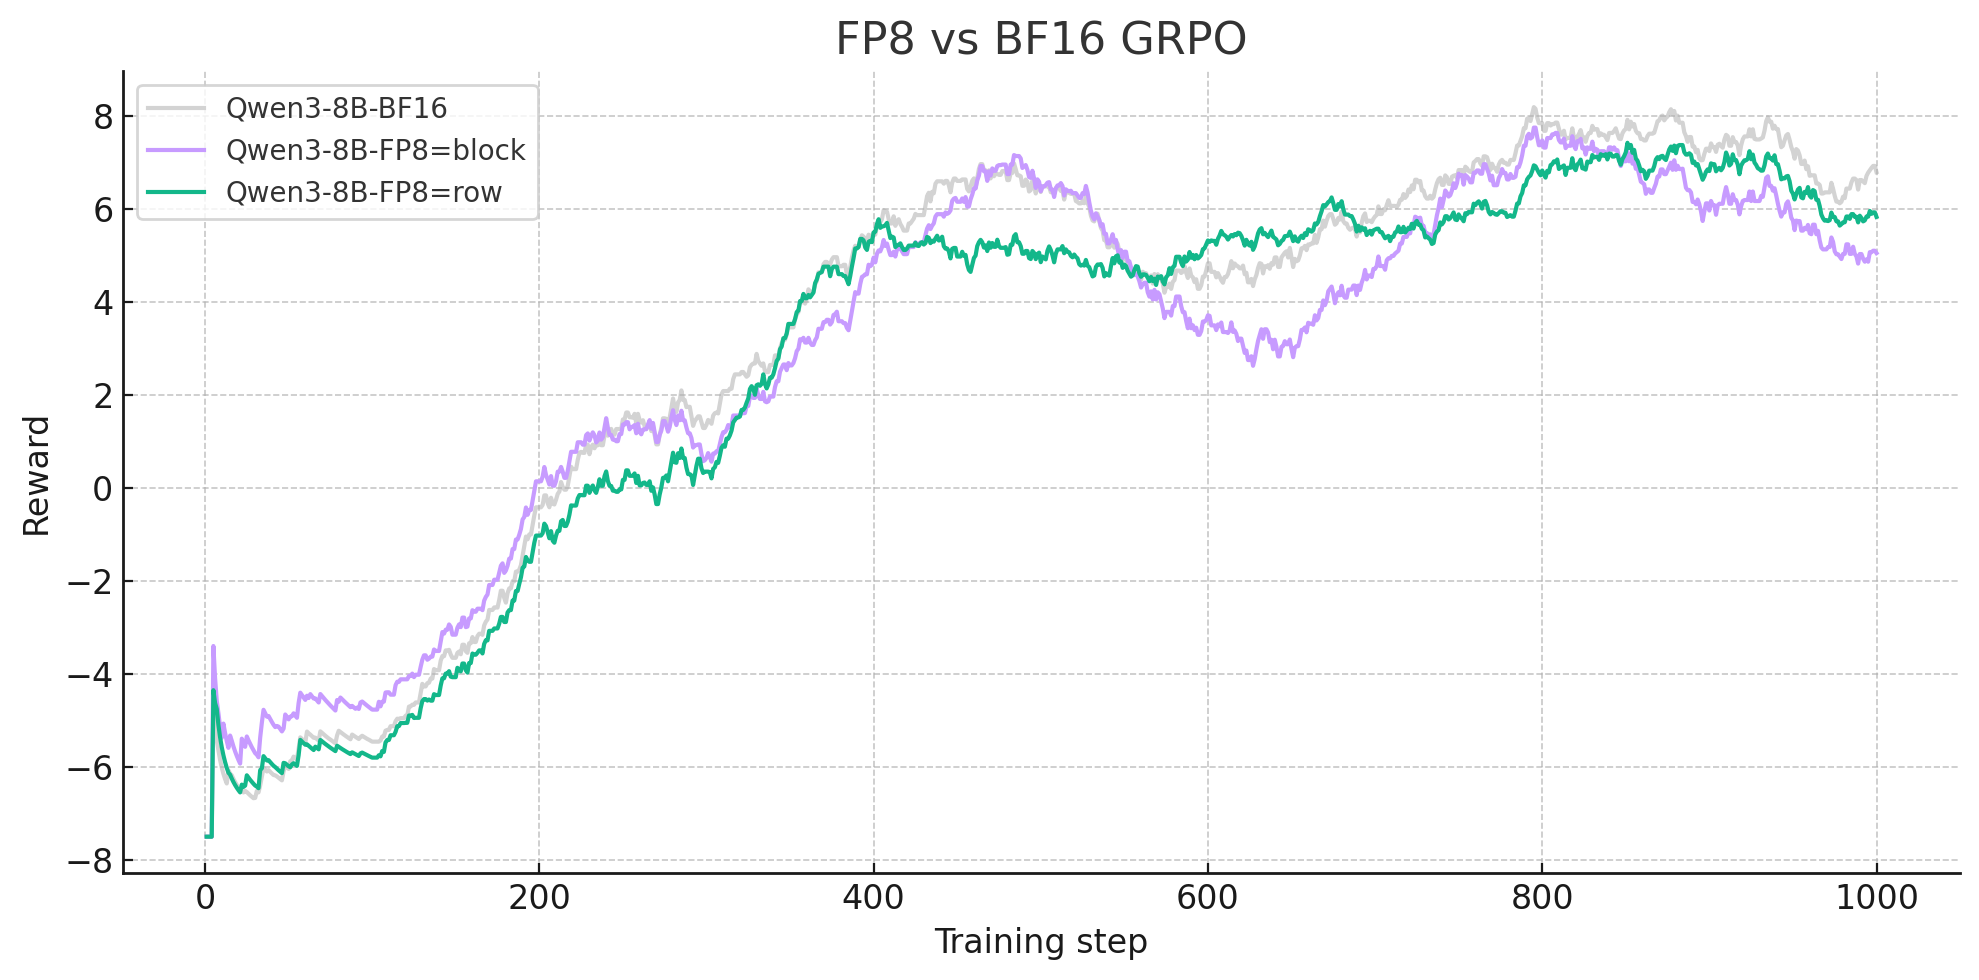
<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FNhbi7jRc6zwCAeuddBBk%2Foutput(14).png?alt=media&amp;token=80ad0712-4626-4536-aa57-29bc53b40540" alt="" width="375"><figcaption><p>奖励曲线显示 FP8 与 BF16 走势一致</p></figcaption></figure>

### :sunflower:FP8 与 BF16 训练

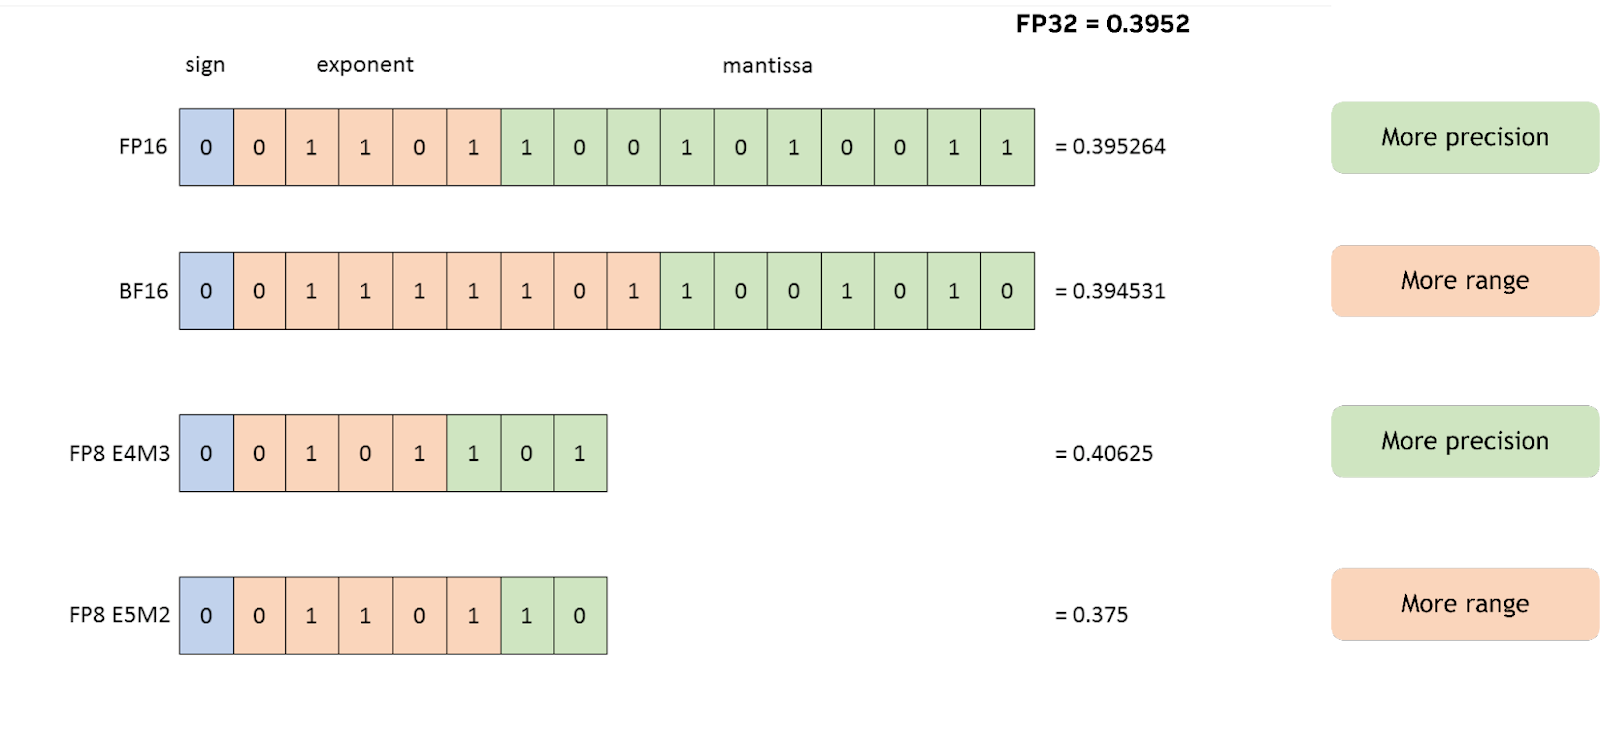
研究表明，FP8 训练在很大程度上可以达到与 BF16 相当的准确率，而且如果你以 FP8 提供模型服务， **训练和部署使用相同精度** 有助于保持准确率。此外，与 BF16 相比，FP8 在 H100 上吞吐量高 1.6 倍，内存占用低 2 倍。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FApLfXUBVZSbjpPhRJG6z%2Ffp8%20f16%20quant.png?alt=media&amp;token=77a2917a-f191-44a7-8597-6796fcf24ed7" alt="" width="375"><figcaption></figcaption></figure>

#### 权重缩放与 FP8 类型

量化训练会保存低精度权重（例如 FP8）以及更高精度的缩放因子（FP16/BF16/FP32）。你可以通过以下方式近似恢复原始权重： `original_weight ≈ quantized_weight * weight_scale`

缩放因子会把权重的范围映射到 FP8 可表示的范围。更多的缩放因子通常会提高准确率，但会额外占用高精度内存，因此这是一种权衡。 [DeepSeek R1](https://arxiv.org/abs/2501.12948)例如，主要偏向块量化。

vLLM 定义了 3 种常见的 FP8 类型 [llm-compressor](https://github.com/vllm-project/llm-compressor)。我们在这 3 种类型上对 Qwen3-8B 进行了基准测试，并检查了吞吐量、MMLU Pro 和 GQPA Diamond。我们发现 **FP8 按块或按通道（-FP8-Dynamic）是最佳选择** ，无论准确率还是吞吐量。

<table><thead><tr><th width="121">类型</th><th width="225.20001220703125"></th><th width="126.4000244140625">吞吐量</th><th width="121.60003662109375">MMLU Pro</th><th>GQPA Diamond</th></tr></thead><tbody><tr><td></td><td>Bfloat16 基线</td><td>11,367</td><td><strong>62.04%</strong></td><td>28.79%</td></tr><tr><td>按块</td><td>每个块使用缩放因子（128×128）</td><td>12,041</td><td><strong>62.37%</strong></td><td><strong>29.29%</strong></td></tr><tr><td>按通道</td><td>每行或每列 1 个缩放因子</td><td>12,963</td><td>61.89%</td><td><strong>31.82%</strong></td></tr><tr><td>按张量</td><td>整个张量使用 1 个缩放因子</td><td><strong>13,681</strong></td><td>61.83%</td><td>27.78%</td></tr></tbody></table>

### :zap:FP8 性能基准

通过 vLLM 进行的 Unsloth FP8 RL 推理通常比 BF16 快 1.4 倍。如果模型更大，你可能会看到更明显的速度提升！

#### 准确率与训练损失基准

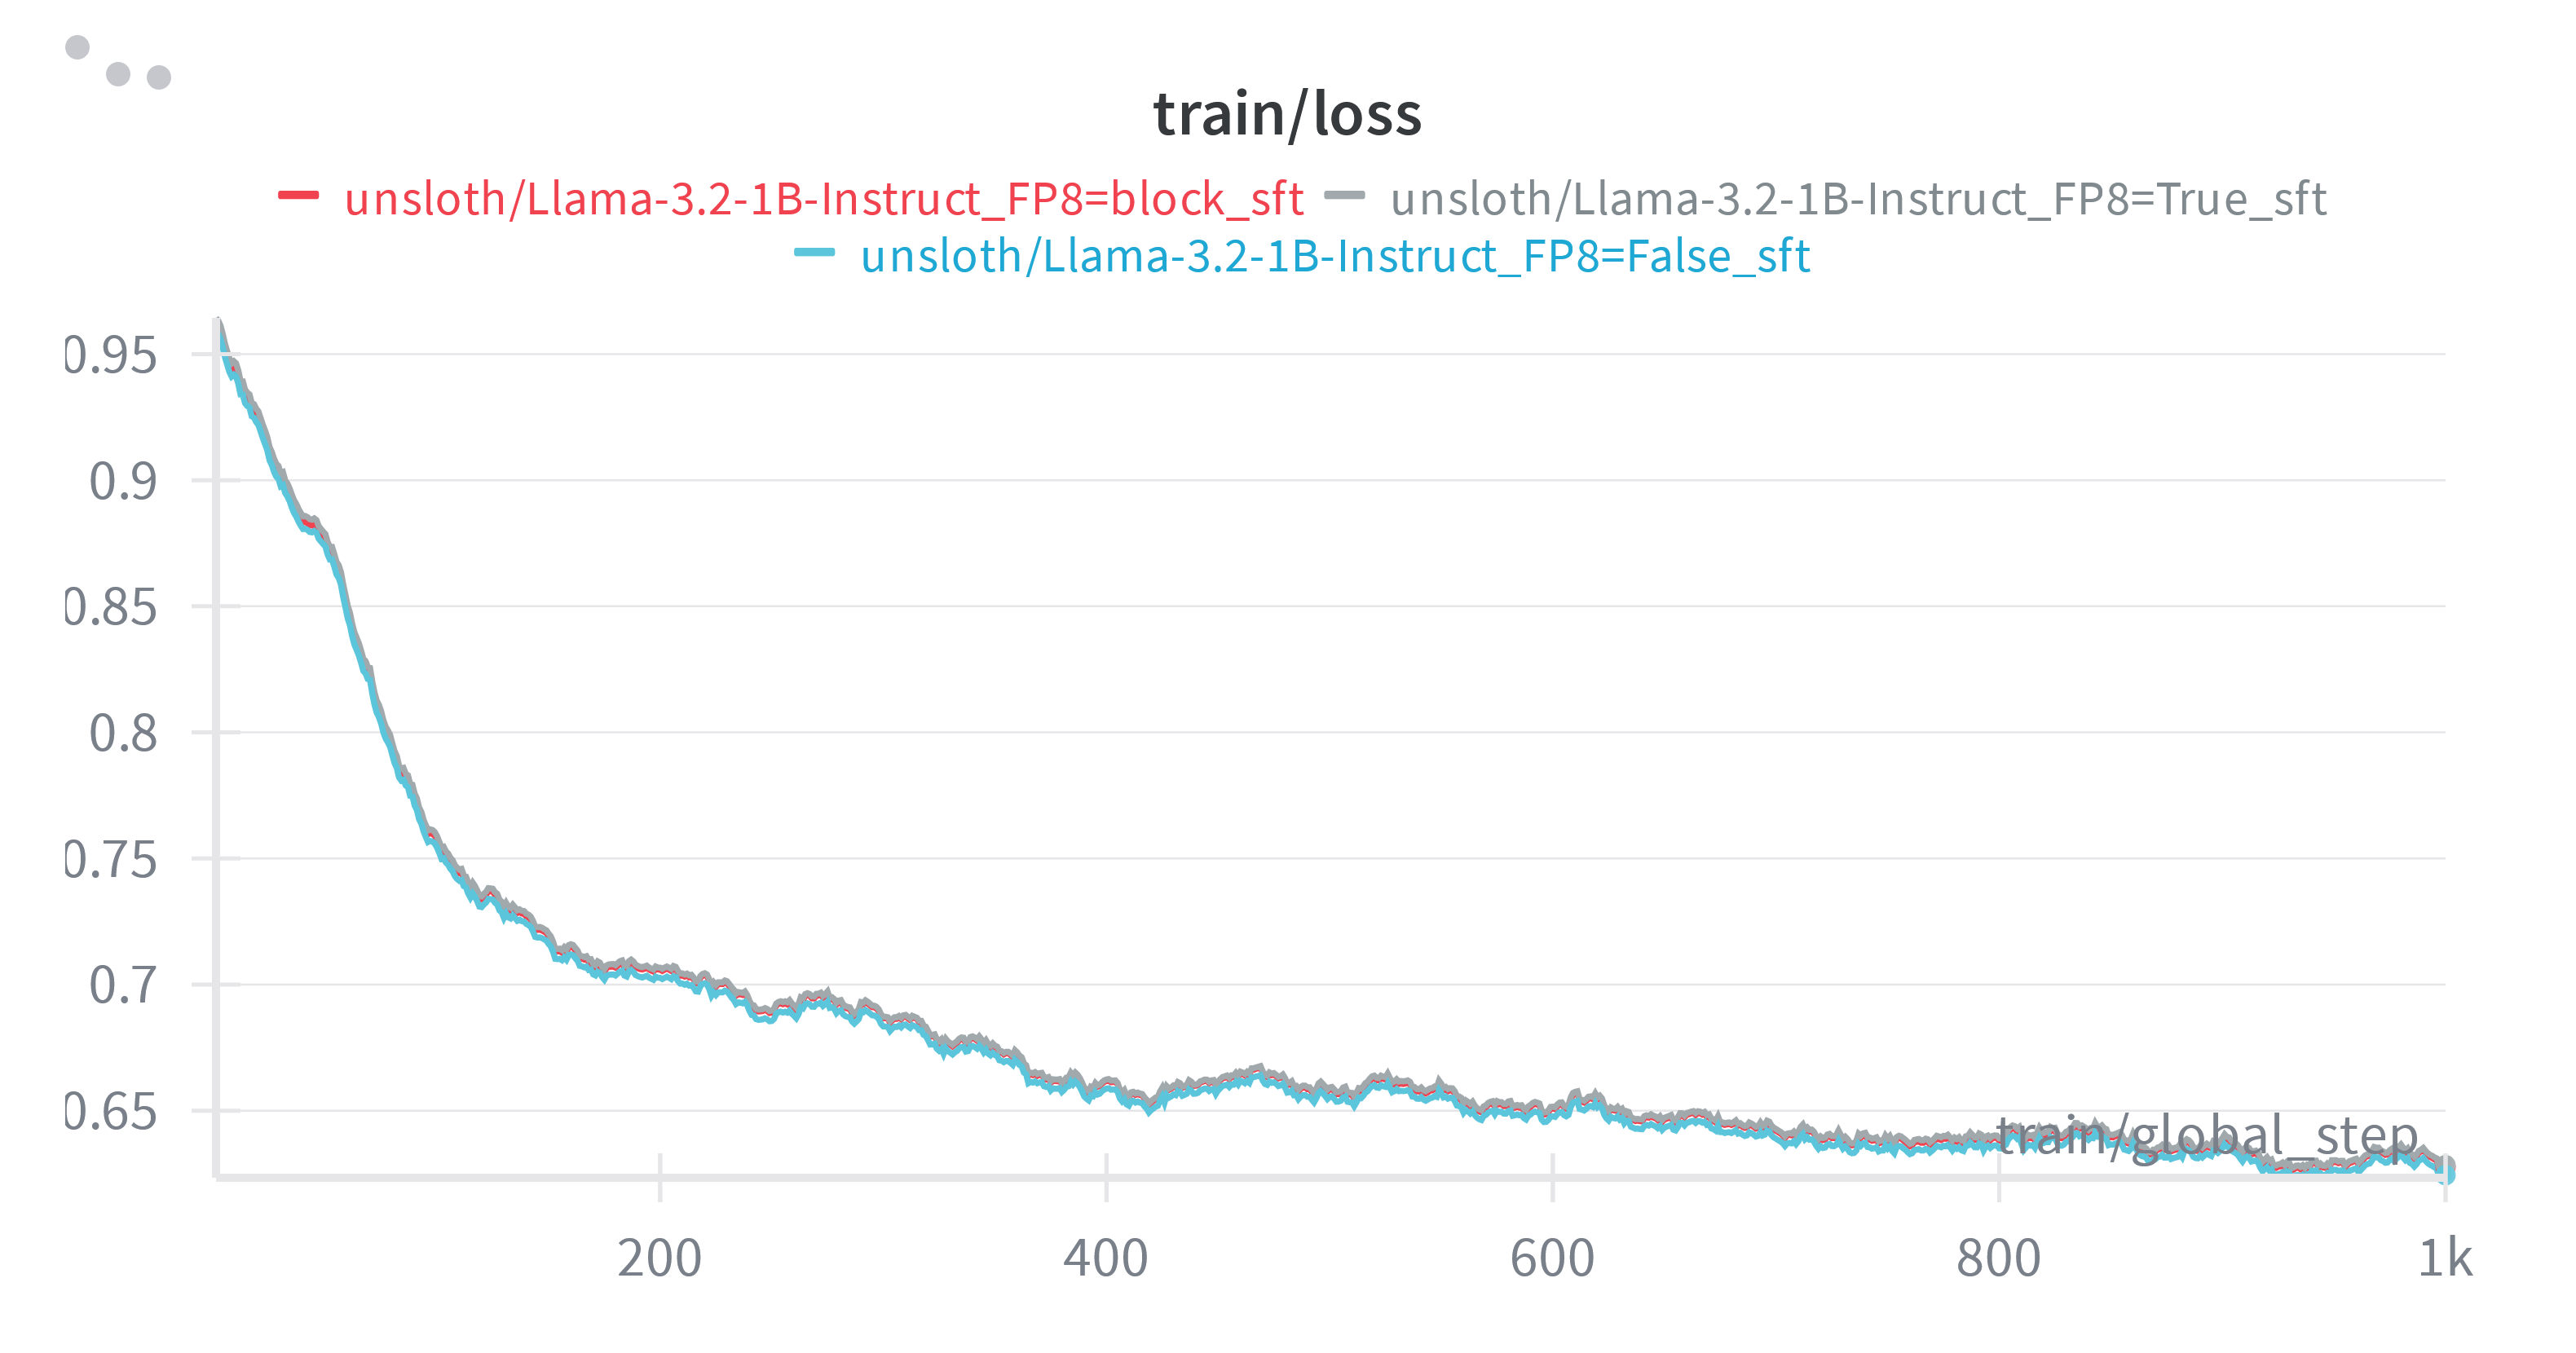
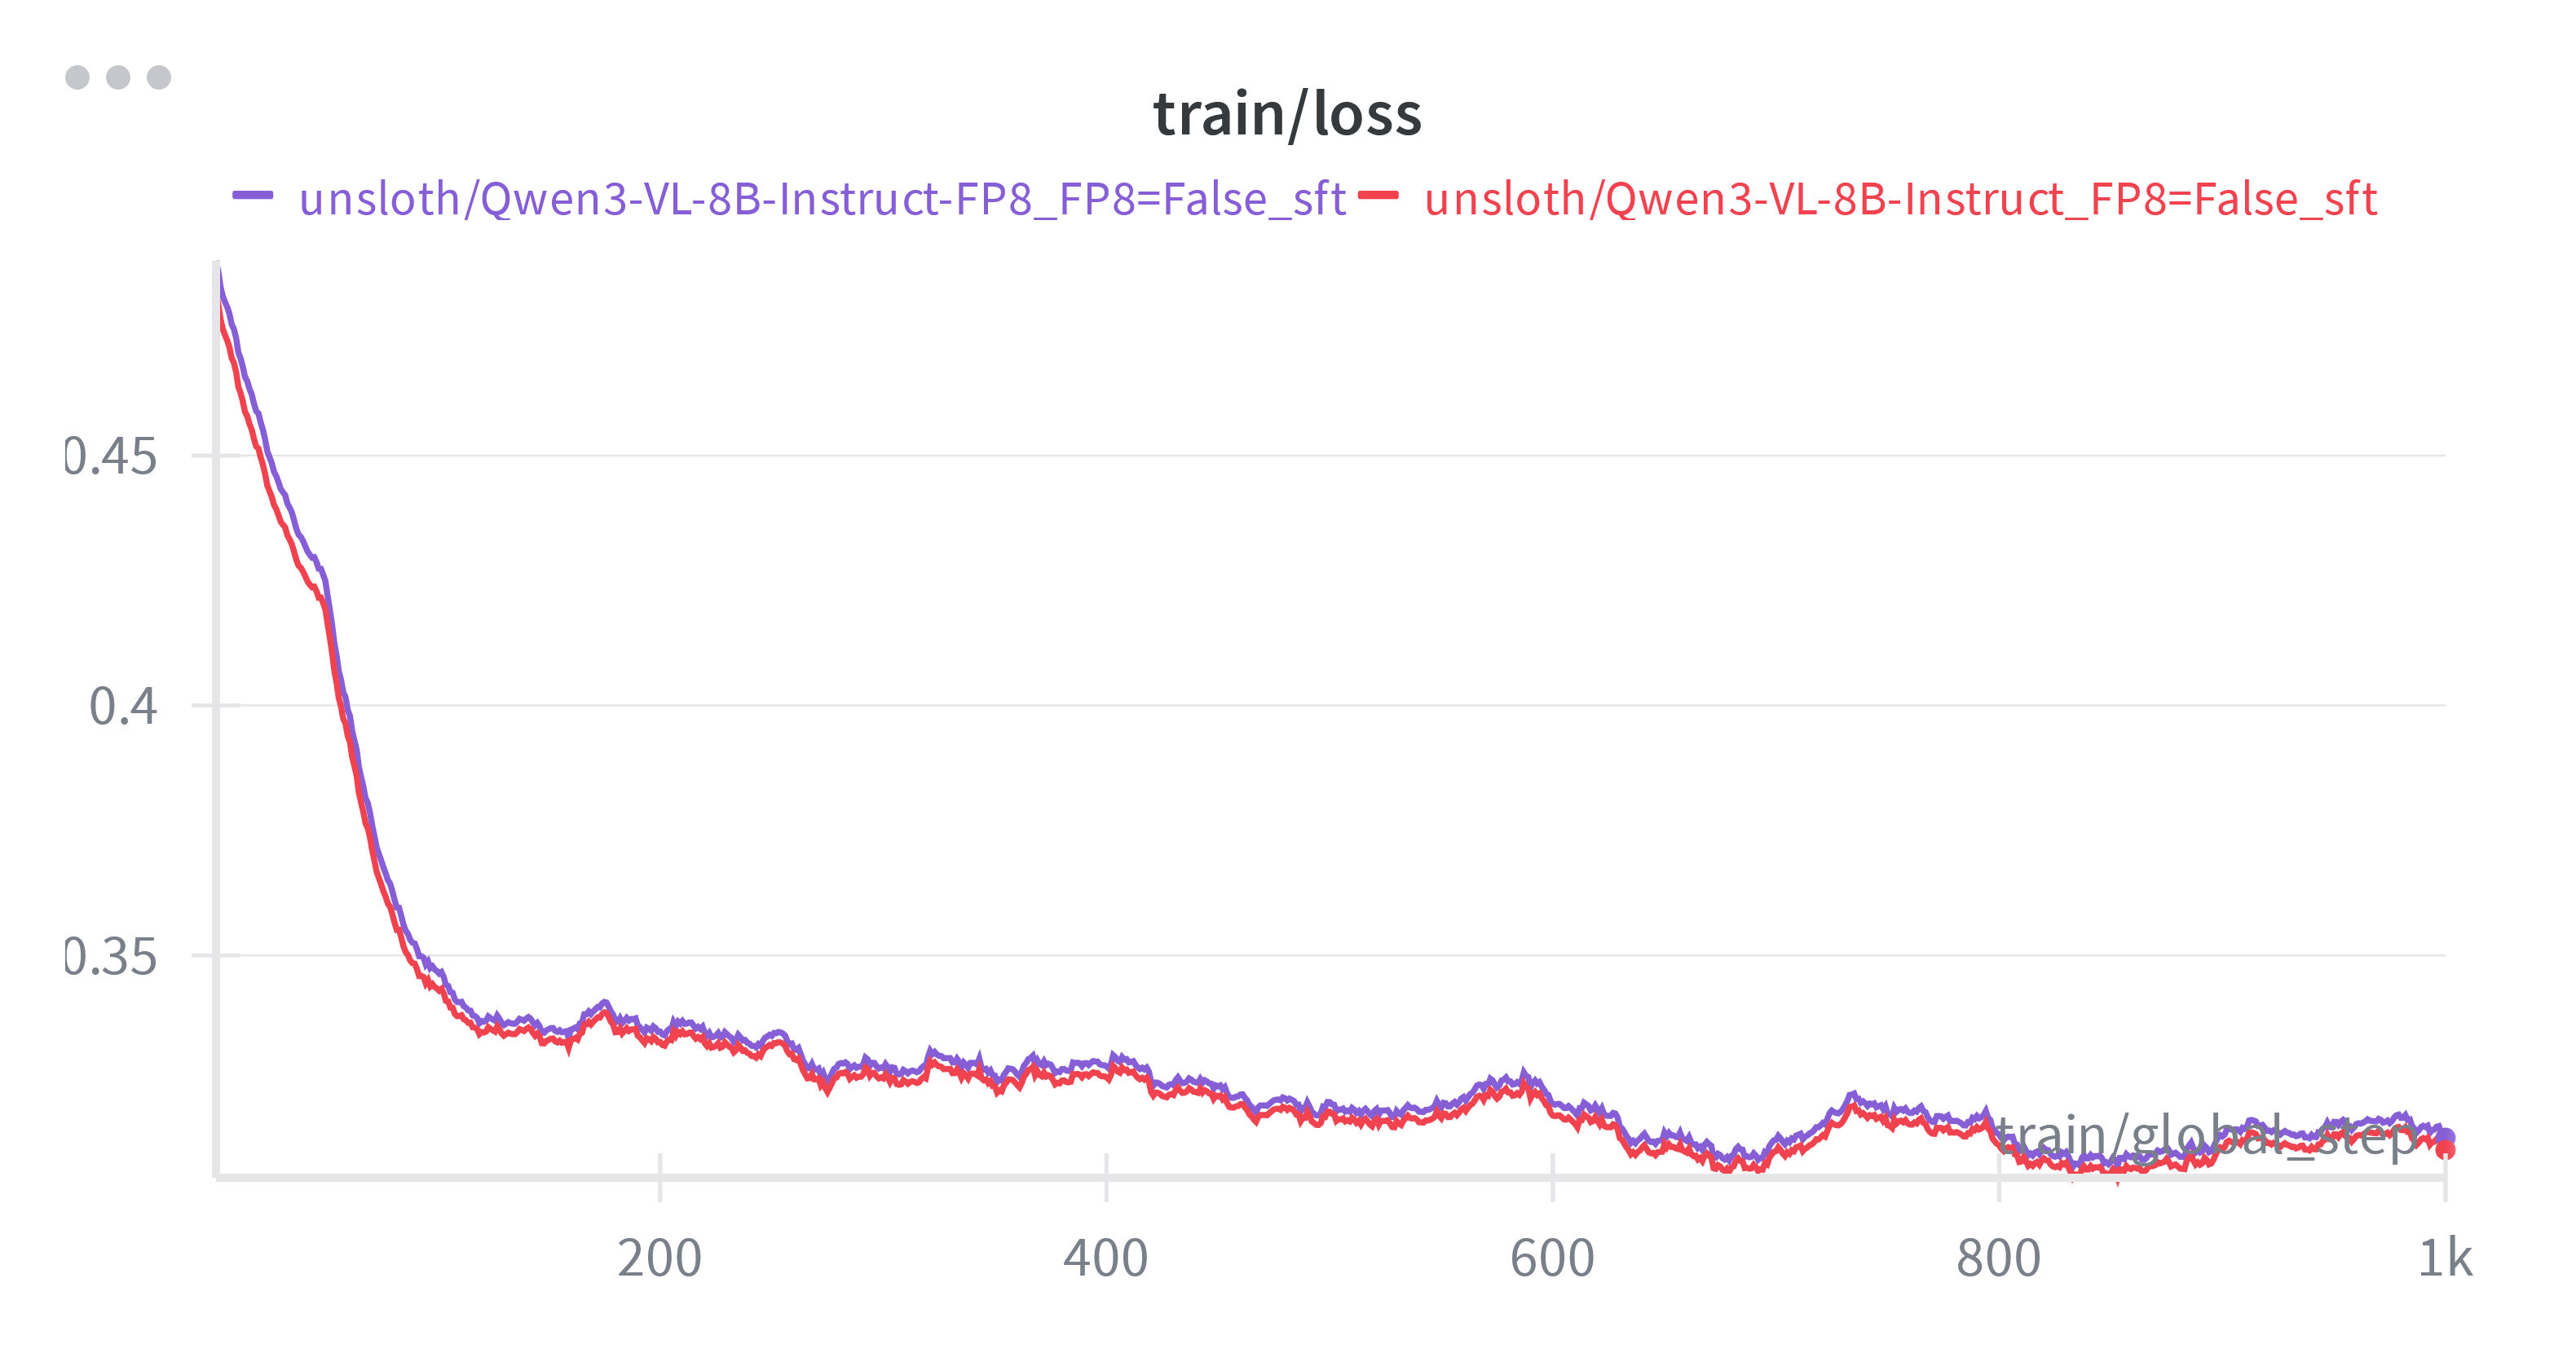
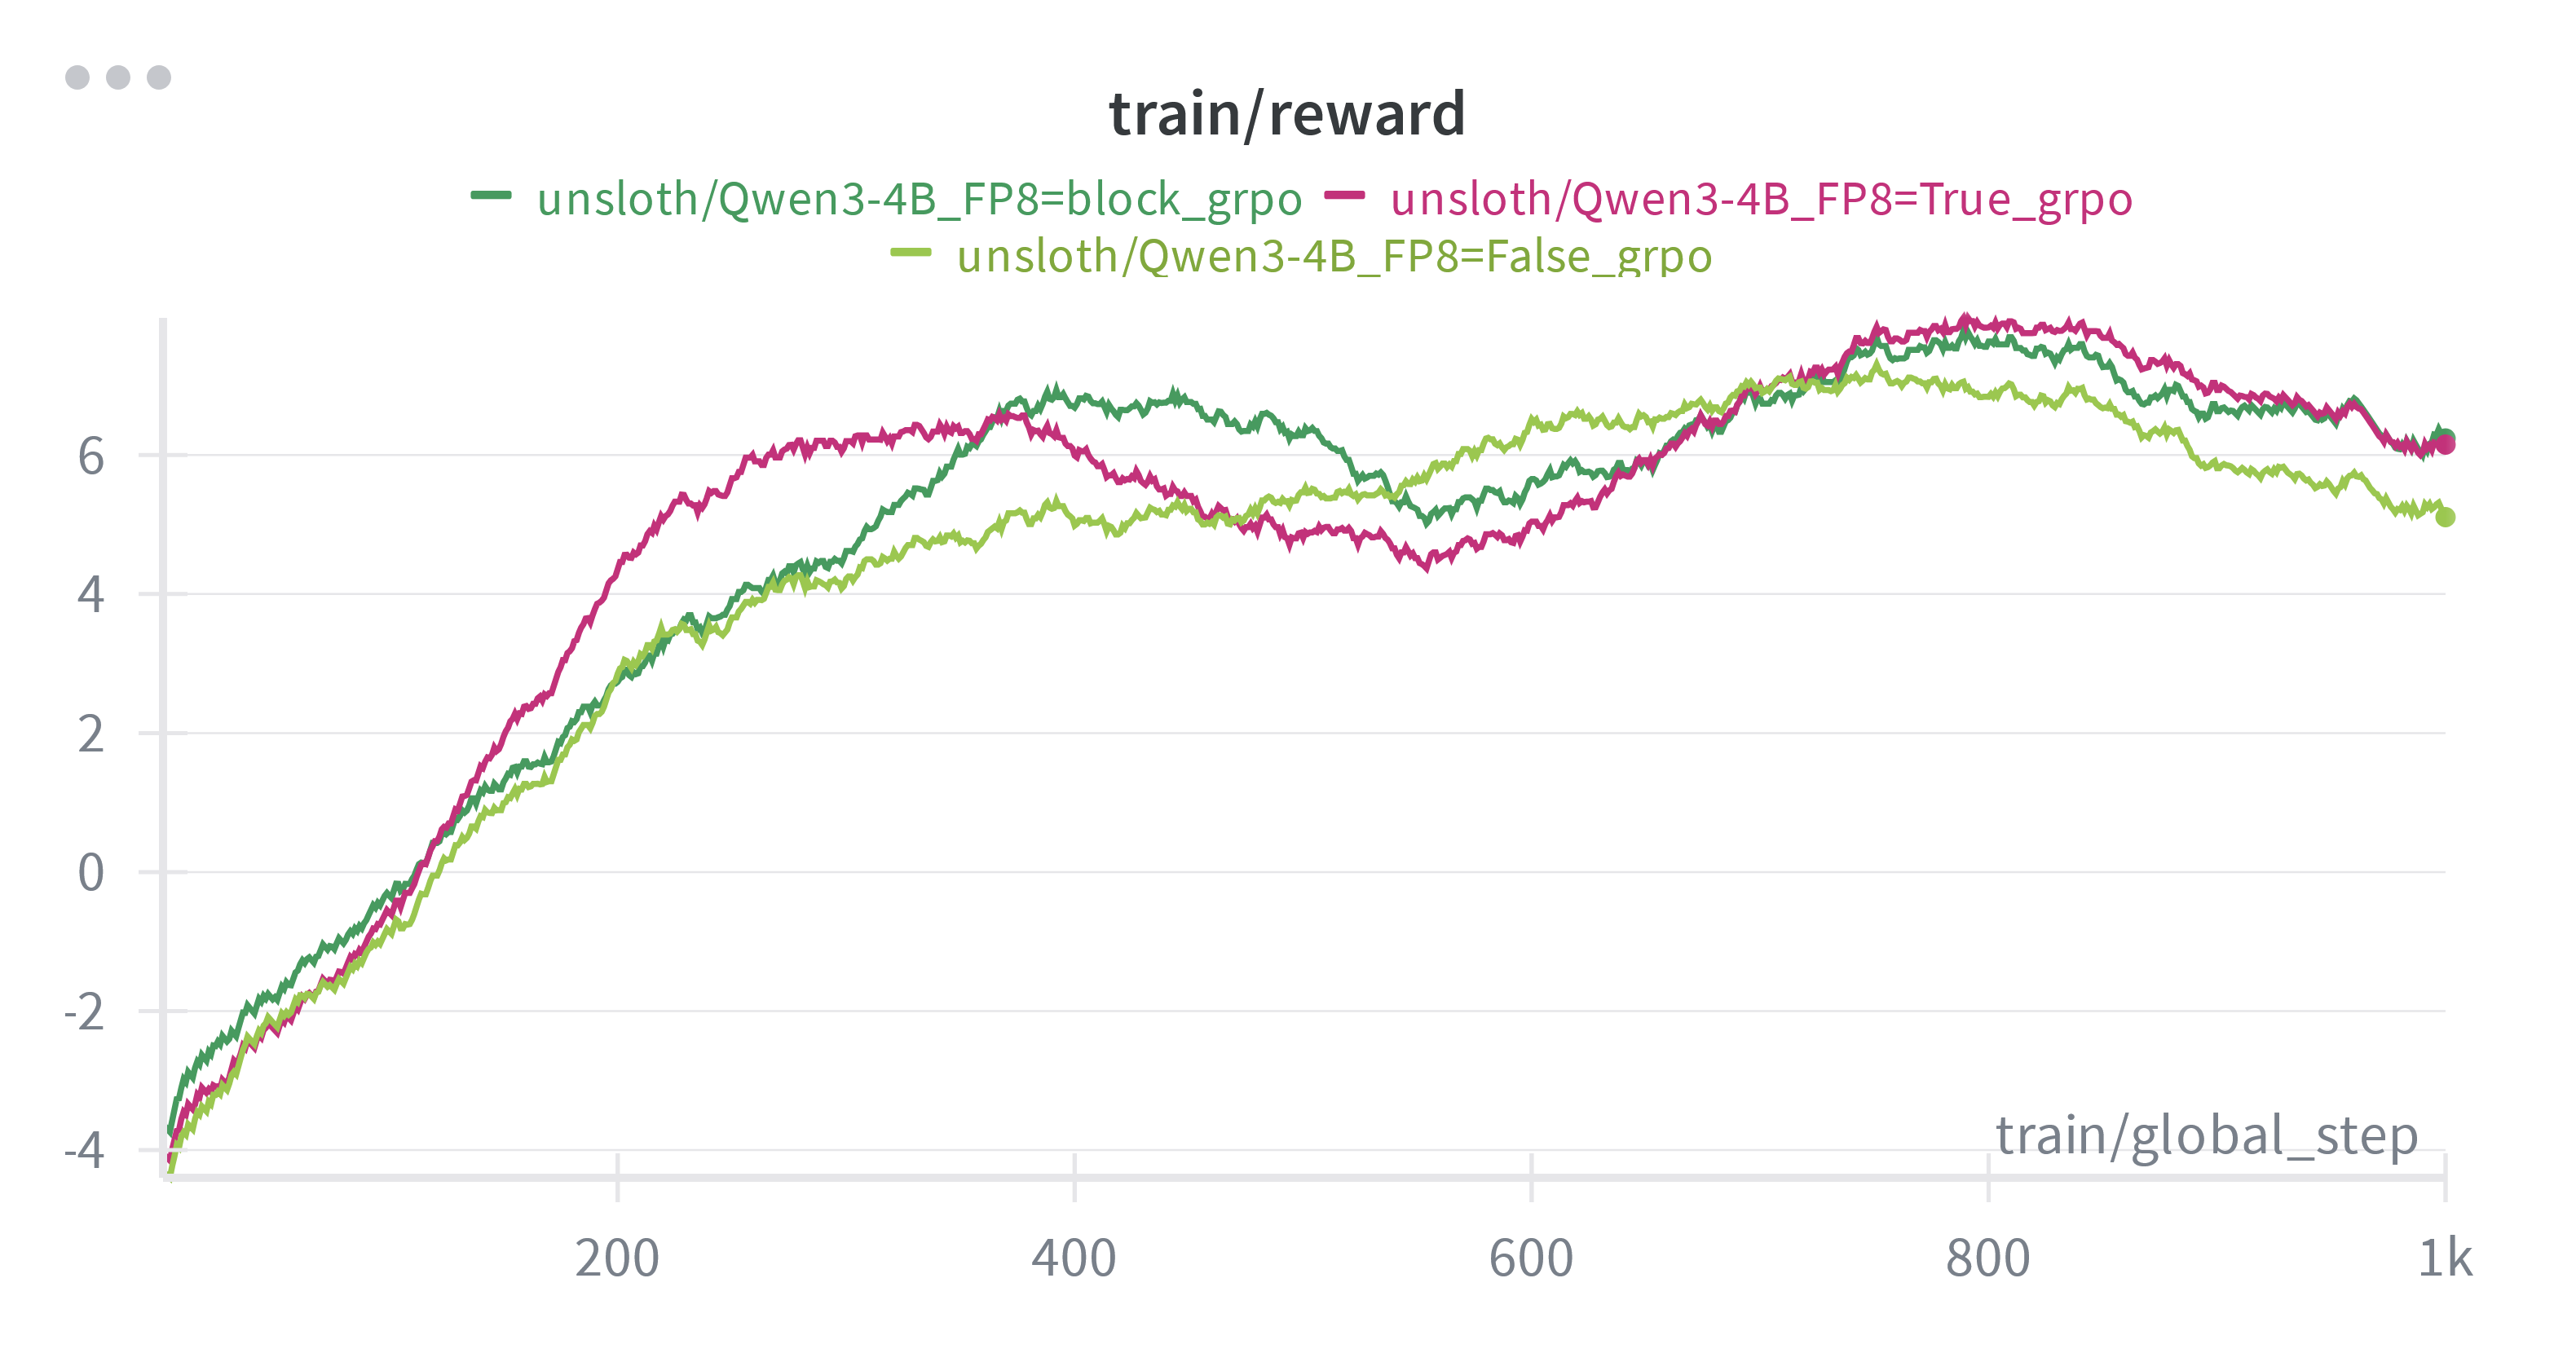
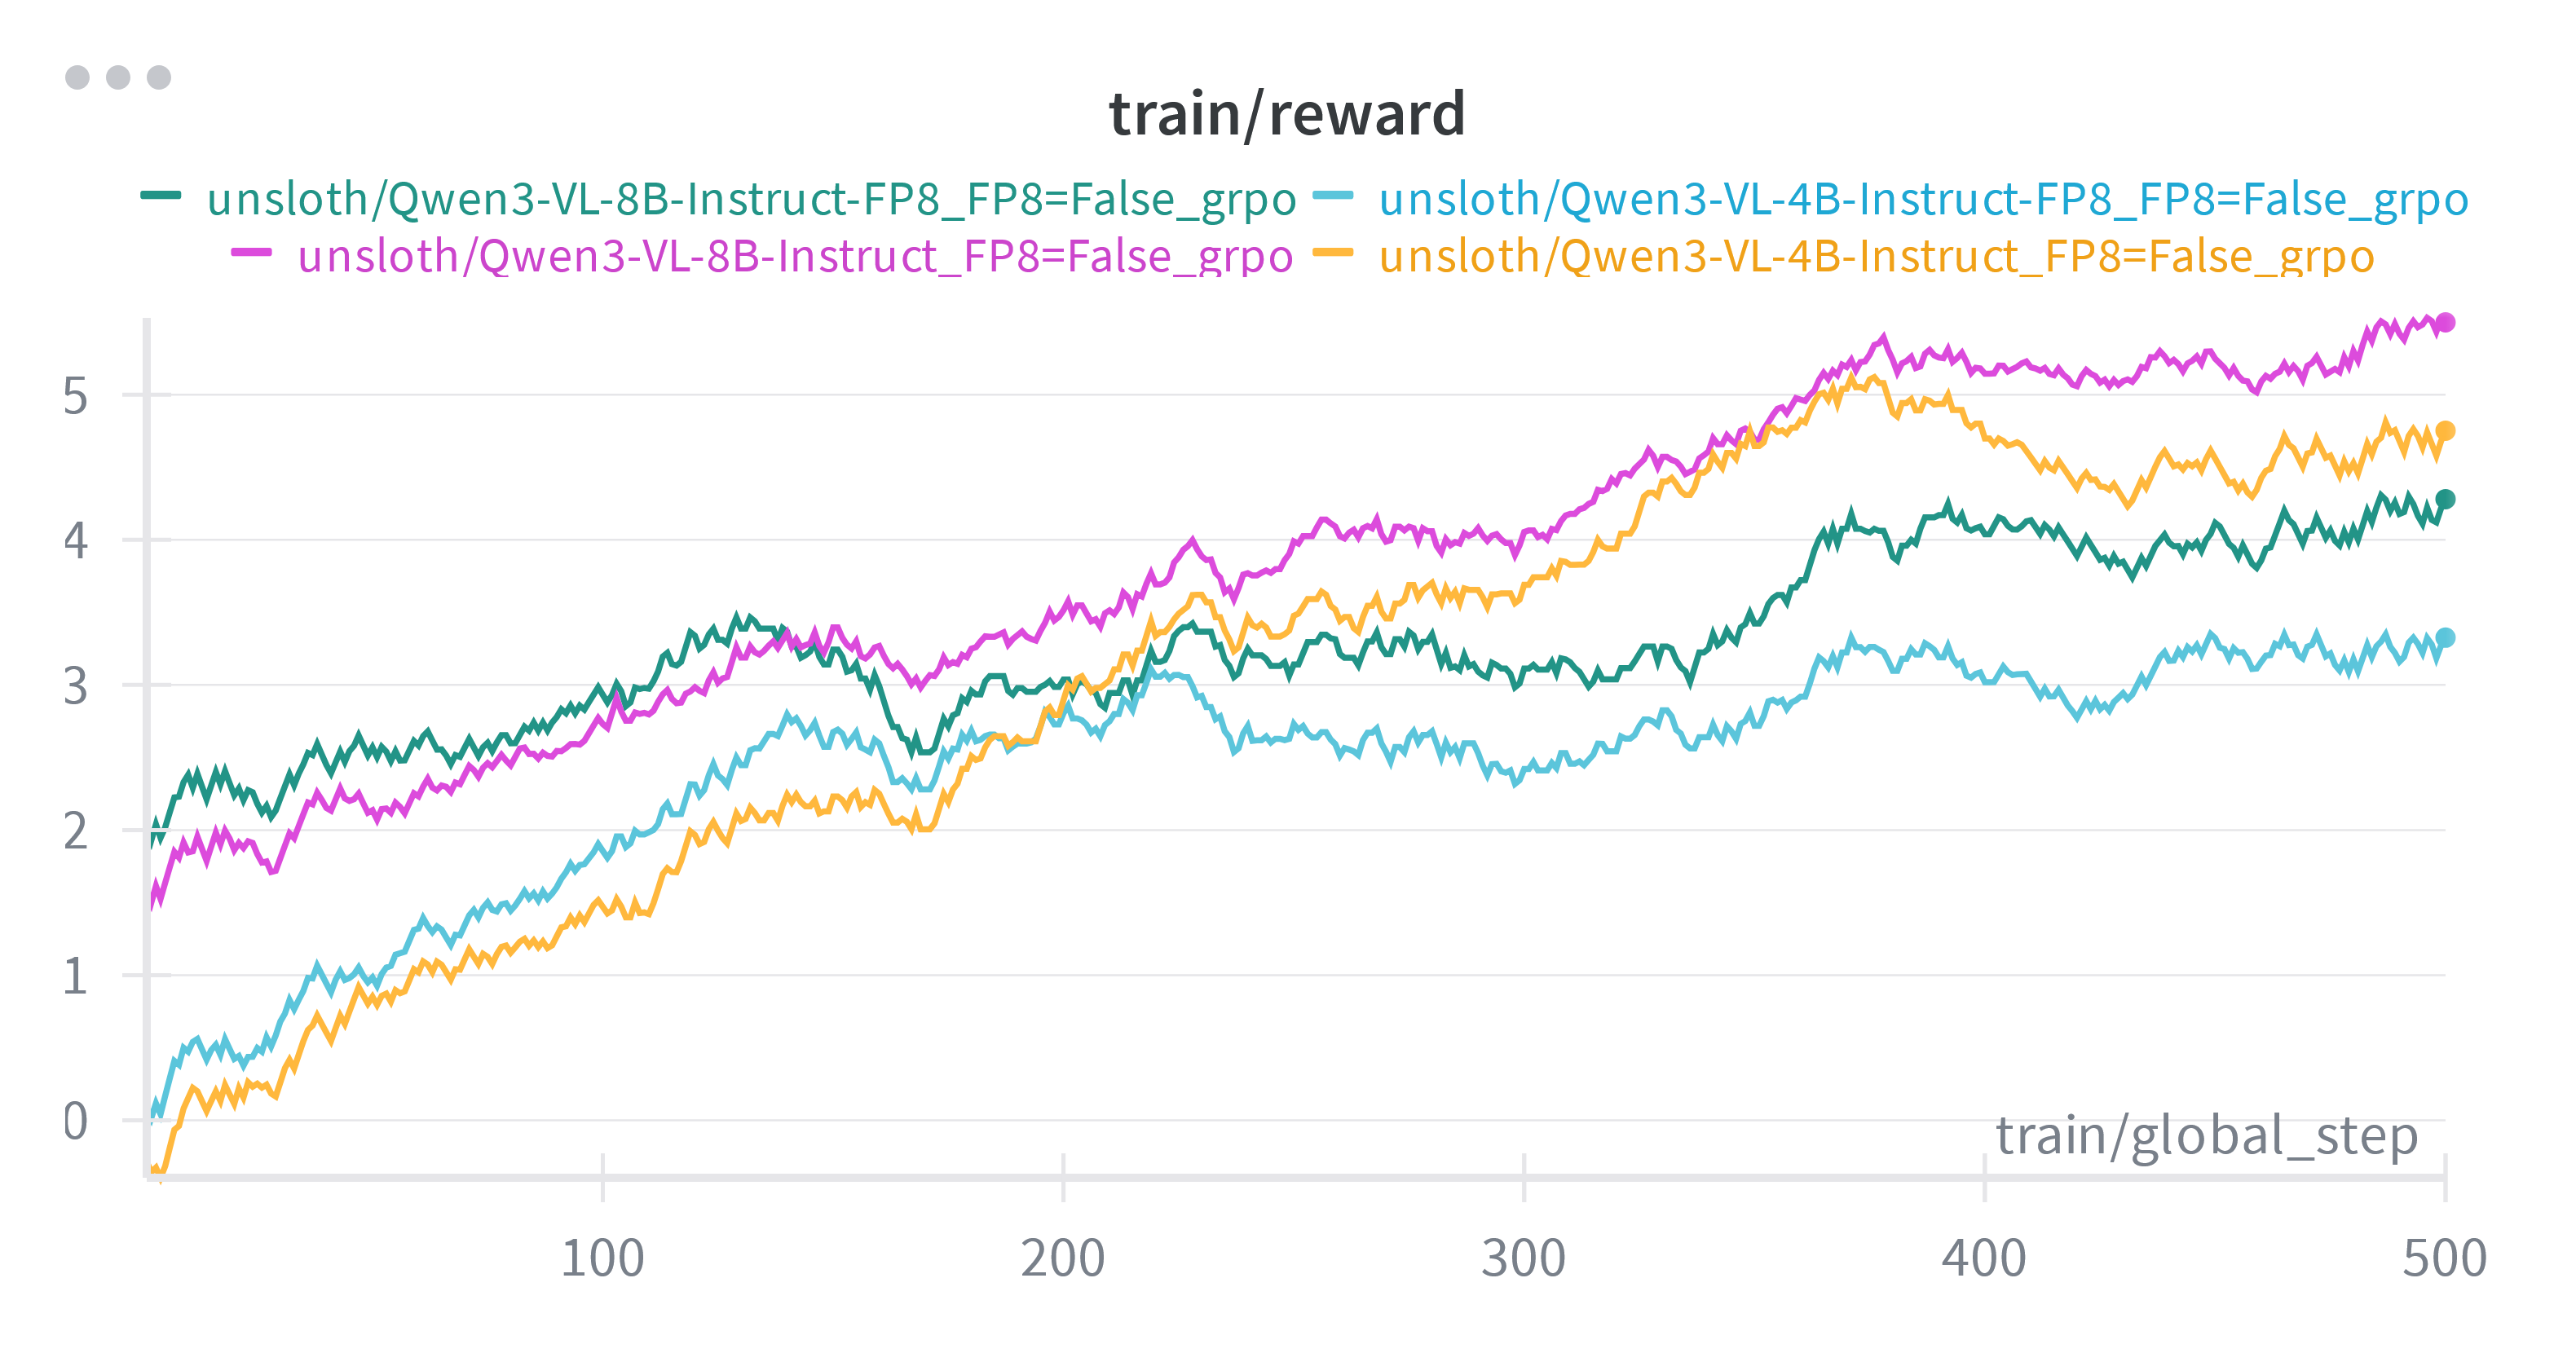
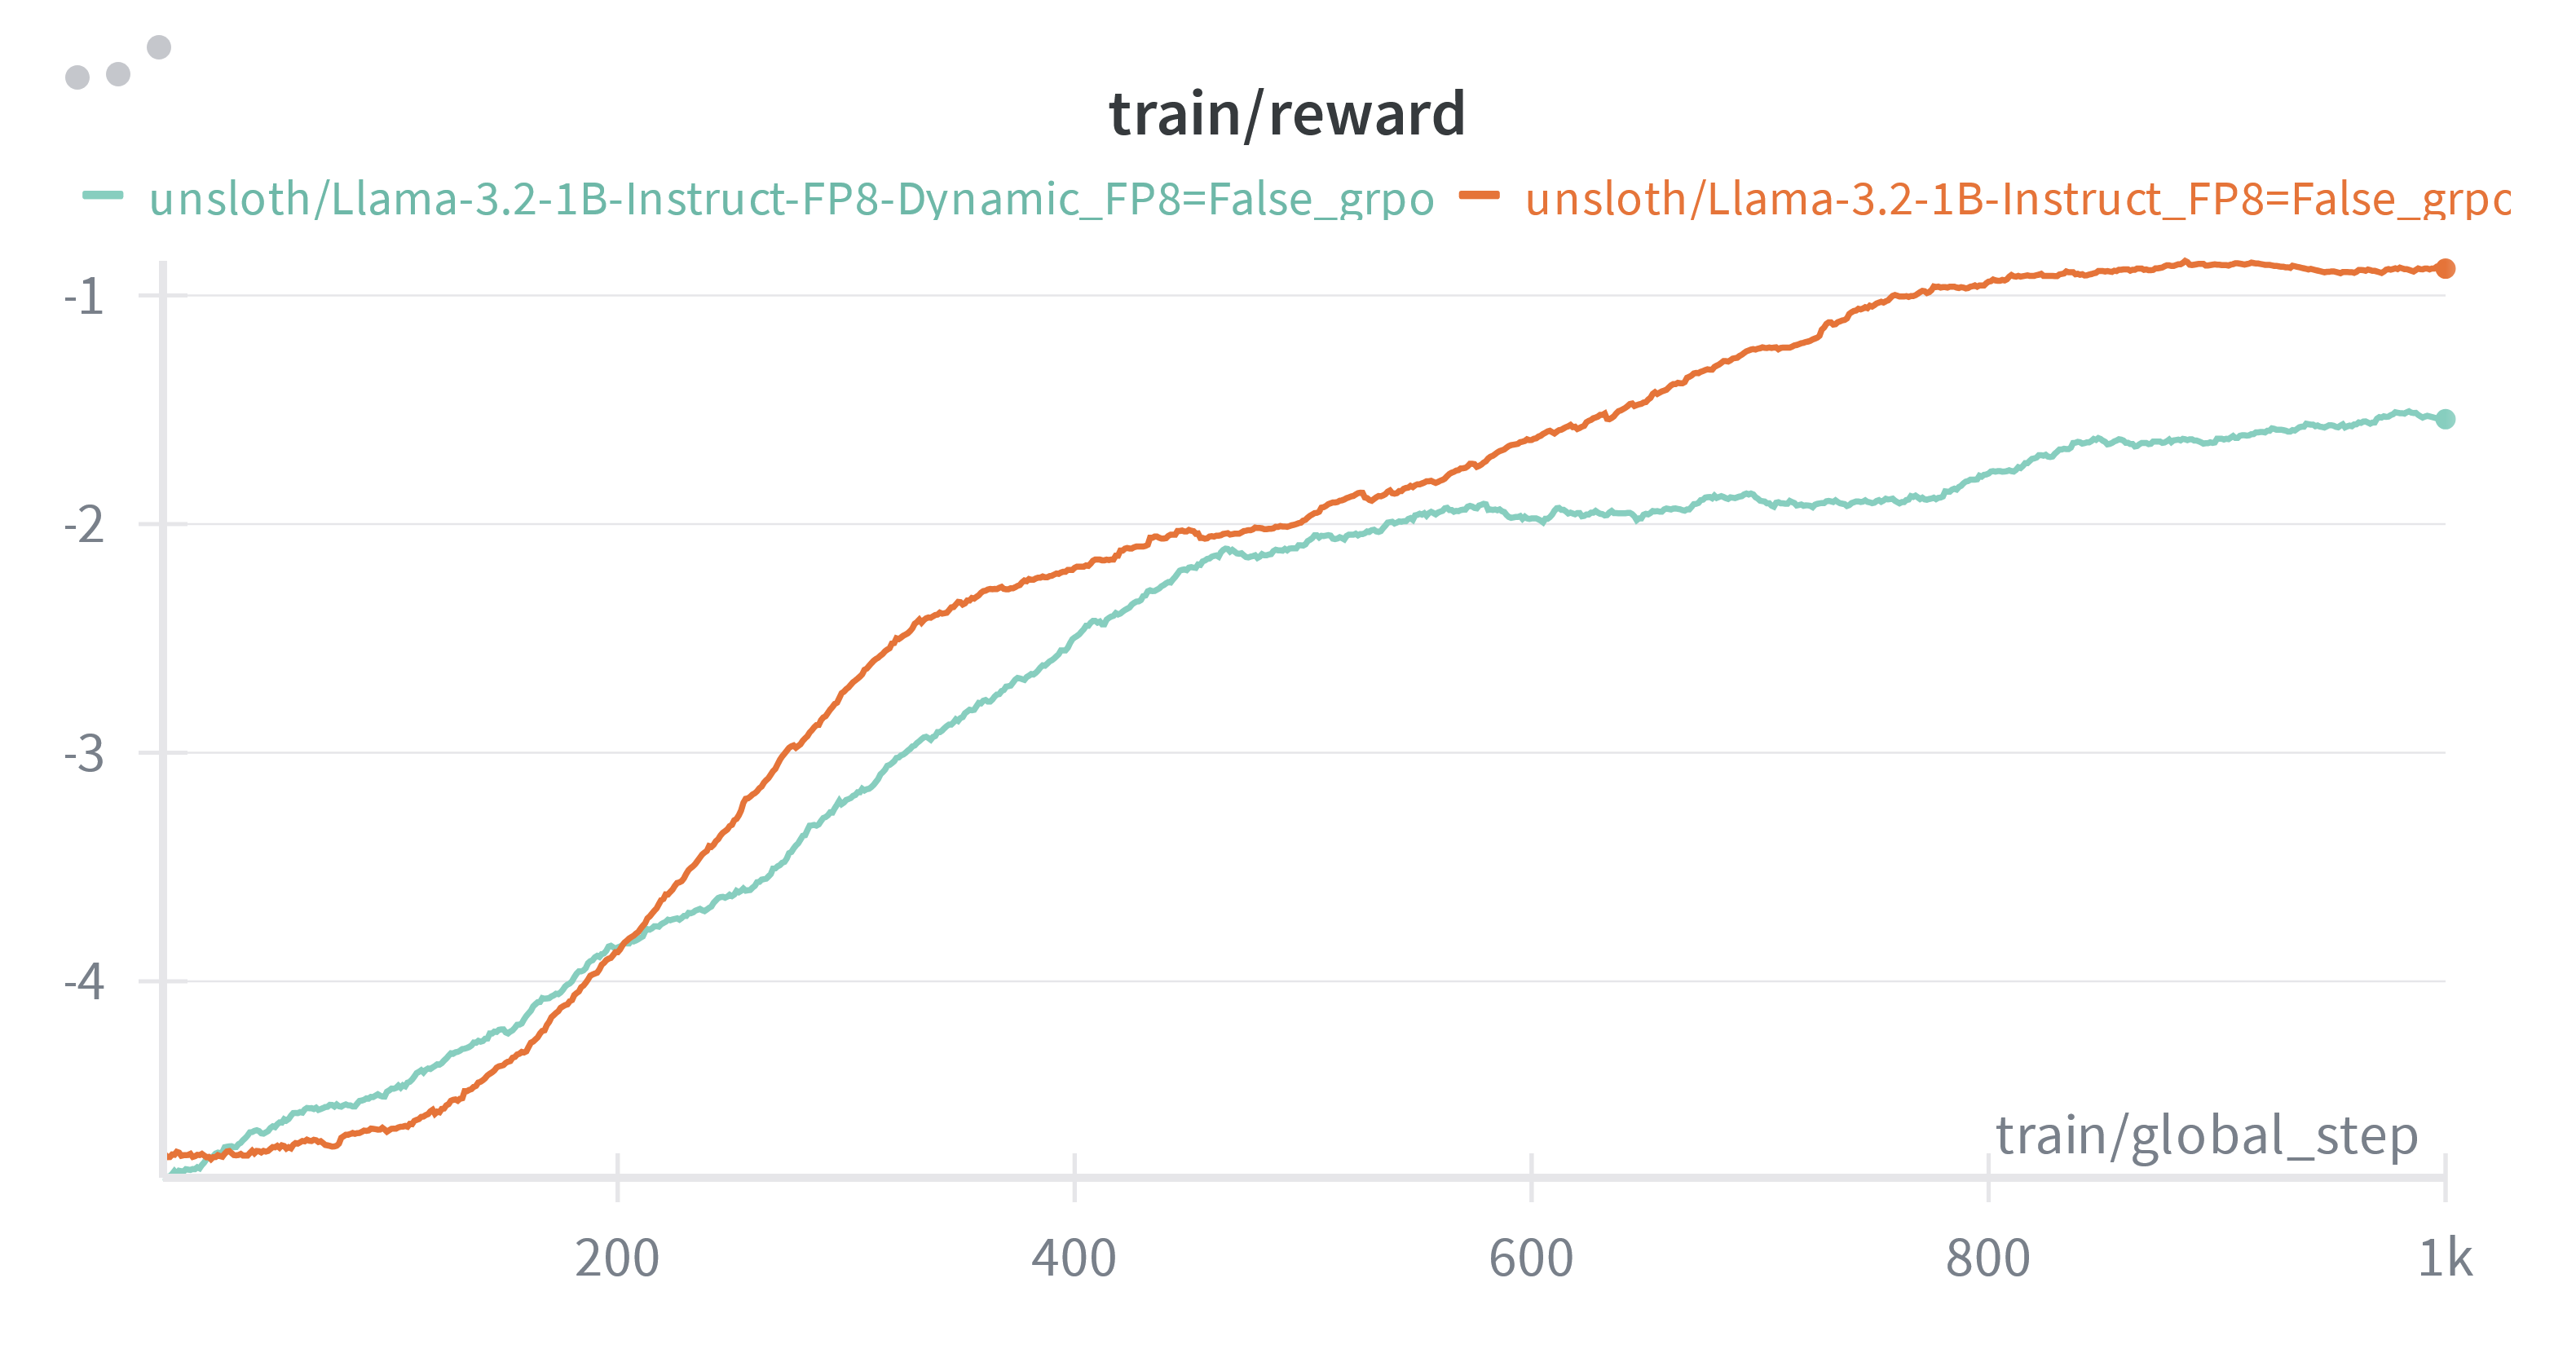
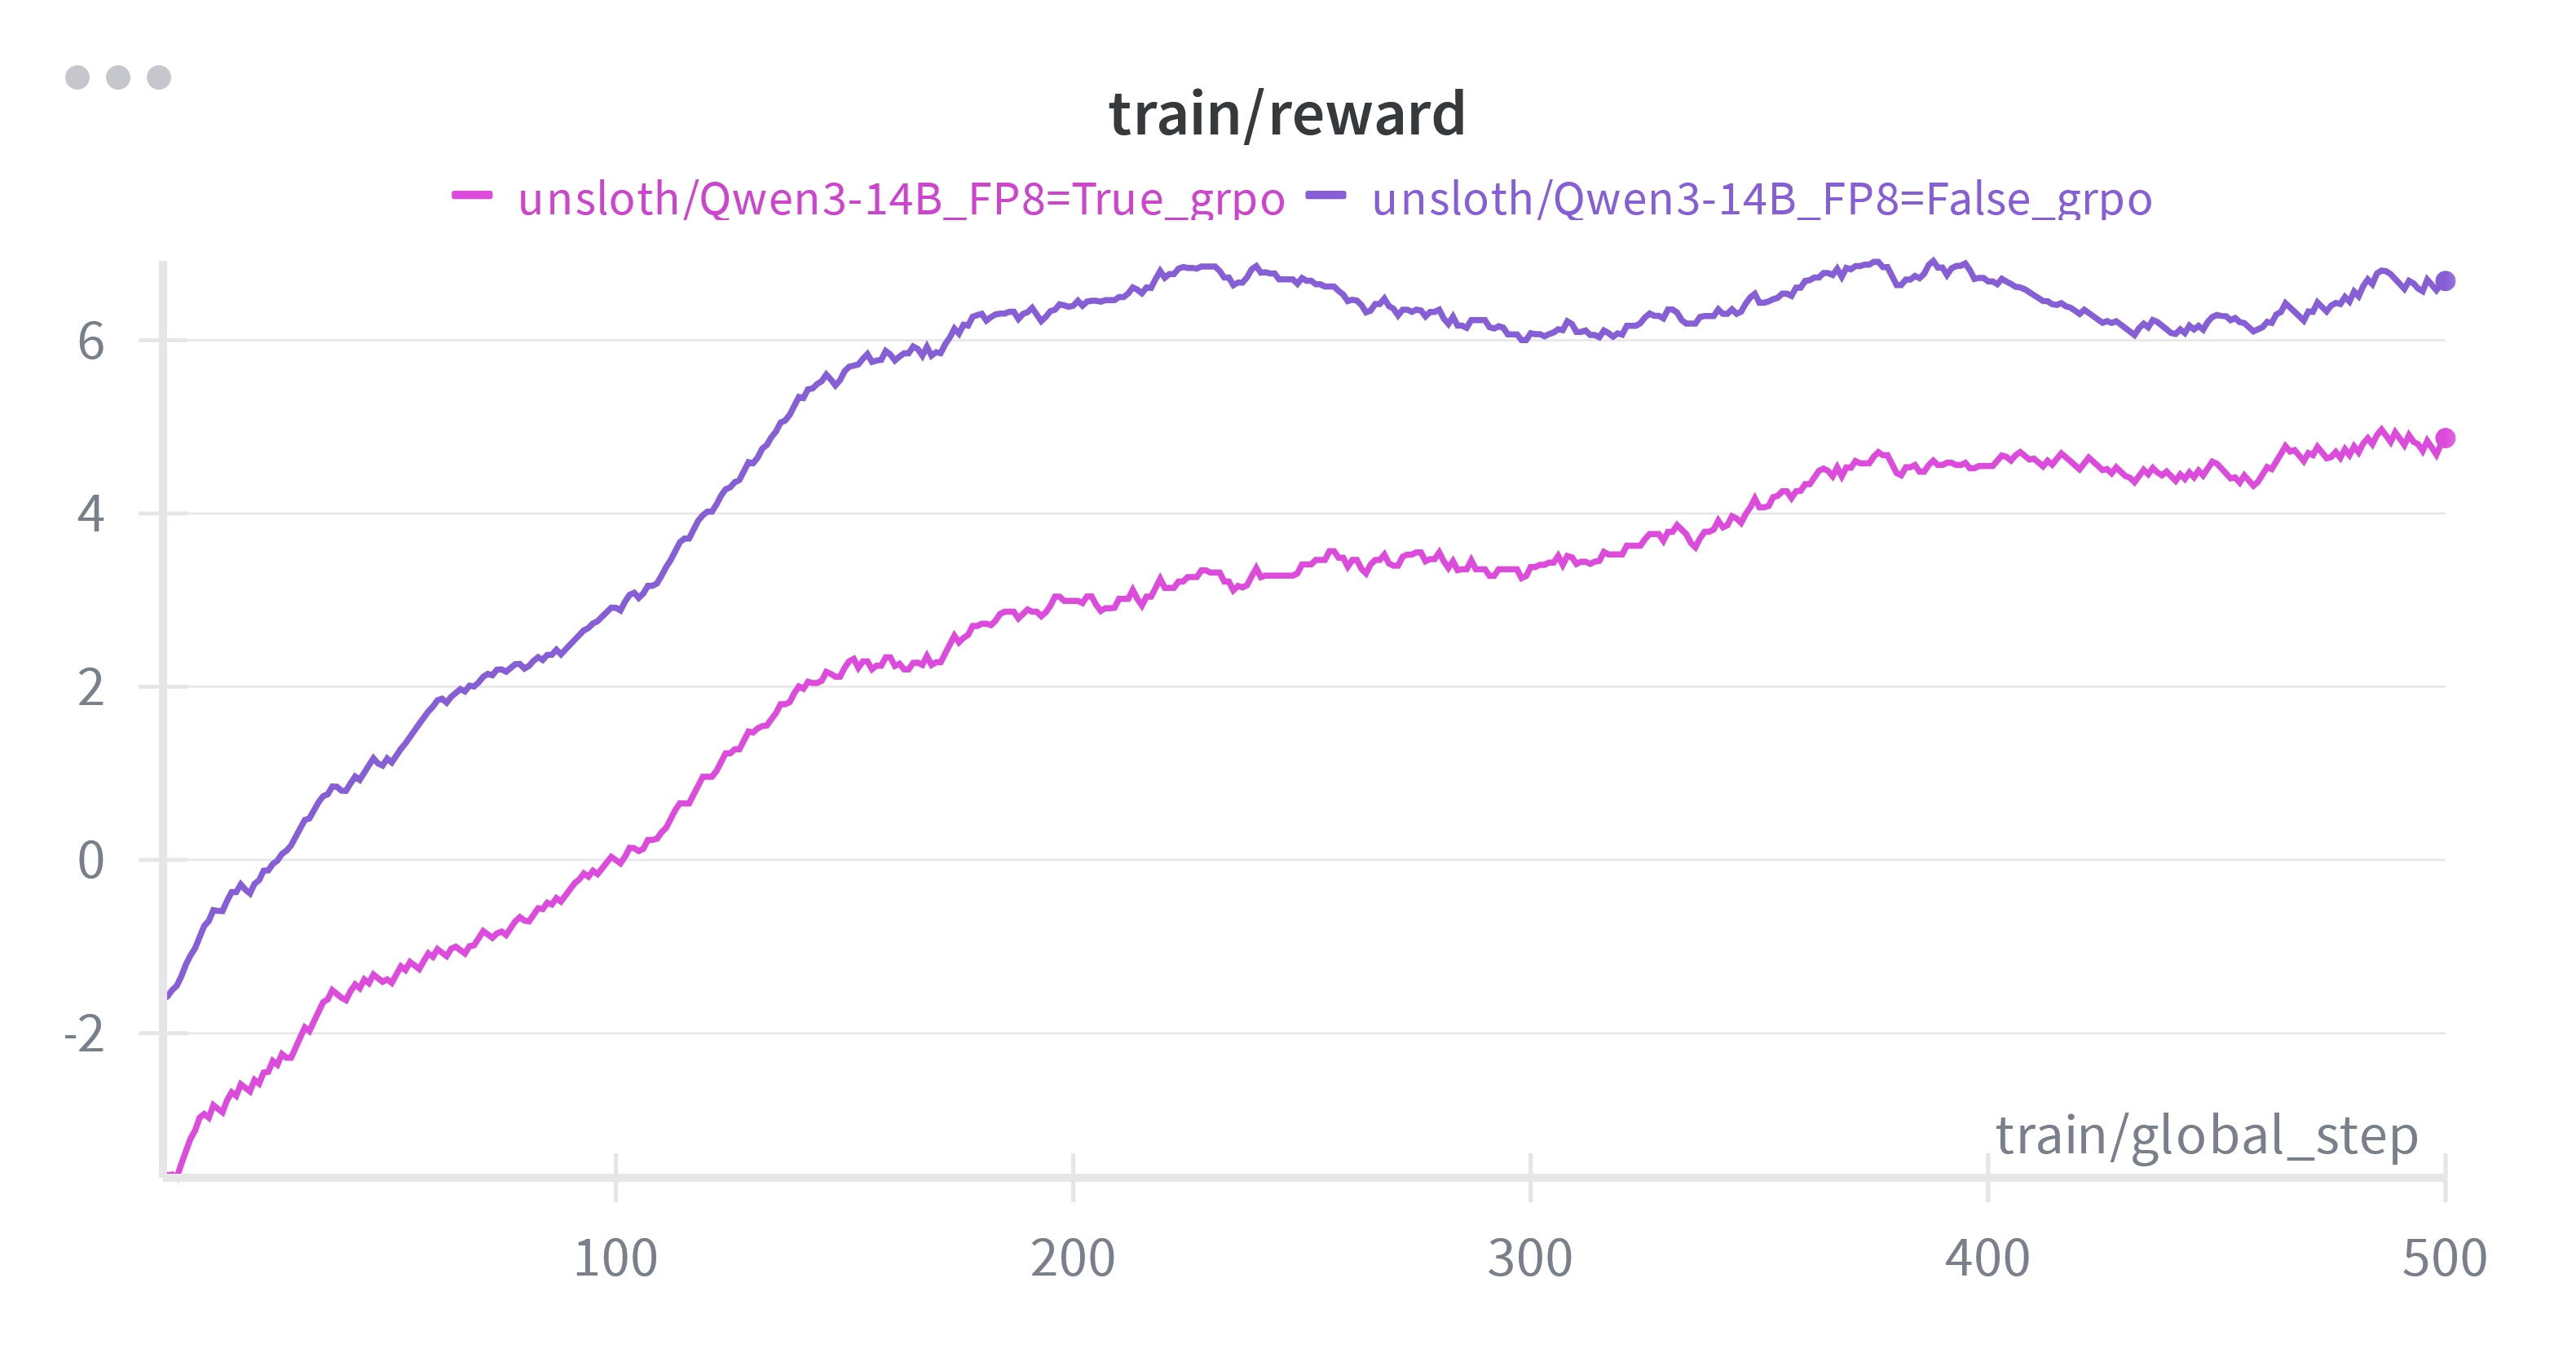
我们测试了多个模型，包括 Qwen3-4B、8B、14B、Llama 3.2 1B、3B、Qwen3-VL-2B、Qwen3-VL 4B 等等。它们都分别以 BF16 和 FP8 进行了训练。正如图中所示， **BF16 和 FP8 在 SFT 期间的损失曲线非常接近**。就训练损失而言，这两种数据类型几乎没有差别：

{% columns %}
{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FR6Hx9RtgqPXnYxvx5BbR%2FW%26B%20Chart%2025_11_2025%2C%208_54_56%20am.png?alt=media&amp;token=d1d70d59-df00-45bb-8352-e833f9b5f3cd" alt=""><figcaption></figcaption></figure>
{% endcolumn %}

{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FlUzs2uNkCyF1ulNdrVRc%2FW%26B%20Chart%2025_11_2025%2C%208_56_50%20am.png?alt=media&amp;token=09545235-c9fa-4b76-a834-ffe0ceb8f639" alt=""><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

特别是对于 GRPO，由于生成差异，目标是看奖励曲线是否至少一致而不发散（例如有时 Qwen3-14B 的运行结果可能并不完全相似）

{% columns %}
{% column width="50%" %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FeLBs5GrQb988GcrYVzpF%2FW%26B%20Chart%2025_11_2025%2C%209_00_50%20am.png?alt=media&amp;token=59220833-33c6-4c28-abe7-b5d0d93a0a17" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FPqXVeofauAIr5Qngm9d2%2FW%26B%20Chart%2025_11_2025%2C%209_08_06%20am.png?alt=media&amp;token=16498cf1-17e1-4984-b933-fe3633e19a6b" alt=""><figcaption></figcaption></figure>
{% endcolumn %}

{% column width="50%" %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FC76ql9G59SB0v3nG3pbL%2FW%26B%20Chart%2025_11_2025%2C%209_05_32%20am.png?alt=media&amp;token=554b6fe8-c121-48a4-8b33-41f28fc38ebb" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FqM5NKHjOxqJv0hrzmr2B%2FW%26B%20Chart%2025_11_2025%2C%209_07_12%20am.png?alt=media&amp;token=a7ad9eb0-0ea2-4364-982a-0875ec63459f" alt=""><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

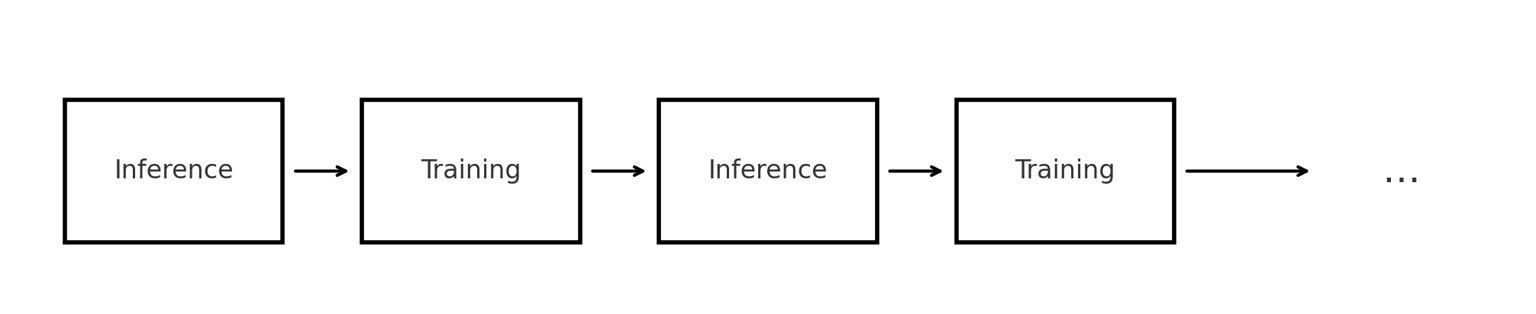
### :shinto\_shrine:推理 = RL 训练的 96%

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FTvC7GqMM5XAfV8Zv2tpf%2Fimage.avif?alt=media&amp;token=62b40c34-3111-40a9-b02a-4bfa8826402d" alt=""><figcaption></figcaption></figure>

在 RL 中，我们必须调用 LLM / VLM 为一次运行生成一些可能的候选解，然后对每个可能的解进行评分，并 **奖励好的方案，并惩罚糟糕的答案**。为了实现最高效率，我们必须让推理几乎占据整个训练过程的 100%。在 Unsloth 中，我们 **成功让训练只占整个 RL 运行的不到 4%，其中 96% 纯粹是 vLLM 推理。**

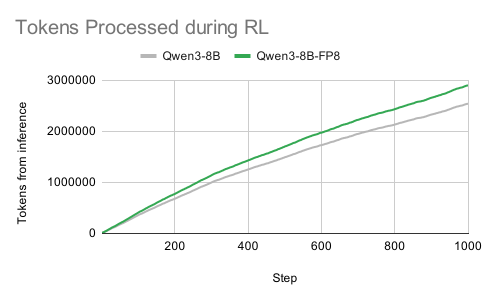
例如，Qwen-3-8B 在较短序列长度下快 1.15 倍，而仅用于推理（不含训练）的 vLLM FP8 吞吐量本身也快 1.15 倍。我们看到 Unsloth 中的 RL 运行在已处理 token 上也快 1.15 倍，这表明 **在 Unsloth 中，训练开销可以忽略不计。**

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F105iKEPXAor00mdUPTfo%2FTokens%20Processed%20during%20RL.svg?alt=media&amp;token=ca1c1d76-64b2-4019-91ac-7043f0ab79fd" alt=""><figcaption></figcaption></figure>

### :1234:内存占用减少 60%

从理论上讲，你会预期节省的内存大致 **等于模型权重所占内存**，因为：优化器状态仍然以高精度存储，而激活值目前也仍以高精度存储。我们的结果与理论一致。对于 LoRA 微调，我们观察到： **节省约 30 GB** 用于 **Qwen3-32B，节省约 14 GB** 用于 **Qwen2.5-14B** 和 **节省约 8 GB** 用于 **Qwen3-8B**

对于 **在……上进行 BF16 LoRA 微调** Qwen3-32B 在更高批大小时会 OOM，我们不得不缩小 batch。 **FP8 变体则没有这些问题**，而且我们可以使用 **更大的 batch 大小** 而不会 OOM。

另外提醒一下，在 Unsloth 中，我们会共享 vLLM 的权重内存空间，如在…中所介绍 [内存高效的 RL](/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/memory-efficient-rl.md) ——我们已经把这个技巧带到了 FP8 领域！

| 80GB GPU                                                                                                                                               | 推理引擎           | 训练引擎         |
| ------------------------------------------------------------------------------------------------------------------------------------------------------ | -------------- | ------------ |
| 模型权重                                                                                                                                                   | **8GB 共享 FP8** | **<<< 共享**   |
| <p><mark style="background-color:purple;"><strong>多用途</strong></mark></p><p><mark style="background-color:purple;"><strong>72GB 空间</strong></mark></p> | KV 缓存          | 激活值、梯度、优化器状态 |

为启用 [Unsloth Standby](/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/memory-efficient-rl.md) 对于 FP8（或 BF16）RL，只需在任何 Unsloth 导入之前，将下面这行添加到所有 RL / GRPO 训练运行中：

```python
import os
os.environ["UNSLOTH_VLLM_STANDBY"] = "1"
```

### :question:如何使用 FP8 RL / 安装

只需更新 Unsloth，或在新的虚拟环境中为 H100、L4、RTX 50x、RTX 40x、H200、B200，以及任何在 RTX 4090 之后发布的 NVIDIA GPU（消费级或数据中心级）安装 Unsloth。

要更新 Unsloth： `pip install --upgrade --force-reinstall --no-cache-dir --no-deps unsloth unsloth_zoo`或者创建一个新环境：

{% code overflow="wrap" %}

```bash
python -m venv unsloth_env
source unsloth_env/bin/activate

pip install unsloth vllm
pip install --pre torchao --index-url https://download.pytorch.org/whl/nightly/cu128 --force-reinstall
pip install --pre fbgemm-gpu fbgemm-gpu-genai --index-url https://download.pytorch.org/whl/cu128 --force-reinstall
pip install --upgrade numba numpy
```

{% endcode %}

然后使用 `load_in_fp8 = True` 然后就可以了！我们会自动将模型名称映射到 Float8 变体，或者即时将模型转换为 Float8！

<pre class="language-python" data-overflow="wrap"><code class="lang-python">import os
os.environ['UNSLOTH_VLLM_STANDBY'] = "1" # Unsloth standby 可为 RL 节省 30% 以上内存
from unsloth import FastLanguageModel
import torch
max_seq_length = 2048 # 可为更长的推理轨迹提高
lora_rank = 32 # 更大的 rank = 更聪明，但更慢
model, tokenizer = FastLanguageModel.from_pretrained(
    model_name = "unsloth/Qwen3-8B",
    max_seq_length = max_seq_length,
    load_in_4bit = False, # LoRA 16bit 时为 False
    fast_inference = True, # 启用 vLLM 快速推理
    max_lora_rank = lora_rank,
<strong>    load_in_fp8 = True, # Float8 RL / GRPO！
</strong>)
</code></pre>

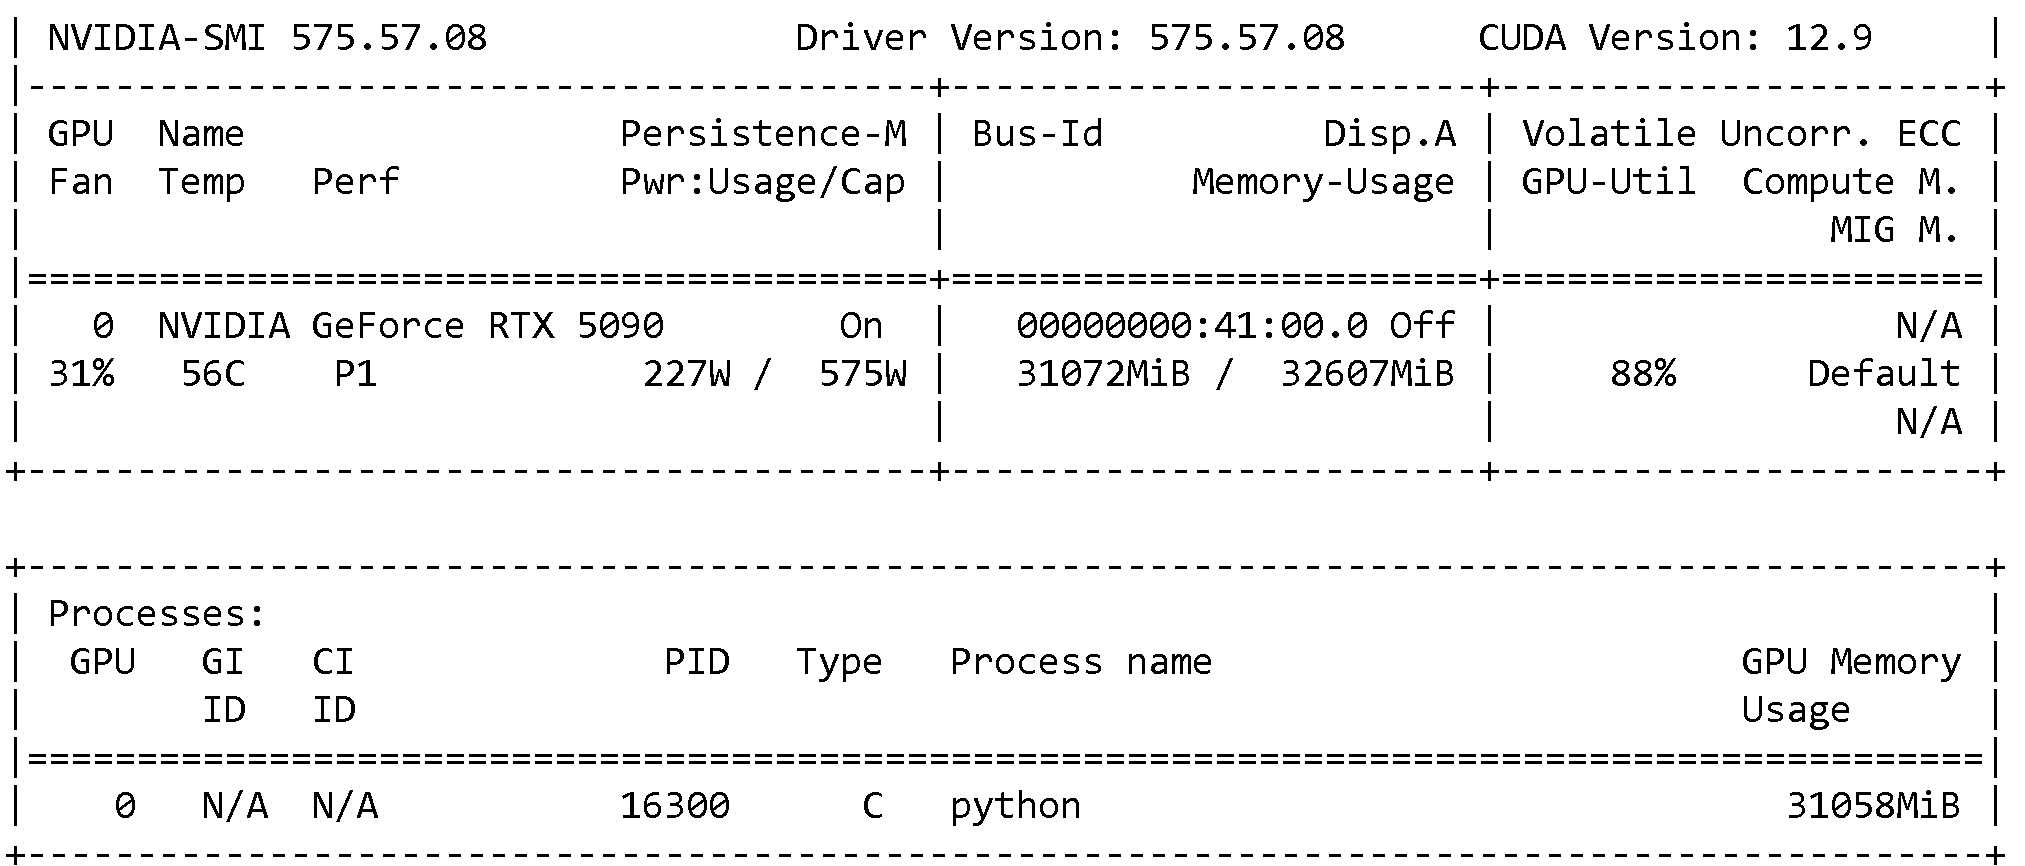
例如在 RTX 5090 上（提醒设置 `os.environ["UNSLOTH_VLLM_STANDBY"] = "1"` )

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FlVA3v7E5J8pHb1QKLi2V%2Fimage.png?alt=media&amp;token=20b5329c-6ac2-479a-a4cc-2a0d74486696" alt="" width="375"><figcaption></figcaption></figure>

然后使用我们的 2 个用于 RL 的 FP8 notebook：

{% columns %}
{% column %}
**Qwen3-8B FP8 RL Colab**

{% embed url="<https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_8B_FP8_GRPO.ipynb>" %}
{% endcolumn %}

{% column %}
**Llama-3.2-1B-FP8 RL Colab**

{% embed url="<https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Llama_FP8_GRPO.ipynb>" %}
{% endcolumn %}
{% endcolumns %}

### :cd:实现 FP8 训练

我们的第一个参考点是 `transformers`，它已经以几种方式支持 FP8。其中一种是块量化的 matmul 实现：当某一层接收到 16 位激活值时，它会将其量化并传递给一个自定义的 FP8 matmul 内核。在完成集成并在 NVIDIA H100 上基准测试后，我们看到的结果与预期相反：微调变成了大约 **慢 4×** ，比标准 BF16 微调更慢。

### 🔥TorchAO 合作

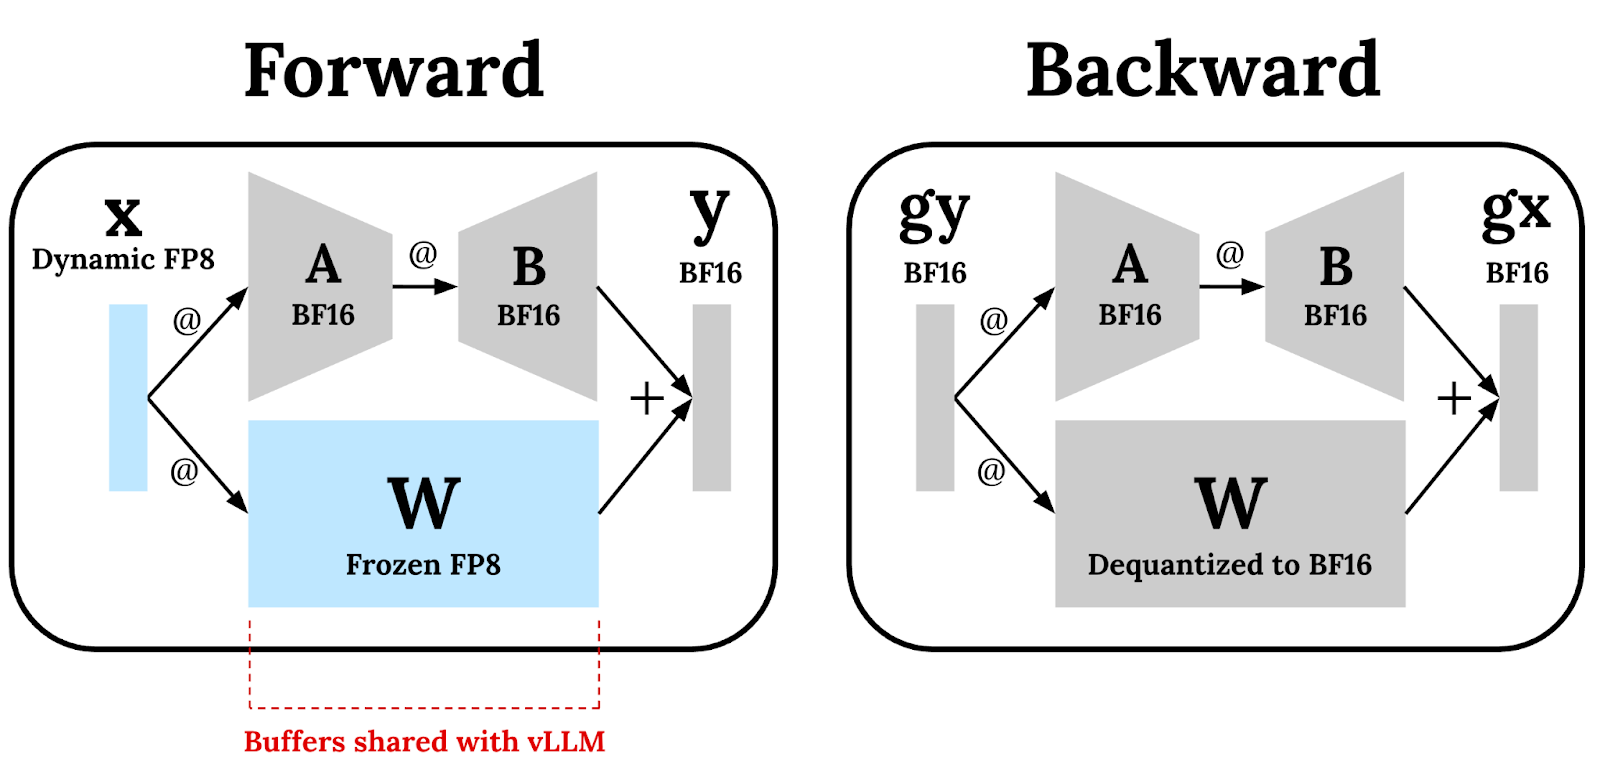
因此我们与 [TorchAO](https://github.com/pytorch/ao) 团队合作（非常感谢[ Andrew](https://github.com/unslothai/unsloth/pull/3440)）将 TorchAO 的 FP8 支持集成到我们的 RL 工作负载中，并看到了大约 **吞吐量快 1.4×** 以及最高 **模型内存占用减少 60%**。从高层来看：

* 我们将冻结的 LoRA 权重以 FP8 存储。
* 在前向传播中，我们对输入激活值应用动态 FP8 量化，同时将可训练的 LoRA 适配器保持为 BF16。
* 这些 FP8 权重与 vLLM 模型权重共享同一缓冲区，因此在任何时刻内存中只有模型的一份 FP8 副本（没有“模型双份”内存开销）。
* 在反向传播中，我们对 LoRA 权重进行反量化，使所有梯度计算都在 BF16 中完成，以获得更好的准确率。

这种通用设置适用于所有受支持的 RL 算法，包括 [GSPO](/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/advanced-rl-documentation/gspo-reinforcement-learning.md)、Dr. GRPO、PPO 和 DPO。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FUir0hB7T0xBtWUTnK3aG%2Funknown.png?alt=media&amp;token=d225cd2e-fdf4-4521-8e9f-72bd684eb9e4" alt="" width="375"><figcaption></figcaption></figure>

TorchAO 为训练和推理都提供了 PyTorch 原生的 FP8 支持，提供多种缩放粒度，包括按张量、按行以及 128×128 按块（原型）。TorchAO 的 FP8 支持可将推理吞吐量最高提升 [在 27B 规模下提升至 1.64x](https://huggingface.co/pytorch/gemma-3-27b-it-FP8/blob/main/README.md#results-h100-machine) ，采用按行缩放粒度。更多详情请访问 TorchAO [FP8 README](https://github.com/pytorch/ao/blob/main/torchao/float8/README.md).

#### TorchAO 的块量化 FP8 matmul

我们使用了 TorchAO 的块量化 FP8 matmul 实现，它提供了：

* **BF16 吞吐量的 80%**
* 且不会降低损失或训练稳定性

因此有一段时间，这成了我们默认的 FP8 matmul 后端，直到 FBGEMM 迎头赶上——如果你的 GPU 支持，现在我们默认使用 FBGEMM 的实现！当前版本的 Unsloth 可以根据已安装的组件自动选择最佳后端。如果你装齐了相应软件包，就不必牺牲性能 🙂

附注：我们也尝试过 DeepSeek 的 DeepGEMM，但没能将其完整端到端集成起来，因此无法进行干净、同条件的对比。

### :bird:即时 TorchAO FP8 量化

非常感谢 [Andrew](https://github.com/unslothai/unsloth/pull/3440) 来自 TorchAO 的帮助，Unsloth FP8 RL 还允许你在模型加载时进行量化，并将其传递给 vLLM，从而实现即时量化模型。这样，你就不需要自己显式地量化模型（我们会替你处理）。你可以通过设置 `load_in_fp8 = True` 在模型加载参数中；如果我们找不到合适的预量化检查点，就会执行离线 FP8。

```python
from unsloth import FastLanguageModel
fp8_model = FastLanguageModel.from_pretrained(
    "unsloth/Llama-3.3-70B-Instruct", # 可以是任意模型名称！
    load_in_fp8 = True, # 对于块 FP8 可设为 "block"，对于行 FP8 可设为 True，False
)
```

### :tada:Unsloth FP8 上传

为了方便起见，我们已在 Hugging Face 上上传 FP8 Dynamic 和 FP8 Block 模型。你可以将它们用于 FP8 训练，也可以通过……进行高效快速的服务/部署 [vLLM](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/vllm-guide.md)/[SGLang](/docs/zh/ji-chu-zhi-shi/inference-and-deployment/sglang-guide.md) 等。

FP8 Dynamic 的训练略快于 FP8 Block，VRAM 占用也更低，但准确率会有一点点折衷。 [请看这里](/docs/zh/kuai-su-kai-shi/unsloth-model-catalog.md#fp8) 查看我们完整的 FP8 量化列表，不过这里列出最受欢迎的几个：

| 模型                    | FP8 上传                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                      |
| --------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Qwen3（2507）**       | <p>4B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-4B-Instruct-2507-FP8">FP8</a><br>4B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-4B-Thinking-2507-FP8">FP8</a><br>30B-A3B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-30B-A3B-Instruct-2507-FP8">FP8</a><br>30B-A3B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-30B-A3B-Thinking-2507-FP8">FP8</a></p>                                                                                                                                                                                                                                                                                                                 |
| **Qwen3-VL**          | <p>4B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-VL-4B-Instruct-FP8">FP8</a><br>4B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-VL-4B-Thinking-FP8">FP8</a><br>8B Instruct — <a href="https://huggingface.co/unsloth/Qwen3-VL-8B-Instruct-FP8">FP8</a><br>8B Thinking — <a href="https://huggingface.co/unsloth/Qwen3-VL-8B-Thinking-FP8">FP8</a></p>                                                                                                                                                                                                                                                                                                                                             |
| **Llama 3.1**         | <p>8B Instruct — <a href="https://huggingface.co/unsloth/Llama-3.1-8B-Instruct-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.1-8B-Instruct-FP8-Block">块</a><br>8B Base — <a href="https://huggingface.co/unsloth/Llama-3.1-8B-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.1-8B-FP8-Block">块</a><br>70B — <a href="https://huggingface.co/unsloth/Llama-3.1-70B-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.1-70B-FP8-Block">块</a></p>                                                                                                                                                                                            |
| **Qwen3**             | <p>0.6B — <a href="https://huggingface.co/unsloth/Qwen3-0.6B-FP8">FP8</a><br>1.7B — <a href="https://huggingface.co/unsloth/Qwen3-1.7B-FP8">FP8</a><br>4B — <a href="https://huggingface.co/unsloth/Qwen3-4B-FP8">FP8</a><br>8B — <a href="https://huggingface.co/unsloth/Qwen3-8B-FP8">FP8</a><br>14B — <a href="https://huggingface.co/unsloth/Qwen3-14B-FP8">FP8</a><br>32B — <a href="https://huggingface.co/unsloth/Qwen3-32B-FP8">FP8</a></p>                                                                                                                                                                                                                                                                         |
| **Llama 3.3**         | 70B — [Dynamic](https://huggingface.co/unsloth/Llama-3.3-70B-Instruct-FP8-Dynamic) · [块](https://huggingface.co/unsloth/Llama-3.3-70B-Instruct-FP8-Block)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                   |
| **Llama 3.2**         | <p>1B Base — <a href="https://huggingface.co/unsloth/Llama-3.2-1B-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.2-1B-FP8-Block">块</a><br>1B Instruct — <a href="https://huggingface.co/unsloth/Llama-3.2-1B-Instruct-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.2-1B-Instruct-FP8-Block">块</a><br>3B Base — <a href="https://huggingface.co/unsloth/Llama-3.2-3B-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.2-3B-FP8-Block">块</a><br>3B Instruct — <a href="https://huggingface.co/unsloth/Llama-3.2-3B-Instruct-FP8-Dynamic">Dynamic</a> · <a href="https://huggingface.co/unsloth/Llama-3.2-3B-Instruct-FP8-Block">块</a></p> |
| **Granite 4.0**       | <p>h-tiny — <a href="https://huggingface.co/unsloth/granite-4.0-h-tiny-FP8-Dynamic">FP8 Dynamic</a><br>h-small — <a href="https://huggingface.co/unsloth/granite-4.0-h-small-FP8-Dynamic">FP8 Dynamic</a></p>                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                               |
| **Magistral Small**   | [FP8 Dynamic](https://huggingface.co/unsloth/Magistral-Small-2509-FP8-Dynamic) · [FP8 torchao](https://huggingface.co/unsloth/Magistral-Small-2509-FP8-torchao)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                             |
| **Mistral Small 3.2** | [FP8](https://huggingface.co/unsloth/Mistral-Small-3.2-24B-Instruct-2506-FP8)                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                               |
| **Gemma 3**           | <p>270m — <a href="https://huggingface.co/unsloth/gemma-3-270m-it-FP8-Dynamic">FP8</a><br>1B — <a href="https://huggingface.co/unsloth/gemma-3-1b-it-FP8-Dynamic">FP8</a><br>4B — <a href="https://huggingface.co/unsloth/gemma-3-4b-it-FP8-Dynamic">FP8</a><br>12B — <a href="https://huggingface.co/unsloth/gemma-3-12B-it-FP8-Dynamic">FP8</a><br>27B — <a href="https://huggingface.co/unsloth/gemma-3-27b-it-FP8-Dynamic">FP8</a></p>                                                                                                                                                                                                                                                                                  |

### :person\_tipping\_hand:致谢

非常感谢整个 PyTorch 和 TorchAO 团队的帮助与合作！特别要感谢：Andrew Or、Jerry Zhang、Supriya Rao、Scott Roy 和 Mergen Nachin，他们在许多关于 FP8 RL 的讨论中提供了帮助，并协助将其集成到 Unsloth 中！也感谢 Executorch 团队！


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://unsloth.ai/docs/zh/kuai-su-kai-shi/reinforcement-learning-rl-guide/fp8-reinforcement-learning.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.