> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/ji-chu/dynamic-3.0-ggufs.md).

# Unsloth Dynamic 3.0 GGUF

[**Unsloth**](https://github.com/unslothai/unsloth) **动态 v3.0** 是我们动态量化的下一代版本，相比 Dynamic v2.0 有重大改进。

今天，我们发布 [**Qwen3.8-27B**](/docs/zh/mo-xing/qwen3.8.md) Dynamic v3.0 量化版本，带来 **>10% 在相同大小下的 top-1% 准确率提升** 相较于 **其他所有提供方**。这是我们首次共享的 **早期预览** 版 Dynamic v3.0。新的 3.0 GGUF 可与大多数推理引擎兼容，包括 **llama.cpp** 和 [**Unsloth Desktop**](/docs/zh/desktop.md).

{% columns %}
{% column width="41.66666666666667%" %}
Dynamic v3.0 整体在保持相同大小的同时保留了更多模型质量，在以下指标上表现更强，如 **Divergence-300** @32 和 **KL Divergence**.

也非常感谢大家的支持！我们在短短 5 天内就看到了超过 510 万次 Unsloth Qwen3.8 下载！
{% endcolumn %}

{% column width="58.33333333333333%" %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fl9piThTmmUsePst5w3F2%2Fimage.png?alt=media&amp;token=821e88e2-ad4e-40bf-adf2-e13837228e82" alt=""><figcaption><p>更多图表/基准测试和分析见下方</p></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

我们新的方法包含许多新特性和改进。我们现在使用来自多种来源、质量更高的 imatrix 校准数据集。该数据集经过优化，适用于 **agentic 编码、聊天**以及多语言性能。我们还改进了 **层选择** 并引入了更多量化技术，以尽可能保留模型质量。

我们 **不会在 imatrix 校准数据集上训练**，并且我们绝不使用 **QAT** 或 **QAD**。所有操作都通过 **训练后量化**完成。我们使用的 imatrix 文件已开放给社区进行测试、评估和使用。我们鼓励研究人员和开发者基于我们的 Unsloth 量化版本/imatrix 为 Qwen3.8 创建变体和微调。你也可以阅读我们的 [过拟合分析](#not-overfitting) 。

* 我们还从 `UD-Q2_K_XL` 以下的小型量化版本中移除了 MTP 模块（8.37GB 及以下），以节省约 500MB 磁盘空间 - 如有需要，你可以使用 `Q4_0` 单独的 MTP 模块
* 我们还制作了一些更小的 UD-1bit 量化版本，使用 `UD-IQ1_S` ，大小为 6.2GB（不含 MTP），保留了约 72% 的 top-1% 准确率，同时体积缩小了 89%。
* `UD-Q2_K_XL` 在 top-1% 上比下一个最佳方案大约准确 +8%，大小为 9.83GB，并成功生成了一个可运行的 HTML 程序，仅有一个很小的 JS bug——之前会崩溃。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FHkiEb4BgU9IZ4t0pbMKs%2FUD-Q2_K_XL-Qwen.gif?alt=media&amp;token=6b4cd6d5-0b70-4741-a72e-1f5e1974dbb0" alt="" width="360"><figcaption><p>使用 2-bit Qwen3.8-27B GGUF 生成</p></figcaption></figure>

### 🔀 Divergence-300 @32

我们通常报告 top-1% 准确率，就像对于 Kimi-K3，“Dynamic 1-bit 达到 **\~78.9%** top-1 准确率，同时体积为 **缩小 62%**。”不过 top-1% 是对 1 个预测取 argmax，因此它并不真正适合衡量实际推理效果。

我们创建了一个包含 300 个保留样本（不在校准数据集中） 的数据集，来源于 Terminal-Bench 2.1 + DeepSWE + Harbor + MathArena 2025-26 + 非拉丁语/长文档提示，并对 BF16 与所有量化版本及提供方进行了 32 个 token 的贪婪 argmax 解码。详见 [过拟合分析](#not-overfitting) 以了解更多关于过拟合的细节。

这使我们能够判断是否存在过拟合，以及量化输出在多个 token 上是否与 BF16 的轨迹相似。这比 top-1% 准确率更好的指标，因为我们将 KLD top-1% 扩展到更接近 32 个 token 上的 KLD top-1%。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FySCIjoinQuhNqfGz3C4Q%2Fimage.png?alt=media&amp;token=dcc5a2be-3445-4a67-b1e2-0ca5e89fbcf6" alt=""><figcaption></figcaption></figure>

### :question:1-bit 不应用于 agentic 用例

如在 [#divergence-300-32](#divergence-300-32 "mention")中所示，从 UD-Q2\_K\_XL 到 UD-IQ2\_S，在 32 token 预测上的准确率会急剧下降，从约 25% 降至不足 8-10%。这种骤降意味着工具调用和非思考模式会失效。如果使用 1-bit，存在一些问题和缓解措施：

1. **过度循环**\
   使用低于 UD-Q2\_K\_XL 的量化版本时，你会看到大量循环——请在所有情况下使用 `presence_penalty = 1.5` （或更高）
2. **空响应**\
   对于 1-bit 量化版本，务必至少在 low reasoning 模式下启用思考——非推理模式甚至会导致模型根本不输出。
3. **Agentic 用例和工具调用**\
   不要将该模型用于工具调用——只 **在重度量化时保留通用知识** ，模型要么无法调用工具，要么持续调用工具，要么甚至不会调用。
4. **通用知识可用**\
   77% 的 top-1% 恢复率并不能替代 Divergence-300 @32 的 8%，后者更能反映实际推理工作负载——你可以将该模型用于非常短的通用知识事实问答，但最好使用 UD-Q2\_K\_XL。

### 🔀 KL 散度基准测试

我们也对所有提供方运行了 KLD 基准测试，并报告 Top-1% 和 KLD 均值。在所有层级，尤其是在更小的量化尺寸上，Unsloth UD-3 量化版本在相同磁盘空间下可获得高达 +10% 的额外 top-1% 准确率！

所有图在计算磁盘空间时都会从 x 轴中移除 MTP head，以便与所有人公平比较。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F4ipZ74oiCRRLbB2FJa4J%2Fimage.png?alt=media&amp;token=09f263b9-4cd9-45dc-bd31-8c7ecff2ca41" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FA6YPmwKLaJ7IZ4U4bQE3%2Fimage.png?alt=media&amp;token=e003bf7b-5c78-4eb4-bbae-5358410ef3fa" alt=""><figcaption></figcaption></figure>

### :dove:不过拟合

与我们旧的 UD-2 在未见过的 Wikitext 和 Code 数据上比较时，我们在 KLD 上展示了显著改进——但较大的版本提升不那么明显，因此对于更大的量化版本我们仍然使用旧的 UD-2——我们计划继续实验并改进它们！

我们还通过使用完全不同的数据集进行校准来控制过拟合，并尽可能移除所有泄漏。我们在这些未见过的数据集上测试 KLD，而且我们也不做 QAD / QAT，只做纯 PTQ，因此与其他 QAD / QAT 方法相比，对过拟合的担忧更少。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FP6ro1GH2PqtO63Zdvale%2Fimage.png?alt=media&amp;token=109ca035-6fe1-4154-a33e-20d609f2bf57" alt=""><figcaption></figcaption></figure>

同样 [#divergence-300-32](#divergence-300-32 "mention") 使用了来自 DeepSWE、Terminal Bench 等的 300 个提示的未见过数据集，并作为另一个衡量过拟合的数据集——结果表明我们的新 UD-3 方法没有过拟合。

***

## Dynamic v2.0（旧版）

我们正在推出 [Unsloth](https://github.com/unslothai/unsloth) Dynamic v2.0 量化——对我们之前量化版本的一次重大升级。此新方法优于领先的量化方法，并为以下项目设定了新的基准： [Aider Polyglot](/docs/zh/ji-chu/dynamic-3.0-ggufs/unsloth-dynamic-ggufs-on-aider-polyglot.md)、5-shot MMLU 和 KL 散度。

这意味着你现在可以运行并微调 [量化 LLM](/docs/zh/mo-xing/tutorials.md) ，同时尽可能保留准确率！你可以在大多数推理引擎上运行 2.0 GGUF，比如 llama.cpp、 [Unsloth Studio](/docs/zh/xin/studio.md) 等。

{% columns %}
{% column %}
**2026年4月20日更新：** 查看我们针对以下内容的新 GGUF 基准测试： [Qwen3.6](/docs/zh/mo-xing/qwen3.6.md#unsloth-gguf-benchmarks) 和 [Gemma 4](/docs/zh/mo-xing/gemma-4.md#unsloth-gguf-benchmarks).

[2026年2月27日更新：](/docs/zh/mo-xing/qwen3.5/gguf-benchmarks.md) **Qwen3.5** 已发布，我们修复了一些工具调用聊天模板问题，并对每个 GGUF 进行了困惑度和 KL 散度基准测试。 [查看基准测试！](/docs/zh/mo-xing/qwen3.5/gguf-benchmarks.md)

使用 **的关键优势** 的 [Unsloth 套件](https://github.com/unslothai/unsloth) 和量化版本在于我们积极参与修复主流模型中的 bug。我们直接与以下团队合作： [Qwen3](https://www.reddit.com/r/LocalLLaMA/comments/1kaodxu/qwen3_unsloth_dynamic_ggufs_128k_context_bug_fixes/), [Meta（Llama 4）](https://github.com/ggml-org/llama.cpp/pull/12889), [Mistral（Devstral）](https://app.gitbook.com/o/HpyELzcNe0topgVLGCZY/s/xhOjnexMCB3dmuQFQ2Zq/~/changes/618/basics/tutorials-how-to-fine-tune-and-run-llms/devstral-how-to-run-and-fine-tune), [谷歌（Gemma 1–3）](https://news.ycombinator.com/item?id=39671146) 和 [微软（Phi-3/4）](https://simonwillison.net/2025/Jan/11/phi-4-bug-fixes)，贡献了提高准确率的修复。
{% endcolumn %}

{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FtRVN97QDzO0Pq7SscC7x%2Fgemma%20426b%20bench.png?alt=media&amp;token=80b4da76-efe9-4554-8e31-cca6494d456c" alt=""><figcaption><p>Gemma 4 26B A4B 基准测试（越低越好）</p></figcaption></figure>

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FHq98A18pHA2ePwlInrFG%2Fqwen36_mean_q6k_corrected_arrow_pareto_fixed.png?alt=media&amp;token=a5190c8a-4d04-4d4d-be94-dd15214e6687" alt=""><figcaption><p>Qwen3.6 基准测试（越低越好）</p></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

{% hint style="success" %}
Unsloth Dynamic GGUF 现在可以在 [Unsloth Studio](/docs/zh/xin/studio.md) ✨

<img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FsERzR65n4jc1UtuSHozZ%2Fwedefrwfwe.gif?alt=media&amp;token=e303ed9e-0d90-456d-8d57-874a06803903" alt="" data-size="original">
{% endhint %}

{% hint style="success" %}
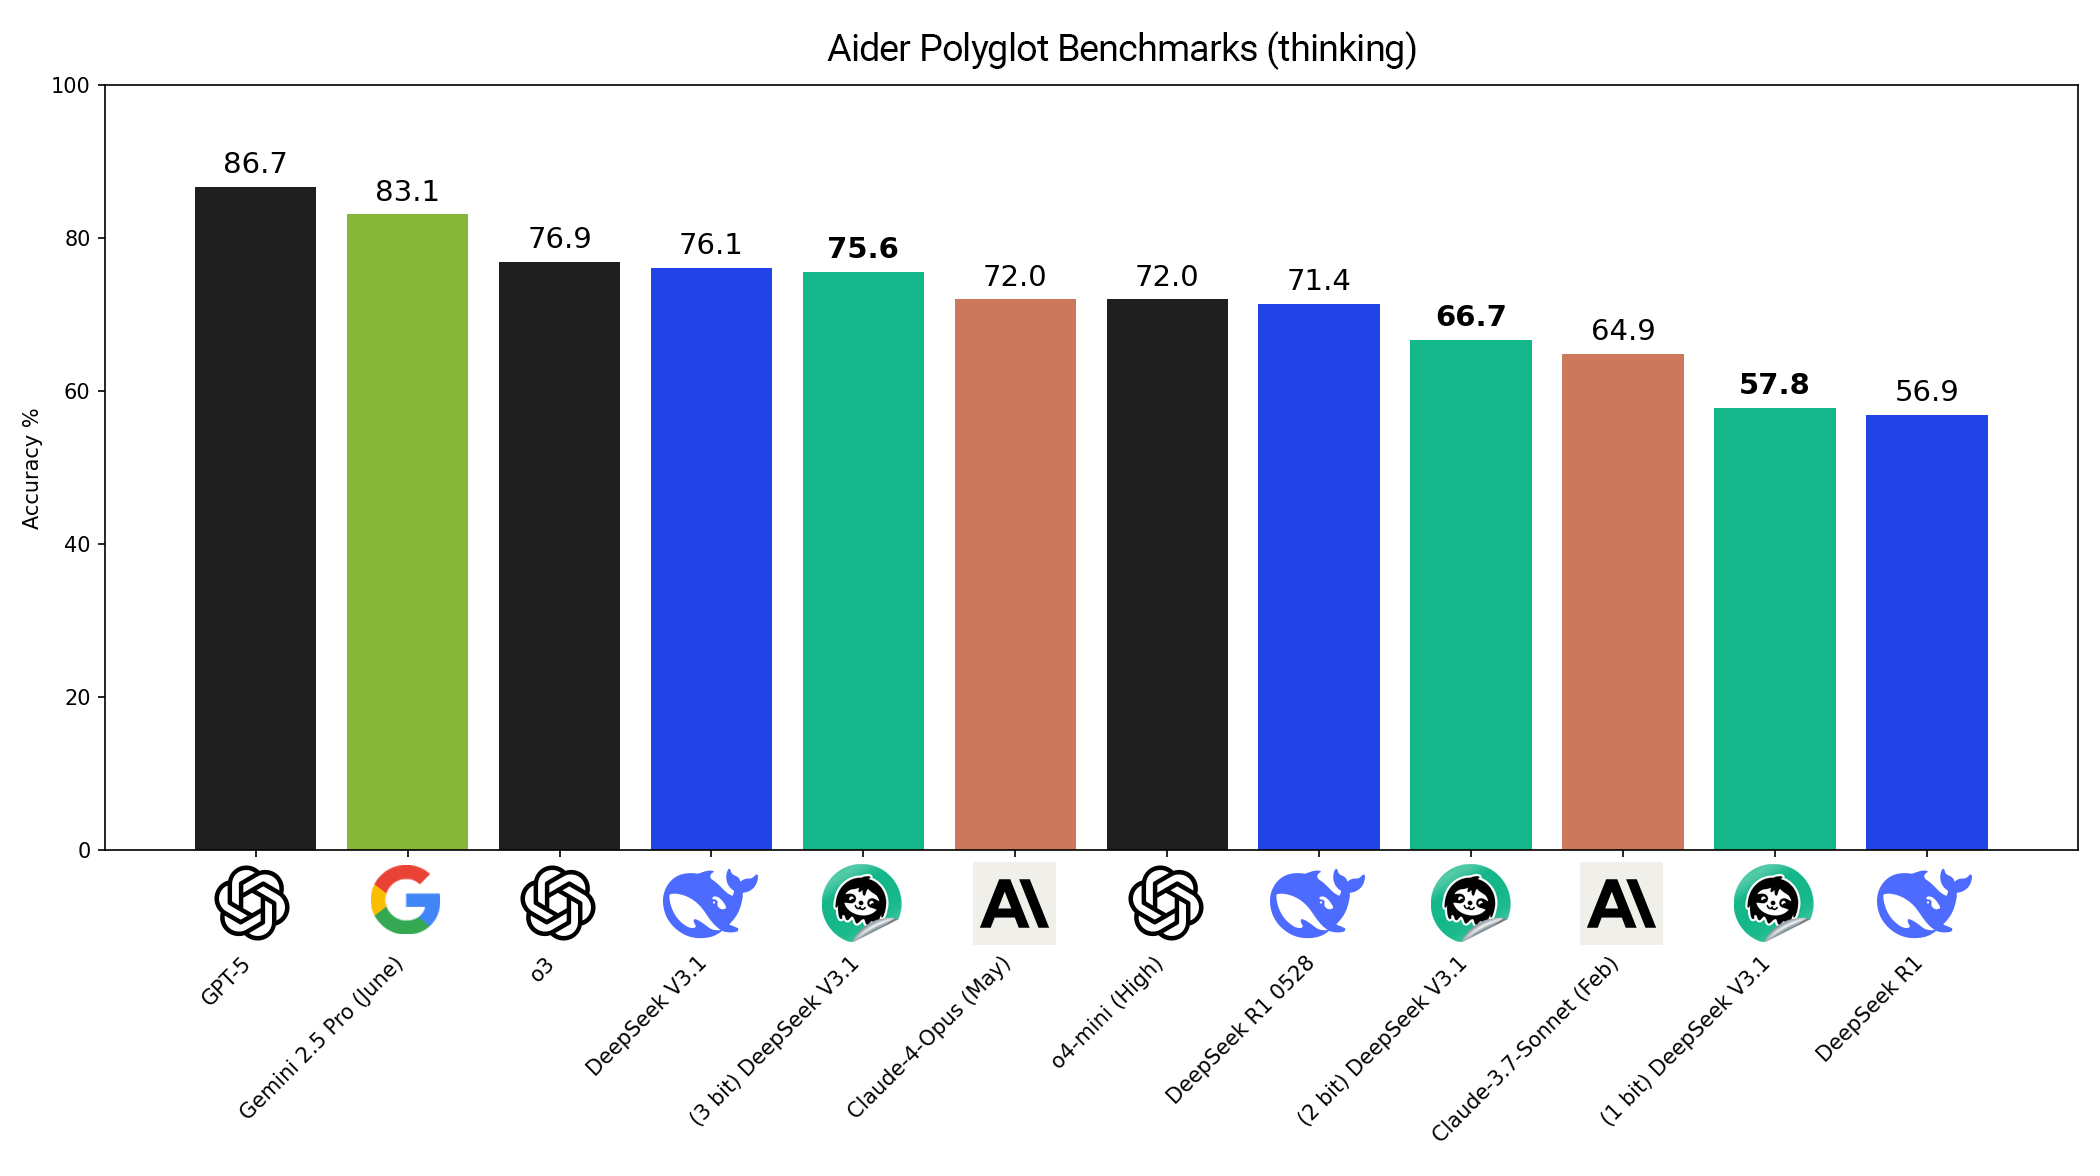
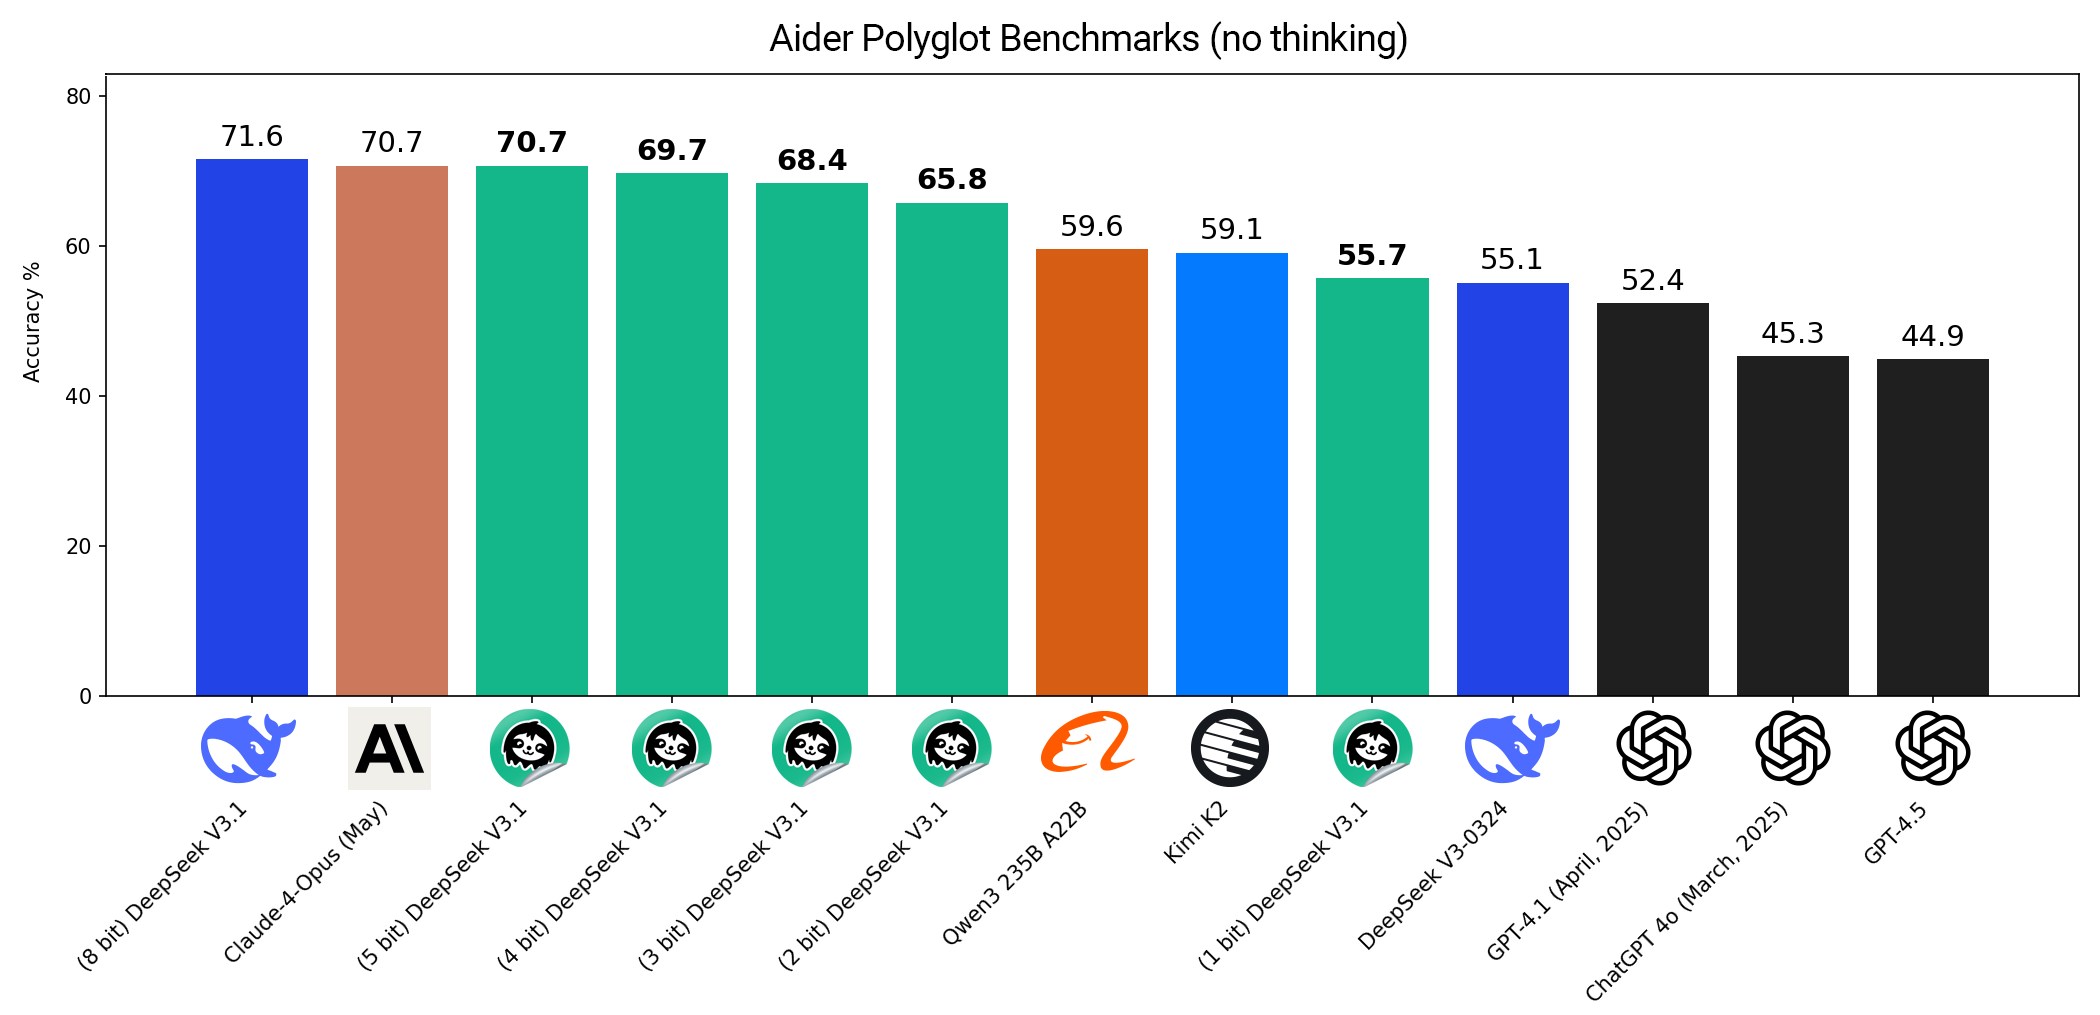
[2025年9月10日更新：](/docs/zh/ji-chu/dynamic-3.0-ggufs/unsloth-dynamic-ggufs-on-aider-polyglot.md) 你们要求更严苛的基准测试，所以这里是 Aider Polyglot 结果！我们的 Dynamic 3-bit DeepSeek V3.1 GGUF 得分 **75.6%**，超过了许多全精度 SOTA LLM。 [阅读更多。](/docs/zh/ji-chu/dynamic-3.0-ggufs/unsloth-dynamic-ggufs-on-aider-polyglot.md)
<img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-a114143bdd47add988182aabf9313ab40be38d7d%2Faider%20thinking.png?alt=media" alt="DeepSeek-V3.2 Thinking Aider Benchmarks" data-size="original"><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-b085c16c7f8351308229f1341846cbf1a2617d0a%2Faider%20non.png?alt=media" alt="Llama 4 5-shot MMLU Benchmarks" data-size="original">
{% endhint %}

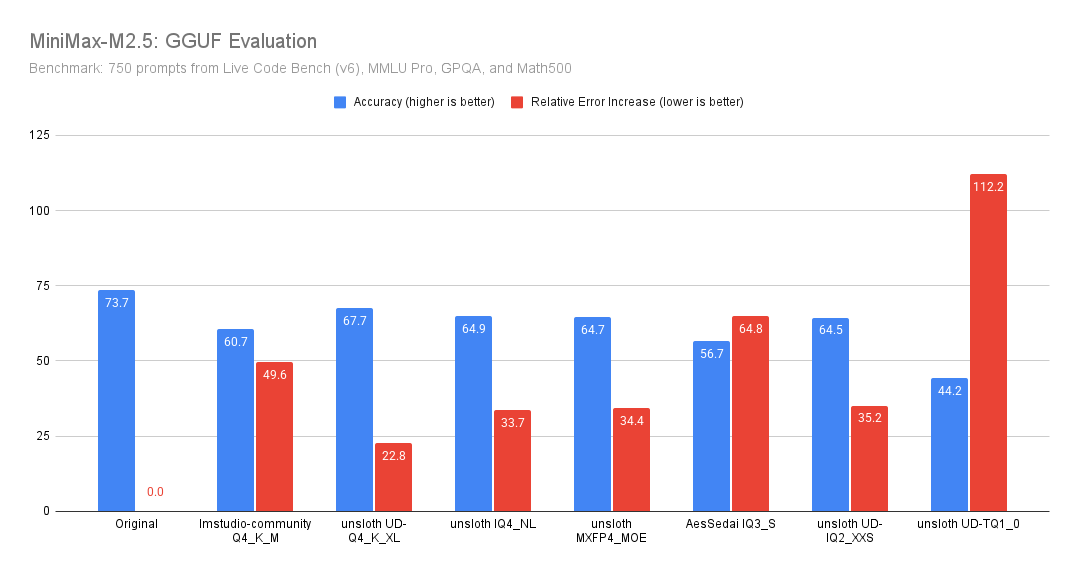
你也可以查看 Benjamin Marie 针对 LiveCodeBench v6、MMLU Pro 等进行的真实世界用例基准测试：

<div><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FhfO2gsbz2lWrZXg3ojyE%2FHCGBTzgboAASv_A.png?alt=media&amp;token=7d6334ca-4f3c-4946-aacd-d55527375fce" alt="" width="563"><figcaption></figcaption></figure> <figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Ftbfnqq8ppzwFbeqPhnw0%2FHAfMRrrXQAALkQb.png?alt=media&amp;token=9730d4e1-3d4a-4ae6-92bf-32aa6724ab86" alt="" width="450"><figcaption></figcaption></figure></div>

你可以看到，尽管体积约小 8GB，Unsloth 的 GGUF 表现仍优于非 Unsloth 量化版本。

我们对基准测试和评估的详细分析见下文。

### 💡 Dynamic v2.0 有哪些新内容？

* **GGUF + safetensors 的层选择全面改造：** Unsloth Dynamic 2.0 现在会更智能、更广泛地有选择性地对层进行量化。我们不再只修改少数选定层，而是动态调整每个可能层的量化类型，并且不同层和不同模型的组合会有所不同。
* 当前选定的以及未来所有 GGUF 上传都将采用 Dynamic 2.0 和我们的新校准数据集。该数据集包含超过 >1.5M **个 token** （取决于模型），并由高质量、人工筛选和清洗过的数据组成——从而大幅提升对话聊天性能。
* 此前，我们的 Dynamic 量化（DeepSeek-R1 1.58-bit GGUF）仅对 MoE 架构有效。 <mark style="background-color:green;">**Dynamic 2.0 量化现在适用于所有模型（包括 MoE 和非 MoE）**</mark>.
* **模型特定量化：** 每个模型现在都使用量身定制的量化方案。例如，Gemma 3 中被量化的层与 Llama 4 中的层差异显著。
* 为了最大化效率，尤其是在 Apple Silicon 和 ARM 设备上，我们现在还添加了 Q4\_NL、Q5.1、Q5.0、Q4.1 和 Q4.0 格式。

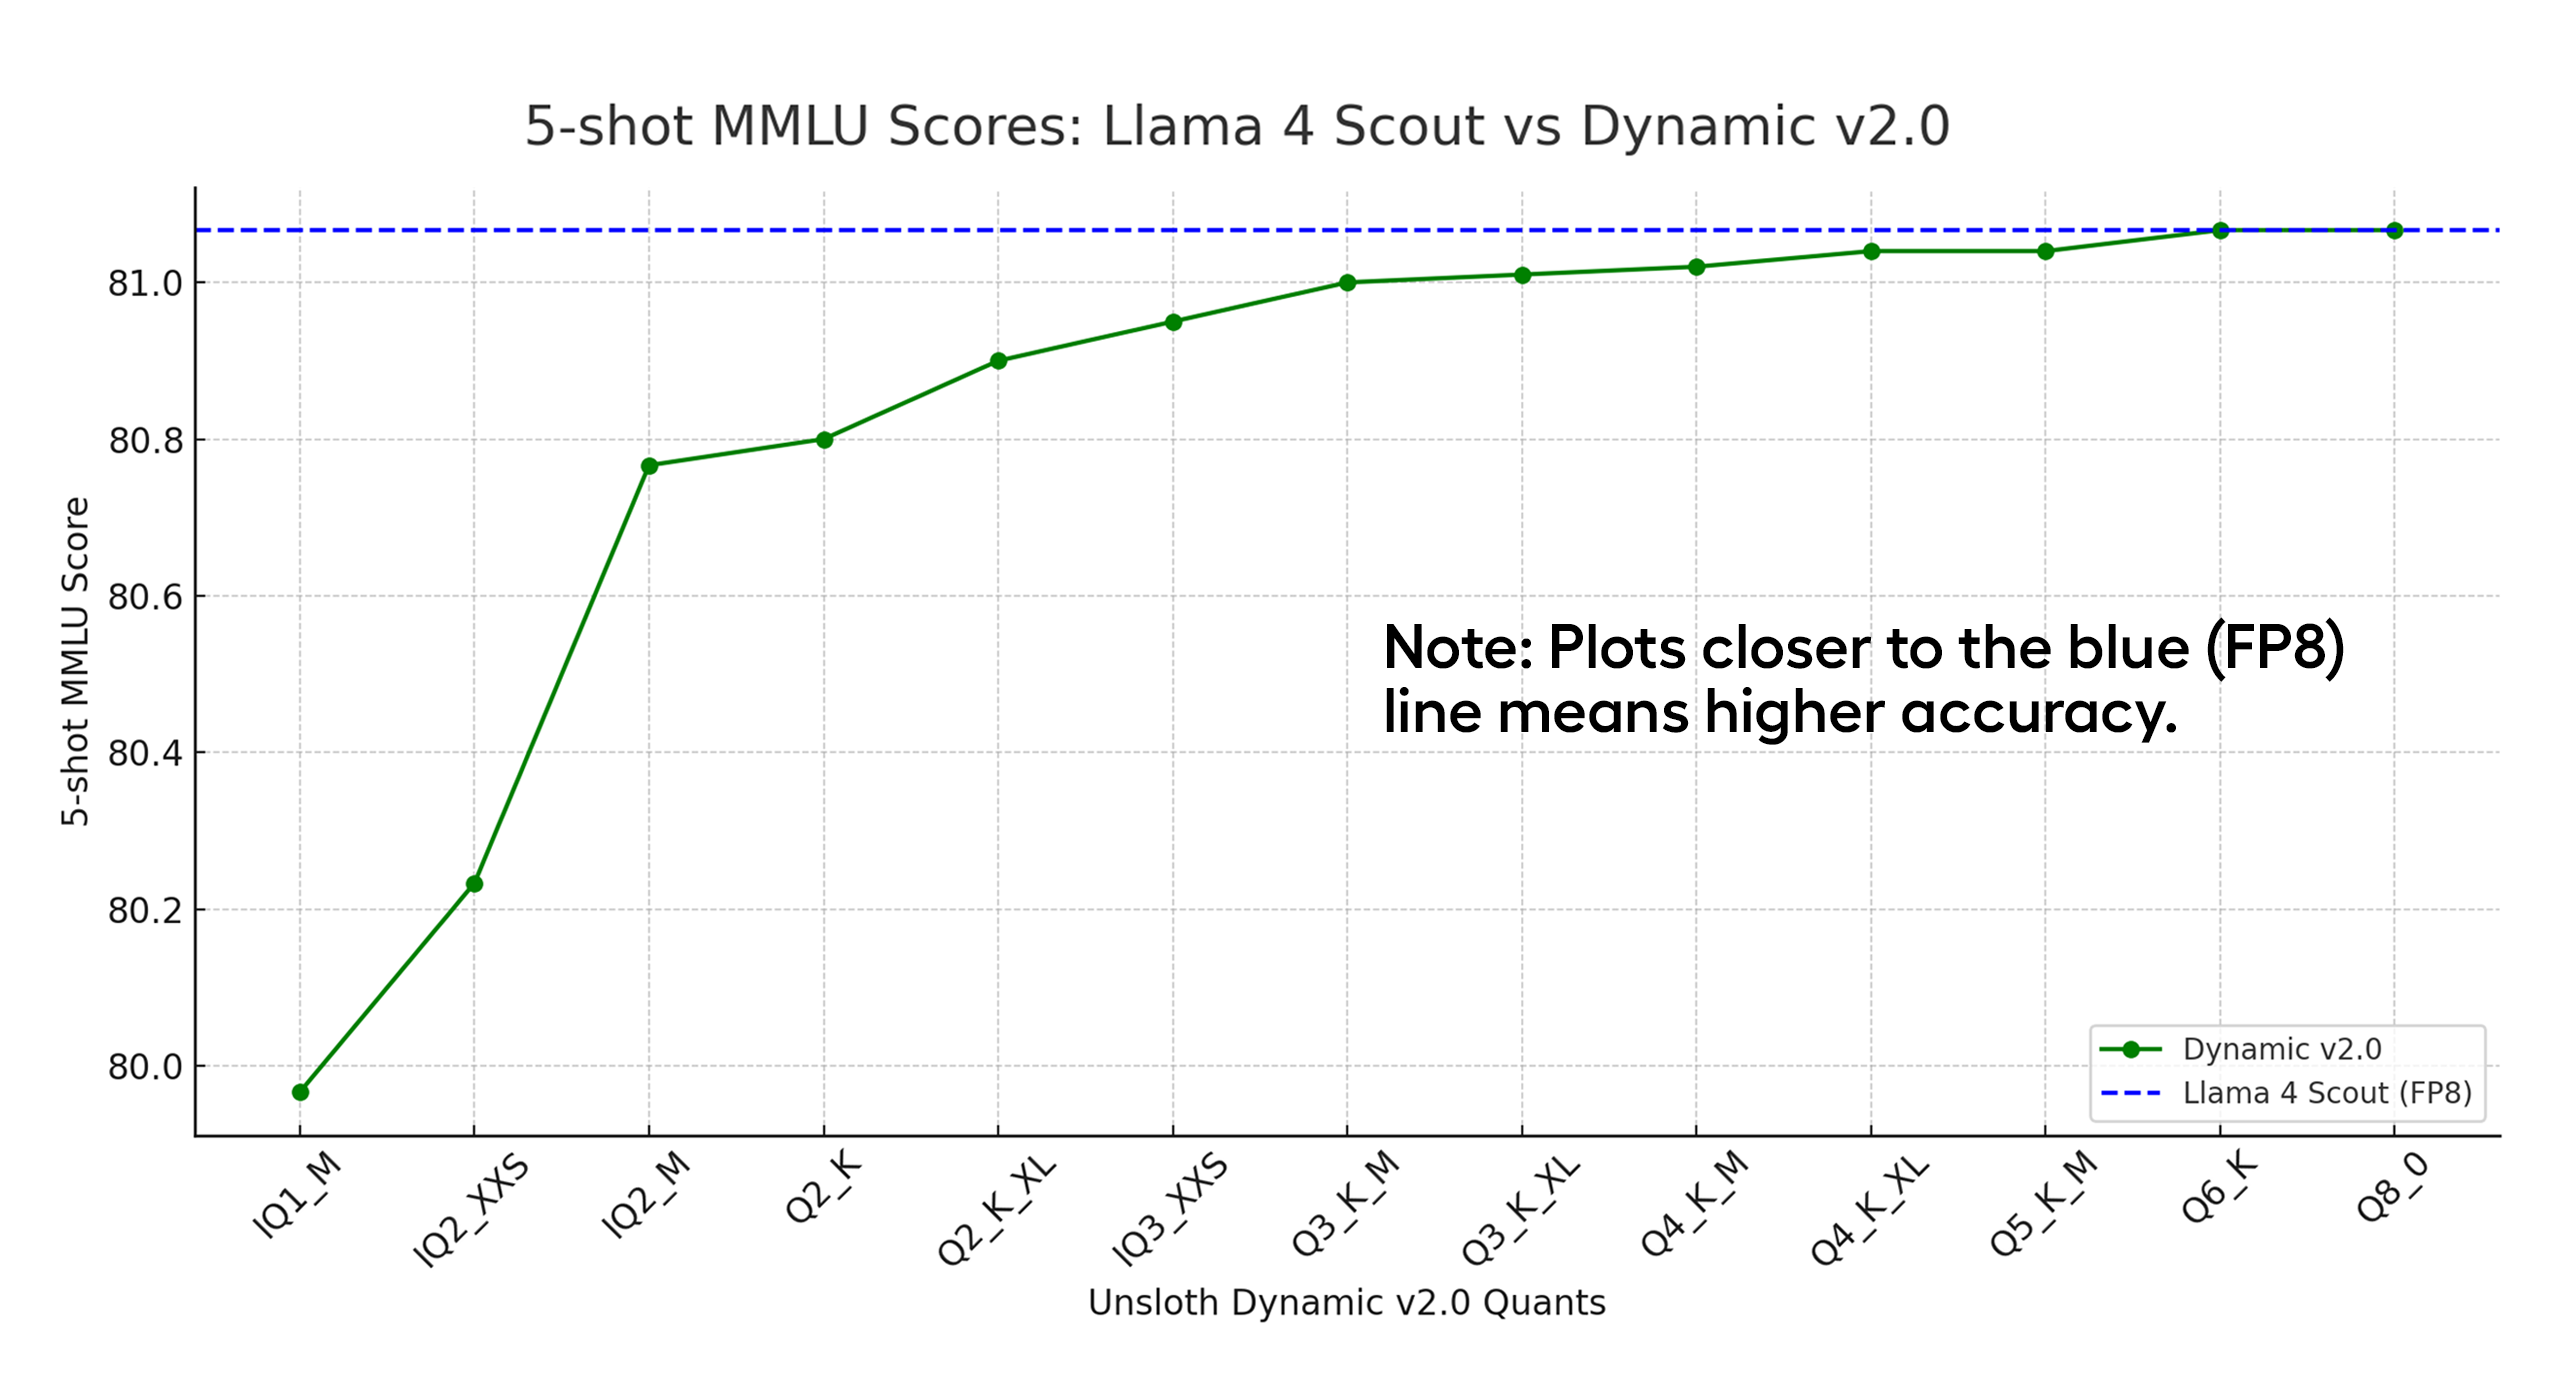
为确保基准测试准确，我们构建了一个内部评估框架，使其与 Llama 4 和 Gemma 3 官方报告的 5-shot MMLU 分数匹配。这让我们能够对全精度与 Dynamic v2.0 进行苹果对苹果的比较， **QAT** 以及标准 **imatrix** GGUF 量化版本。

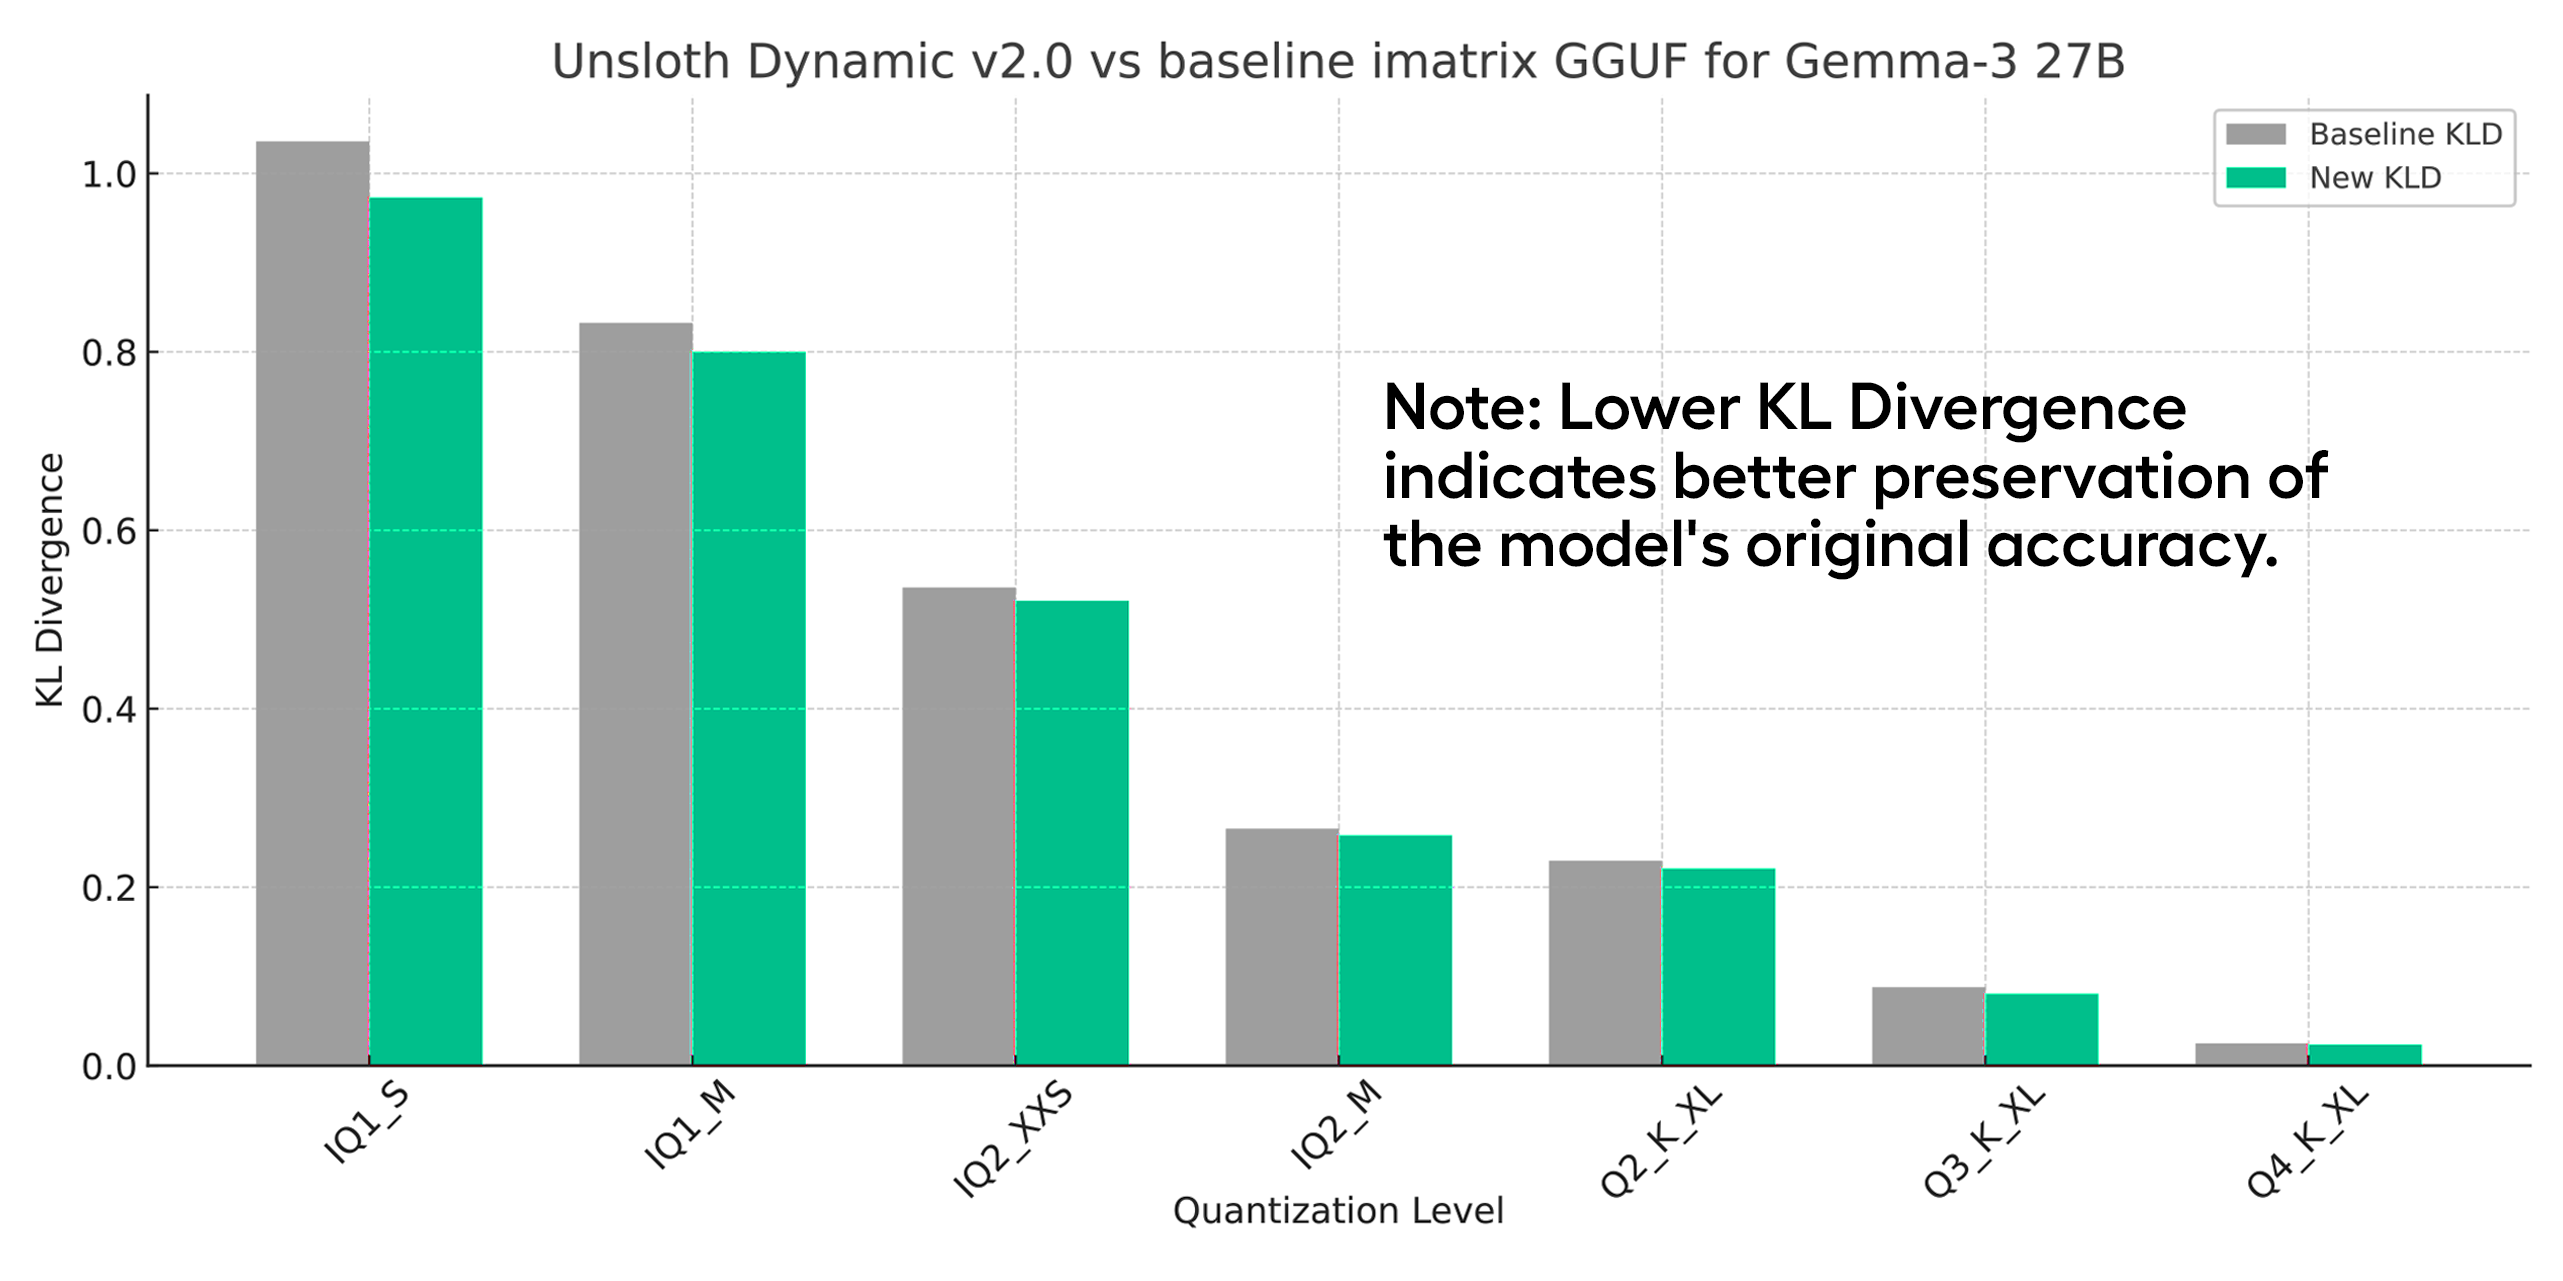
<div><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-fd0a92a2bea8efa37b71946ea934a22f00589f40%2Fkldivergence%20graph.png?alt=media" alt="" width="563"><figcaption></figcaption></figure> <figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-76662317725a3b76fb1e5e33b586c86e712bee6f%2F5shotmmlu.png?alt=media" alt="" width="563"><figcaption></figcaption></figure></div>

未来所有 GGUF 上传都将采用 Unsloth Dynamic 2.0，而我们的 Dynamic 4-bit safetensor 量化版本在未来也会从中受益。

## 📊 为什么是 KL 散度？

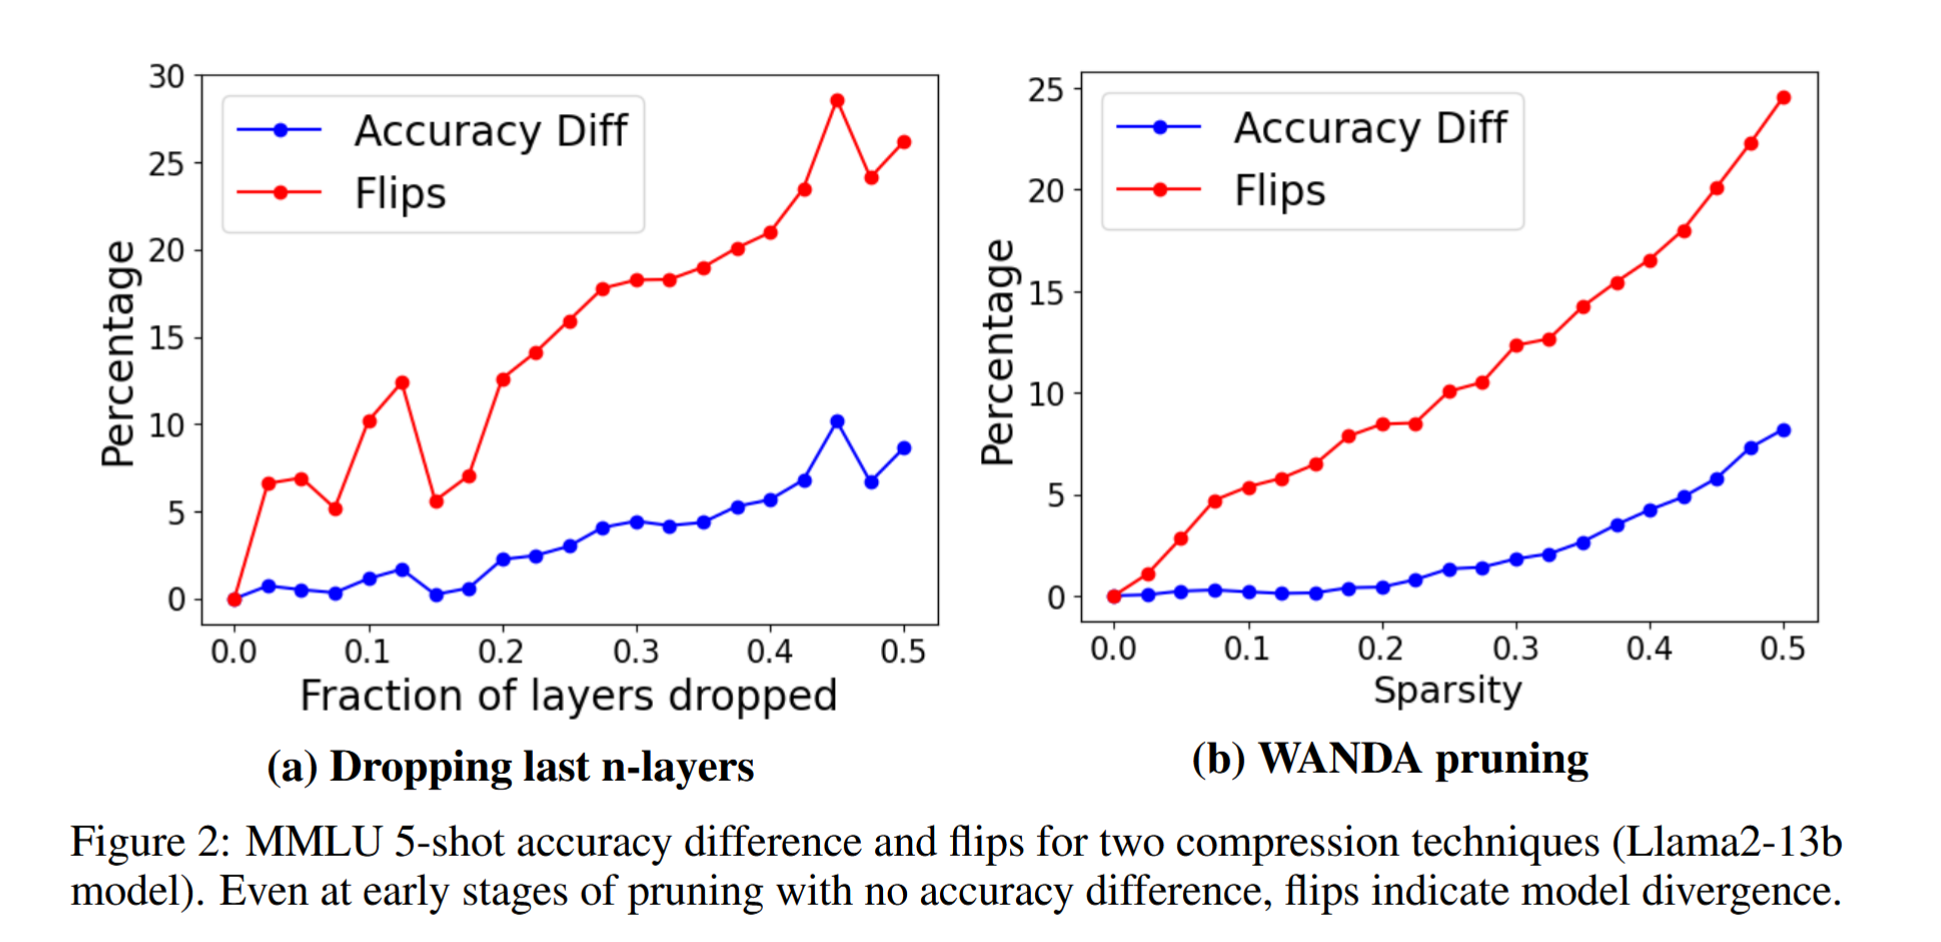
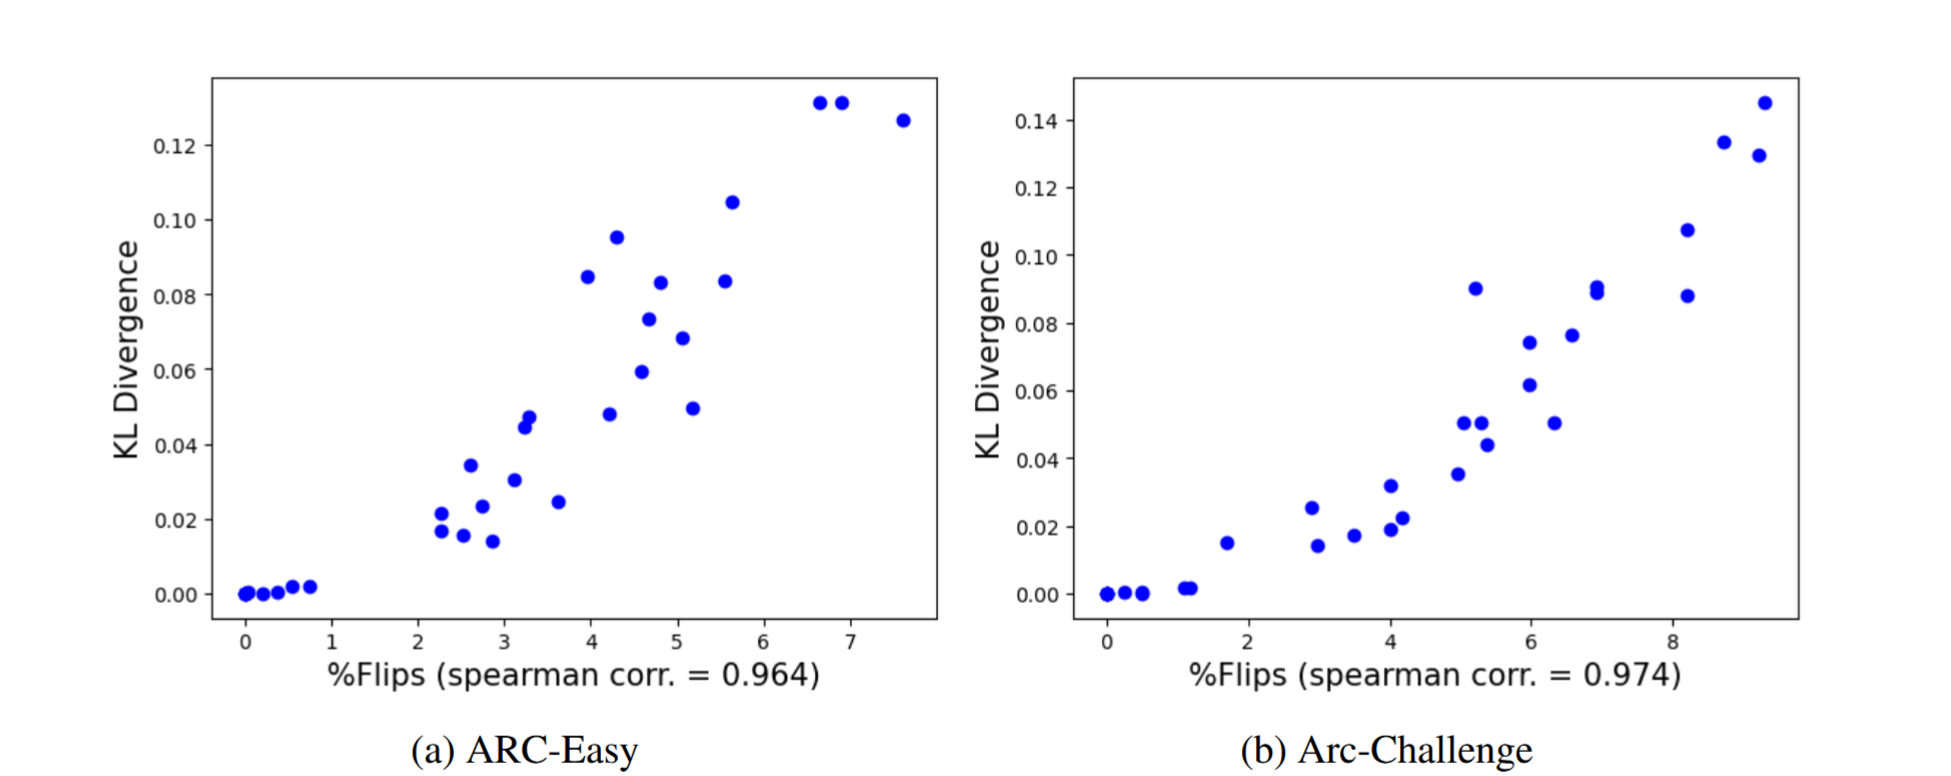
[准确率并非你所需要的一切](https://arxiv.org/pdf/2407.09141) 展示了即便通过选择不必要的层进行剪枝，在“翻转”方面仍会产生巨大差异。“翻转”定义为答案从错误变为正确，或从正确变为错误。论文表明，当我们剪枝层或进行量化时，MMLU 可能不会下降，但那是因为某些错误答案可能“翻转”成了正确答案。我们的目标是匹配原始模型，因此衡量“翻转”是一个很好的指标。

<div><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-5a97c101b0df31fb49df20ce4241930897098cf8%2Fimage.png?alt=media" alt=""><figcaption></figcaption></figure> <figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-e4a60354ad8613b6f2361f63fa82c552e00fdda9%2Fimage.png?alt=media" alt=""><figcaption></figcaption></figure></div>

{% hint style="info" %}
**KL Divergence** 应该是 **报告量化误差的黄金标准之一** 根据论文《准确率并非你所需要的一切》。 **使用困惑度是错误的** 因为输出 token 的值可能相互抵消，所以我们必须使用 KLD 或更难的基准测试，如 [Aider](/docs/zh/ji-chu/dynamic-3.0-ggufs/unsloth-dynamic-ggufs-on-aider-polyglot.md).
{% endhint %}

论文还表明，KL 散度与翻转高度相关，因此我们的目标是在尽可能少增加量化磁盘空间的同时，降低平均 KL 散度。

## ⚖️ 校准数据集过拟合

大多数框架使用维基百科文章测试集来报告困惑度和 KL 散度。不过，我们注意到，使用同样与维基百科相关的校准数据集会导致量化版本过拟合，并获得更低的困惑度分数。我们使用 [Calibration\_v3](https://gist.github.com/bartowski1182/eb213dccb3571f863da82e99418f81e8) 和 [Calibration\_v5](https://gist.github.com/tristandruyen/9e207a95c7d75ddf37525d353e00659c/) 数据集进行公平测试，其中除了其他数据外还包括一些 wikitext 数据。 <mark style="background-color:red;">**此外，指令模型有独特的聊天模板，而仅使用文本的校准数据集对指令模型并不有效**</mark> （基础模型可以）。事实上，大多数 imatrix GGUF 通常都带有这些问题进行校准。因此，它们在也使用维基百科数据的 KL 散度基准测试上自然表现更好，因为模型实际上是针对该领域进行了优化。

为确保公平且受控的评估，在进行 KL 散度基准测试时，我们不会使用我们自己的校准数据集（它是为聊天性能优化的）。相反，我们使用相同的标准维基百科数据集进行测试，从而能够直接比较我们的 Dynamic 2.0 方法与基线 imatrix 方法的性能。

## :1234: MMLU 复现之旅

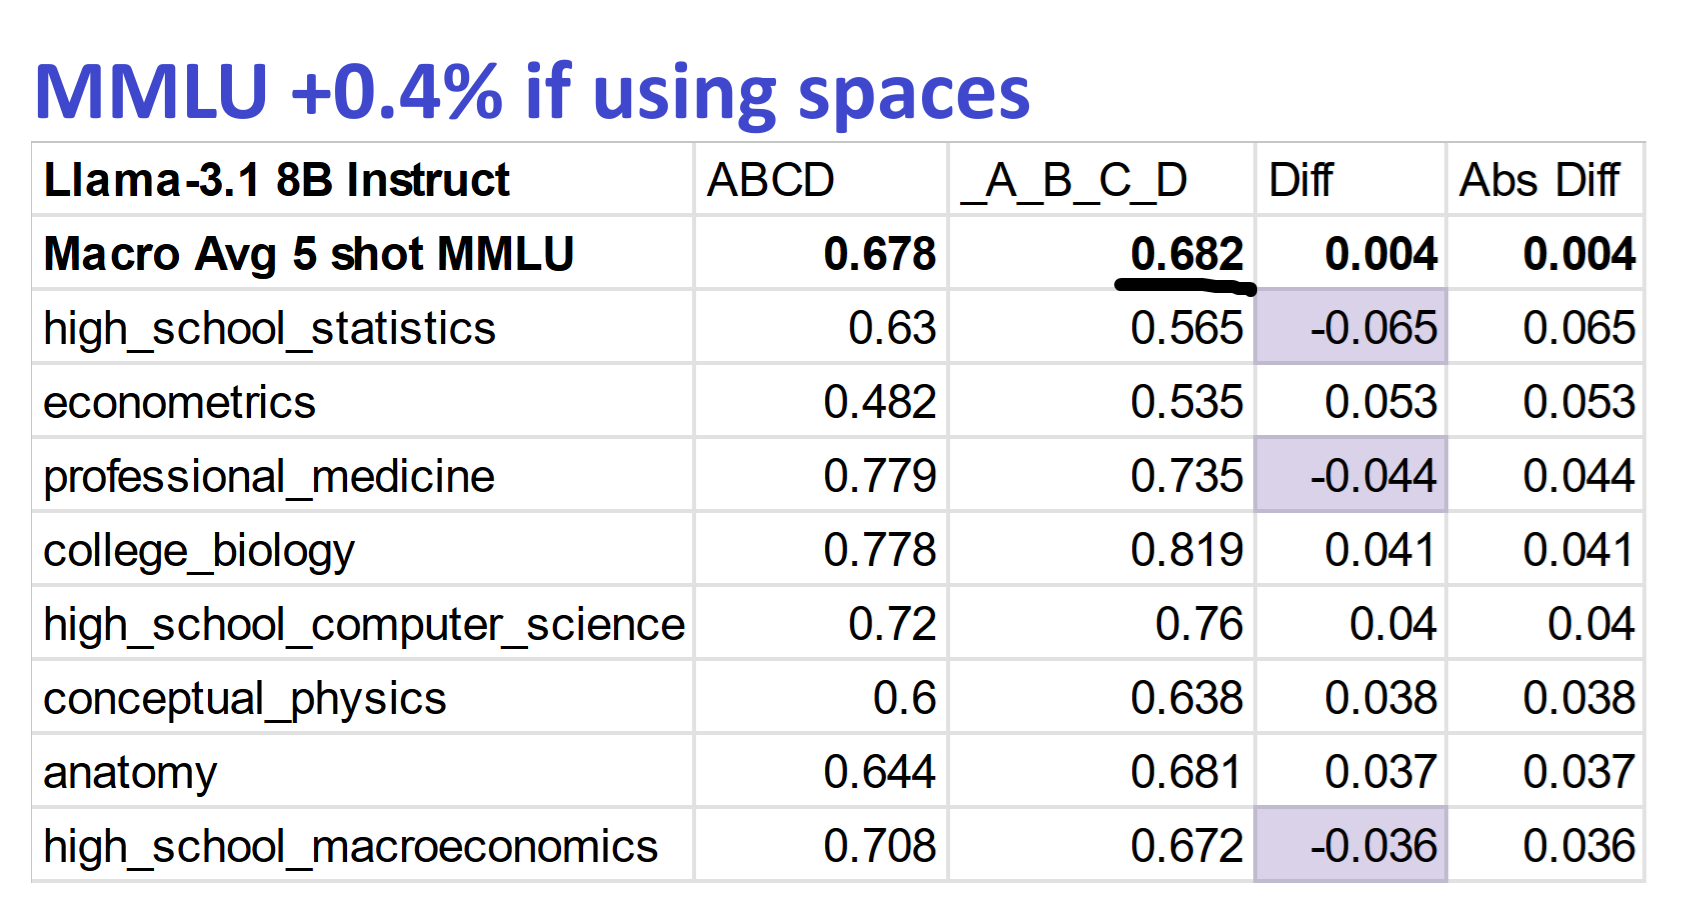
* 复现 MMLU 5-shot 简直是噩梦。我们 <mark style="background-color:red;">**无法**</mark> 复现许多模型的 MMLU 结果，包括 Llama 3.1（8B）Instruct、Gemma 3（12B）等，原因在于 <mark style="background-color:yellow;">**细微的实现问题**</mark>。例如，Llama 3.1（8B）理论上应达到约 68.2%，而使用错误实现时只能达到 <mark style="background-color:red;">**35% 的准确率。**</mark>

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-cc2b4b2bc512b3c9bc065250930259b9b9a9fce0%2FMMLU%20differences.png?alt=media" alt="" width="375"><figcaption><p>MMLU 实现问题</p></figcaption></figure>

* 使用朴素的 MMLU 实现，Llama 3.1（8B）Instruct 的 MMLU 5-shot 准确率为 67.8%。不过我们发现 Llama **将“A”和“\_A”（前面带空格的 A）标记为不同的 token id**。如果我们同时考虑有空格和无空格的 token，就能得到 68.2% <mark style="background-color:green;">(+0.4%)</mark>
* 有趣的是，按照 Eleuther AI 的 [LLM Harness](https://github.com/EleutherAI/lm-evaluation-harness/blob/main/lm_eval/tasks/llama3/instruct/mmlu/_continuation_template_yaml) Llama 3 还会附加 <mark style="background-color:purple;">**“The best answer is”**</mark> 到问题中，遵循 Llama 3 原始的 MMLU 基准测试。
* 还有许多其他细微问题，因此为了在受控环境中对所有内容进行基准测试，我们通过直接研究 [github.com/hendrycks/test](https://github.com/hendrycks/test) 并在多个模型上验证结果、与报告数值进行比较，从零开始设计了我们自己的 MMLU 实现。

## :sparkles: Gemma 3 QAT 复现，基准测试

Gemma 团队发布了两个 Gemma 3 的 QAT（量化感知训练）版本：

1. Q4\_0 GGUF - 通过公式将所有层量化为 Q4\_0 `w = q * block_scale` ，每个 block 有 32 个权重。详见 [llama.cpp wiki ](https://github.com/ggml-org/llama.cpp/wiki/Tensor-Encoding-Schemes)了解更多细节。
2. int4 版本——大概是 [TorchAO int4 风格](https://github.com/pytorch/ao/blob/main/torchao/quantization/README.md)?

我们对所有 Q4\_0 GGUF 版本进行了基准测试，并对 12B 模型进行了广泛实验。我们看到 **12B Q4\_0 QAT 模型得分 67.07%** 而全 bfloat16 12B 版本在 5-shot MMLU 上得分 67.15%。这非常令人印象深刻！27B 模型基本已经非常接近了！

<table><thead><tr><th>指标</th><th>1B</th><th valign="middle">4B</th><th>12B</th><th>27B</th></tr></thead><tbody><tr><td>MMLU 5-shot</td><td>26.12%</td><td valign="middle">55.13%</td><td><mark style="background-color:blue;"><strong>67.07%（BF16 为 67.15%）</strong></mark></td><td><strong>70.64%（BF16 为 71.5%）</strong></td></tr><tr><td>磁盘空间</td><td>0.93GB</td><td valign="middle">2.94GB</td><td><strong>7.52GB</strong></td><td>16.05GB</td></tr><tr><td><mark style="background-color:green;"><strong>效率*</strong></mark></td><td>1.20</td><td valign="middle">10.26</td><td><strong>5.59</strong></td><td>2.84</td></tr></tbody></table>

我们设计了一个新的 **效率指标** 用于计算模型的实用性，同时考虑其磁盘大小和 MMLU 5-shot 分数：

$$
\text{Efficiency} = \frac{\text{MMLU 5 shot score} - 25}{\text{Disk Space GB}}
$$

{% hint style="warning" %}
我们必须 **减去 25** 因为 MMLU 有 4 个选项——A、B、C 或 D。假设我们做出一个只会随机选择答案的模型——它会得到 25% 准确率，而且磁盘空间只有几字节。但显然这不是一个有用的模型。
{% endhint %}

下面是一张关于相对于基础模型的 KL 散度的表格，展示了改进。提醒一下，KL 散度越接近 0 越好（即 0 表示与全精度模型完全相同）

| 量化版本      | 基线 KLD   | GB    | 新 KLD    | GB    |
| --------- | -------- | ----- | -------- | ----- |
| IQ1\_S    | 1.035688 | 5.83  | 0.972932 | 6.06  |
| IQ1\_M    | 0.832252 | 6.33  | 0.800049 | 6.51  |
| IQ2\_XXS  | 0.535764 | 7.16  | 0.521039 | 7.31  |
| IQ2\_M    | 0.26554  | 8.84  | 0.258192 | 8.96  |
| Q2\_K\_XL | 0.229671 | 9.78  | 0.220937 | 9.95  |
| Q3\_K\_XL | 0.087845 | 12.51 | 0.080617 | 12.76 |
| Q4\_K\_XL | 0.024916 | 15.41 | 0.023701 | 15.64 |

如果我们绘制磁盘空间增加与 KL 散度变化比率的图，就能看出更明显的收益！我们的动态 2bit Q2\_K\_XL 将 KLD 降低了不少（约 7.5%）。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-5b352d0449e723556e6e871396c2ee78ae8ec3dc%2Fchart(2).svg?alt=media" alt=""><figcaption></figcaption></figure>

Gemma 3（27B）的 MMLU 结果截断表。见下方。

1. **我们的动态 4bit 版本小 2GB，同时相比 QAT 版本额外提高了 1% 的准确率！**
2. 从效率角度看，2bit Q2\_K\_XL 等表现似乎非常好！

| 量化版本           | Unsloth   | Unsloth + QAT | 磁盘大小      | 效率       |
| -------------- | --------- | ------------- | --------- | -------- |
| IQ1\_M         | 48.10     | 47.23         | 6.51      | 3.42     |
| IQ2\_XXS       | 59.20     | 56.57         | 7.31      | 4.32     |
| IQ2\_M         | 66.47     | 64.47         | 8.96      | 4.40     |
| Q2\_K\_XL      | 68.70     | 67.77         | 9.95      | 4.30     |
| Q3\_K\_XL      | 70.87     | 69.50         | 12.76     | 3.49     |
| **Q4\_K\_XL**  | **71.47** | **71.07**     | **15.64** | **2.94** |
| **Google QAT** |           | **70.64**     | **17.2**  | **2.65** |

<details>

<summary><mark style="color:绿色;">点击这里</mark> 查看完整的 Google Gemma 3（27B）QAT 基准测试：</summary>

| 模型             | Unsloth   | Unsloth + QAT | 磁盘大小      | 效率       |
| -------------- | --------- | ------------- | --------- | -------- |
| IQ1\_S         | 41.87     | 43.37         | 6.06      | 3.03     |
| IQ1\_M         | 48.10     | 47.23         | 6.51      | 3.42     |
| IQ2\_XXS       | 59.20     | 56.57         | 7.31      | 4.32     |
| IQ2\_M         | 66.47     | 64.47         | 8.96      | 4.40     |
| Q2\_K          | 68.50     | 67.60         | 9.78      | 4.35     |
| Q2\_K\_XL      | 68.70     | 67.77         | 9.95      | 4.30     |
| IQ3\_XXS       | 68.27     | 67.07         | 10.07     | 4.18     |
| Q3\_K\_M       | 70.70     | 69.77         | 12.51     | 3.58     |
| Q3\_K\_XL      | 70.87     | 69.50         | 12.76     | 3.49     |
| Q4\_K\_M       | 71.23     | 71.00         | 15.41     | 2.98     |
| **Q4\_K\_XL**  | **71.47** | **71.07**     | **15.64** | **2.94** |
| Q5\_K\_M       | 71.77     | 71.23         | 17.95     | 2.58     |
| Q6\_K          | 71.87     | 71.60         | 20.64     | 2.26     |
| Q8\_0          | 71.60     | 71.53         | 26.74     | 1.74     |
| **Google QAT** |           | **70.64**     | **17.2**  | **2.65** |

</details>

## :llama: Llama 4 Bug 修复 + 运行

我们还帮助修复了一些 Llama 4 bug：

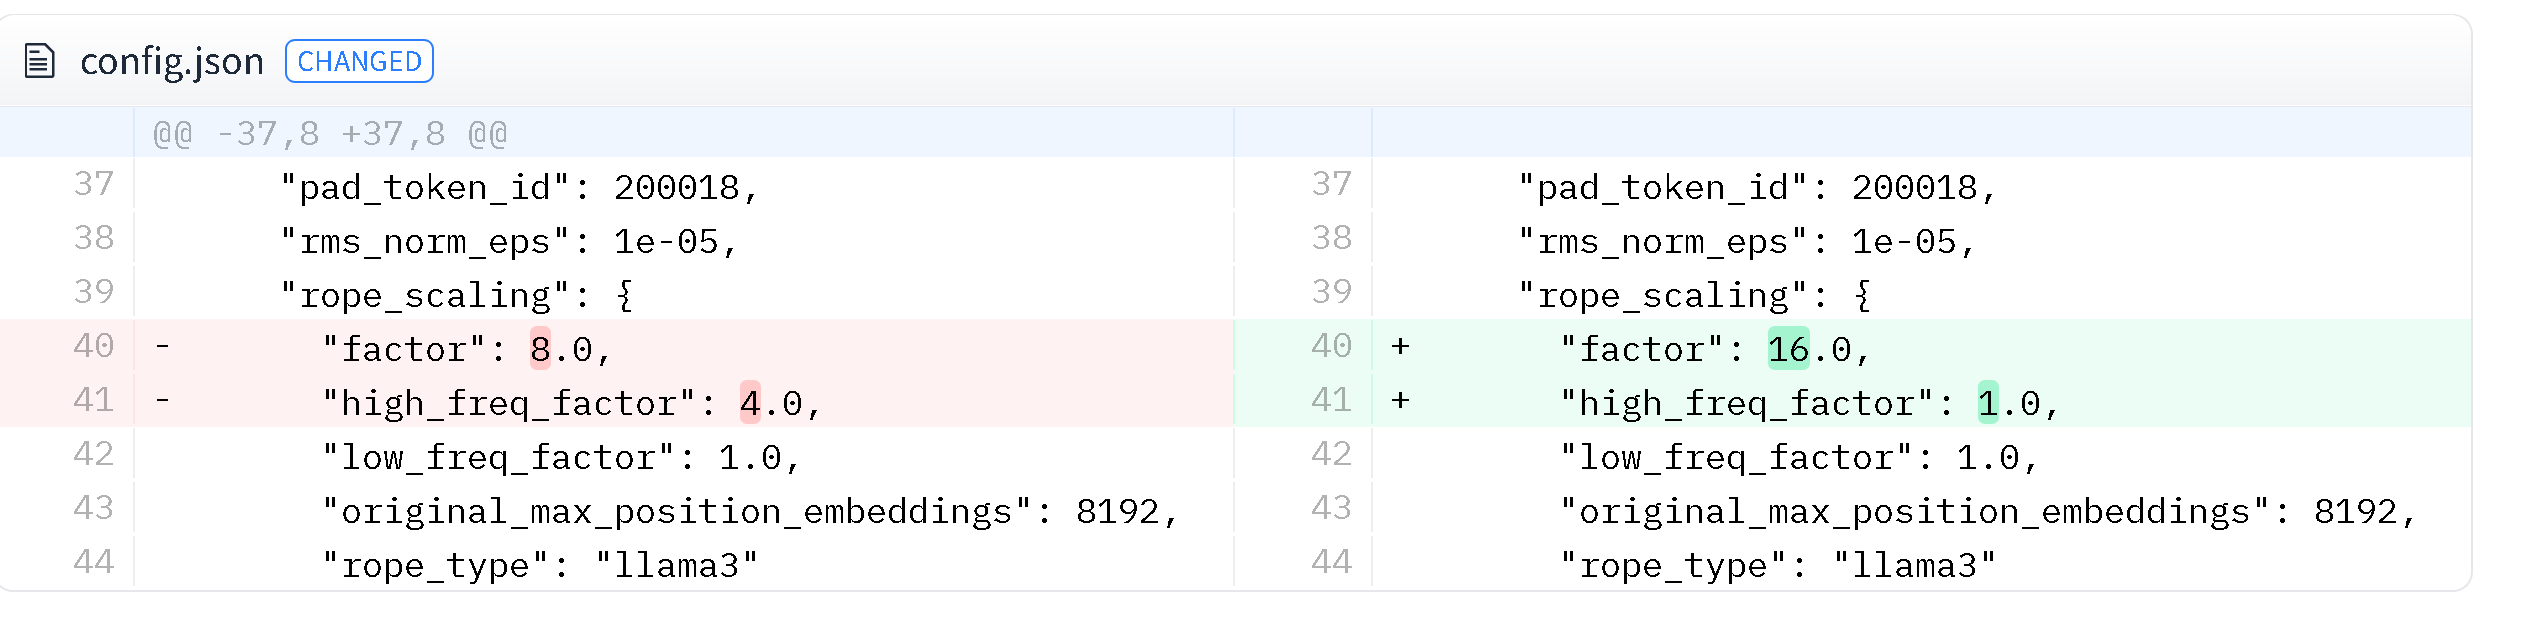
* Llama 4 Scout 在其官方仓库中更改了 RoPE Scaling 配置。我们帮助在 llama.cpp 中解决了使此 [更改生效的问题](https://github.com/ggml-org/llama.cpp/pull/12889)

  <figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-7ff8229dfa96425f50c2c87f9ca988ef9cc99eff%2Fimage.png?alt=media" alt=""><figcaption></figcaption></figure>
* Llama 4 的 QK Norm 中 Scout 和 Maverick 的 epsilon 应该来自配置文件——这意味着应使用 1e-05 而不是 1e-06。我们帮助在 [llama.cpp](https://github.com/ggml-org/llama.cpp/pull/12889) 和 [transformers](https://github.com/huggingface/transformers/pull/37418)
* Llama 4 团队和 vLLM 也独立修复了 QK Norm 在所有 head 之间共享的问题（本不应如此） [这里](https://github.com/vllm-project/vllm/pull/16311)。MMLU Pro 准确率从 68.58% 提高到 71.53%。
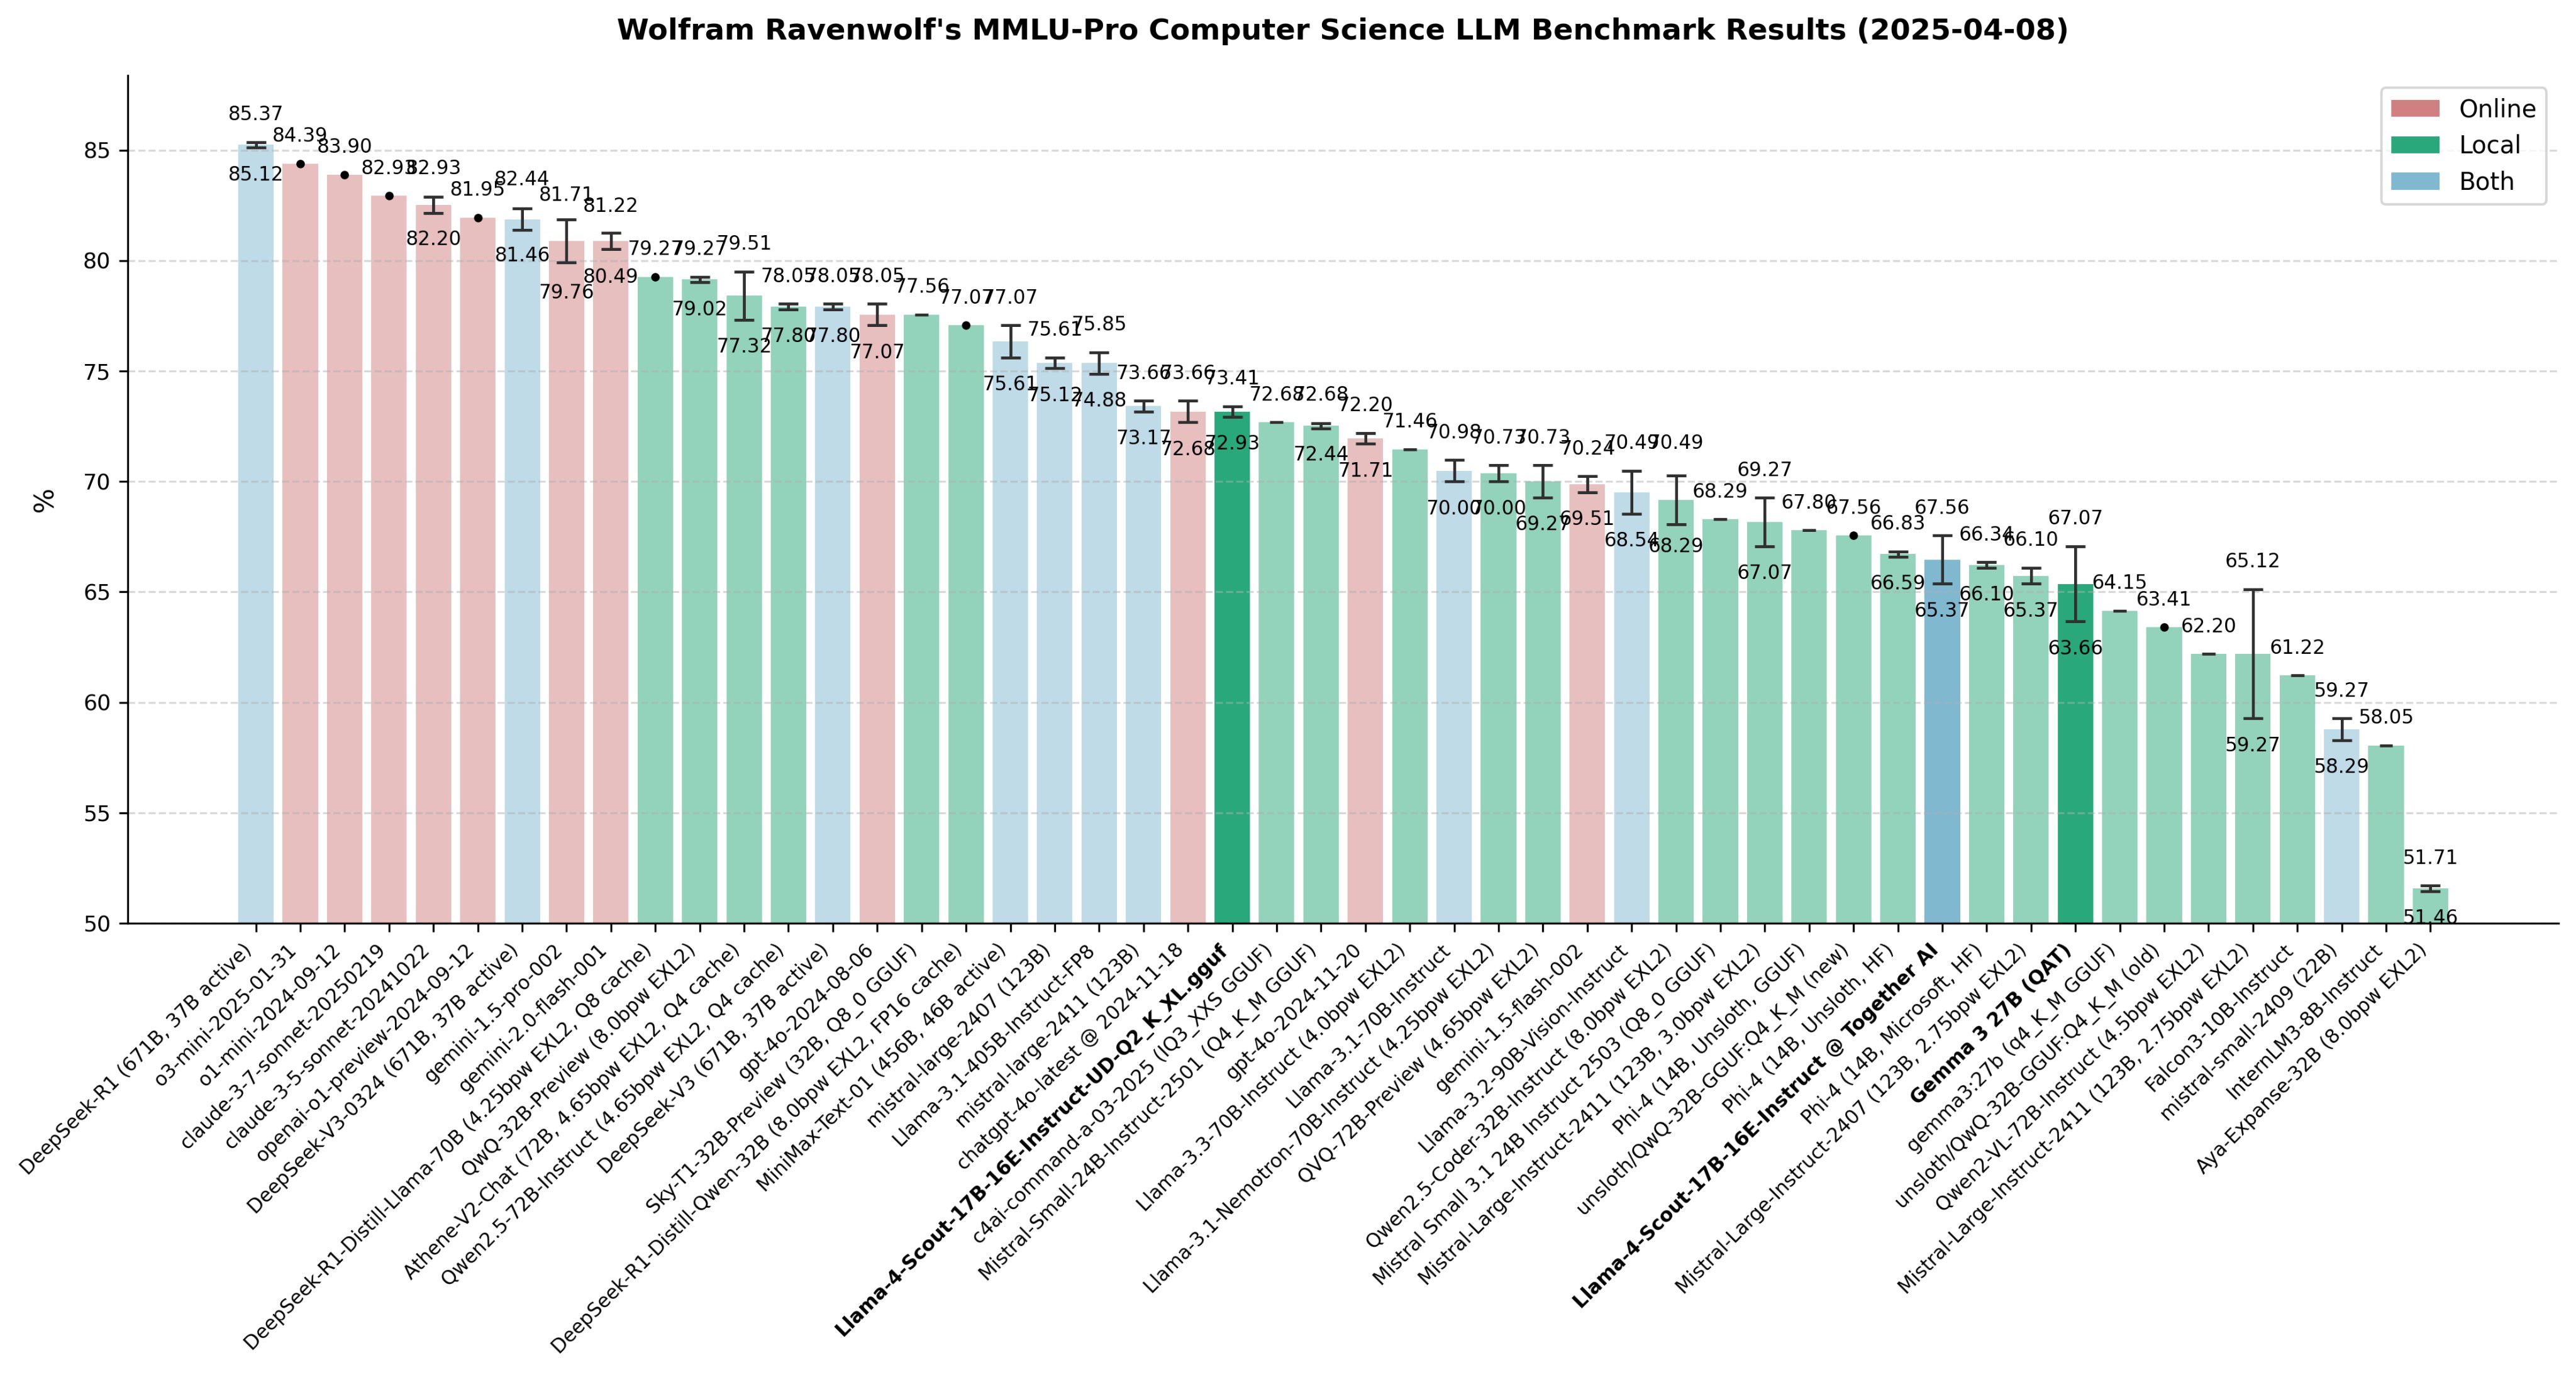
* [Wolfram Ravenwolf](https://x.com/WolframRvnwlf/status/1909735579564331016) 展示了我们通过 llama.cpp 提供的 GGUF 相比第三方推理提供方能达到高得多的准确率——这很可能是上述问题的综合作用，也可能部分由于量化问题。

  <figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-76c49d8c8e3e42f7407f431a2cede369f87878e4%2FGoC79hYXwAAPTMs.jpg?alt=media" alt=""><figcaption></figcaption></figure>

如我们的图所示，我们的 4-bit Dynamic QAT 量化在 5-shot MMLU 上提供了更好的性能，同时体积也更小。

### 运行 Llama 4 Scout：

例如，要运行 Llama 4 Scout，首先克隆 llama.cpp：

```bash
apt-get update
apt-get install pciutils build-essential cmake curl libcurl4-openssl-dev -y
git clone https://github.com/ggml-org/llama.cpp
cmake llama.cpp -B llama.cpp/build \
    -DBUILD_SHARED_LIBS=OFF -DGGML_CUDA=ON -DLLAMA_CURL=ON
cmake --build llama.cpp/build --config Release -j --clean-first --target llama-cli llama-gguf-split
cp llama.cpp/build/bin/llama-* llama.cpp
```

然后为 Scout 下载我们的新 dynamic v 2.0 量化版本：

```python
# !pip install huggingface_hub hf_transfer
import os
os.environ["HF_HUB_ENABLE_HF_TRANSFER"] = "1"
from huggingface_hub import snapshot_download
snapshot_download(
    repo_id = "unsloth/Llama-4-Scout-17B-16E-Instruct-GGUF",
    local_dir = "unsloth/Llama-4-Scout-17B-16E-Instruct-GGUF",
    allow_patterns = ["*IQ2_XXS*"],
)
```

然后让我们进行推理！

{% code overflow="wrap" %}

```bash
./llama.cpp/llama-cli \
    --model unsloth/Llama-4-Scout-17B-16E-Instruct-GGUF/Llama-4-Scout-17B-16E-Instruct-UD-IQ2_XXS.gguf \
    --threads 32 \
    --ctx-size 16384 \
    --n-gpu-layers 99 \
    -ot ".ffn_.*_exps.=CPU" \
    --seed 3407 \
    --prio 3 \
    --temp 0.6 \
    --min-p 0.01 \
    --top-p 0.9 \
    -no-cnv \
    --prompt "<|header_start|>user<|header_end|>\n\n创建一个 Flappy Bird 游戏。<|eot|><|header_start|>assistant<|header_end|>\n\n"
```

{% endcode %}

{% hint style="success" %}
在这里阅读更多关于运行 Llama 4 的内容： <https://docs.unsloth.ai/basics/tutorial-how-to-run-and-fine-tune-llama-4>
{% endhint %}


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.

Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:

```
GET https://unsloth.ai/docs/zh/ji-chu/dynamic-3.0-ggufs.md?ask=<question>&goal=<endgoal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.