> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/ji-chu-zhi-shi/embedding-finetuning.md).
# Unsloth 向量嵌入模型微调指南
了解如何轻松使用 Unsloth 对向量嵌入模型进行微调。
对嵌入模型进行微调,能在特定任务上大幅提升检索和 RAG 性能。它会让模型的向量与您的领域以及与用例相关的“相似性”对齐,从而提升您数据上的搜索、RAG、聚类和推荐效果。
例如:如果你只是把“Google 推出 Pixel 10”和“Qwen 发布 Qwen3”都标记为“科技”,那么它们可能会被嵌入得很相似;但如果你在做语义搜索,它们就不相似,因为它们讲的是不同的事情。微调能帮助模型为你的用例建立“正确”的相似性,从而减少错误并提升结果。
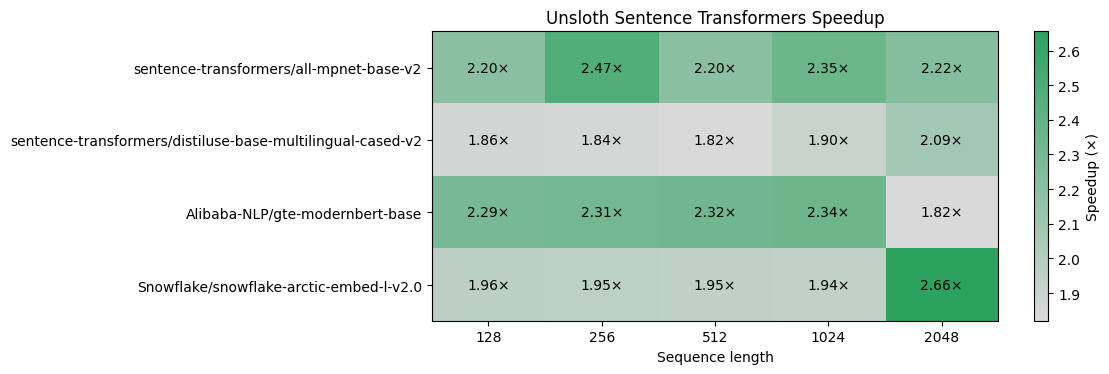
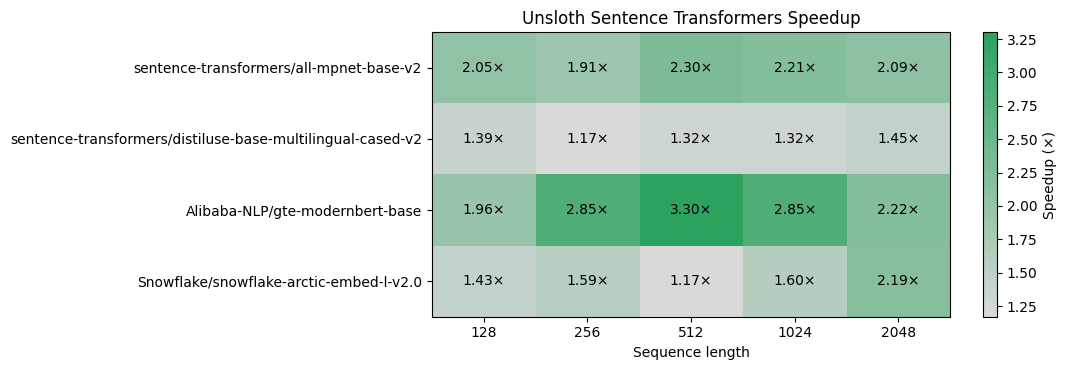
[**Unsloth**](https://github.com/unslothai/unsloth) 现在支持训练嵌入、 **分类器**, **BERT**, **重排序器** 模型 [**约快 1.8-3.3 倍**](#unsloth-benchmarks) 在比其他 Flash Attention 2 实现少 20% 内存、上下文长度长 2 倍的情况下——且不会降低准确率。EmbeddingGemma-300M 仅需 **3GB 显存**。你可以在任何地方使用你训练好的 **模型**:transformers、LangChain、Ollama、vLLM、llama.cpp 等。
Unsloth 使用 [SentenceTransformers](https://github.com/huggingface/sentence-transformers) ,以支持像 Qwen3-Embedding、BERT 等兼容模型。 **即使没有 notebook 或上传,也仍然受支持。**
**我们创建了免费的微调 notebooks,包含 3 个主要用例:**
| [EmbeddingGemma(300M)](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/EmbeddingGemma_\(300M\).ipynb) | [Qwen3-Embedding 4B](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_Embedding_\(4B\).ipynb) • [0.6B](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Qwen3_Embedding_\(0_6B\).ipynb) | [BGE M3](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/BGE_M3.ipynb) |
| ------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------- |
| [ModernBERT](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/bert_classification.ipynb) - 分类 | [All-MiniLM-L6-v2](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/All_MiniLM_L6_v2.ipynb) | [ModernBERT-large](https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/bert_classification.ipynb) |
* `All-MiniLM-L6-v2`:生成紧凑、面向特定领域的句向量,用于语义搜索、检索和聚类,并在您自己的数据上进行调优。
* `tomaarsen/miriad-4.4M-split`:将医学问题和生物医学论文嵌入,以实现高质量的医学语义搜索和 RAG。
* `electroglyph/technical`:更好地捕捉技术文本(文档、规格说明和工程讨论)中的含义和语义相似性。
您可以在以下位置查看我们其余已上传的模型: [我们的合集这里](https://huggingface.co/collections/unsloth/embedding-models).
> 非常感谢 Unsloth 贡献者 [**electroglyph**](https://github.com/unslothai/unsloth/pull/3719),他的工作对支持这一点非常重要。您可以在 Hugging Face 上查看 electroglyph 的自定义模型 [这里](https://huggingface.co/electroglyph).
### 🦥 Unsloth 功能
* 用于嵌入的 LoRA/QLoRA 或全量微调,无需重写您的流水线
* 对仅编码器 `SentenceTransformer` 模型的最佳支持(带有一个 `modules.json`)
* 即使在回退路径下,交叉编码器模型也已确认能正确训练
* 此版本还支持 `transformers v5`
对于没有 `modules.json` 的模型,支持有限 `SentenceTransformers` (我们会自动分配默认的
)。如果你在做自定义内容(自定义头、非标准池化),请再次检查诸如池化后的嵌入行为等输出。某些模型需要自定义添加,例如 MPNet 或 DistilBERT,可通过将梯度检查点补丁到 `transformers` 模型。
### 🛠️ 微调工作流
新的微调流程以 `FastSentenceTransformer`.
主要保存/推送方法:
* `save_pretrained()` 保存 **LoRA 适配器** 到本地文件夹
* `save_pretrained_merged()` 保存 **合并后的模型** 到本地文件夹
* `push_to_hub()` 推送 **LoRA 适配器** 到 Hugging Face
* `push_to_hub_merged()` 推送 **合并后的模型** 到 Hugging Face
**还有一个非常重要的细节:推理加载需要 `for_inference=True`**
`from_pretrained()` 与 Lacker 的其他快速类相似,但有 **一个例外**:
* 要将模型加载为 **推理** 使用 `FastSentenceTransformer`,你 **必须** 传入: `for_inference=True`
因此你的推理加载应如下所示:
```python
model = FastSentenceTransformer.from_pretrained(
"sentence-transformers/all-MiniLM-L6-v2",
for_inference=True,
)
```
对于 Hugging Face 授权,如果你运行:
```
hf auth login
```
并在调用 hub 方法之前在同一个虚拟环境中执行,那么:
* `push_to_hub()` 和 `push_to_hub_merged()` **不需要令牌参数**.
### ✅ 随处推理与部署!
你微调后的 Unsloth 模型可以使用并部署到所有主流工具中:transformers、LangChain、Weaviate、sentence-transformers、Text Embeddings Inference(TEI)、vLLM 和 llama.cpp、自定义嵌入 API、pgvector、FAISS/向量数据库,以及任何 RAG 框架。
不存在锁定,因为微调后的模型之后可以下载到你自己的设备上本地使用。
```python
# 1. 加载一个预训练的 Sentence Transformer 模型
model = SentenceTransformer("
下面是我们与以下方案对比的 Unsloth 热力图基准: `SentenceTransformers` + Flash Attention 2(FA2),用于 16bit LoRA。 **对于 16bit LoRA,Unsloth 快 1.2x 到 3.3x:**
### 🔮 模型支持
以下是 Unsloth 支持的一些流行嵌入模型(此处并未列出所有模型):
```
Alibaba-NLP/gte-modernbert-base
BAAI/bge-large-en-v1.5
BAAI/bge-m3
BAAI/bge-reranker-v2-m3
Qwen/Qwen3-Embedding-0.6B
answerdotai/ModernBERT-base
answerdotai/ModernBERT-large
google/embeddinggemma-300m
intfloat/e5-large-v2
intfloat/multilingual-e5-large-instruct
mixedbread-ai/mxbai-embed-large-v1
sentence-transformers/all-MiniLM-L6-v2
sentence-transformers/all-mpnet-base-v2
Snowflake/snowflake-arctic-embed-l-v2.0
```
大多数 [常见模型](https://huggingface.co/models?library=sentence-transformers) 已经支持。如果你想要的仅编码器模型还不在其中,欢迎提交一个 [GitHub issue](https://github.com/unslothai/unsloth/issues) 请求它。
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://unsloth.ai/docs/zh/ji-chu-zhi-shi/embedding-finetuning.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.