> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/zh/ji-chu-zhi-shi/dynamic-3.0-ggufs/unsloth-dynamic-ggufs-on-aider-polyglot.md).

# Aider Polyglot 上的 Unsloth Dynamic GGUF

Aider Polyglot 基准测试中 Unsloth Dynamic GGUF 的性能

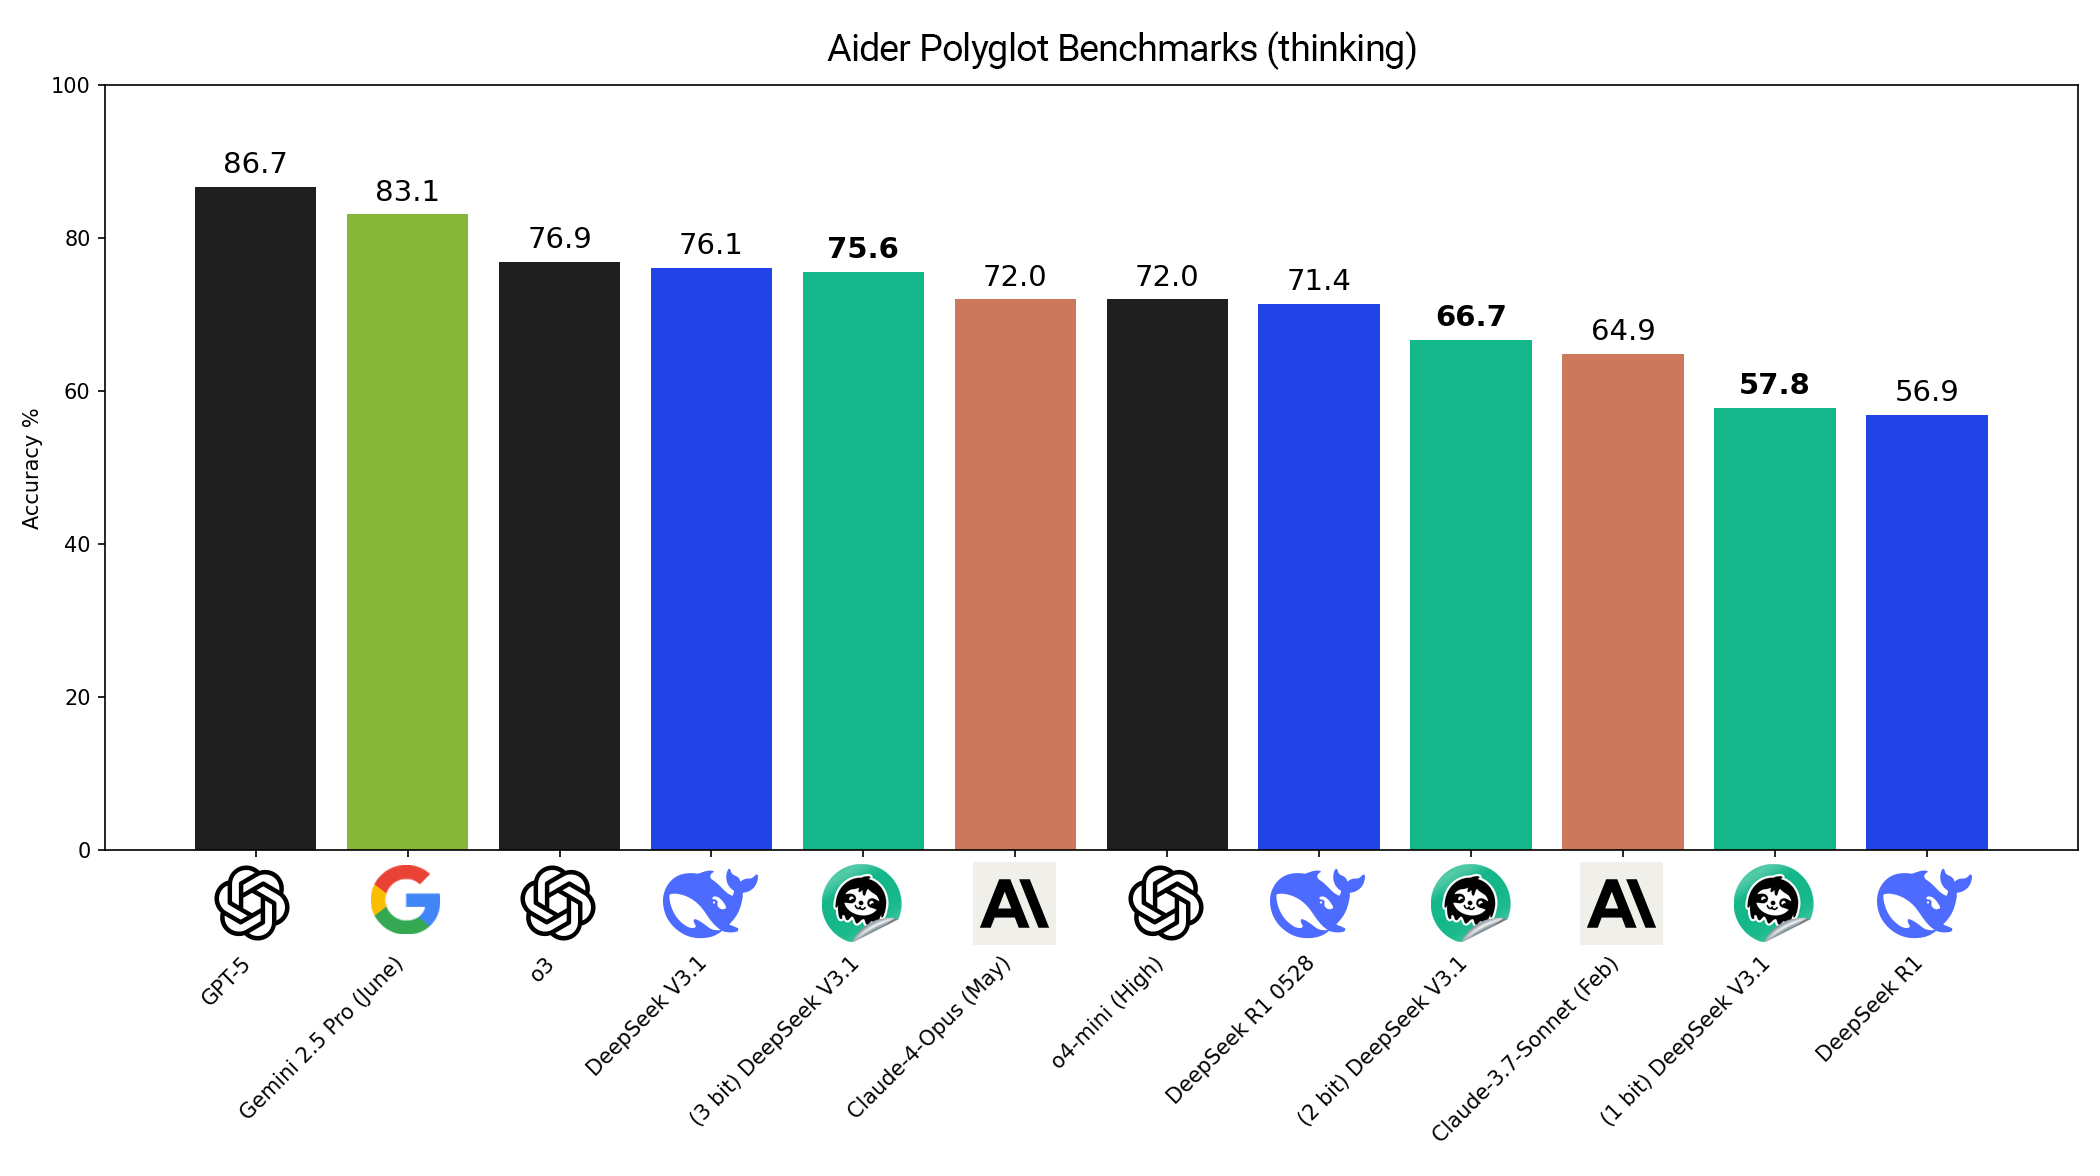
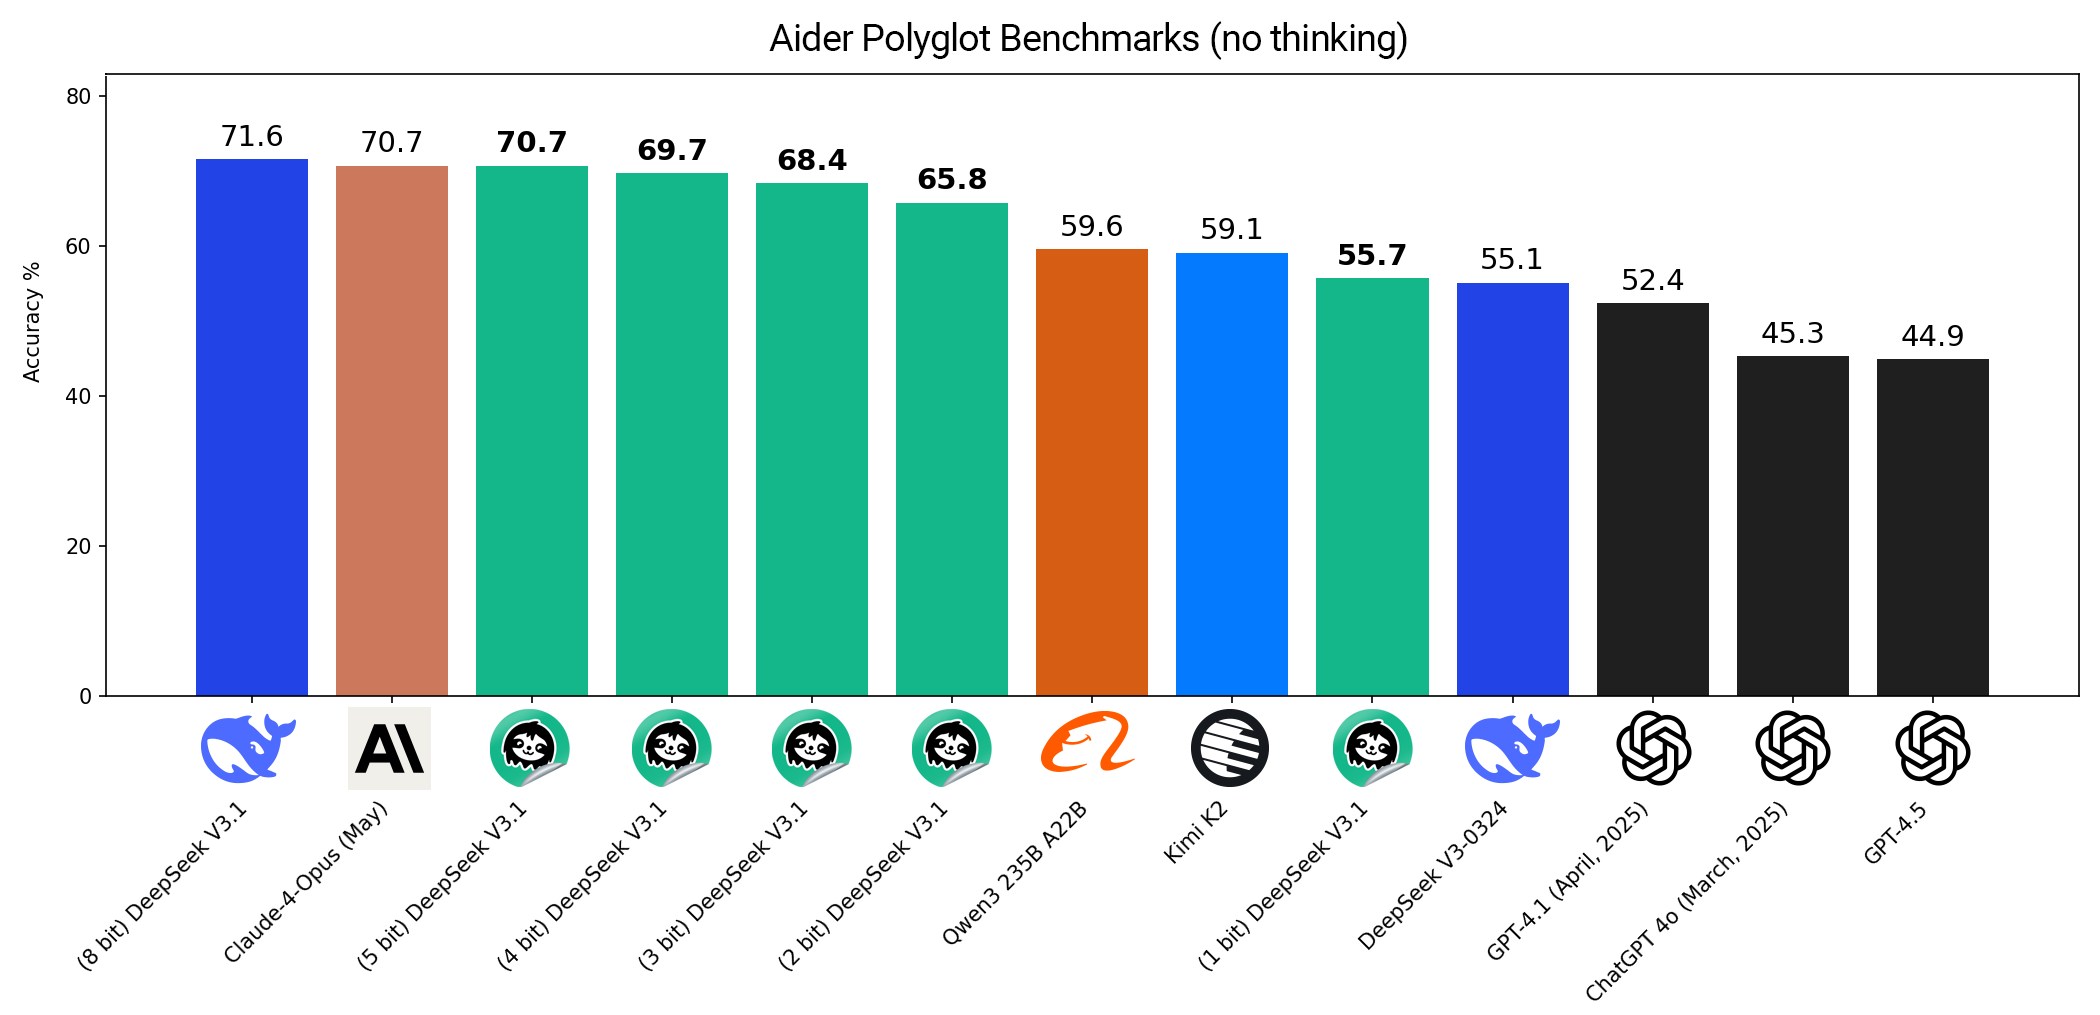
我们很高兴展示 Unsloth Dynamic GGUF 如何使量化诸如 [DeepSeek-V3.1](/docs/zh/mo-xing/tutorials/deepseek-v3.1-how-to-run-locally.md) (671B) 压缩到仅 **1-bit** 或 **3 位**，而且仍能胜过如下 SOTA 模型： **GPT-4.5, GPT-4.1** （2025年4月）以及 **Claude-4-Opus** （2025年5月）。

此前， [我们展示了](/docs/zh/ji-chu-zhi-shi/dynamic-3.0-ggufs.md) Unsloth Dynamic GGUF 如何在 5-shot MMLU 和 KL 散度上优于其他量化方法。现在，我们将通过以下基准展示它们在独立第三方评测中的表现： **Aider Polyglot** **基准。**

<div><figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-a114143bdd47add988182aabf9313ab40be38d7d%2Faider%20thinking.png?alt=media" alt="" width="563"><figcaption><p>带思考的 Aider 基准</p></figcaption></figure> <figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-b085c16c7f8351308229f1341846cbf1a2617d0a%2Faider%20non.png?alt=media" alt="" width="563"><figcaption><p>不带思考的 Aider 基准</p></figcaption></figure></div>

### ⭐**关键结果**

* 我们的 **1-bit** Unsloth Dynamic GGUF 将 DeepSeek-V3.1 从 **671GB → 192GB（体积减少 75%）** 且非思考模式显著优于 GPT-4.1（2025年4月）、GPT-4.5 和 DeepSeek-V3-0324。
* **3 位** Unsloth DeepSeek-V3.1（思考）GGUF：优于 Claude-4-Opus-20250514（思考）。
* **5-bit** Unsloth DeepSeek-V3.1（非思考）GGUF：性能与 Claude-4-Opus-20250514（非思考）相当。
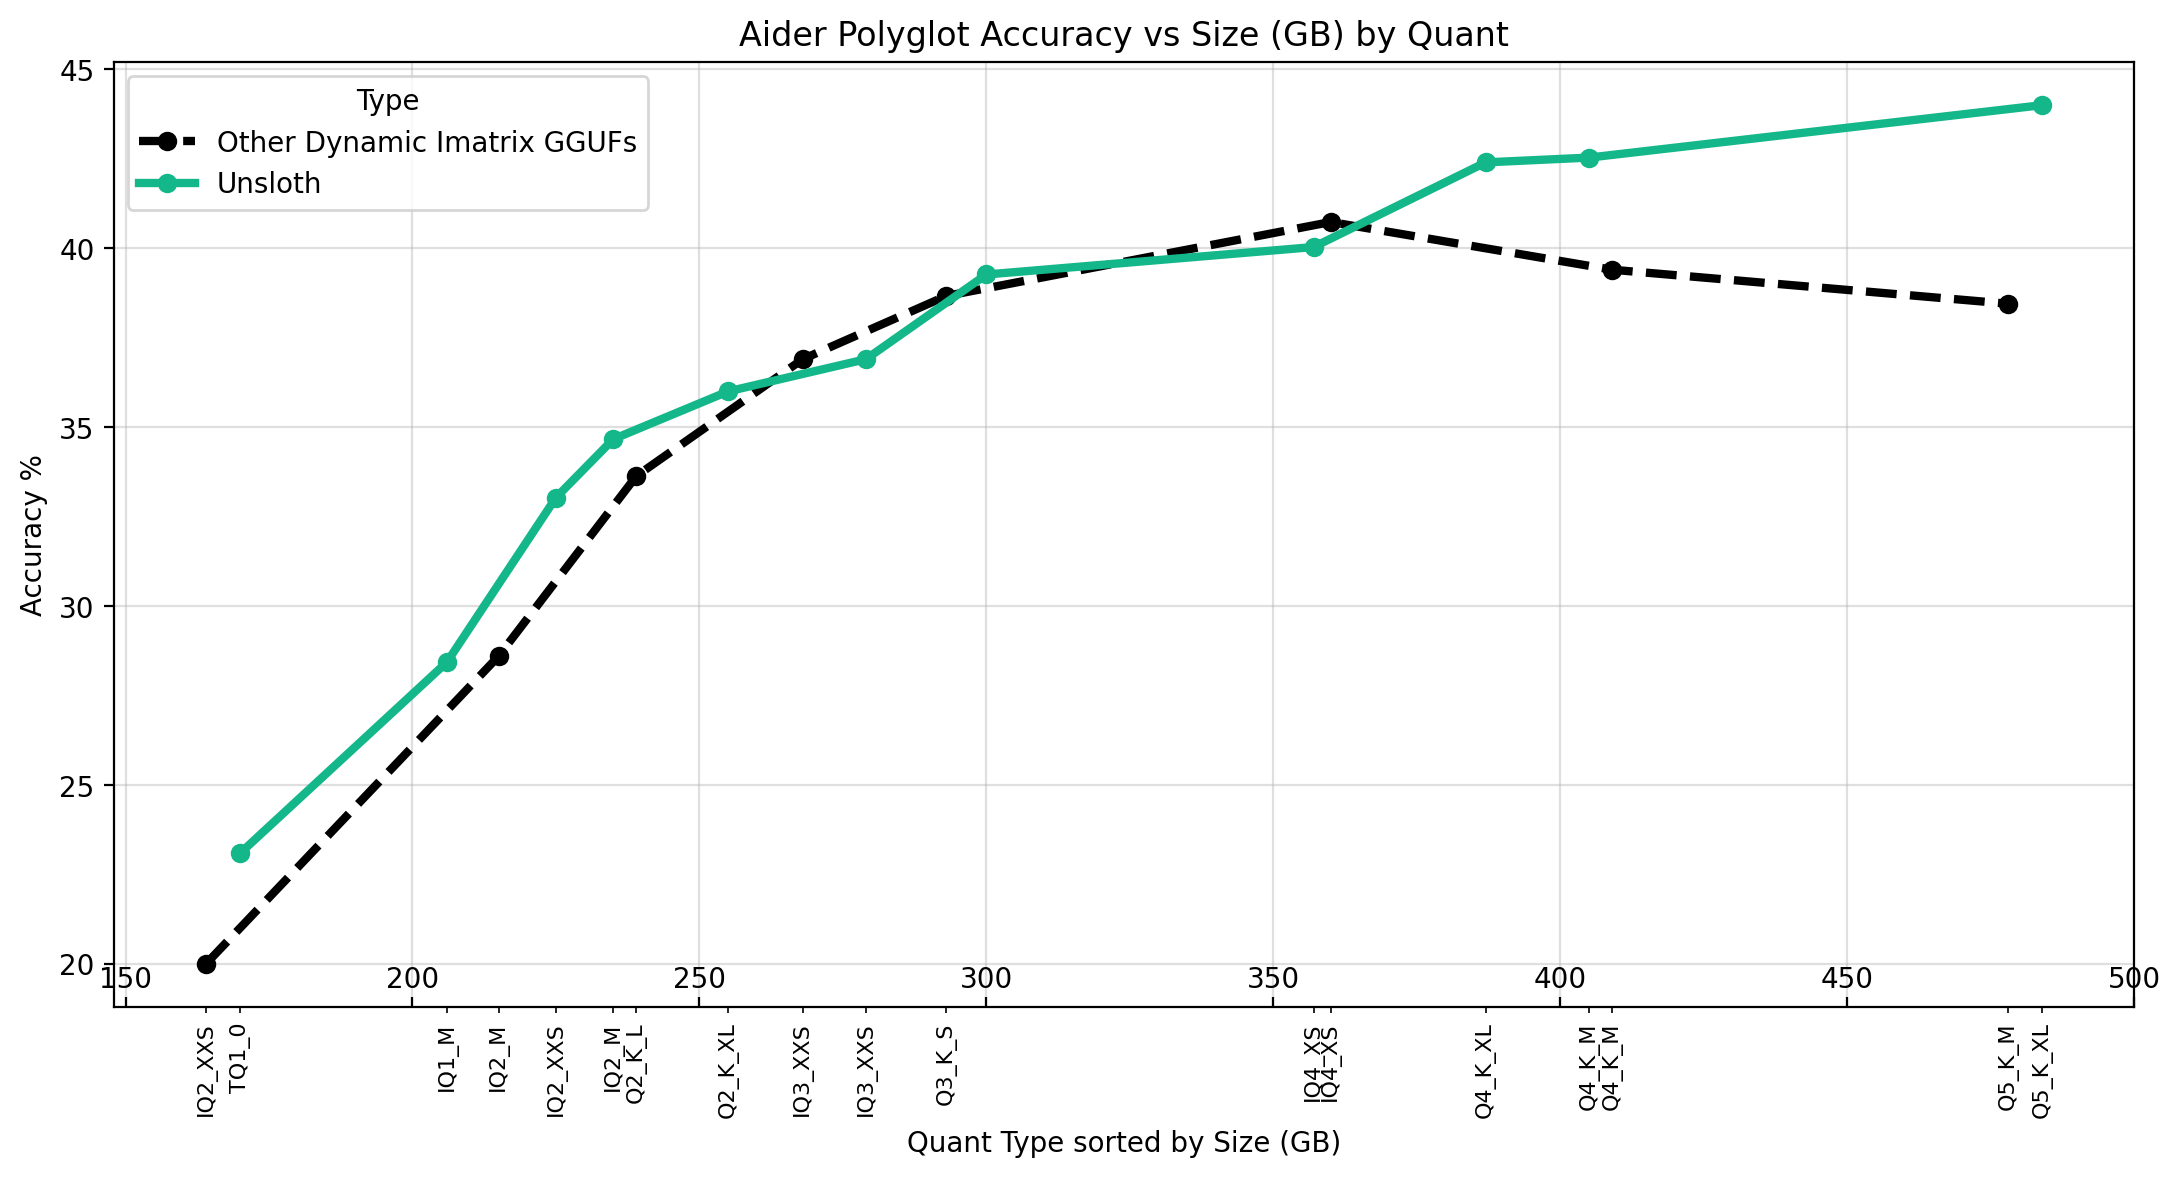
* Unsloth Dynamic GGUF 的表现始终优于其他非 Unsloth 的 Dynamic imatrix GGUF
* 其他非 Unsloth 的 1-bit 和 2-bit DeepSeek-V3.1 量化，以及未进行选择性层量化的标准 1-bit 量化，要么加载失败，要么输出胡言乱语并陷入循环。这凸显了 Unsloth Dynamic GGUF 能在很大程度上保留准确率，而其他方法甚至无法正常工作。

**为什么** [**Aider Polyglot**](https://aider.chat/docs/leaderboards/) **基准？** Aider 是衡量 LLM 在无需人工干预的情况下，写作、编程、遵循指令和应用修改能力最全面的指标之一，因此也是现实世界使用中最难、最有价值的基准之一。

{% hint style="success" %}
“ **关键优势** 使用 Unsloth 套件和模型的一个优势在于，我们积极参与 ***修复关键漏洞*** 在主流模型中的问题。我们已与以下团队直接合作： [Qwen3](https://www.reddit.com/r/LocalLLaMA/comments/1kaodxu/qwen3_unsloth_dynamic_ggufs_128k_context_bug_fixes/), [Meta（Llama 4）](https://github.com/ggml-org/llama.cpp/pull/12889), [Mistral（Devstral）](https://app.gitbook.com/o/HpyELzcNe0topgVLGCZY/s/xhOjnexMCB3dmuQFQ2Zq/~/changes/618/basics/tutorials-how-to-fine-tune-and-run-llms/devstral-how-to-run-and-fine-tune), [Google（Gemma 1–3）](https://news.ycombinator.com/item?id=39671146) 和 [Microsoft（Phi-3/4）](https://simonwillison.net/2025/Jan/11/phi-4-bug-fixes)，贡献了显著提升准确率的关键修复。
{% endhint %}

## 🦥Unsloth 动态量化

{% hint style="success" %}
**动态 1 bit 会将重要层保留为 8 或 16 bit，而将不重要层量化为 1、2、3、4、5 或 6 bit。**
{% endhint %}

在 2024 年 11 月，我们的 [4-bit 动态](https://unsloth.ai/blog/dynamic-4bit) 量化方案展示了，只需通过 <mark style="background-color:green;">**选择性量化层**</mark>，就可以在很大程度上恢复 QLoRA 微调和模型准确率。之后，我们研究了 [DeepSeek-R1](/docs/zh/mo-xing/tutorials/deepseek-r1-how-to-run-locally.md)的架构，并应用了类似的方法：将部分层量化到低至 1-bit，而将重要层量化到更高位宽（6、8-bit）。这一方法迅速流行起来，并已被证明对 MoE 模型尤其有效，使动态量化成为 MoE 量化的事实标准。

当我们的 Dynamic GGUF 与以下内容结合时，效果更佳： [imatrix 校准数据集](https://unsloth.ai/docs/zh/ji-chu-zhi-shi/dynamic-3.0-ggufs/pages/e658f01212ed739b6cc1648a22333767661730a1#whats-new-in-dynamic-v2.0)，专为聊天和编程性能设计。所有这些使得在不造成灾难性质量损失的情况下实现极端的 LLM 压缩成为可能。

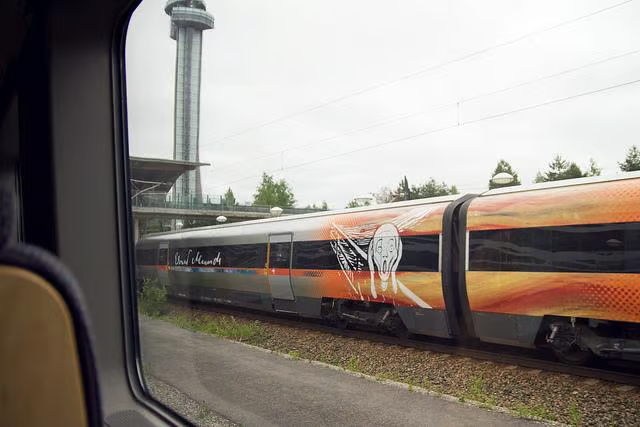
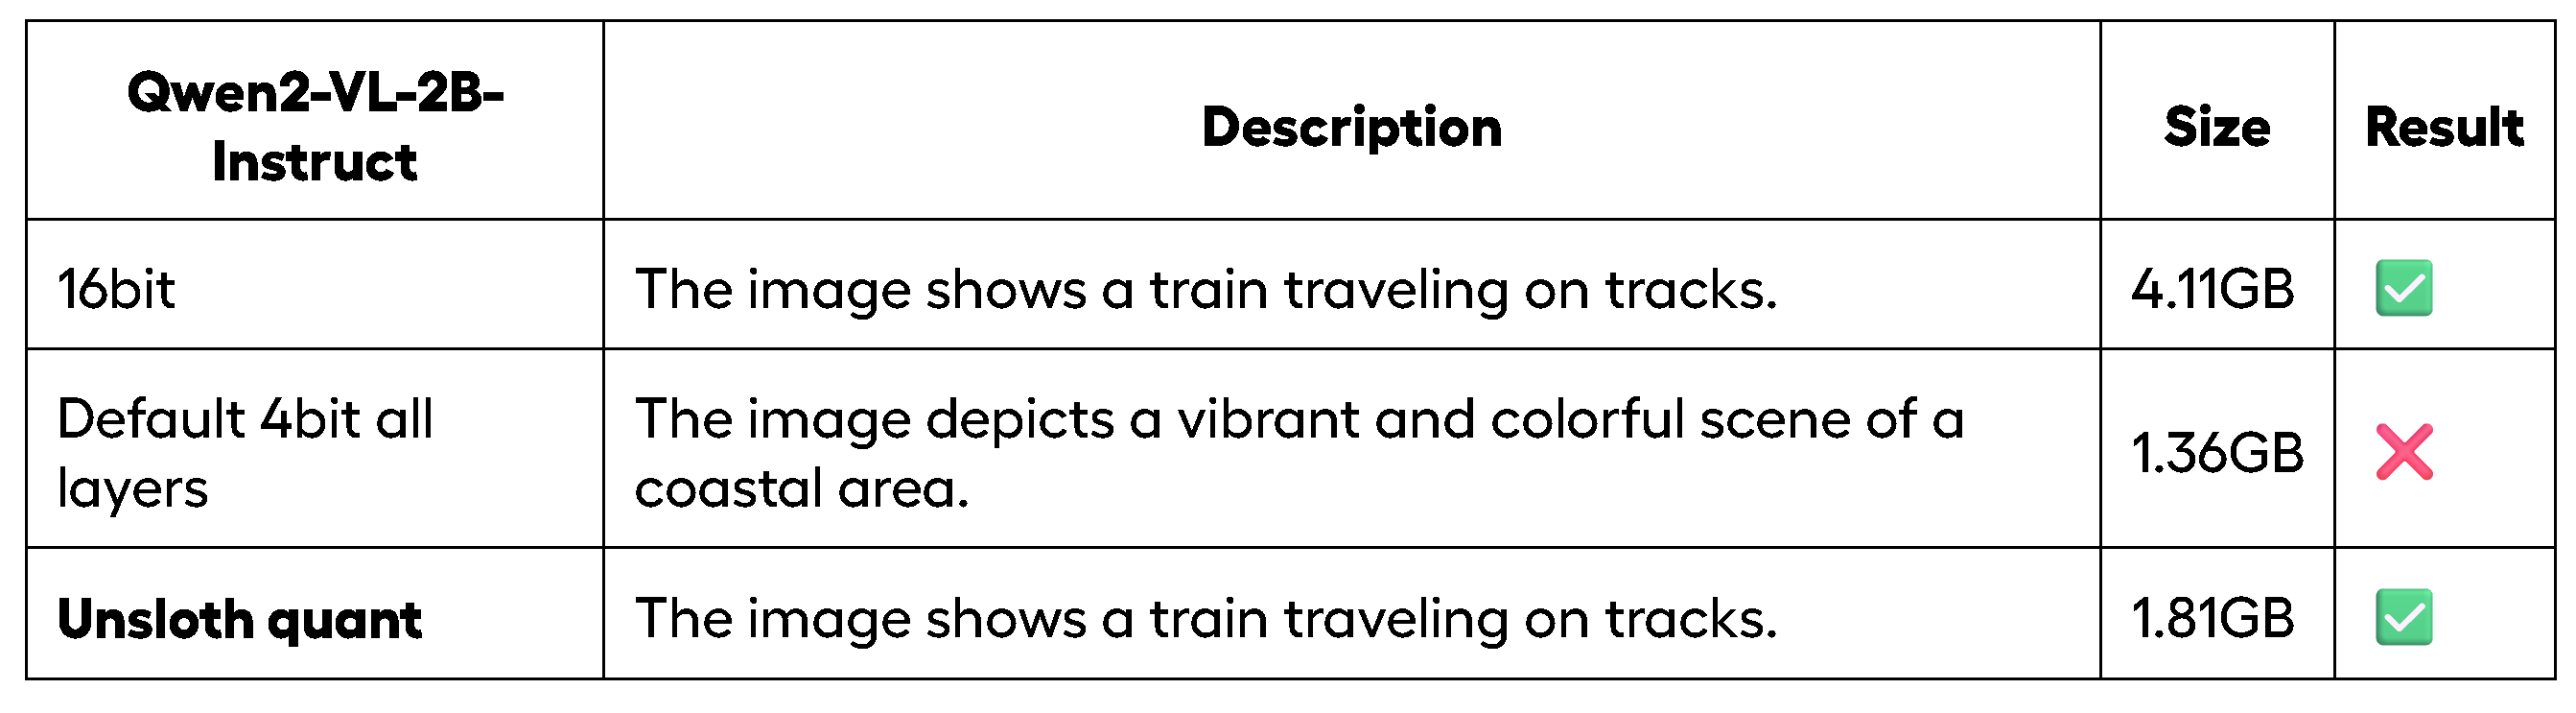
例如在 Qwen2-VL-2B-Instruct 中，若天真地将所有层都量化为 4bit，模型就无法理解下图。那是一列火车，不是海岸景色！

{% columns %}
{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-379bd5cc72a8f8e9acb4b6a6ad9fe847bf1ec296%2FTrain_NPovU814oJVjqy9Gu3BSm.avif?alt=media" alt=""><figcaption></figcaption></figure>
{% endcolumn %}

{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-38f5ea51c343a79bde7996d678761944f1dedaa7%2Fimage.png?alt=media" alt=""><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

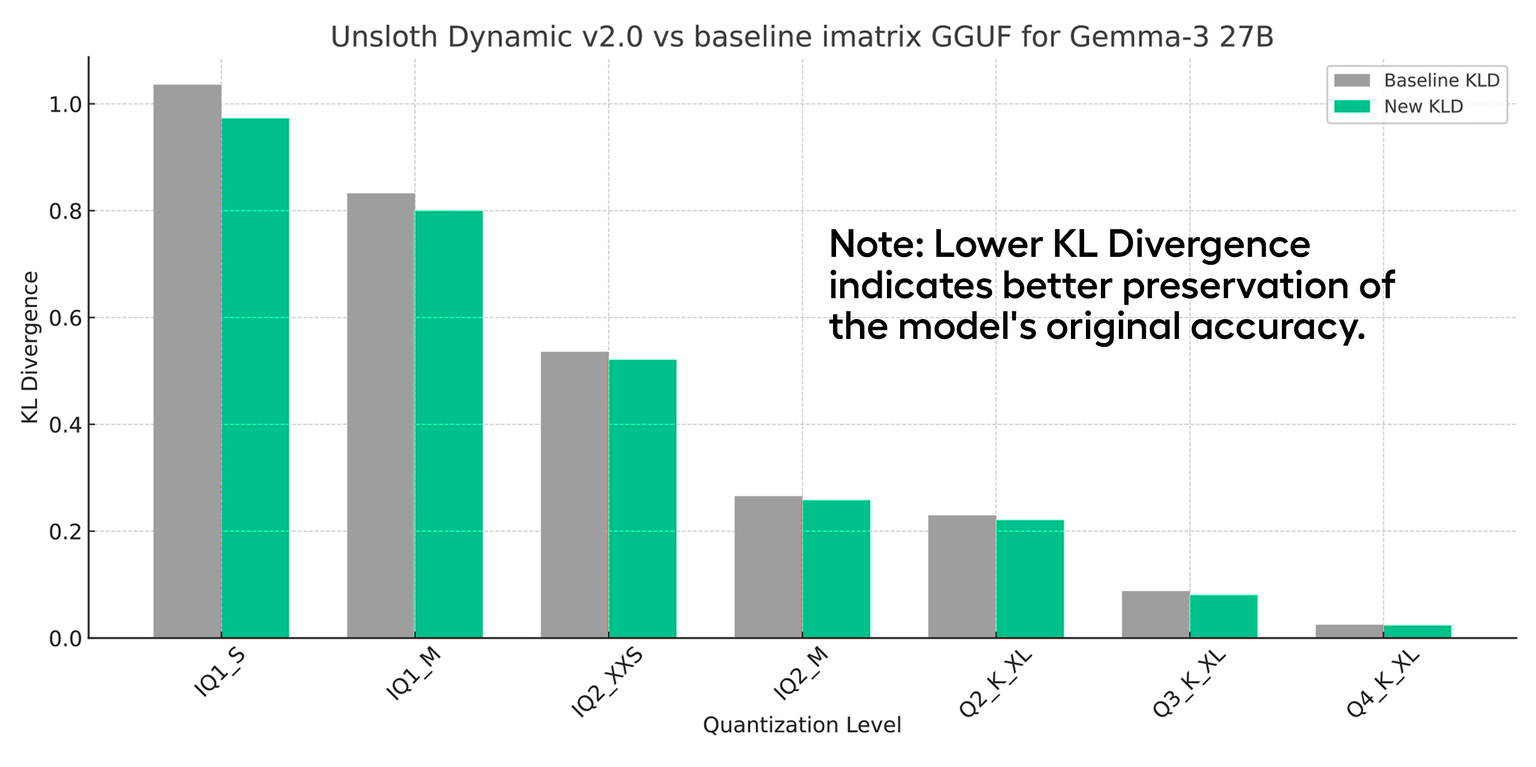
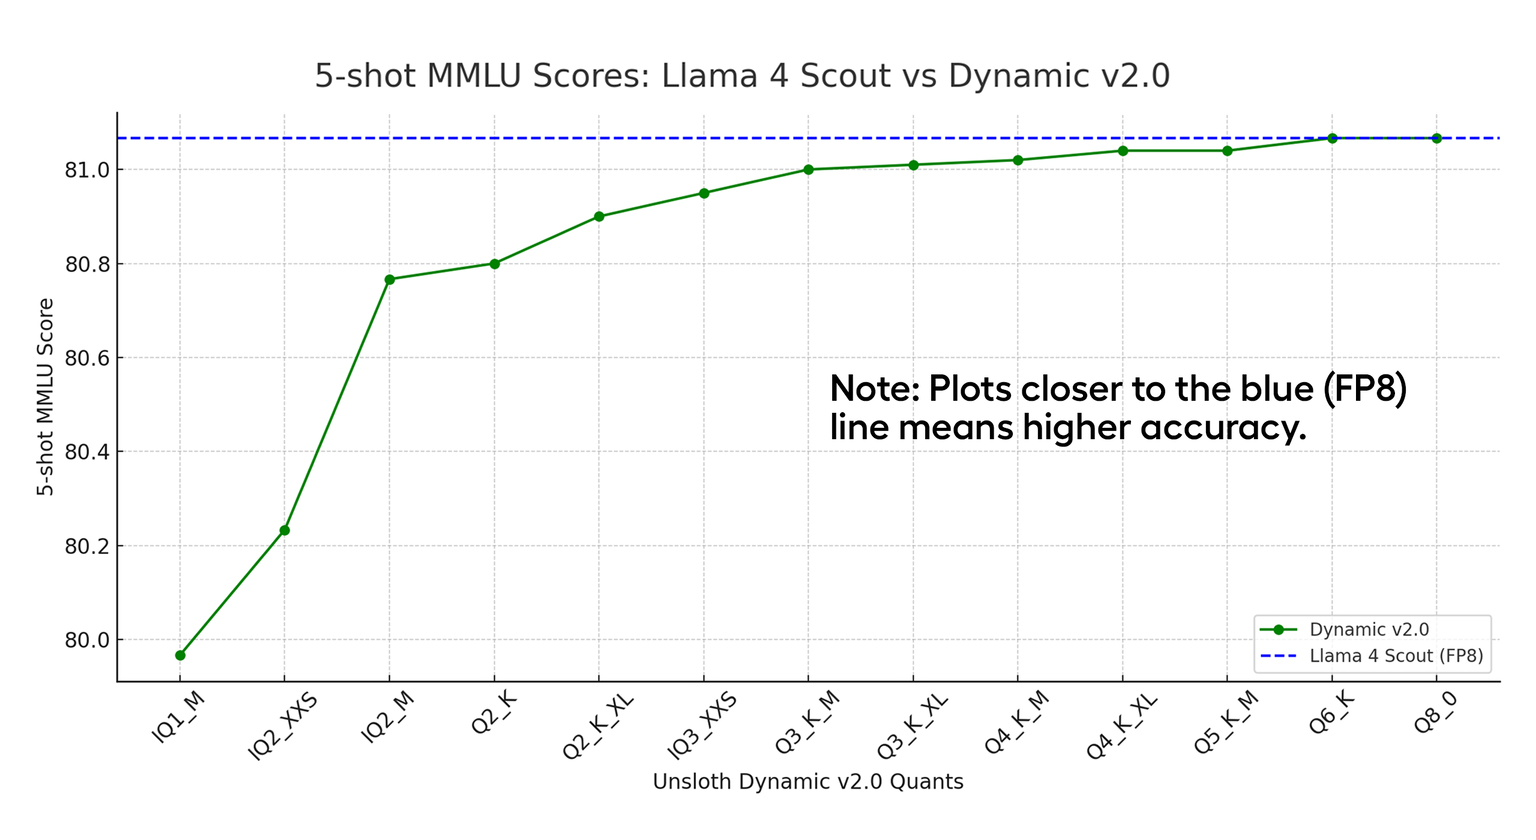
我们还在以下内容中展示了动态基准： <https://docs.unsloth.ai/basics/unsloth-dynamic-2.0-ggufs> 针对 Gemma 3 和 Llama 4 Scout，展示了我们的方法有多么有效：

{% columns %}
{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-28c5aa4355f5c09aef43217f2a02131aa6e3517f%2Fimage.avif?alt=media" alt=""><figcaption></figcaption></figure>
{% endcolumn %}

{% column %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-db47ebf519863f334f58c925dd6b39d0e01c359b%2Fimage.avif?alt=media" alt=""><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

### ⚙️ 基准设置

在 DeepSeek-V3.1 实验中，我们比较了不同位宽的 **Unsloth Dynamic GGUF** 与以下对象对比：

* **全精度、未量化的 LLM** 包括 GPT 4.5、4.1、Claude-4-Opus、DeepSeek-V3-0324 等。
* ***其他*****&#x20;动态 imatrix V3.1 GGUF**
* ***半-*****动态** （部分选择性层量化）imatrix V3.1 GGUF，用于 **消融实验**.

基准实验主要由 [David Sluys](https://www.linkedin.com/in/david-sluys-231348208/) （neolithic5452 在 [Aider Discord](https://discord.com/channels/1131200896827654144/1408293692074360914)），他是 Aider Polyglot 评测中值得信赖的社区贡献者。测试大约运行 3 次并取平均以得到中位数分数，且按照惯例报告 Pass-2 准确率。Aider 的 Discord 中还有一些可复现的基准代码片段。

<details>

<summary>展开查看推理模型 Aider 基准</summary>

| 模型                               | 准确率      |
| -------------------------------- | -------- |
| GPT-5                            | 86.7     |
| Gemini 2.5 Pro（6月）               | 83.1     |
| o3                               | 76.9     |
| DeepSeek V3.1                    | 76.1     |
| **（3 bit）DeepSeek V3.1 Unsloth** | **75.6** |
| Claude-4-Opus（5月）                | 72       |
| o4-mini（高）                       | 72       |
| DeepSeek R1 0528                 | 71.4     |
| **（2 bit）DeepSeek V3.1 Unsloth** | **66.7** |
| Claude-3.7-Sonnet（2月）            | 64.9     |
| **（1 bit）DeepSeek V3.1 Unsloth** | **57.8** |
| DeepSeek R1                      | 56.9     |

</details>

<details>

<summary>展开查看非推理模型 Aider 基准</summary>

| 模型                               | 准确率      |
| -------------------------------- | -------- |
| DeepSeek V3.1                    | 71.6     |
| Claude-4-Opus（5月）                | 70.7     |
| **（5 bit）DeepSeek V3.1 Unsloth** | **70.7** |
| **（4 bit）DeepSeek V3.1 Unsloth** | **69.7** |
| **（3 bit）DeepSeek V3.1 Unsloth** | **68.4** |
| **（2 bit）DeepSeek V3.1 Unsloth** | **65.8** |
| Qwen3 235B A22B                  | 59.6     |
| Kimi K2                          | 59.1     |
| **（1 bit）DeepSeek V3.1 Unsloth** | **55.7** |
| DeepSeek V3-0324                 | 55.1     |
| GPT-4.1（2025年4月）                 | 52.4     |
| ChatGPT 4o（2025年3月）              | 45.3     |
| GPT-4.5                          | 44.9     |

</details>

DeepSeek V3.1 既有推理模式也有非推理模式，我们都进行了测试。对于非推理模式，我们可以清楚地看到下面这些动态量化的表现趋势。动态 5-bit 在 Aider Pass-2 上达到 70.7%，而动态 1-bit 达到 55.7%。在体积和准确率方面，3 和 4bit 非常强大！

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-b085c16c7f8351308229f1341846cbf1a2617d0a%2Faider%20non.png?alt=media" alt=""><figcaption></figcaption></figure>

## :sparkler:与其他量化方案的比较

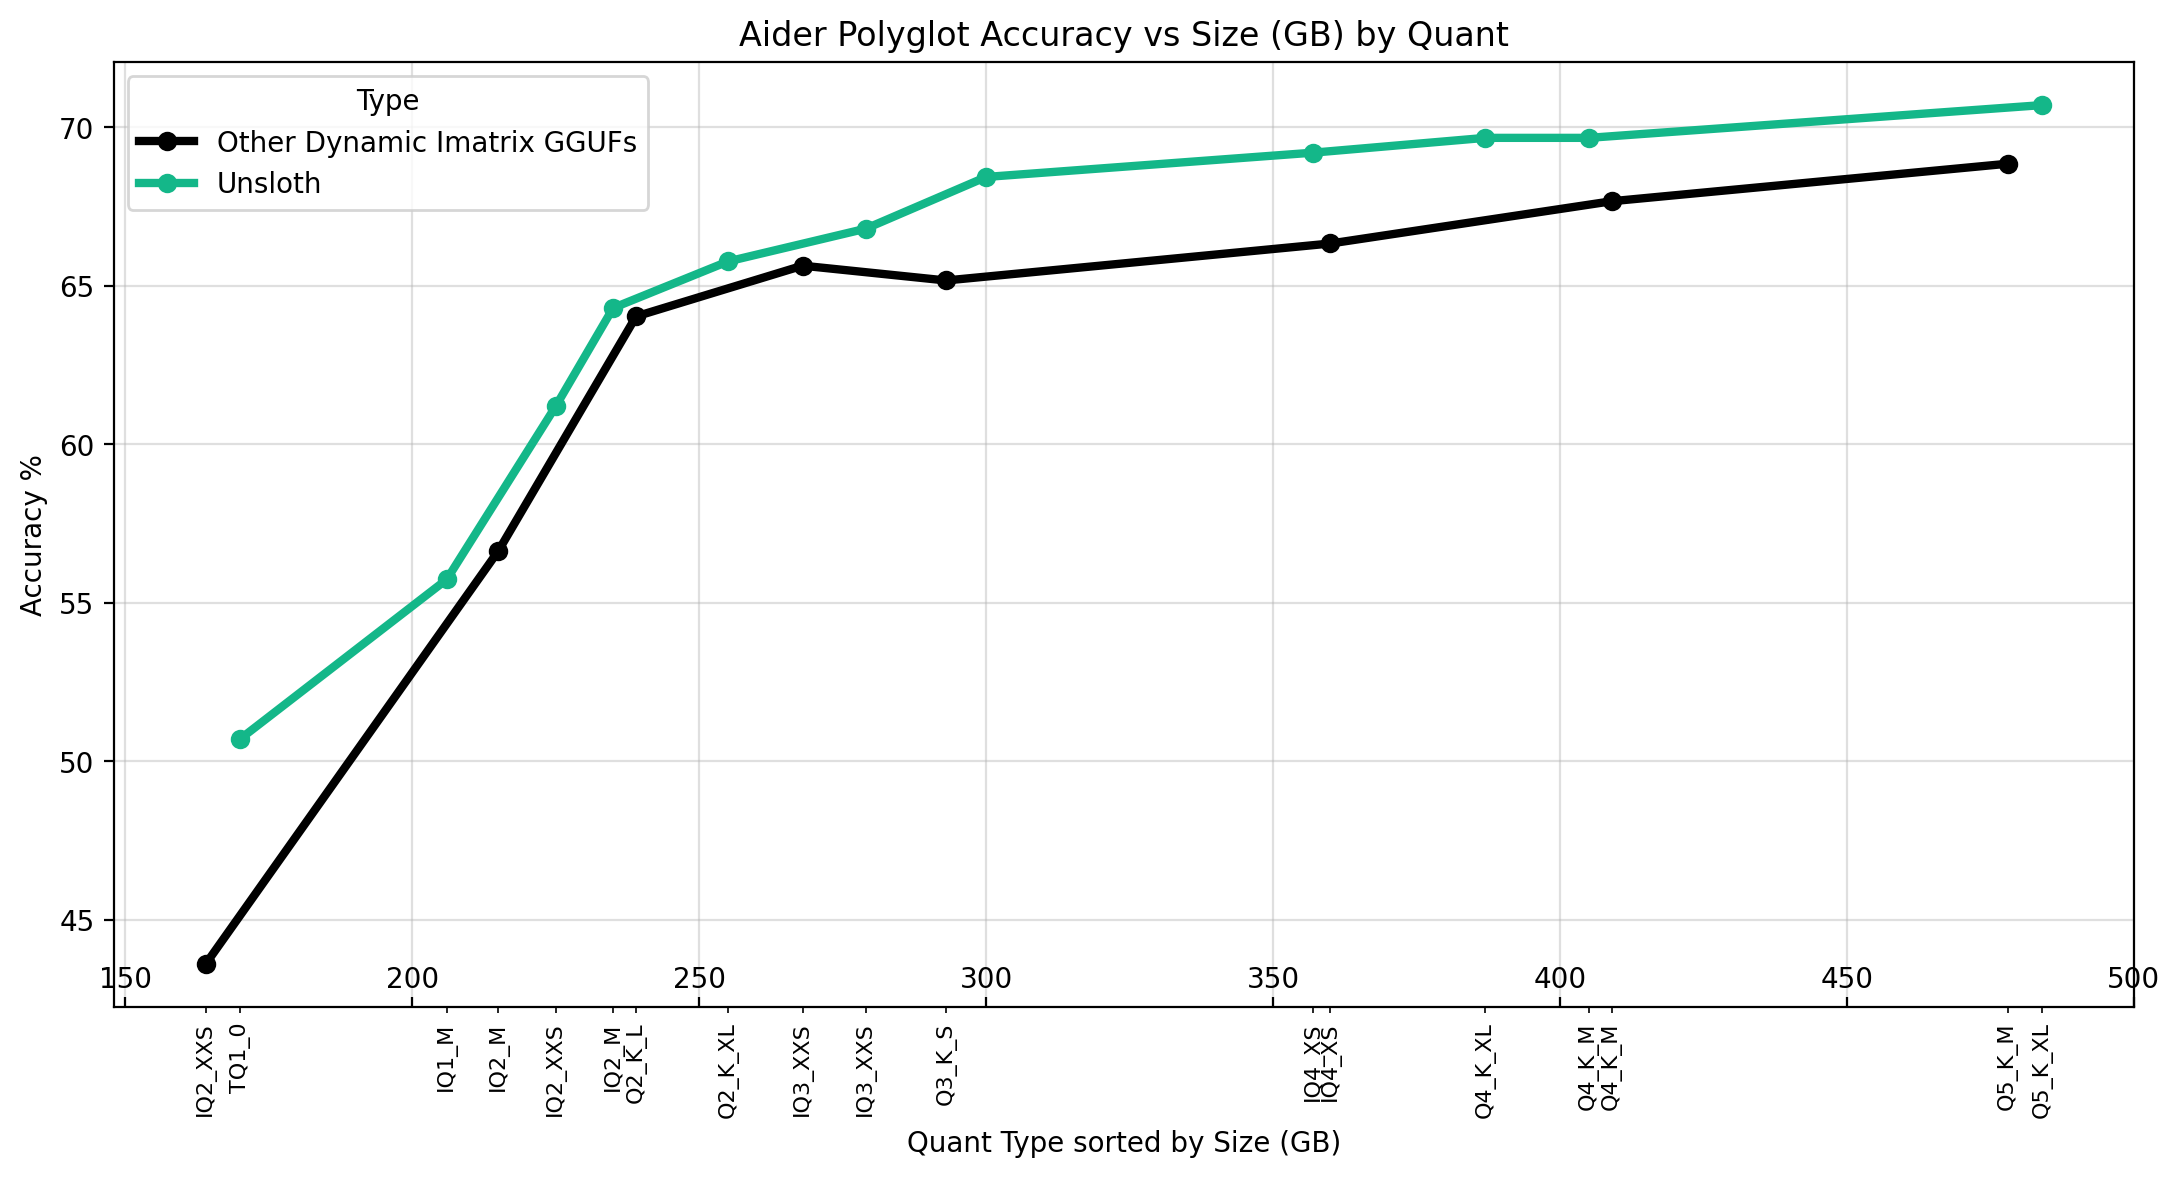
我们还在社区其他动态 imatrix GGUF 上运行 Aider Polyglot 基准，并与我们的结果进行比较。为确保 **公平比较**，我们采取以下做法：

1. 我们选择与每个 Unsloth 量化方案大小和位类型相近的文件。
2. 我们使用我们的 **固定聊天模板** 如果社区量化方案无法执行基准测试。我们发现一些社区量化方案 `{"code":500,"message":"split method must have between 1 and 1 positional arguments and between 0 and 0 keyword arguments at row 3, column 1908"}`，而使用我们的固定聊天模板即可修复这一问题。

与同模型大小和相同量化类型的其他社区量化方案相比，Unsloth 动态量化表现非常出色！

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-bbebbacfa75126d246c3ca1ed2ca269bc815b028%2FOther%20quants.png?alt=media" alt=""><figcaption></figcaption></figure>

<details>

<summary>展开查看与其他量化方案的原始数值对比</summary>

<table><thead><tr><th width="109.25">量化</th><th width="171.25006103515625">量化大小（GB）</th><th>Unsloth 准确率 %</th><th>对比准确率 %</th></tr></thead><tbody><tr><td>IQ2_XXS</td><td>164</td><td></td><td>43.6</td></tr><tr><td>TQ1_0</td><td>170</td><td>50.7</td><td></td></tr><tr><td>IQ1_M</td><td>206</td><td>55.7</td><td></td></tr><tr><td>IQ2_M</td><td>215</td><td></td><td>56.6</td></tr><tr><td>IQ2_XXS</td><td>225</td><td>61.2</td><td></td></tr><tr><td>IQ2_M</td><td>235</td><td>64.3</td><td></td></tr><tr><td>Q2_K_L</td><td>239</td><td></td><td>64.0</td></tr><tr><td>Q2_K_XL</td><td>255</td><td>65.8</td><td></td></tr><tr><td>IQ3_XXS</td><td>268</td><td>65.6</td><td>65.6</td></tr><tr><td>IQ3_XXS</td><td>279</td><td>66.8</td><td></td></tr><tr><td>Q3_K_S</td><td>293</td><td></td><td>65.2</td></tr><tr><td>Q3_K_XL</td><td>300</td><td>68.4</td><td></td></tr><tr><td>IQ4_XS</td><td>357</td><td>69.2</td><td></td></tr><tr><td>IQ4_XS</td><td>360</td><td></td><td>66.3</td></tr><tr><td>Q4_K_XL</td><td>387</td><td>69.7</td><td></td></tr><tr><td>Q4_K_M</td><td>405</td><td>69.7</td><td></td></tr><tr><td>Q4_K_M</td><td>409</td><td></td><td>67.7</td></tr><tr><td>Q5_K_M</td><td>478</td><td></td><td>68.9</td></tr><tr><td>Q5_K_XL</td><td>484</td><td>70.7</td><td></td></tr></tbody></table>

</details>

### :cake:动态量化消融实验

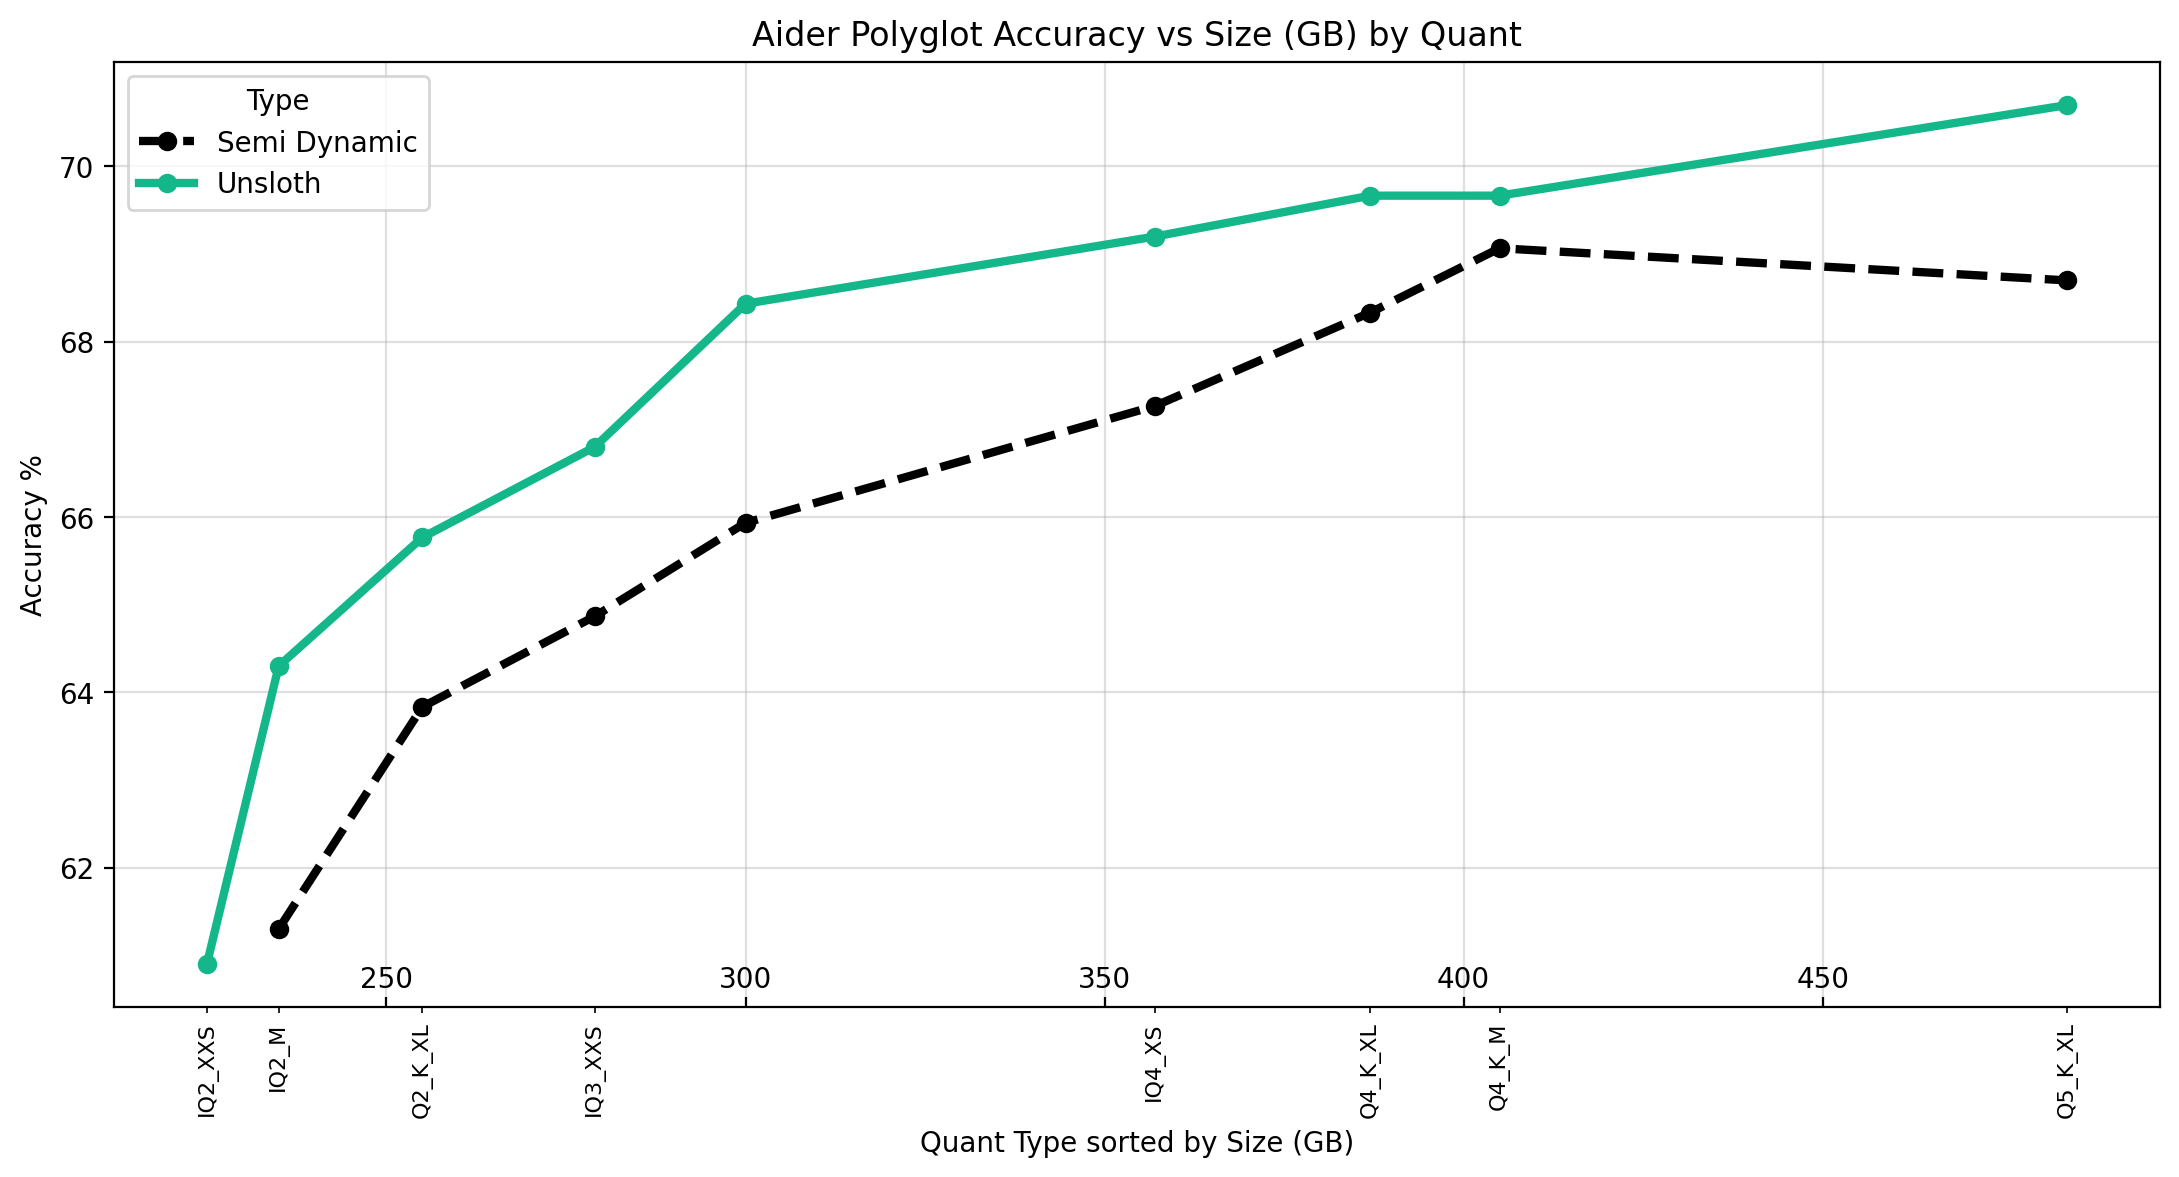
我们还做了一些消融实验，以确认我们的校准数据集和动态量化方法是否真正有效。Unsloth 动态方法的诀窍在于将 **重要层量化为更高位宽** 例如 8bits，而 **不重要层则保留为较低位宽，比如 2bits**.

为测试我们的方法，我们让特定张量保持较低精度，例如 4bit 对比更高精度。下面的例子中，我们保留 `attn_k_b` 张量为 4bit（半动态）而非 8bit（Unsloth 当前方案）；而量化大小仅增加约 100MB（<0.1%）时，准确率就会大幅提升！

{% hint style="success" %}
`attn_k_b` 而 DeepSeek V3.1 中的其他张量对量化非常重要/敏感，应保留更高精度以维持准确率！
{% endhint %}

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-3b4f8ac3af4ec8d09763c2e5f5d7de912d0b042e%2FSemi%20Dynamic.png?alt=media" alt=""><figcaption></figcaption></figure>

### :bug:聊天模板错误修复

在测试 DeepSeek-V3.1 量化方案时，我们发现一些低位宽量化方案没有正确包裹 `<think> </think>` ，或出现一些奇怪的格式。这导致某些社区量化方案在低位宽下无法工作，从而造成不公平比较。我们发现 llama.cpp 对 minja（一个更简单的 jinja 版本）的使用并不接受 `.split`中的位置参数。我们不得不将：

```
{%- set content = content.split("</think>", 1)[1] -%}
```

改为如下：

```
{%- set splitted = content.split("</think>") -%}
{%- set content = splitted[1:] | join("</think>") -%}
```

请看 [这里](https://huggingface.co/unsloth/DeepSeek-V3.1-GGUF?chat_template=default\&format=true) 用于我们的固定聊天模板，或者 [这里](https://huggingface.co/unsloth/DeepSeek-V3.1/raw/main/chat_template.jinja) 用于原始 jinja 文件。

### :bar\_chart:通过率 1

Aider 主要报告通过率 2。我们也报告通过率 1，以比较相同大小的社区量化方案。我们看到，我们的动态量化在与相近大小的其他社区量化方案相比时表现更好，尤其是在小于 2 bit 和大于 4 bits 的情况下。3 bit 和 4 bit 的表现也同样出色。

<figure><img src="https://2657992854-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fgit-blob-dfea83b4ef3e0d1a1c835476270eeb4f3f6db798%2FPass%20Rate%201%20Non%20Thinking.png?alt=media" alt=""><figcaption></figcaption></figure>

## :computer:运行 DeepSeek V3.1 动态量化

前往我们的 [DeepSeek V3.1 指南](/docs/zh/mo-xing/tutorials/deepseek-r1-how-to-run-locally/deepseek-r1-dynamic-1.58-bit.md) 或者要快速获取动态 2bit 版本，请执行：

```bash
apt-get update
apt-get install pciutils build-essential cmake curl libcurl4-openssl-dev -y
git clone https://github.com/ggml-org/llama.cpp
cmake llama.cpp -B llama.cpp/build \\
    -DBUILD_SHARED_LIBS=OFF -DGGML_CUDA=ON -DLLAMA_CURL=ON
cmake --build llama.cpp/build --config Release -j --clean-first --target llama-quantize llama-cli llama-gguf-split llama-mtmd-cli llama-server
cp llama.cpp/build/bin/llama-* llama.cpp
```

然后使用 `llama.cpp` 直接下载权重。我们也已设置好推荐的最优参数，如 temperature、聊天模板等：

```bash
export LLAMA_CACHE="unsloth/DeepSeek-V3.1-GGUF"
./llama.cpp/llama-cli \\
    -hf unsloth/DeepSeek-V3.1-GGUF:Q2_K_XL \\
    --jinja \\
    --n-gpu-layers 99 \
    --temp 0.6 \\
    --top-p 0.95 \\
    --min-p 0.01 \
    --ctx-size 8192 \
    --seed 3407 \
    -ot ".ffn_.*_exps.=CPU"
```


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://unsloth.ai/docs/zh/ji-chu-zhi-shi/dynamic-3.0-ggufs/unsloth-dynamic-ggufs-on-aider-polyglot.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.