> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/jp/moderu/qwen3.5/gguf-benchmarks.md).

# Qwen3.5 GGUFベンチマーク

Unsloth Dynamic GGUFの性能と、perplexity、KL divergence、MXFP4の分析をご覧ください。

すべてを更新しました [Qwen3.5](/docs/jp/moderu/qwen3.5.md) Unsloth Dynamic量子化版 **SOTAであること** ほぼすべてのビットで。合計で150回以上のKLダイバージェンスベンチマークを実施しました **9TBのGGUF**。研究成果物をすべてアップロードしました。

また、 **ツール呼び出し** チャットテンプレートの問題 **（どこで使っているか、どこ由来かにかかわらず、すべての量子化アップローダーと種類に影響します）**.

{% hint style="success" %}
[**3月5日更新**](#id-4-march-5th-2026-update-more-robustness)**:** Qwen3.5-を再ダウンロード**35B**, **27B,** **122B** そして **397B。**

* すべてのGGUFが現在、 **改良された量子化** アルゴリズムも導入されています。
* すべて、私たちの **新しいimatrixデータ**。チャット、コーディング、長文コンテキスト、ツール呼び出しのユースケースでいくつかの改善が見られます。

**新しいベンチマーク** Qwen3.5-122B-A10Bと35-A3Bの新しいベンチマークが公開されました！
{% endhint %}

{% hint style="info" %}
モデルの実行方法とハードウェア要件を知りたいですか？私たちの [推論ガイド](/docs/jp/moderu/qwen3.5.md).
{% endhint %}

**99.9% KLダイバージェンスでSOTAを示します** のパレートフロンティア上で [Unsloth Dynamic](/docs/jp/ji-chu/dynamic-3.0-ggufs.md) `Q4_K_XL`, `IQ3_XXS` など：

<div><figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F1XLNe1MoxtF1ODs5gDej%2F122b%20final.png?alt=media&amp;token=9eee5d8d-f16c-4c3f-8e36-18856e5609aa" alt="" width="563"><figcaption><p>Qwen3.5-<strong>122B-A10B</strong> ベンチマーク</p></figcaption></figure> <figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FAeecRAsAA3lxJ36HI8pO%2Fhoriztonal%20plot.png?alt=media&amp;token=173d4050-9442-4d2b-9f1b-ee8bd0d423df" alt="" width="563"><figcaption><p>Qwen3.5-<strong>35B-A3B</strong> ベンチマーク</p></figcaption></figure></div>

* ImatrixはKLDとPPLの削減に確実に役立ちますが、推論は5〜10%遅くなります。
* 私たちのGGUFを多くの他の提供元と比較してテストしました
* ssm\_out（Mamba層）を量子化するのは良い考えではなく、ffn\_down\_expsも同様です。
* **MXFP4の廃止** すべてのGGUF量子化から：純粋なMXFP4\_MOEを除くQ2\_K\_XL、Q3\_K\_XL、Q4\_K\_XL。

| [Qwen3.5-35B-A3B](https://huggingface.co/unsloth/Qwen3.5-35B-A3B-GGUF) | [Qwen3.5-27B](https://huggingface.co/unsloth/Qwen3.5-27B-GGUF) | [Qwen3.5-122B-A10B](https://huggingface.co/unsloth/Qwen3.5-122B-A10B-GGUF) | [Qwen3.5-397B-A17B](https://huggingface.co/unsloth/Qwen3.5-397B-A17B-GGUF) |
| ---------------------------------------------------------------------- | -------------------------------------------------------------- | -------------------------------------------------------------------------- | -------------------------------------------------------------------------- |

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FHq3gIokmPZJRYlnKVFmH%2FHCp7gV9XgAEP5og.png?alt=media&amp;token=a1268383-1648-45f8-996d-c89c7dde3706" alt="" width="563"><figcaption><p>Benjamin Marieによる新しいQwen3.5-9B GGUFベンチマーク</p></figcaption></figure>

### 1) **一部のテンソルは量子化に非常に敏感です**

* 9TB以上の研究成果物を、コミュニティがさらに調査できるように私たちの [実験ページ](https://huggingface.co/unsloth/Qwen3.5-35B-A3B-Experiments-GGUF)。KLD指標と、私たちがテストした121の設定すべてが含まれています。
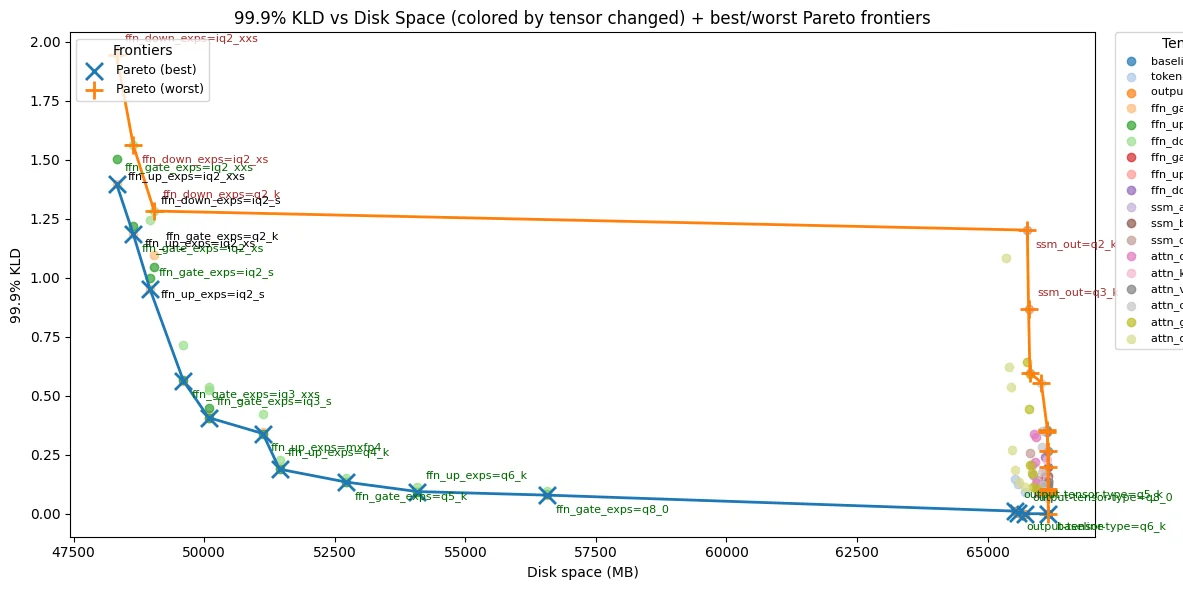
* 各テンソルタイプごとにビット幅を変え、以下に99.9% KLDとの最良・最悪のパレートフロンティア図を生成しました。
* 量子化に向いている項目では、ffn\_up\_expsとffn\_gate\_expsは一般に3bitまで量子化しても問題ありません。ffn\_down\_expsはやや敏感です。
* 最悪の項目では、ssm\_outはKLDを大幅に増やし、ディスク容量の節約はごくわずかです。たとえば、q2\_kのssm\_outは著しく悪化します。 **attn\_\*を量子化するのは特に敏感です** ハイブリッドアーキテクチャでは、より高い精度のままにしておくのがうまくいきます。

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F485gYwcqz2az5Pm9v3u3%2Fnew-qwen3-5-35b-a3b-unsloth-dynamic-ggufs-benchmarks-v0-pakdmbv1n2mg1.webp?alt=media&amp;token=2eeb55ca-51f3-402a-ae30-ea078c7554da" alt="" width="563"><figcaption></figcaption></figure>

{% columns %}
{% column %}
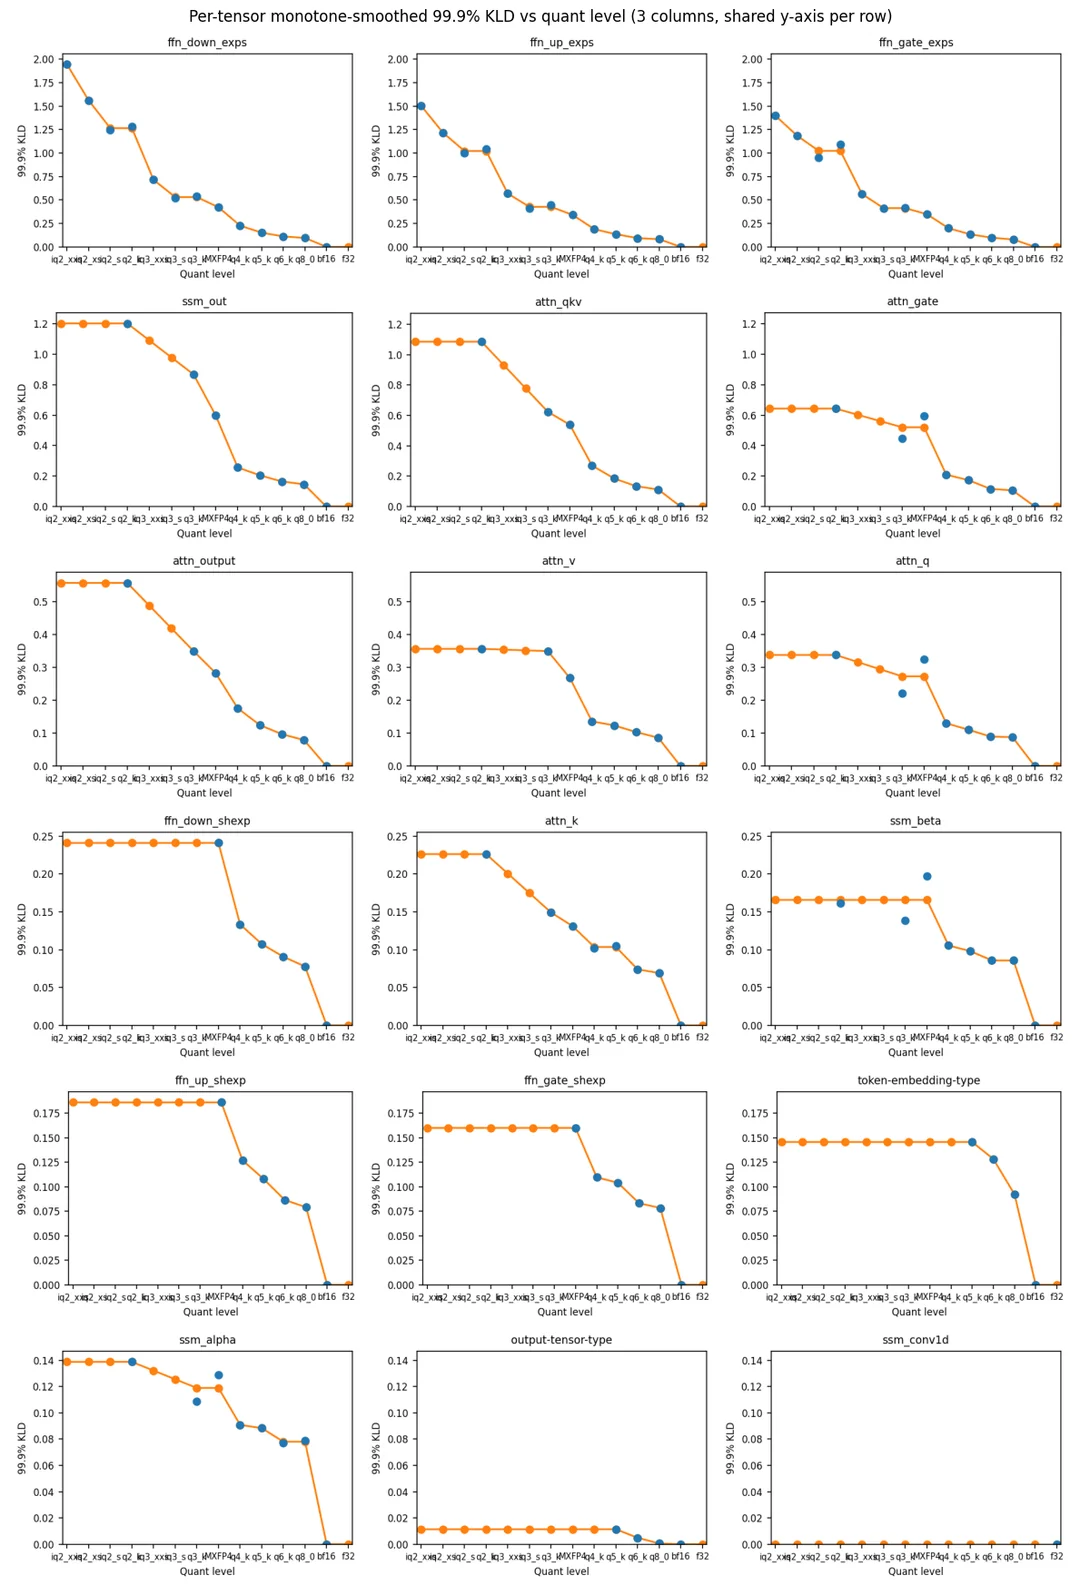
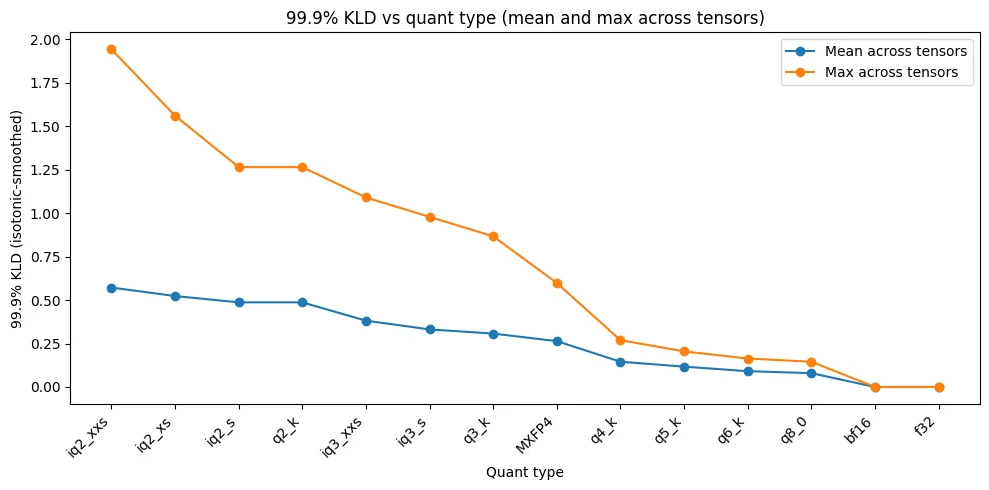
**99.9% KLダイバージェンスにおけるテンソルタイプ対ビット数**

* すべての量子化レベルを99.9% KLDに対してプロットし、KLDが最悪のものから最良のものへ並べています。ffn\_\*層を下げすぎて量子化するのは良くありません。
* ただし、 **いくつかのビット幅は良好で、特に3bitです**。例えば、ffn\_\*（down、up、gate）をiq3\_xxsあたりにしておくのが、ディスク容量と99.9% KLD変化の点で最良の妥協案のようです。2bitはさらに劣化を招きます。
  {% endcolumn %}

{% column %}

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FcE0WAmPVddczWC3dQsWS%2Fnew-qwen3-5-35b-a3b-unsloth-dynamic-ggufs-benchmarks-v0-squz1jz4n2mg1.webp?alt=media&amp;token=3a31adf1-7c4c-446c-91a7-48e63d223189" alt="" width="188"><figcaption></figcaption></figure>
{% endcolumn %}
{% endcolumns %}

**MXFP4は多くのテンソルでかなり悪いです** — attn\_gate、attn\_q、ssm\_beta、ssm\_alphaでMXFP4を使うのは良い考えではなく、むしろQ4\_Kのほうが良いです。なお、MXFP4は重み1つあたり4.25ビットを使うのに対し、Q4\_Kは重み1つあたり4.5ビットを使います。どちらかを選ぶなら、MXFP4よりQ4\_Kを使うほうがよいです。

<div><figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FH8FliHXsetx9lLoKelPX%2Fnew-qwen3-5-35b-a3b-unsloth-dynamic-ggufs-benchmarks-v0-xgugdgzmv2mg1.webp?alt=media&amp;token=f0c49e94-571e-4883-84fe-2c4634d425eb" alt="" width="563"><figcaption></figcaption></figure> <figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FEWsX87d1Ig42Uk81fpJo%2Ffixed%20the%20grapg.png?alt=media&amp;token=323932fd-8344-4f6c-b8c3-47cc1b1f6ccf" alt="" width="563"><figcaption><p>ご覧のとおり、MXFP4は異常に高いです</p></figcaption></figure></div>

### **2) Imatrixは非常にうまく機能します**

* Imatrixは量子化プロセスに正しい重み付けをするのに確実に役立ちます。たとえば、以前は2bitのssm\_outが本当にひどかったのですが、imatrixは99.9% KLDを大幅に下げます。
* Imatrixは一般に低ビットで役立ち、すべての量子化方式とビット幅で機能します。
*

```
<figure><img src="/files/067aa9798a42bea61251cf26b16cd5b68420fc40" alt=""><figcaption></figcaption></figure>
```

I量子化（iq3\_xxs、iq2\_sなど）は推論を5〜10%遅くします。効率の面では確かに優れていますが、トレードオフがあります。

| 型        | pp512（≈） | tg128（≈） |
| -------- | -------- | -------- |
| mxfp4    | 1978.69  | 90.67    |
| q4\_k    | 1976.44  | 90.38    |
| q3\_k    | 1972.61  | 91.36    |
| q6\_k    | 1964.55  | 90.50    |
| q2\_k    | 1964.20  | 90.77    |
| q8\_0    | 1964.17  | 90.33    |
| q5\_k    | 1947.74  | 90.72    |
| iq3\_xxs | 2030.94  | 85.68    |
| iq2\_xxs | 1997.64  | 85.79    |
| iq3\_s   | 1990.12  | 84.37    |
| iq2\_xs  | 1967.85  | 85.19    |
| iq2\_s   | 1952.50  | 85.04    |

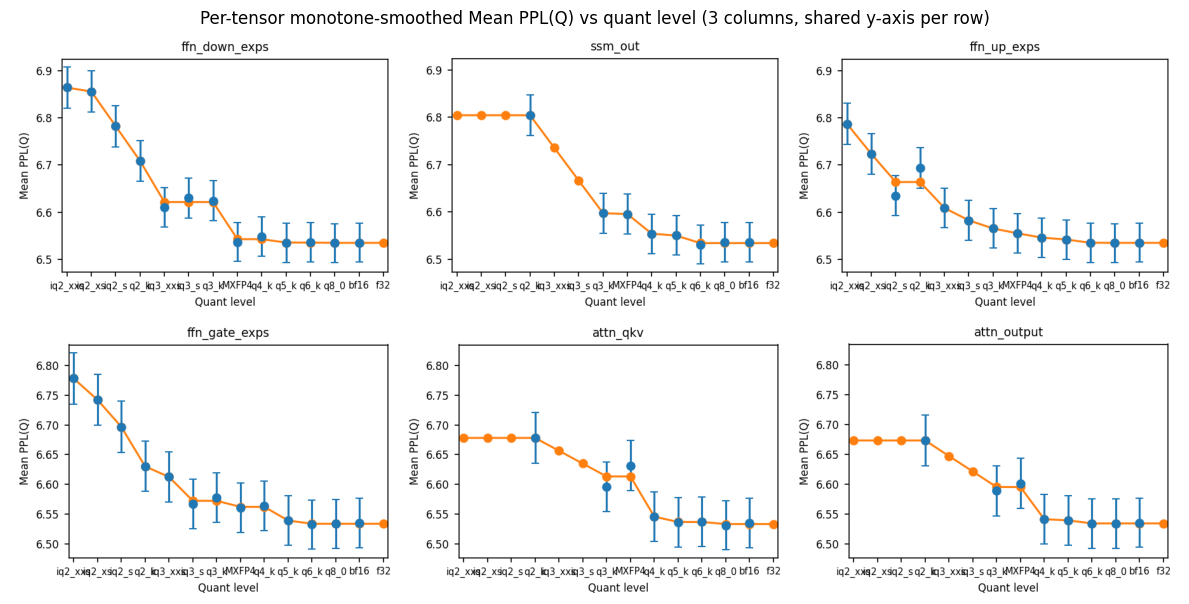
### **3) パープレキシティとKLDは誤解を招くことがあります**

パープレキシティとKLDは、キャリブレーションの影響を強く受けるため、誤解を招くことがあります。ほとんどのGGUFは512コンテキストウィンドウのWiki-testで評価されるため、GGUFのimatrixキャリブレーションセットにWikipedia風の512コンテキストサンプルが含まれていると、結果は大きく変わります（多くのGGUFがそうです）。そのため、私たちのGGUFは、imatrixデータとして代わりに長文コンテキストのチャットやツール呼び出しの例を使っているので、パープレキシティが高く出ることがあります。

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FhfO2gsbz2lWrZXg3ojyE%2FHCGBTzgboAASv_A.png?alt=media&amp;token=7d6334ca-4f3c-4946-aacd-d55527375fce" alt="" width="563"><figcaption></figcaption></figure>

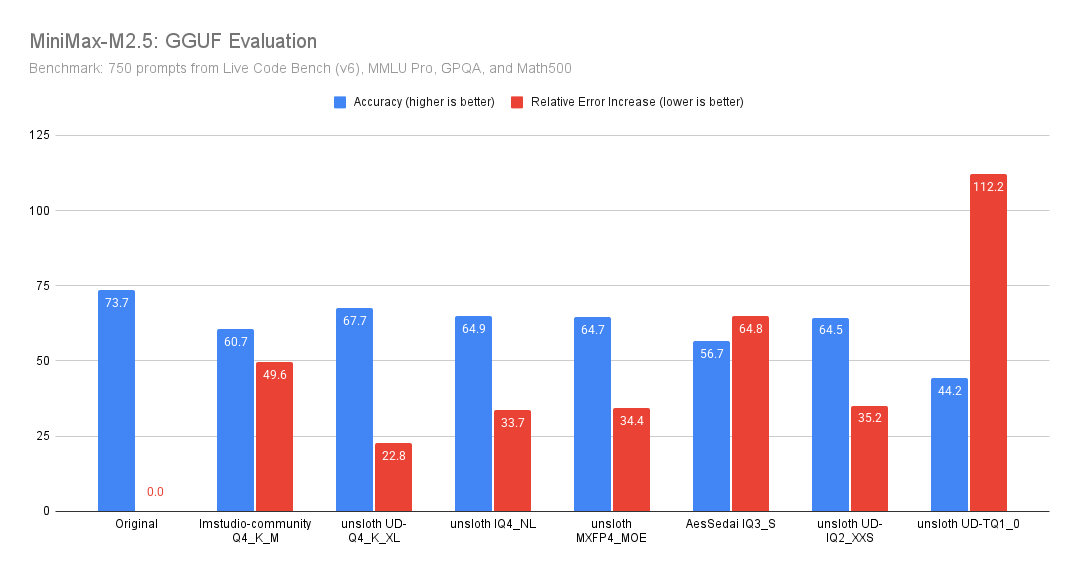
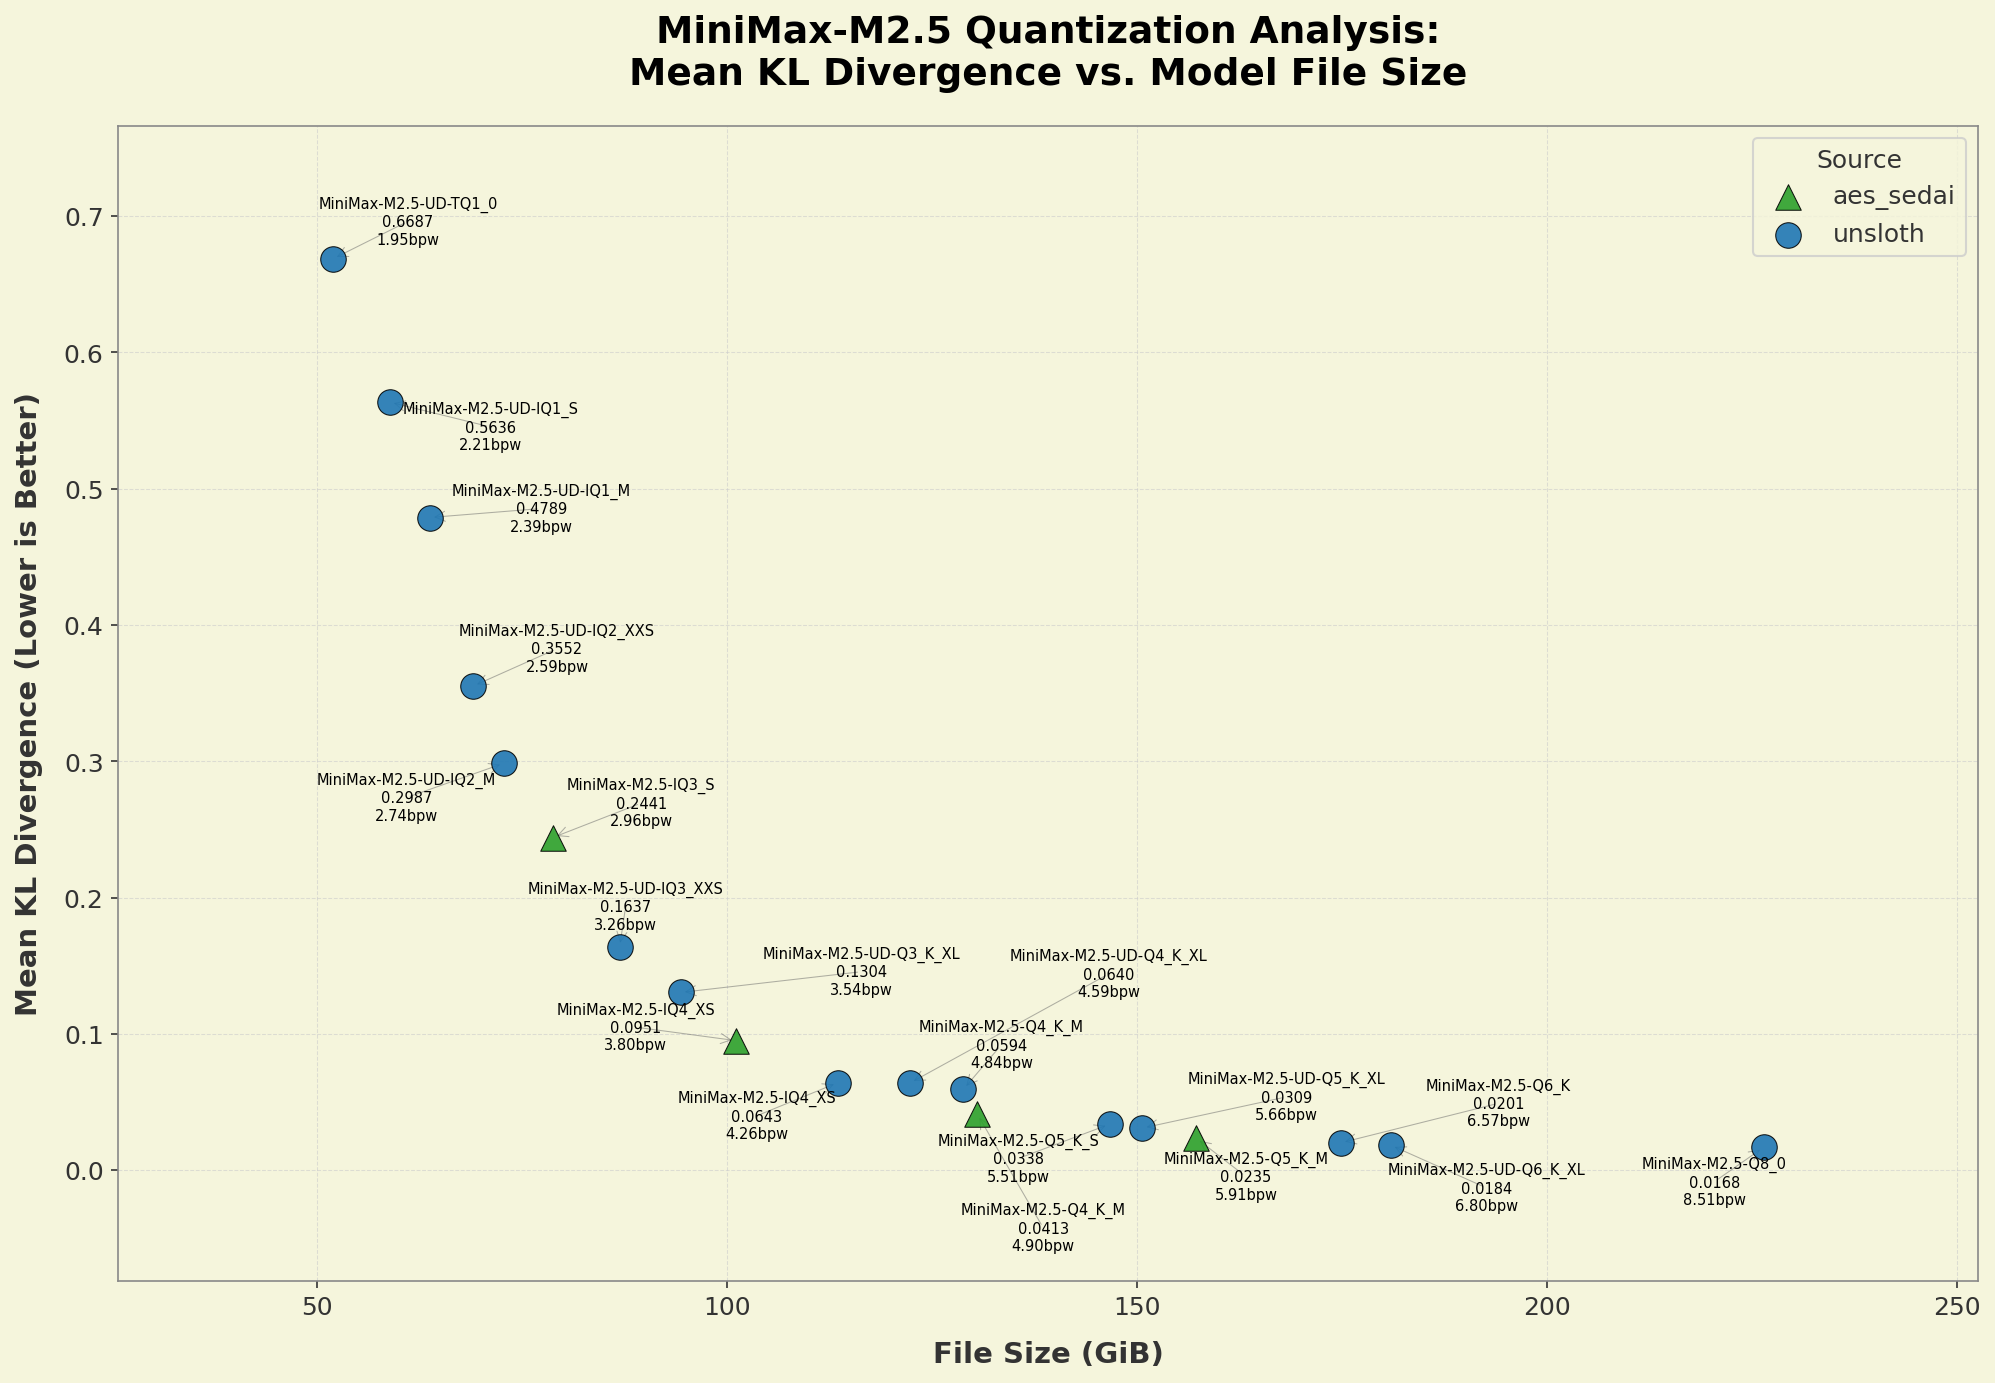
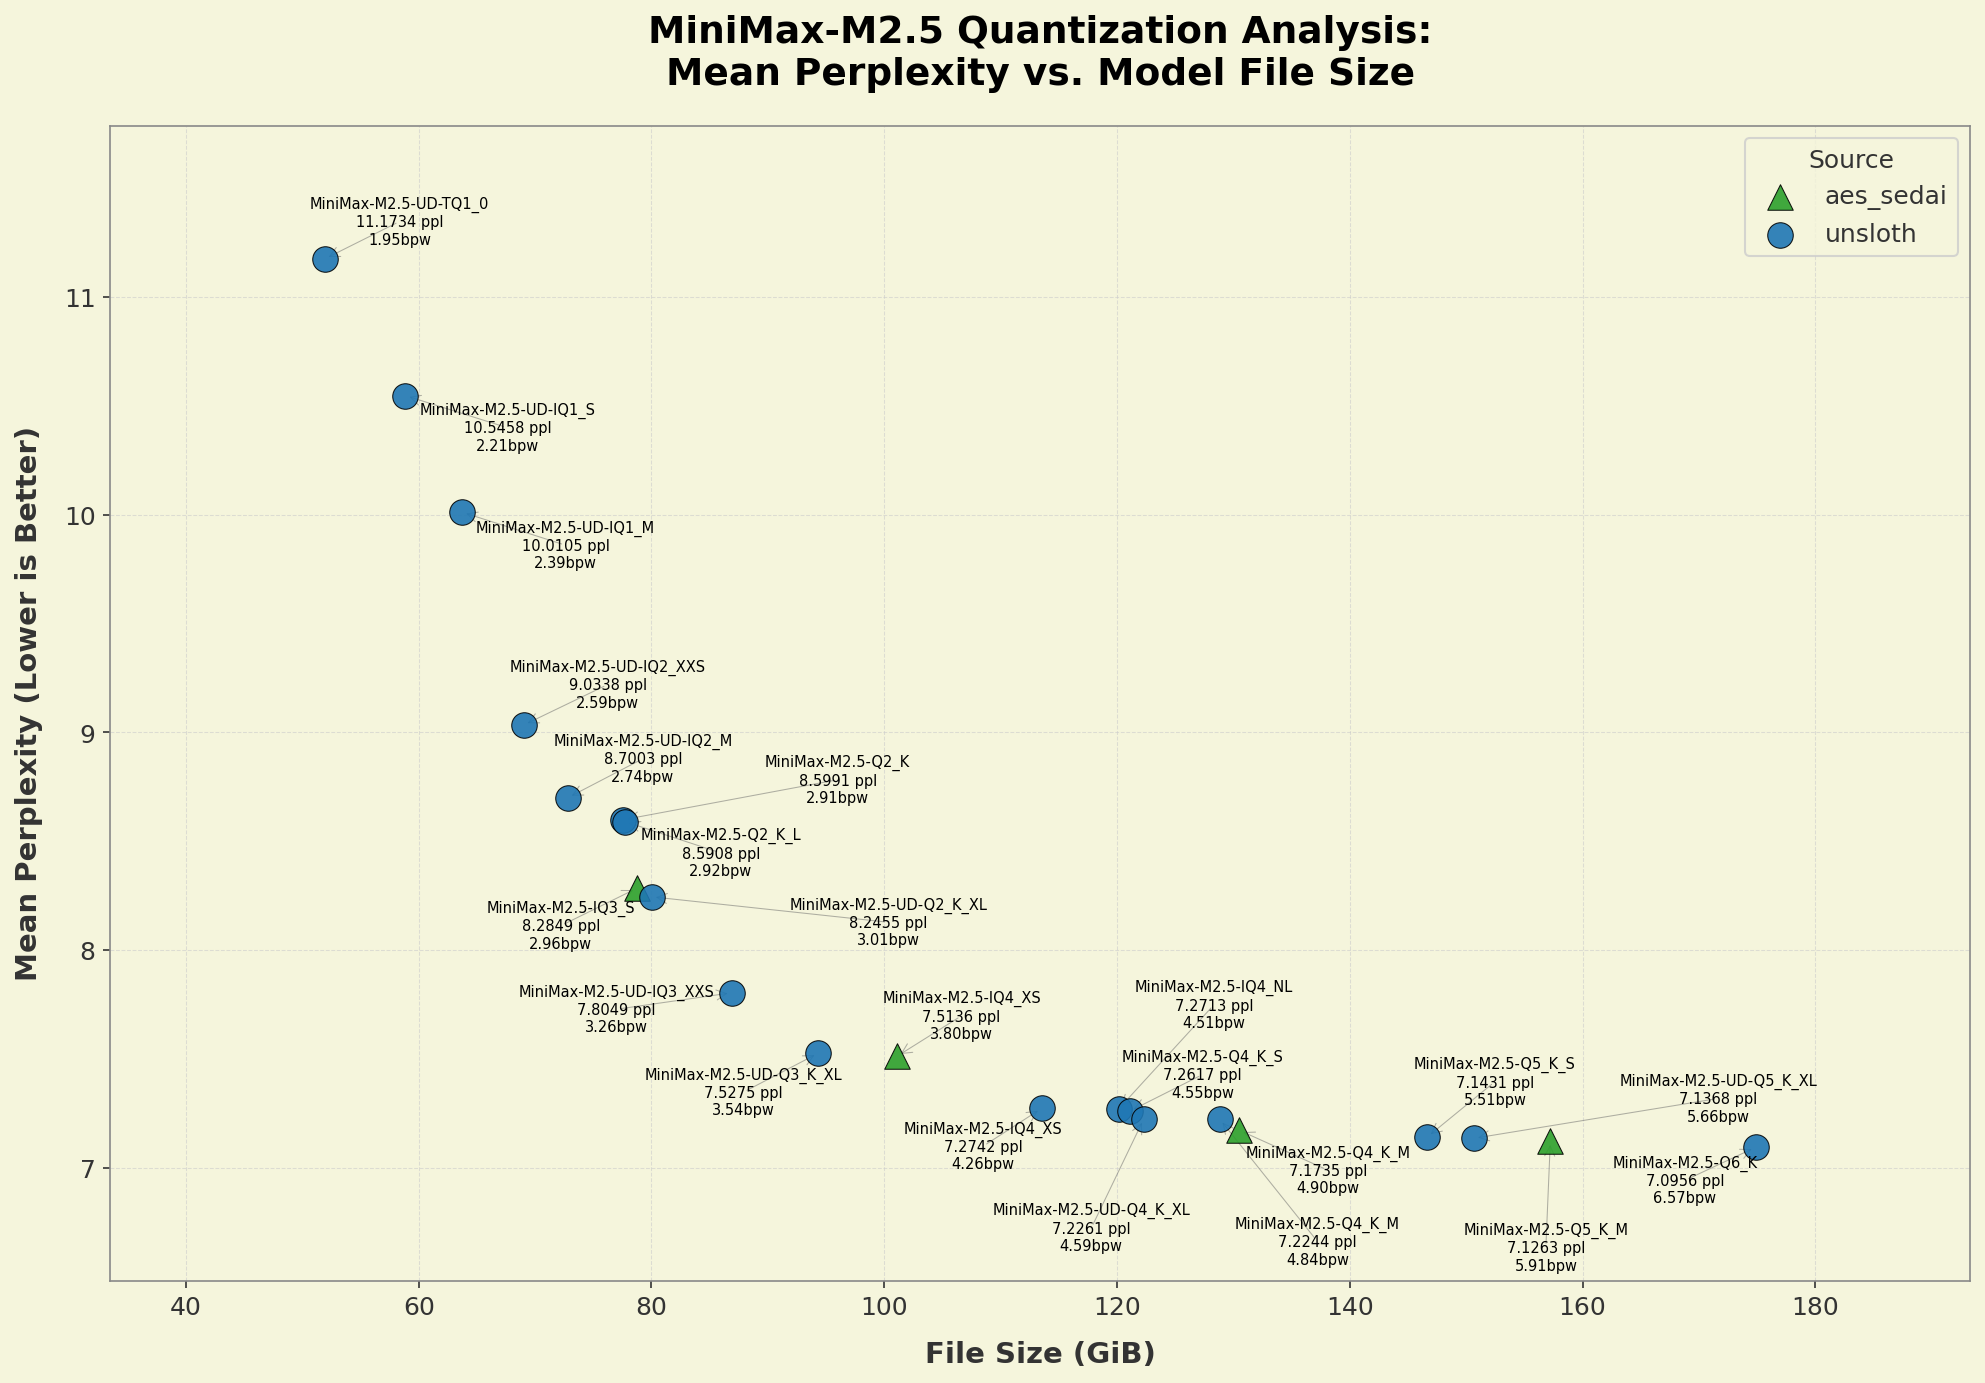
[Benjaminによる最近のMiniMax‑M2.5分析](https://x.com/bnjmn_marie/status/2027043753484021810) パープレキシティとKLDがいかに非常に誤解を招きうるかを示す事例です。Unsloth Dynamic IQ2\_XXSは、11GB小さいにもかかわらず、実世界の評価（LiveCodeBench v6、MMLU Pro）ではAesSedaiのIQ3\_Sより優れています。にもかかわらず、AesSedaiのパープレキシティとKLDベンチマークは逆の結果を示しています。（PPL: 0.3552 対 0.2441；KLD: 9.0338 対 8.2849 - 低いほど良い）。

<div><figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2F7csgZI82adnvKmQQVlp1%2F01_kld_vs_filesize_pareto.png?alt=media&amp;token=d907a2c0-7df5-4e6a-9d9b-0524c8e6ae77" alt="" width="188"><figcaption><p>KLダイバージェンス - AesSedai</p></figcaption></figure> <figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fd8KBa3uNhkDEZzq32v7q%2F02_ppl_vs_filesize_pareto.png?alt=media&amp;token=d471fce1-7482-4fde-bc98-2d10503253a4" alt="" width="188"><figcaption><p>パープレキシティ - AesSedai</p></figcaption></figure></div>

この不一致は、パープレキシティやKLDが低いことが必ずしも実世界での性能向上につながらないことを示しています。グラフはまた、UD‑Q4-K‑XLが他のQ4量子化より優れていながら、約8GB小さいことも示しています。とはいえ、パープレキシティやKLDが無意味というわけではなく、おおまかな संकेतを与えてくれます。そのため今後は、コミュニティが何らかの参照を持てるよう、すべての量子化についてパープレキシティとKLDを公開します。

### 4) 2026年3月5日アップデート - さらなる堅牢性

Qwen3.5のMoE向け量子化手法をさらに強化し、Maximum KLDを直接下げました。通常は99.9%が使われますが、大きな外れ値に対してはMaximum KLDが有用な場合があります。私たちの新しい手法は、3月5日以前の更新と比べて、Maximum KLDを全体的にかなり下げます。

<figure><img src="https://735611837-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2Fqxt3Dv8HIOWG8y3RvNYf%2FCode_Generated_Image(11).png?alt=media&amp;token=54e20159-4243-42cf-89de-d2c9d7b6409b" alt=""><figcaption></figcaption></figure>

| 量子化          | 旧GB        | 新GB          | 旧Max KLD | 新Max KLD           |
| ------------ | ---------- | ------------ | -------- | ------------------ |
| UD-Q2\_K\_XL | 12.0       | ***11.3***   | 8.237    | ***8.155***        |
| UD-Q3\_K\_XL | 16.1       | ***15.5***   | 5.505    | ***5.146***        |
| UD-Q4\_K\_XL | ***19.2*** | 20.7 (+7.8%) | 5.894    | ***2.877 (-51%)*** |
| UD-Q5\_K\_XL | ***23.2*** | 24.6 (+6%)   | 5.536    | ***3.210 (-42%)*** |

### 完全ベンチマーク

| 量子化器      | 量子化レベル           | ディスク容量（GB） | PPL    | KLD 99.9% | 平均KLD  |
| --------- | ---------------- | ---------- | ------ | --------- | ------ |
| AesSedai  | IQ3\_S           | 12.65      | 6.9152 | 1.8669    | 0.0613 |
| AesSedai  | IQ4\_XS          | 16.4       | 6.6447 | 0.8067    | 0.0235 |
| AesSedai  | Q4\_K\_M         | 20.62      | 6.5665 | 0.3171    | 0.0096 |
| AesSedai  | Q5\_K\_M         | 24.45      | 6.5356 | 0.21      | 0.0058 |
| Ubergarm  | Q4\_0            | 19.79      | 6.5784 | 0.4829    | 0.0142 |
| Unsloth   | IQ2\_XXS         | 9.09       | 7.716  | 4.2221    | 0.1846 |
| Unsloth   | Q2\_K\_XL        | 12.04      | 7.0438 | 2.9092    | 0.097  |
| Unsloth   | IQ3\_XXS         | 13.12      | 6.7829 | 1.5296    | 0.0501 |
| Unsloth   | IQ3\_S           | 14.13      | 6.7715 | 1.4193    | 0.0457 |
| Unsloth   | Q3\_K\_M         | 15.54      | 6.732  | 0.9726    | 0.0324 |
| Unsloth   | Q3\_K\_XL        | 16.06      | 6.7245 | 0.9539    | 0.0308 |
| Unsloth   | MXFP4\_MOE       | 18.17      | 6.6    | 0.7789    | 0.0272 |
| Unsloth   | Q4\_K\_M         | 18.49      | 6.6053 | 0.5478    | 0.0192 |
| Unsloth   | Q4\_K\_L         | 18.82      | 6.5905 | 0.4828    | 0.015  |
| Unsloth   | Q4\_K\_XL        | 19.17      | 6.5918 | 0.4097    | 0.0137 |
| Unsloth   | Q5\_K\_XL        | 23.22      | 6.5489 | 0.236     | 0.0069 |
| Unsloth   | Q6\_K\_S         | 26.56      | 6.5456 | 0.2226    | 0.0065 |
| Unsloth   | Q6\_K\_XL        | 28.22      | 6.5392 | 0.1437    | 0.0041 |
| Unsloth   | Q8\_K\_XL        | 36.04      | 6.5352 | 0.1033    | 0.0026 |
| bartowski | Qwen\_IQ2\_XXS   | 8.15       | 9.3427 | 6.0607    | 0.3457 |
| bartowski | Qwen\_Q2\_K\_L   | 11.98      | 7.5504 | 3.8095    | 0.1559 |
| bartowski | Qwen\_IQ3\_XXS   | 12.94      | 7.0938 | 2.1563    | 0.0851 |
| bartowski | Qwen\_Q3\_K\_M   | 14.95      | 6.772  | 1.7779    | 0.0585 |
| bartowski | Qwen\_Q3\_K\_XL  | 15.97      | 6.8245 | 1.7516    | 0.0627 |
| bartowski | Qwen\_IQ4\_XS    | 17.42      | 6.6234 | 0.7265    | 0.0234 |
| bartowski | Qwen\_Q4\_K\_M   | 19.77[^1]  | 6.6097 | 0.5771    | 0.0182 |
| bartowski | Qwen\_Q5\_K\_M   | 23.11      | 6.5828 | 0.3549    | 0.0106 |
| noctrex   | MXFP4\_MOE\_BF16 | 20.55      | 6.5948 | 0.7939    | 0.0248 |
| noctrex   | MXFP4\_MOE\_F16  | 20.55      | 6.5937 | 0.7614    | 0.0247 |

[^1]: BartowskiのQ4\_K\_MはUnslothのものより1Gb大きいです


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://unsloth.ai/docs/jp/moderu/qwen3.5/gguf-benchmarks.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.