> For the complete documentation index, see [llms.txt](https://unsloth.ai/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://unsloth.ai/docs/jp/ji-chu/inference-and-deployment/saving-to-gguf/speculative-decoding.md).
# 推測デコード
llama-server、llama.cpp、vLLMなどを使った推測デコードで、推論を2倍高速化します
## :llama:llama.cpp、llama-server における推測的デコード
llama.cpp の推測的デコードは、次を通じて簡単に有効化できます `llama-cli` そして `llama-server` を通じて `--model-draft` 引数。なお、draft モデルが必要です。通常はより小さいモデルですが、同じトークナイザを持っている必要があります
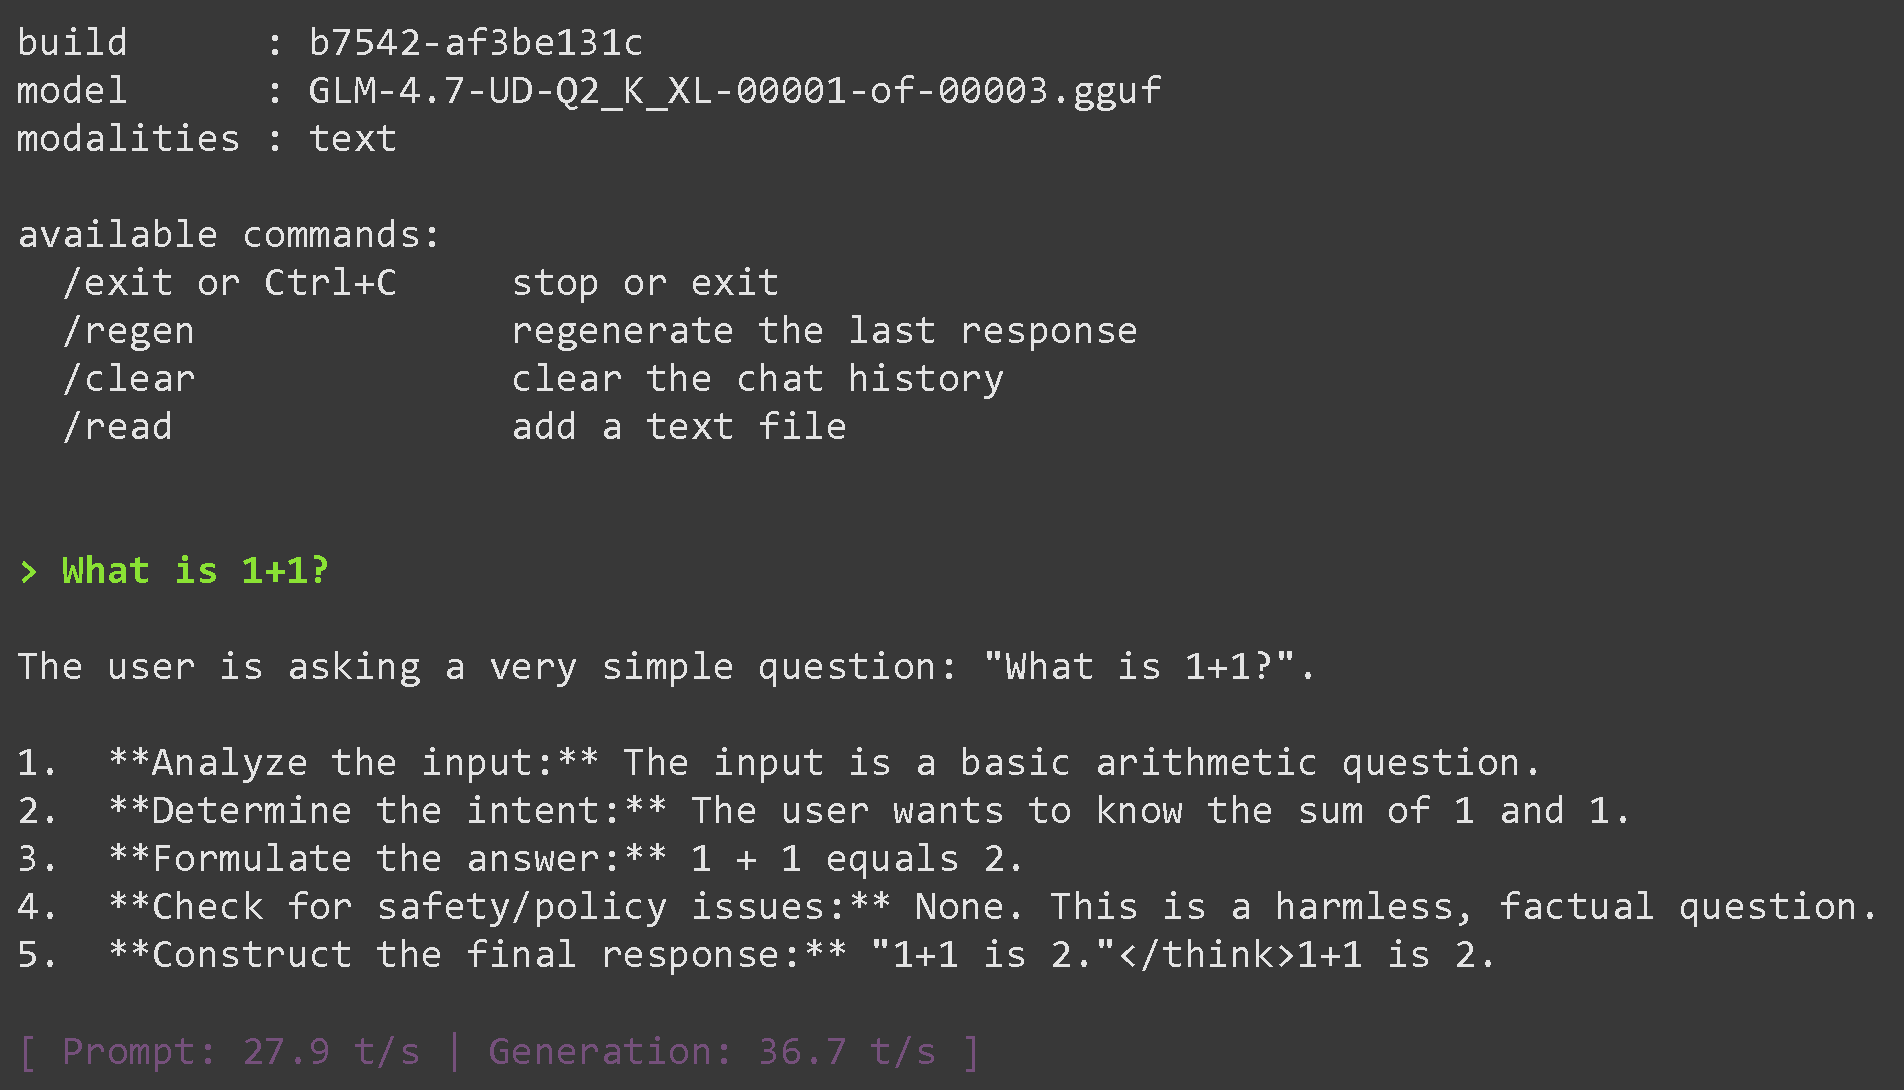
### GLM 4.7 の Spec デコード
```python
# !pip install huggingface_hub hf_transfer
import os
os.environ["HF_HUB_ENABLE_HF_TRANSFER"] = "0" # 時々レート制限が発生することがあるため、無効にするには 0 に設定します
from huggingface_hub import snapshot_download
snapshot_download(
repo_id = "unsloth/GLM-4.7-GGUF",
local_dir = "unsloth/GLM-4.7-GGUF",
allow_patterns = ["*UD-Q2_K_XL*"], # 動的 2bit。動的 1bit には "*UD-TQ1_0*" を使用
)
snapshot_download(
repo_id = "unsloth/GLM-4.5-Air-GGUF",
local_dir = "unsloth/GLM-4.5-Air-GGUF",
allow_patterns = ["*UD-Q4_K_XL*"], # 動的4bit。動的1bitには "*UD-TQ1_0*" を使用
)
```
{% code overflow="wrap" %}
```bash
./llama.cpp/llama-cli \
--model unsloth/GLM-4.7-GGUF/UD-Q2_K_XL/GLM-4.7-UD-Q2_K_XL-00001-of-00003.gguf \\
--threads -1 \
--fit on \\
--prio 3 \\
--temp 1.0 \\
--top-p 0.95 \\
--ctx-size 16384 \\
--jinja
```
{% endcode %}
{% code overflow="wrap" %}
```bash
./llama.cpp/llama-cli \
--model unsloth/GLM-4.7-GGUF/UD-Q2_K_XL/GLM-4.7-UD-Q2_K_XL-00001-of-00003.gguf \\
--model-draft unsloth/GLM-4.5-Air-GGUF/UD-Q4_K_XL/GLM-4.5-Air-UD-Q4_K_XL-00001-of-00002.gguf \
--threads -1 \
--fit on \\
--prio 3 \\
--temp 1.0 \\
--top-p 0.95 \\
--ctx-size 16384 \\
--ctx-size-draft 16384 \
--jinja \\
--device CUDA0 \
--device-draft CUDA0,CUDA1
```
{% endcode %}
{% code overflow="wrap" %}
```bash
./llama.cpp/llama-server \
--model unsloth/GLM-4.7-GGUF/UD-Q2_K_XL/GLM-4.7-UD-Q2_K_XL-00001-of-00003.gguf \\
--alias "unsloth/GLM-4.7" \\
--threads -1 \
--fit on \\
--prio 3 \\
--temp 1.0 \\
--top-p 0.95 \\
--ctx-size 16384 \\
--port 8001 \\
--jinja
```
{% endcode %}
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://unsloth.ai/docs/jp/ji-chu/inference-and-deployment/saving-to-gguf/speculative-decoding.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.